Intel
Jensen Huang’s Resignation as CEO Creates Uncertainty for Nvidia and Opportunities for Competing AI Chip Suppliers
Introduction:
Jensen Huang’s abrupt resignation as Nvidia’s President and CEO on November 12, 2026, creates uncertainty for the world’s leading AI semiconductor company and potentially far-reaching consequences for the artificial intelligence (AI) industry. Huang co-founded Nvidia in 1993 and spent 33 years transforming it from a graphics processor supplier into the dominant provider of accelerated computing platforms powering today’s AI infrastructure buildout.
Huang was much more than Nvidia’s CEO. He was the AI industry’s chief cheerleader, dealmaker and ecosystem architect. Through his technological vision, industry relationships, investments and strategic partnerships, he helped establish Nvidia at the center of an extensive network of AI developers, cloud service providers, semiconductor companies and data center operators.
“My management style is what made it possible for the company to grow,” Huang told Bloomberg News’ Emily Chang in a recent interview. “I wanted an organization that was able to adapt to change, both in inventing change for itself and the rest of the industry, as well as reacting to change that’s coming toward us.”
Nvidia’s board appointed longtime CFO Colette Kress as interim CEO while beginning a search for a permanent successor. Although the company says its operations, customer commitments and product roadmap will continue without interruption, the sudden departure of the executive who personally drove much of its strategy raises questions about leadership continuity, customer confidence and the future direction of its AI ecosystem.
Huang’s exit could reverberate across the global tech sector, well past Nvidia’s position as the primary silicon supplier for the AI era. As an active strategic dealmaker, Huang has leveraged the company’s resources to strengthen critical supply chain bottlenecks and back next-generation AI startups. Furthermore, he remains one of the sector’s most visible evangelists, championing accelerated computing and enterprise AI adoption while countering alarmist views on existential safety risks. The most important potential consequence is competitive: uncertainty surrounding Nvidia could encourage customers to accelerate diversification of their AI accelerator suppliers, creating opportunities for AMD, Google’s Tensor Processing Units (TPUs), Broadcom, Cerebras and Huawei’s Ascend AI processors in China.
Nvidia’s Leadership and Ecosystem Advantage:
Nvidia’s competitive position is based on considerably more than the performance of its GPUs. The company has developed an integrated computing platform combining:
- GPU accelerators: High-performance processors designed for parallel computing workloads, including AI model training and inference.
- NVLink and NVSwitch: High-bandwidth interconnect technologies that allow multiple GPUs to operate as tightly coupled computing systems.
- InfiniBand and Spectrum-X Ethernet: Networking platforms connecting large numbers of GPUs across AI data centers via the company’s acquisition of Mellanox (announced March 11, 2019; completed on April 27, 2020).
- CUDA software ecosystem: A programming platform, libraries and development tools that support a large community of AI developers and applications.
- Complete AI computing systems: Integrated combinations of GPUs, CPUs, networking, storage and software designed for large-scale AI infrastructure.
This combination of hardware, networking and software has created substantial customer dependence on Nvidia’s technology. Replacing Nvidia GPUs is not simply a matter of purchasing competing accelerator chips. Customers must also consider software compatibility, application optimization, networking architecture, performance, power consumption and the cost of migrating existing workloads.
Huang was instrumental in building this integrated ecosystem and cultivating the relationships that helped make Nvidia the preferred AI computing platform for many of the industry’s largest customers. His departure raises critical questions about whether the AI industry will continue its unprecedented circular financing deals.
…………………………………………………………………………………………………………………………………………………………………………………………………………
Will Nvidia’s Circular AI Financing Continue Without Jensen Huang?
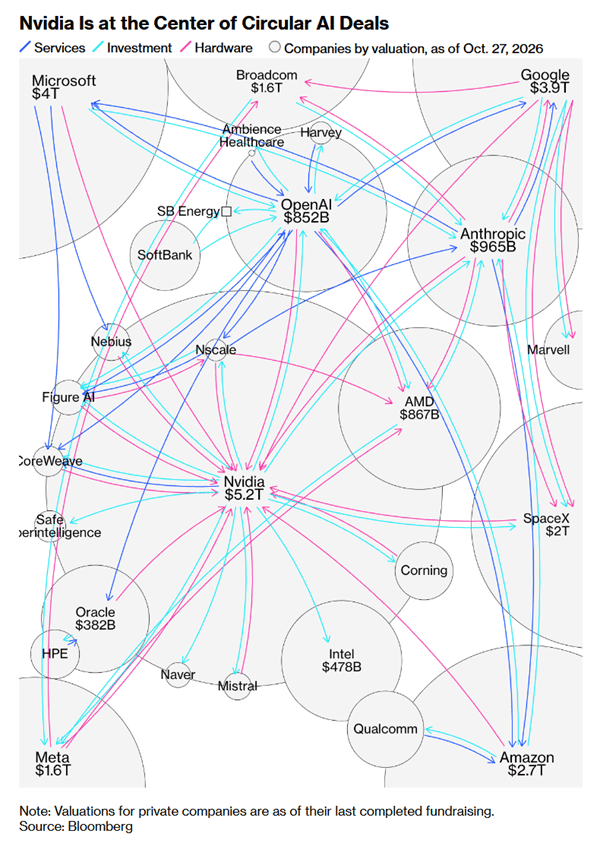
The diagram above shows how Nvidia sits at the center of a complex web of circular investments, hardware purchases and services relationships. Broadcom is another important participant, but the central question is whether Nvidia’s financing strategy will retain its momentum without Huang, who personally championed the initiative. Nvidia announced in August 2026 that it was partnering with Apollo, BlackRock, Blackstone, Brookfield, Goldman Sachs and KKR to establish financing platforms intended to mobilize more than $500 billion in third-party capital for AI infrastructure. Huang described the initiative as a way to turn AI computing infrastructure into an investable asset class. However, Bloomberg subsequently reported that the initiative had not produced financing deals after months of activity, with some customers and financial partners seeking stronger financial backing from Nvidia. The uncertainty surrounding Huang’s departure therefore raises questions about the initiative’s future.
Will Nvidia’s new leadership maintain Huang’s aggressive approach to financing the AI ecosystem, including investments and financial commitments that help stimulate demand for Nvidia’s own products? Or will the company become more conservative in allocating capital and assuming financial exposure?
The implications extend beyond Nvidia. As the Bloomberg graphic illustrates, AI infrastructure investment increasingly involves interconnected relationships among chip suppliers, cloud providers, AI developers and financial institutions. If Nvidia reduces or restructures its financial commitments, the consequences could affect AI infrastructure deployment, customer purchasing plans and competing semiconductor suppliers. Ultimately, the question is whether the AI industry’s closely interconnected investments and financing model can sustain its momentum without the executive who was its most prominent champion and dealmaker.
………………………………………………………………………………………………………………………………………………………………………………………………
Potential Opportunities for Competing AI Chip Suppliers and Platforms:
Jensen’s exit also raises the question if Nvidia can maintain the same pace of technological innovation, strategic deal making and ecosystem development under different leadership? A sudden leadership transition at a company as strategically important as Nvidia could prompt some customers to reassess their dependence on its products. Large cloud providers and AI developers have strong incentives to maintain alternative accelerator platforms, reduce supplier concentration and negotiate more favorable computing costs. Several AI chip competitors warrant particular attention.
AMD: Direct Competition in AI GPUs
Advanced Micro Devices (AMD) is Nvidia’s most direct competitor in the market for general-purpose AI GPU accelerators.
AMD’s Instinct accelerator family, supported by its ROCm software ecosystem, offers an alternative platform for AI training and inference. AMD has been working to improve accelerator performance, memory capacity, interconnect capabilities and software compatibility to compete more effectively with Nvidia.
The principal opportunity for AMD is to attract customers seeking a second source of AI accelerators or greater negotiating leverage in purchasing decisions.
However, AMD must demonstrate competitive performance, reliable software support and the ability to deliver complete systems at scale. Nvidia’s established CUDA ecosystem remains a significant competitive advantage.
Google: Tensor Processing Units
Google’s Tensor Processing Units are custom-designed application-specific integrated circuits (ASICs) developed to accelerate machine learning workloads.
Unlike general-purpose GPUs, TPUs are designed around Google’s particular AI computing requirements and software environment. They are deployed within Google Cloud and support Google’s own AI models and services, as well as external customers using its cloud infrastructure. Google’s TPU platform provides an alternative to Nvidia GPUs for selected workloads, particularly where customers can optimize their software and applications for Google’s architecture. Google could benefit if customers increasingly seek alternatives to Nvidia’s GPU platform, although its opportunity is primarily tied to its own cloud and AI ecosystem rather than unrestricted sales of standalone accelerators.
Broadcom: Custom AI Accelerators and Networking Silicon
Broadcom is arguably one of Nvidia’s most important competitors in the broader AI semiconductor market, although it competes differently from AMD.
Rather than selling general-purpose GPUs, Broadcom specializes in designing custom AI accelerators (ASICs) for hyperscale customers. Its XPU platform combines custom compute silicon, high-speed SerDes, advanced packaging, memory interfaces and networking technologies.
Broadcom’s partnerships with major AI infrastructure customers are particularly significant:
- Google: Broadcom has been a key technology partner in Google’s custom TPU development.
- Meta: Broadcom is collaborating on Meta’s MTIA (Meta Training and Inference Accelerator) custom AI silicon, including a multi-generation deployment roadmap.
- OpenAI: Broadcom and OpenAI announced a collaboration in June 2026 to develop custom AI accelerators optimized for large language model inference, with planned deployment at gigawatt scale.
Broadcom’s competitive significance extends beyond individual chips. Its Ethernet networking and connectivity technologies also support the construction of large-scale AI computing clusters.
As hyperscalers increasingly develop their own AI accelerators to reduce dependence on Nvidia GPUs, Broadcom is positioned to benefit from the shift toward custom silicon.
Cerebras Systems: Wafer-Scale AI Computing
Cerebras Systems takes a substantially different architectural approach to AI acceleration.
Its Wafer-Scale Engine (WSE) integrates an exceptionally large number of processing cores, memory and interconnects onto a single silicon wafer. This architecture is designed to reduce communication bottlenecks associated with distributing AI workloads across large numbers of conventional processors.
Cerebras offers integrated AI computing systems rather than simply selling accelerator cards. Its technology targets large-scale AI model training and inference, with particular emphasis on high-throughput, low-latency inference.
Cerebras has attracted significant attention through commercial relationships with major AI developers, including OpenAI.
Although Cerebras does not yet have Nvidia’s breadth of software ecosystem, installed base or general-purpose GPU market presence, its wafer-scale architecture represents a credible alternative for selected AI workloads.
Its potential competitive advantage is architectural differentiation rather than direct replication of Nvidia’s GPU platform.
Intel: Gaudi AI Accelerators and Data Center Computing
Intel is another potential competitor, although its position in AI accelerators is less established than AMD’s or Broadcom’s.
Intel’s Gaudi 3 accelerator was designed for generative AI training and inference, featuring high-bandwidth memory and integrated networking capabilities. Intel has promoted Gaudi as an alternative to Nvidia GPUs, emphasizing performance, power efficiency and total cost of ownership.
Intel also brings an extensive data center processor business and established relationships with enterprise customers and server manufacturers.
However, Intel has faced challenges establishing Gaudi as a widely adopted alternative to Nvidia’s dominant GPU platform. Its ability to compete will depend on future accelerator products, software development, customer adoption and execution of its AI semiconductor roadmap.
Intel should therefore be considered a potential challenger rather than an established competitor on the same footing as AMD or Broadcom.
Huawei: China’s Domestic AI Accelerator Alternative
Huawei’s Ascend AI processor family is an important alternative for Chinese AI developers and data center operators. U.S. export restrictions have already encouraged China’s domestic semiconductor industry to develop alternatives to advanced Nvidia accelerators. Huawei is positioned to benefit from this trend through its Ascend AI processors, computing systems and associated software ecosystem. Recent reports indicate that lawmakers in Congress are actively pushing for even stricter export curbs on Nvidia’s China-bound chips (such as the H20 and H200) and have summoned Huang to testify. This impending regulatory tightening would further reinforce Nvidia’s China headwinds and boost sales of Huawei’s Ascend chips in China.
While Huang’s departure adds another element of uncertainty to Nvidia’s long-term position in China. Huawei’s opportunity is driven primarily by China’s semiconductor self-sufficiency objectives, domestic procurement policies and U.S. export controls—not simply Nvidia’s leadership transition. Huawei must still address performance, manufacturing capacity, software compatibility and the ability to support large-scale AI deployments.
………………………………………………………………………………………………………………………………………………………………………………
In addition to the above AI chip suppliers, Amazon, Microsoft and Meta hyperscalers are developing their own custom AI accelerators, while Marvell is an important custom-silicon and connectivity supplier.
………………………………………………………………………………………………………………………………………………………………………………
Major AI chip companies and competitive market positioning:
The following table distinguishes companies selling merchant AI accelerators from those developing custom silicon primarily for their own cloud or AI infrastructure.
| Company | AI chip / platform | Niche and technological strengths | Market presence |
|---|---|---|---|
| Nvidia | Blackwell, Rubin GPUs; Grace CPUs | GPU acceleration, CUDA software, NVLink, InfiniBand, Spectrum-X Ethernet; integrated AI factories |
Dominant market leader
Broadest commercial AI accelerator ecosystem |
| AMD | Instinct MI350/MI400; ROCm | General-purpose AI GPUs, HBM, chiplet architecture, open software ecosystem |
Major challenger
Competing for hyperscaler, enterprise and HPC deployments |
| Broadcom | Custom XPUs, networking ASICs | Custom AI accelerators for hyperscalers; high-speed SerDes, Ethernet switching and connectivity |
Major competitor
Important supplier to hyperscalers developing custom AI silicon |
| TPU | Custom ASICs optimized for AI training and inference; tightly integrated with Google Cloud and AI software |
Major alternative
Significant internal deployment and external cloud availability |
|
| Huawei | Ascend processors; Atlas systems | AI accelerators, integrated computing systems and domestic Chinese semiconductor ecosystem |
Major China-market player
Important alternative amid U.S. export restrictions |
| Intel | Gaudi; Xeon | AI accelerators, CPUs, memory and data-center platforms |
Challenger
Established semiconductor presence, but limited AI accelerator traction relative to Nvidia |
| Cerebras Systems | Wafer-Scale Engine (WSE) | Wafer-scale integration, massive on-chip parallelism, high-bandwidth memory and specialized AI inference systems |
Specialist competitor. Differentiated architecture for large AI workloads. Full-year 2026 core revenue outlook of $940 million to $960 million.
|
| Amazon | Trainium, Inferentia | Custom ASICs for AI training and inference; integration with AWS infrastructure |
Significant captive platform
Expanding AWS alternative to Nvidia |
| Microsoft | Maia | Custom AI accelerator architecture for Azure workloads |
Emerging platform
Strategic internal development and deployment |
| Meta | MTIA | Custom accelerators designed for Meta’s recommendation, ranking and generative AI workloads |
Emerging platform
Large internal deployment opportunity |
| Marvell | Custom AI ASICs, optical DSPs, interconnect silicon | Custom compute silicon, high-speed connectivity and optical networking for AI data centers |
Important infrastructure competitor
Benefits from hyperscaler custom silicon investment |
Source: Frontier Tech Intelligence, ChatGPT
Editor’s Note: Not every company listed above is a direct merchant-chip competitor to Nvidia. Some are building captive platforms, while others supply the technology that enables those platforms.
………………………………………………………………………………………………………………………………………………………………………………………………
Top AI Chip Company Beneficiaries & Competitive Positioning:
| Supplier | Core AI Platform | Why They Gain Share Now | Primary Bottleneck / Risk |
|---|---|---|---|
| Broadcom | Custom XPUs, Tomahawk 6 / Jericho switches | Holds 70%+ share of custom AI ASIC design with a $73B+ backlog across Google, Meta, OpenAI, and Anthropic. Captures both custom compute and the Ethernet networking fabric required for non-Nvidia clusters. | Custom ASICs require 12–24 month design cycles and are largely limited to hyperscale budgets. |
| AMD | Instinct MI350 / MI400 series, Helios racks, ROCm 7 | The only merchant general-purpose GPU alternative capable of drop-in cluster deployment. Offers 30–50% lower TCO and higher HBM capacity per chip for inference workloads. | ROCm software maturity and scale-up interconnect bandwidth still trail CUDA and NVLink in frontier training. |
| Google (TPU) | Ironwood (TPU v7) / Trillium (TPU v6) | Most mature non-Nvidia production ecosystem. Captures external AI developers through Google Cloud who want immediate compute capacity without waiting on Nvidia’s post-Huang roadmap. | Captive to Google Cloud; not sold as standalone merchant silicon for on-premises data centers. |
| Marvell | Custom AI ASICs, 1.6T optical DSPs | Co-designs AWS Trainium and Microsoft Maia. Benefits directly as AWS and Azure shift internal inference workloads onto captive silicon to reduce Nvidia exposure. | Smaller customer base than Broadcom; remains vulnerable if hyperscalers bring physical design fully in-house. |
| Cerebras Systems | Wafer-Scale Engine (WSE-3) | Eliminates off-chip interconnect bottlenecks for ultra-low-latency inference. Recently raised its 2026 core revenue outlook to $940M–$960M following major enterprise/cloud wins like Microsoft. | Niche architectural footprint; lacks the general-purpose software ecosystem needed to replace broad GPU fleets. |
Source: Google Gemini
………………………………………………………………………………………………………………………………………………………………………………………………..
Will Nvidia Customers Diversify Their AI Accelerator Suppliers?
The key question is whether Nvidia’s leadership transition will materially change customer purchasing decisions. Nvidia’s board has expressed confidence in the company’s existing management team and technology roadmap. Colette Kress is an experienced executive who has served as CFO since 2013, and the company has emphasized continuity in its operations and customer commitments. Nevertheless, the loss of Huang’s leadership creates uncertainty that competitors could exploit.
AI infrastructure investments involve long planning cycles, substantial capital expenditures and commitments to particular hardware and software platforms. Customers making multibillion-dollar investments need confidence that their suppliers will maintain technological leadership, product availability, software support and long-term strategic relationships. Consequently, even if Nvidia’s engineering organization and product roadmap remain intact, some customers could accelerate qualification and deployment of competing accelerators.
This would not necessarily mean abandoning Nvidia. A more likely initial response would be supplier diversification, with AMD GPUs, Google TPUs and other specialized accelerators deployed alongside Nvidia systems where technically and economically appropriate. The transition toward multi-vendor AI computing could also increase interest in software portability, open programming frameworks and more interoperable data center architectures.
………………………………………………………………………………………………………………………………………………………………………………………………
Conclusions:
Jensen Huang’s resignation does not eliminate Nvidia’s substantial technological advantages, established customer relationships or extensive CUDA software ecosystem. The company retains a strong engineering organization, an experienced executive team and a broad portfolio of AI computing products.
However, Huang’s departure removes the individual who was arguably the most influential executive in the AI infrastructure industry. His combination of technological vision, deal making, industry relationships and strategic leadership was central to Nvidia’s rise and its position at the center of the global AI ecosystem. The immediate issue is whether Nvidia’s customers and strategic partners will maintain confidence in the company’s future direction. If uncertainty persists, competitors could benefit as hyperscalers, AI developers and enterprise customers seek greater supplier diversity.
AMD has the clearest opportunity to gain external GPU accelerator business, Google can expand its TPU-based AI computing services, and Huawei has an opportunity to strengthen its position in China’s domestic AI accelerator market.
Nvidia’s leadership transition faces immediate geopolitical and financial tests that could accelerate customer diversification. In Washington, lawmakers are pushing new defense-bill export controls—such as the AI Overwatch, Chip Security, and Remote Access Security acts—to tighten China chip curbs and close overseas cloud-rental loopholes while summoning Jensen Huang to testify in December. Meanwhile, interim CEO Colette Kress faces her first major test during Nvidia’s November 17 Q3 FY27 earnings call, where customers and investors will watch closely for reassurance on Vera Rubin schedules and ongoing ecosystem financing commitments.
The ultimate competitive test will not be whether Nvidia can continue selling GPUs without Jensen Huang. It will be whether the company can retain customer confidence, sustain its technology and software leadership, and preserve the strategic ecosystem that he spent 33 years building.
……………………………………………………………………………………………………………………………………………………………………………………………..
Addendum: Two competing approaches to AI-RAN implementation:
1. Nvidia and Nokia: GPU-centric RAN
-
Nvidia and Nokia are promoting GPUs as the computing engine for AI-RAN.
-
Nokia is designing future RAN products around Nvidia GPUs, including execution of demanding Layer 1 (Physical layer) processing functions.
-
The objective is to use accelerated computing for both conventional RAN processing and AI workloads, potentially improving spectral efficiency and enabling shared infrastructure.
- This represents a departure from Nokia’s previous reliance on Marvell custom silicon for Physical layer processing.
2. Ericsson: Custom ASICs and CPU-based vRAN
-
Ericsson favors its own purpose-built ASICs for demanding Layer 1 RAN processing.
-
Its separate virtual RAN strategy uses Intel x86 CPUs for most Layer 1 functions, with hardware acceleration for forward error correction (FEC).
-
Ericsson is also exploring software portability to AMD and Arm-based CPU platforms.
- Ericsson argues that its custom silicon offers cost, performance and technological independence advantages over adopting Nvidia GPUs throughout the RAN.
Marvell deserves particular attention. It was Nokia’s custom silicon partner, and its technology remains relevant to existing Nokia RAN deployments. Even Nokia’s AI-RAN trials with Virgin Media O2 reportedly used Marvell Layer 1 silicon rather than Nvidia GPUs.
Attribution: ChatGPT was used extensively for research, technical analysis, and drafting, including an assessment of competing AI-RAN architectures, Nvidia’s GPU-centric approach with Nokia, and alternative custom-silicon and CPU-based RAN strategies pursued by Ericsson and its technology partners. The author reviewed, revised, and fact-checked all the material and is 100% responsible for its content.
………………………………………………………………………………………………………………………………………………………………………………………………………………………….
References:
https://nvidianews.nvidia.com/news/nvidia-announces-ceo-transition
https://www.sec.gov/Archives/edgar/data/1045810/000104581026000082/nvda-20261111.htm
https://www.reuters.com/business/view-nvidia-ceo-jensen-huang-steps-down-2026-11-12/
https://www.amd.com/en/products/accelerators/instinct/mi350.html
https://rocm.docs.amd.com/en/latest/reference/gpu-arch/mi350.html
https://cloud.google.com/tpu/docs/intro-to-tpu
https://www.broadcom.com/products/ai
https://www.intel.com/content/www/us/en/products/details/processors/ai-accelerators/gaudi.html
https://www.huawei.com/en/technology-insights/industry-insights/outlook/5g
Custom AI Silicon: OpenAI, Anthropic, Hyperscalers, Huawei and the Battle with Nvidia, AMD and Broadcom
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
2026 OCP Summit: Full-Stack AI Networking Silicon from Nvidia/Cisco and Broadcom; Ethernet vs InfiniBand Interconnects
Huawei’s Ascend Silicon Roadmap Extends From AI Chips to Cluster-Scale Infrastructure
AI-RAN Push: NVIDIA, Nokia, and Operators Drive Towards Distributed Compute Platforms
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
Intel and Broadcom Demonstrate IEEE 802.11bn/Wi-Fi 8 Interoperability
Disclaimer: ChatGPT was used for research in this article, but the author had to frequently checkpoint its AI work for omissions and accuracy.
…………………………………………………………………………………………………………………………………………………
Introduction:
Wi-Fi 8, based on the IEEE 802.11bn amendment, reached an important development milestone with a public cross-vendor interoperability demonstration involving prototype equipment from Intel and Broadcom. Conducted in London on October 27, the demonstration showed that a Broadcom-based Wi-Fi 8 access point could interoperate with an Intel Wi-Fi 8 client while demonstrating improvements in spectrum utilization, aggregate throughput and latency.
The demonstration is significant because it moves Wi-Fi 8 beyond individual vendor prototypes toward cross-vendor interoperability. It also illustrates the technology’s central objective: improving reliability, predictable performance and efficient spectrum utilization rather than simply increasing maximum theoretical data rates. However, this was an engineering demonstration, not formal Wi-Fi Alliance certification in advance of the IEEE 802.11bn standard which has not been finalized.
IEEE 802.11bn: The Foundation for Wi-Fi 8:
Wi-Fi 8 is the industry designation for the next-generation wireless LAN technology being developed through the IEEE 802.11 Working Group’s P802.11bn amendment, formally titled Enhancements for Ultra High Reliability (UHR). Unlike previous generations that emphasized increasing maximum theoretical data rates, IEEE 802.11bn focuses on improving actual network performance under challenging operating conditions. These include dense deployments, overlapping access points, interference, mobility, edge-of-coverage conditions and networks supporting large numbers of simultaneously connected devices.
The amendment covers enhancements to both the physical layer (PHY) and medium access control (MAC) layer. Its objectives include:
- Higher reliability and more consistent throughput.
- Reduced latency and latency variation.
- Improved spectrum utilization and coexistence.
- Better performance in dense wireless deployments.
- Improved coordination among multiple access points.
- Greater energy efficiency.
Wi-Fi 8 retains important capabilities introduced with Wi-Fi 7, including operation in the 2.4, 5 and 6 GHz unlicensed bands, channel bandwidths up to 320 MHz, 4096-QAM modulation and Multi-Link Operation (MLO). The key distinction is that Wi-Fi 8 is intended to improve the consistency and reliability of wireless connectivity rather than simply raise maximum advertised speeds.
In other words, UHR is about delivering better real-world wireless performance, particularly when networks are congested or radio conditions are less than ideal.
IEEE 802.11bn Task Group and Standards Status:
The IEEE 802.11 Working Group has been responsible for developing wireless LAN standards, since it was created in September 1990. The IEEE 802.11 Task Group bn (IEEE 802.11bn) is specifically responsible for the technical development of the Wi-FI 8 standard which will provide enhancements for an Ultra High Reliability capability in an IEEE 802.11 Wireless Local Area Network (WLAN). IEEE 802.11bn (Wi-Fi 8) is still under development and is far from a completed, approved standard. The IEEE 802.11 Working Group continues to develop the specification through Task Group bn. Although the project has progressed to draft development and working-group balloting, it has not completed the IEEE standards approval process. Technical features and requirements may therefore change before final approval. The current target timeline calls for completion in 2028, but that schedule remains subject to change.
The IEEE 802.11bn task group includes participants from across the wireless industry, including chipset manufacturers, equipment vendors, technology companies and research organizations. These participants contribute technical proposals, evaluate alternative approaches and develop the amendment through the IEEE standards process.
IEEE’s published project information indicates that the P802.11bn Draft 2.0 Working Group letter ballot passed in September 2026. The ballot attracted 560 returned votes from a pool of 705 voters, with 417 approving and 128 disapproving. The approval rate was 76.5%, just above the required 75% threshold. The task group subsequently began resolving comments and developing the next draft.
Final IEEE 802.11 Working Group approval is currently projected for March 2028, followed by additional IEEE approval processes. These dates remain subject to change. Consequently, Wi-Fi 8 remains a work in progress. Prototype equipment can implement selected draft features, but those implementations should not be confused with compliance to a finalized standard.
Intel and Broadcom Conduct Cross-Vendor Interoperability Testing:
The October 27th demonstration was reported by Wi-Fi NOW and involved Intel and Broadcom engineers. It was conducted at a Wi-Fi Alliance members meeting in London, collocated with the Dynamic Spectrum Alliance (DSA) Global Summit. The demonstration used a Broadcom-based Wi-Fi 8 access point interoperating with an Intel Wi-Fi 8 client device. Existing Wi-Fi 7 equipment was also used for performance comparisons.

The CMX500 Signaling Tester, now has WiFi8 Test Capabilities Photo Credit: Rohde & Schwarz
………………………………………………………………………………………………………………………………………..
It is important to distinguish the responsibilities of the organizations involved:
- IEEE 802.11 Working Group, Task Group bn: Developing the IEEE 802.11bn technical standard.
- Intel and Broadcom: Conducted the cross-vendor interoperability demonstration using their respective prototype devices.
- Rohde & Schwarz: Demonstrated Wi-Fi 8 RF signaling test capabilities with Broadcom using its CMX500 one-box signaling tester. The platform supports RF testing of Wi-Fi 8 devices, including physical-layer measurements such as distributed Resource Unit (dRU) and User EVM Quality Metric (UEQM). This is RF conformance and performance testing, distinct from cross-vendor interoperability demonstrations and Wi-Fi Alliance certification.
- Wi-Fi Alliance: Provides an industry framework for Wi-Fi interoperability and product certification. Its members’ meeting hosted the demonstration, but the demonstration itself was not a Wi-Fi Alliance certification event.
- Dynamic Spectrum Alliance: Organized the colocated Global Summit. It was not responsible for developing IEEE 802.11bn or conducting the Intel-Broadcom test.
This distinction matters. Cross-vendor interoperability demonstrations help identify implementation problems and establish that equipment from different manufacturers can work together. Formal Wi-Fi Alliance certification is a separate process involving defined specifications and testing requirements.
The October 27th demonstration was an encouraging interoperability milestone, not proof of universal compatibility across Wi-Fi 8 products or features.
Non-Primary Channel Access (NPCA): Improving Spectrum Utilization:
The demonstration focused on Non-Primary Channel Access (NPCA), one of the MAC-layer enhancements being developed for Wi-Fi 8. NPCA is designed to improve spectrum utilization when multiple access points compete for access to the same wide channel.
Consider a dense wireless deployment in which two access points operate within the same 160 MHz channel. One access point may transmit using only part of that channel bandwidth, while another access point must wait for the primary channel to become available. This can leave portions of the wider channel temporarily underutilized.
NPCA enables a Wi-Fi 8 device, under specified operating conditions, to access an available non-primary portion of the channel rather than unnecessarily waiting for the entire channel to become available. The objective is to improve channel utilization, reduce contention and increase aggregate network throughput without requiring additional spectrum. This is particularly relevant to enterprise WLANs, high-density residential environments, public venues and other deployments where multiple access points share limited unlicensed spectrum. NPCA is an example of the broader UHR philosophy: improving the efficiency and reliability of existing wireless resources instead of relying exclusively on wider channels or higher-order modulation.
Demonstrated Throughput and Latency Improvements:
Intel and Broadcom constructed a live demonstration to illustrate NPCA’s potential benefits.
The initial configuration showed Wi-Fi 7 network performance without additional interference. A second access point was then activated on the same channel, increasing contention and reducing throughput as the two networks competed for spectrum access.
The demonstration subsequently enabled Wi-Fi 8 NPCA functionality.
According to the reported results, enabling NPCA produced:
- Approximately 30% higher aggregate throughput.
- Up to 50% lower latency compared with the baseline scenario.
These improvements were achieved using existing spectrum resources rather than additional channel allocations.
These numbers require careful interpretation. They are results from a specific demonstration configuration, not independently verified performance improvements applicable to all Wi-Fi 8 deployments.
Actual results will depend on channel conditions, network configuration, access-point density, device capabilities, interference and traffic patterns. The reported improvements should therefore be viewed as evidence of the potential benefits of NPCA, not as guaranteed performance gains for commercial Wi-Fi 8 networks.
Intel also prepared a demonstration of additional intermediate Modulation and Coding Scheme (MCS) levels. These were not presented during the main event because of time constraints.
Additional MCS levels can provide finer adjustments to transmission rates as radio conditions change, potentially improving spectrum efficiency and link performance.
Other Organizations Advancing Wi-Fi 8 Testing:
Cross-vendor interoperability is only one part of the testing required before commercial Wi-Fi 8 products become widely available.
Several organizations are contributing to different aspects of Wi-Fi 8 development and validation:
- Rohde & Schwarz and Broadcom
In February 2026, Rohde & Schwarz announced Wi-Fi 8 RF signaling test capabilities for its CMX500 one-box signaling tester.
Working with Broadcom, Rohde & Schwarz demonstrated testing of a prototype Wi-Fi 8 device at the physical layer. Its testing capabilities address new IEEE 802.11bn features, including distributed Resource Units (dRU) and unequal modulation (UEQM).
These tests are important because cross-vendor interoperability alone does not establish that a device meets all required RF performance specifications. RF signaling tests provide a means to evaluate device behavior and implementation of PHY-layer capabilities under controlled conditions.
- Wi-Fi Alliance
The Wi-Fi Alliance plays a separate industry role in interoperability testing and certification of Wi-Fi products.
Its certification programs help ensure that products from different manufacturers conform to applicable Wi-Fi specifications and can operate together.
As IEEE 802.11bn progresses toward completion, the Wi-Fi Alliance will have an important role in developing the associated Wi-Fi 8 certification program and testing requirements.
The distinction between IEEE standardization and Wi-Fi Alliance certification is fundamental: IEEE develops the underlying technical standard, while the Wi-Fi Alliance develops industry certification programs to promote interoperability and product compatibility.
- Intel and Broadcom
The October demonstration is particularly significant because it moved beyond testing an individual manufacturer’s prototype against its own equipment.
Interoperability between a Broadcom access point and an Intel client demonstrates progress toward cross-vendor operation, an essential requirement for a successful Wi-Fi ecosystem.
Intel has indicated that additional interoperability testing, including a planned industry plugfest around the third quarter of 2027, is expected before its Wi-Fi 8 client products reach commercial introduction.
What Comes Next?
Wi-Fi 8 still faces substantial engineering and standardization work.
The IEEE 802.11bn amendment must complete its draft development, comment resolution and approval processes. Chipset manufacturers and equipment vendors must continue validating PHY and MAC functionality, RF performance and interoperability.
Additional cross-vendor plugfests will be important for identifying implementation differences and testing more combinations of access points, client devices and operating conditions.
The Wi-Fi Alliance will also need to establish its certification program and associated testing procedures. A successful Intel-Broadcom demonstration does not replace that process.
The October demonstration is an encouraging indication that the ecosystem is moving beyond individual prototype development toward cross-vendor interoperability. Nevertheless, a single successful demonstration does not establish full interoperability across the many device configurations, operating conditions and features contemplated by IEEE 802.11bn.
Conclusions:
Wi-Fi 8 represents an important evolution in wireless LAN technology. Its emphasis on Ultra High Reliability, improved spectrum utilization, lower latency and more consistent performance addresses practical shortcomings that cannot necessarily be solved by simply increasing channel bandwidth or peak data rates.
The Intel-Broadcom demonstration of IEEE 802.11bn-based equipment, particularly its use of Non-Primary Channel Access, provides an early indication of how these improvements may be achieved. This demo marks a development milestone, but the reported measurement results are not yet finalized Wi-Fi 8 performance numbers.
Three separate milestones will determine progress toward commercial Wi-Fi 8 deployment:
- IEEE standardization: Completion and approval of the P802.11bn UHR amendment.
- Cross-vendor interoperability: Continued testing by chipset and equipment manufacturers, including Intel and Broadcom, to establish that independently developed implementations work together.
- Industry certification: Development of Wi-Fi 8 certification and testing programs by the Wi-Fi Alliance.
The ultimate measure of Wi-Fi 8’s success will not be its theoretical maximum speed, but whether it delivers more reliable, predictable and efficient wireless connectivity in real-world deployments.
References:
https://standards.ieee.org/ieee/802.11bn/11393/
https://www.ieee802.org/11/Reports/tgbn_update.htm
https://www.ieee802.org/11/Reports/802.11_Timelines.htm
https://ieee802.org/11/email/stds-802-11/msg09578.html
Broadcom with Samsung Electronics: Integrated 5G and Wi-Fi 8 FWA Platform
Analysis: Broadcom’s end-to-end 50G PON Edge AI portfolio with WiFi 8 support
Qualcomm FastConnect 7800 combining WiFi 7 and Bluetooth in single chip
Orange, Nokia, Nvidia, and Intel debate: ASICs vs. GPUs vs. General-Purpose CPUs for RAN Baseband Processing
For Orange CTO Laurent Leboucher, the main attraction of AI today lies in its potential to improve the efficiency of 5G radio access networks (RANs). That helps explain Orange’s recent collaboration with Nokia and Nvidia. Orange already deploys Nokia’s purpose-built 5G network equipment and software at mobile sites in France and other markets. Until recently, it had little obvious need for Nvidia, the U.S. chip making king best known for the graphics processing units (GPUs) used to train large language models. But Nokia and Nvidia became closely aligned last October, when Nvidia took a 3% stake in Nokia as part of a $1 billion investment. Nokia is now developing AI RAN software designed to run on GPUs.
Leboucher’s interest is driven in part by concerns over the cost of custom silicon — the application-specific integrated circuits (ASICs) used in purpose-built 5G networks. “It creates an opportunity to bring a general-purpose chipset instead of an ASIC implementation,” he told Light Reading at last week’s FutureNet World event in London. “I think we could, at some point, benefit from the economies of scale of new chipsets. That could be Nvidia.”
The rationale is much easier to understand than arguments about 5G for autonomous vehicles. Chip manufacturing is already expensive, and both Nokia and Ericsson expect component costs to rise further this year amid relentless AI demand. At the same time, the RAN market remains relatively small and has contracted. According to market research firm Omdia, telco spending fell from $45 billion in 2022 to $35 billion last year and is expected to stay at that level. In that context, it is increasingly difficult to justify designing high-cost chips with limited reuse outside telecom.

Image Credit: Orange
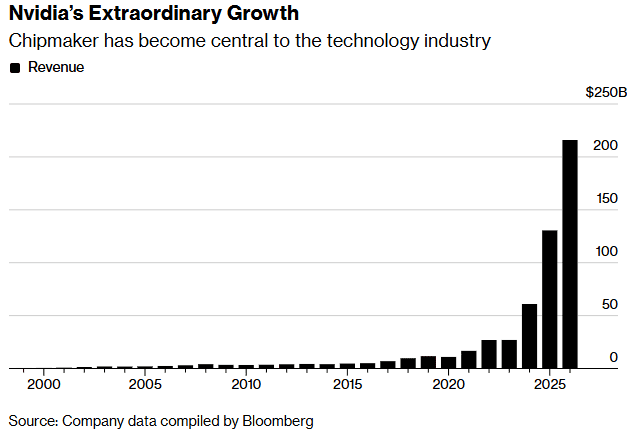
Last year, Nvidia spent about $18.5 billion on research and development, generated nearly $216 billion in revenue, and reported a gross margin of more than 70%. Its financial strength is not in question. If telecom operators can use its GPUs for RAN software, they may face less pressure to secure the long-term economics of 5G and 6G development. That alone could be enough to support the case for Nvidia. The counterarguments are cost and power consumption. By design, custom silicon is optimized for a specific workload and will always outperform a more general-purpose processor at that task. An Nvidia GPU in the RAN could therefore be seen as excessive — like using a crop duster to water a hanging basket.
Leboucher, believes that Nokia and Nvidia are developing something far more compact than a typical data-center deployment. “It is not a Blackwell GPU,” he said, referring to Nvidia’s current hyperscaler-class product line. “I have an understanding it’s something which is a little bit smaller.” One of the first GPU-based products is expected to come on a card that Orange can insert into an existing Nokia AirScale chassis.
He is also interested in replacing traditional RAN algorithms with AI to improve spectral efficiency and overall performance. Through trials with Nokia and Nvidia, Orange wants to determine whether a GPU is actually required to capture the full benefit. “We can completely rethink the way we are doing algorithms today, using AI for the radio Layer 1,” he said, referring to the most compute-intensive part of the RAN software stack. Some of the “AI-RAN” narrative still sounds “a little bit like science fiction,” Leboucher admitted. “But I think there are some very interesting ideas behind that. We want to understand where we are.”
This is not the first time the industry has debated a shift from ASICs to general-purpose processors for RAN equipment. Alongside its purpose-built 5G portfolio, Ericsson already offers cloud RAN products based on Intel CPUs. Samsung is now focused on Intel-based virtual RAN and has recently predicted the end of purpose-built 5G. Even so, cloud and virtual RAN still account for only a small share of live 5G deployments. Huawei and Ericsson, the two largest RAN vendors, remain committed to custom silicon development.
Nvidia’s entry into the market has clearly given Leboucher and his team more to evaluate as RAN technology becomes more sophisticated. “We are introducing new requirements for radio networks, typically for beamforming, and we have to consider the need for quite powerful chipsets,” he said. “Whether the best way to keep going is using ASICs or a general-purpose architecture – I think this is a good time to ask the question. Before, it was too early.”
The answer could shape Orange’s next major RAN decisions. The operator is preparing for what Leboucher describes as a “refresh” of RAN equipment across several countries ahead of the expected 6G launch in 2030. For the first time, he said, Orange will include cloud RAN as a “major option” in its request for proposal.
The concern around Intel as an alternative to Nvidia is its still-fragile financial position. Before December, Intel had been trying to spin off its network and edge group (NEX), which develops RAN chips. Those plans were later shelved, but the company’s net loss widened to about $4.3 billion in the most recent first quarter, from $887 million a year earlier, while revenue rose only 7% year over year to $13.6 billion. Cristina Rodriguez, who had led NEX, left this month to join Coherent, and Intel has not yet named a successor. “The shares jumped 28% in after-hours trading, taking Intel firmly into meme-stock territory,” said Radio Free Mobile analyst Richard Windsor in a blog published after results came out on April 23. “I say meme-stock because there is no other way to describe it when the shares are on a 2026 PER [price-to-earnings ratio] of 137x, and its technology looks obsolete.”
Orange places significant value on separating hardware from software, allowing the same RAN software to run across multiple hardware platforms. Ericsson and Samsung both say the virtual RAN software they have built for Intel CPUs could, with relatively modest changes, be ported to AMD silicon using the same x86 architecture or to Arm-based CPUs.
By contrast, Layer 1 code written for Nvidia GPUs and the CUDA software stack would not be portable to other platforms, according to Ericsson. “I think the main challenge we see with that is we are trying very hard to keep our stack portable, to give hardware options,” Michael Begley, Ericsson’s head of RAN compute, told Light Reading at MWC Barcelona this year. “If you go all in on one, it’s great, but you’re all in on one, and you can’t offer those other options to the operators or the ecosystem.”
Leboucher acknowledges that risk. “The risk of lock-in exists, definitely,” he said. “We really want to stay open. At the same time, we know that benefiting from a very, very large-scale general-purpose architecture should improve the TCO [total cost of ownership]. At the end of the day, it will be a trade-off. But we would welcome an architecture where we have the capacity at some point to decide to swap if we need to swap.”
Nokia’s hope is that much of the Layer 1 software written for Nvidia GPUs will eventually be deployable on other GPU platforms. But Nvidia’s near-monopoly in that segment leaves the industry with few alternatives for now. There is also optimism inside Nokia that GPU-based code could later be adapted for capable CPUs, although Ericsson’s comments suggest that would be much harder. For telecom executives, the choices made over the next couple of years may be pivotal as 6G approaches.
………………………………………………………………………………………………………………………………………………………
References:
https://www.lightreading.com/5g/orange-weighs-nvidia-against-intel-for-5g-chips-ahead-of-new-rfp
RAN Silicon Rethink- Part II; vRAN and General-Purpose Compute
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
Analysis: Nokia and Marvell partnership to develop 5G RAN silicon technology + other Nokia moves
Analysis: Nvidia’s $2 billion investment in Marvell; NVLink Fusion ecosystem & RAN vendor silicon strategy
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Marvell shrinking share of the RAN custom silicon market & acquisition of XConn Technologies for AI data center connectivity
Custom AI Chips: Powering the next wave of Intelligent Computing
OpenAI and Broadcom in $10B deal to make custom AI chips
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Big Tech AI spending binge results in massive job cuts!
AT&T and Ericsson boost Cloud RAN performance with AI-native software running on Intel Xeon 6 SoC
Overview:
AT&T and Ericsson have completed a milestone Cloud RAN test by successfully demonstrating Ericsson’s AI-native Link Adaptation [1.] on a Cloud RAN stack powered by Intel Xeon 6 SoC. The test showed how artificial intelligence (AI) can improve spectral efficiency and network responsiveness in real-world conditions. Conducted over AT&T’s licensed frequency bands, the experiment was the first to use portable Ericsson RAN software running on Intel’s new Xeon 6 system-on-chip (SoC) platform—an architecture designed for high-performance, cloud-native processing of RAN workloads. Engineered specifically for network and edge deployments, Intel Xeon 6 SoC delivers breakthrough AI RAN performance with built-in acceleration. Integrated Intel Advanced Vector Extensions (AVX) and Intel Advanced Matrix Extension (AMX) technologies eliminate the need for discrete accelerators while maximizing capacity, efficiency, and TCO optimization.
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………..
Note 1. AI-native Link Adaptation dynamically adjusts to changes in signal quality and interference, boosting RAN performance on purpose-built and cloud-based infrastructure alike.
Other Notes:
-
vRAN: A radio access network (RAN) in which the baseband processing functions run as software on general-purpose processors (mostly from Intel) instead of on dedicated hardware at the cell site. In vRAN, the functional split defines how baseband processing is divided between centralized processors and the radio unit at the site, and that split drives fronthaul bandwidth, latency, and cost.
- Cloud RAN: An evolution of vRAN where those same RAN functions are re-architected as cloud‑native microservices/containers with CI/CD (Continuous Integration and either Continuous Delivery or Continuous Deployment), automation, and orchestrators, optimized for elastic scaling across distributed cloud infrastructure.
- Ericsson Cloud RAN is a cloud native software solution that handles compute functionality in the RAN. It virtualizes RAN functions on Commercial Off The Shelf (COTS) hardware, decoupling software from hardware to enable more flexible, scalable, and efficient network deployments.
- According to Dell’Oro Group, Cloud RAN (often encompassing vRAN) accounted for approximately 5% to 10% of the total global Radio Access Network (RAN) market revenues in 2025. In early 2026, Dell’Oro revised Cloud RAN projections downward. While virtualization remains a “key pillar” for the long term, short-term adoption is being slowed by performance, power, and cost-parity challenges when compared to purpose-built hardware.
- The total RAN market stabilized in late 2025 after losing approximately 20% of its value between 2022 and 2024. Market concentration reached a 10-year high in 2025, with the top five vendors (Huawei, Ericsson, Nokia, ZTE, and Samsung) capturing 96% of the revenue.
………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………..

Image Credit: Ericsson
In this proof-of-concept setup, Ericsson’s disaggregated and containerized RAN software operated within AT&T’s target Cloud RAN configuration, built on open, commercial off-the-shelf hardware. The test advanced from basic call functionality to validation of feature-rich network behavior in a cloud computing environment. Ericsson’s AI-native Link Adaptation is a learning algorithm that continuously assesses channel state and interference to determine the optimal modulation and coding scheme for each transmission interval. By generating real-time predictions of link quality, the AI model dynamically adjusts data rates to maximize throughput and spectral efficiency.
Early results were promising. Throughput gains reached up to 20% compared with conventional rule-based link adaptation approaches, alongside measurable improvements in spectral efficiency. Ericsson and Intel also used the trial to benchmark various AI inference models, demonstrating performance scalability and energy efficiency on general-purpose compute nodes rather than proprietary hardware accelerators. This suggests a more pragmatic path for deploying AI workloads across distributed RAN architectures.
AI-native Link Adaptation dynamically adjusts to changes in signal quality and interference, boosting RAN performance on purpose-built and cloud-based infrastructure alike.
Ericsson Cloud RAN is a cloud native software solution that handles compute functionality in the RAN. It virtualizes RAN functions on Commercial Off The Shelf (COTS) hardware, decoupling software from hardware to enable more flexible, scalable, and efficient network deployments.
Engineered specifically for network and edge deployments, Intel Xeon 6 SoC delivers breakthrough AI RAN performance with built-in acceleration. Integrated Intel Advanced Vector Extensions (AVX) and Intel Advanced Matrix Extension (AMX) technologies eliminate the need for discrete accelerators while maximizing capacity, efficiency, and TCO optimization.
Beyond the immediate performance improvements, the trial illustrates how open RAN architectures can accelerate innovation. By decoupling RAN software from vendor-specific hardware, AT&T can integrate AI capabilities and update network functions more quickly, avoiding the constraints of lock-in. The portability demonstrated here—running production-grade Ericsson RAN software on Intel Xeon 6 silicon—marks an industry first.
For AT&T, the achievement represents more than a lab milestone. It provides a technical template for scaling AI-native RAN functions into its cloud infrastructure, pointing to a future where machine learning operates natively within radio environments to fine-tune performance in real time. As operators continue balancing cost, flexibility, and efficiency, AI-optimized Cloud RAN deployments could become the next competitive frontier in 5G—and eventually, 6G—network evolution.
………………………………………………………………………………………………………………………………………………………………………………………………………………………..
Quotes:
Rob Soni, Vice President, RAN Technology at AT&T, says: “AT&T is leading the charge toward an open, intelligent, and scalable network future by advancing Open RAN and Cloud RAN with AI-native capabilities at their core. This demo highlights how AI capabilities, powered by our next-generation Cloud RAN platform, can be deployed seamlessly to drive innovation and deliver superior customer experiences.”
Mårten Lerner, Head of Networks Strategy and Product Management, Business Area Networks at Ericsson, says: “Together with AT&T and Intel, Ericsson is demonstrating how our domain expertise combined with AI-native RAN software can drive transformative advancements in both Cloud RAN and purpose-built deployments. Our industry-leading AI-native Link Adaptation serves as the first proof point on this journey. With a hardware-agnostic RAN software stack, Ericsson is committed to offering maximum flexibility and enabling all our customers to benefit from future innovations – regardless of their chosen underlying hardware. This milestone underscores Ericsson’s commitment to helping operators advance their networks by deploying AI functionality across the RAN stack.”
Cristina Rodriguez, VP and GM, Network and Edge at Intel, says: “This successful collaboration with AT&T and Ericsson showcases the power of Intel Xeon 6 SoC to enable and accelerate AI workloads in Cloud RAN environments. Xeon 6 SoC is architected to handle the demanding compute requirements of AI-native network functions, delivering the performance and efficiency operators need to unlock the full potential of intelligent networks. By providing a flexible, standards-based platform, Intel Xeon 6 enables service providers like AT&T to deploy innovative AI capabilities while maintaining the openness and choice that drive industry innovation.”
………………………………………………………………………………………………………………………………………………………………………………………………………………………….
AI-Native Link Adaptation vs. Traditional Methods:
Traditional link adaptation in RAN relies on deterministic, rule-based algorithms that select the Modulation and Coding Scheme (MCS) from predefined lookup tables. These methods primarily use instantaneous Channel Quality Indicator (CQI) reports or estimated Signal-to-Interference-plus-Noise Ratio (SINR) thresholds, often adjusted via Outer Loop Link Adaptation (OLLA) based on ACK/NACK feedback from the UE. This reactive approach applies conservative margins to account for channel estimation errors, prediction lag, and varying interference, which can lead to suboptimal throughput—either underutilizing the link with low MCS or triggering excess HARQ retransmissions with overly aggressive selections.
AI-native Link Adaptation shifts to a predictive, model-driven paradigm using machine learning (typically lightweight neural networks or time-series models) trained on historical channel data. Rather than static thresholds, the AI processes sequences of CQI, beam metrics, mobility patterns, and interference traces to forecast the probable channel state for the next transmission time interval (TTI). This enables precise MCS selection that hugs the Shannon capacity limit more closely, minimizing BLER while maximizing spectral efficiency in dynamic scenarios like high-mobility NLOS or bursty interference.
Key differences include:
| Aspect | Traditional (Rule-Based) | AI-Native (ML-Based) |
|---|---|---|
| Decision Mechanism | Lookup tables, SINR thresholds, OLLA offsets | Real-time inference from ML models |
| Channel Handling | Reactive (past CQI/SINR) | Predictive (time-series forecasting) |
| Adaptation Speed | Step-wise, with feedback lag | Continuous, sub-TTI granularity |
| Performance Gains | Baseline (0% reference) | Up to 20% throughput, 10% spectral efficiency |
| Compute Needs | Low (fixed arithmetic) | Moderate (edge inference on COTS like Xeon 6) |
| Limitations | Struggles with non-stationary channels | Requires training data, retraining overhead |
Analysis: Rakuten Mobile and Intel partnership to embed AI directly into vRAN
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
vRAN market disappoints – just like OpenRAN and mobile 5G
Nokia and Eolo deploy 5G SA mmWave “Cloud RAN” network
Ericsson and Google Cloud expand partnership with Cloud RAN solution
Ericsson and O2 Telefónica demo Europe’s 1st Cloud RAN 5G mmWave FWA use case
Cloud RAN with Google Distributed Cloud Edge; Strategy: host network functions of other vendors on Google Cloud
vRAN market disappoints – just like OpenRAN and mobile 5G
Ericsson and Intel collaborate to accelerate AI-Native 6G; other AI-Native 6G advancements at MWC 2026
Ericsson and Intel at MWC 2026:
Building on milestones in Cloud RAN, 5G Core, and open network innovation, Ericsson and Intel are showcasing joint technology advancements at the Mobile World Congress (MWC) 2026 in Barcelona this week. Demonstrations can be experienced at the Ericsson Pavilion (Hall 2), Intel Booth (Hall 3, Stand 3E31), and across partner event spaces, highlighting the companies’ shared progress in enabling the next era of AI-driven networks.
The two companies are strengthening their long-standing technology partnership to accelerate ecosystem readiness for AI-native 6G networks and use cases. The expanded collaboration spans next-generation mobile connectivity, cloud infrastructure, and compute acceleration — with a focus on AI-driven RAN and packet core evolution, platform-level security, and scalable cloud-native architectures designed to shorten time-to-market for advanced network solutions.
“6G is not merely an iteration of mobile technology; it will serve as the foundational infrastructure distributing AI across devices, the edge, and the cloud,” said Börje Ekholm, President and CEO of Ericsson. “With our deep history in network innovation and global-scale operator deployments, Ericsson is uniquely positioned to drive practical 6G integration from research to commercialization.”
Lip-Bu Tan, CEO of Intel, added: “Intel’s vision is to lead the industry in unifying RAN, Core, and edge AI to enable seamless deployment of AI-native 6G environments. Together with Ericsson, we are proving that next-generation connectivity can be open, energy-efficient, secure, and intelligent. With future Ericsson Silicon built on Intel’s most advanced process technologies, coupled with Intel Xeon-powered AI-RAN ready Cloud RAN and collaborative multi-year research efforts, we are delivering the performance, efficiency, and supply assurance demanded by leading operators worldwide.”
As 6G transitions from research to commercialization, the industry must align around a mature, standards-based ecosystem. The Ericsson–Intel collaboration aims to accelerate development of high-performance, energy-efficient compute architectures optimized for both AI for Networks and Networks for AI.
AI-native 6G will fuse intelligent, programmable network functions with distributed compute and real-time sensing, bringing processing power closer to the network edge and enabling ultra-responsive, adaptive services. This convergence will enhance network efficiency, agility, and service intelligence across future deployments.
About Ericsson:
Ericsson‘s high-performing networks provide connectivity for billions of people every day. For 150 years, we’ve been pioneers in creating technology for communication. We offer mobile communication and connectivity solutions for service providers and enterprises. Together with our customers and partners, we make the digital world of tomorrow a reality.
About Intel:
Intel is an industry leader, creating world-changing technology that enables global progress and enriches lives. Inspired by Moore’s Law, we continuously work to advance the design and manufacturing of semiconductors to help address our customers’ greatest challenges. By embedding intelligence in the cloud, network, edge and every kind of computing device, we unleash the potential of data to transform business and society for the better.
…………………………………………………………………………………………………………………………………………………………
Related AI-Native 6G Announcements at MWC 2026:

In addition to the Ericsson-Intel collaboration, several vendors and operators announced AI-native 6G advancements or related demos at MWC Barcelona 2026. These initiatives emphasize AI-RAN integration, software-defined architectures, and ecosystem partnerships to bridge 5G-A to 6G.
NVIDIA Multi-Partner Commitment: NVIDIA rallied operators and vendors including Booz Allen, BT Group, Cisco, Deutsche Telekom, Ericsson, Nokia, SK Telecom, SoftBank, and T-Mobile to build open, secure AI-native 6G platforms. The focus is on software-defined wireless with AI embedded in RAN, edge, and core for integrated sensing, communications, and interoperability.
Nokia AI-RAN: Nokia highlighted new partnerships with Dell, Quanta, Red Hat, SuperMicro, NVIDIA, and operators like T-Mobile, Indosat Ooredoo Hutchison, BT, Elisa, NTT DOCOMO, and Vodafone for AI-RAN trials paving the way to cognitive 6G networks. Live demos at Nokia’s Hall 3 Booth 3B20 included Southeast Asia’s first AI-RAN Layer 3 5G call on shared GPU infrastructure and vision AI for immersive services.
T-Mobile & Deutsche Telekom Hub: T-Mobile US and (major shareholder) Deutsche Telekom launched a joint 6G Innovation Hub targeting AI-native autonomous networks, secure sensing/positioning, and connectivity-compute convergence for Physical AI. It builds on agentic AI proofs like network-integrated translation, emphasizing “kinetic tokens” for real-time physical world control.
ZTE GigaMIMO 6G Prototype: ZTE unveiled the world’s first 6G prototype with 2000+ U6G-band antenna elements (GigaMIMO), powered by AI algorithms for 10x capacity over 5G-A, 30% spectral efficiency gains, and AI-driven immersive services. Booth 3F30 demos integrate AI across connectivity, computing, and devices for “AI serves AI” networks.
Qualcomm Agentic AI RAN: Qualcomm announced AI-native RAN management services in its Dragonwing suite for autonomous 6G-grade networks, plus new Open RAN AI features for performance optimization. CEO Cristiano Amon’s keynote focused on “Architecting 6G for the AI Era,” with device-to-data-center transformations.
Huawei U6GHz for 6G Path:
Huawei released all-scenario U6GHz products (macro/micro sites, microwave) with AI-centric solutions for 5G-A capacity (100 Gbps downlink) and low-latency AI apps, enabling smooth 6G evolution. Emphasizes hyper-resolution MU-MIMO and multi-band coordination for indoor/outdoor AI experiences.
Summary Chart:
| Vendor/Operator | Key Focus | Partners/Demos | Booth/Location |
|---|---|---|---|
| NVIDIA | Open AI-native platforms | Multiple operators/vendors | MWC general |
| Nokia | AI-RAN trials & cognitive networks | NVIDIA, T-Mobile, IOH et al. | Hall 3, 3B20 |
| T-Mobile/DT | Physical AI hub | Joint R&D | Announced pre-MWC |
| ZTE | GigaMIMO 6G prototype | China Mobile, Qualcomm | Hall 3, 3F30 |
| Qualcomm | Agentic RAN automation | Open RAN ecosystem | Keynote & demos |
| Huawei | U6GHz AI-centric evolution | Carrier-focused | MWC showcase |
…………………………………………………………………………………………………………………………………………………………………………………….
References:
NVIDIA and global telecom leaders to build 6G on open and secure AI-native platforms + Linux Foundation launches OCUDU
Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020)
SKT 6G ATHENA White Paper: a mid-to-long term network evolution strategy for the AI era
Dell’Oro: RAN Market Stabilized in 2025 with 1% CAG forecast over next 5 years; Opinion on AI RAN, 5G Advanced, 6G RAN/Core risks
Nokia and Rohde & Schwarz collaborate on AI-powered 6G receiver years before IMT 2030 RIT submissions to ITU-R WP5D
SK Telecom, DOCOMO, NTT and Nokia develop 6G AI-native air interface
Market research firms Omdia and Dell’Oro: impact of 6G and AI investments on telcos
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Dell’Oro: Analysis of the Nokia-NVIDIA-partnership on AI RAN
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
Intel and AI chip startup SambaNova partner; SN50 AI inferencing chip max speed said to be 5X faster than competitive AI chips
Intel and AI chip startup SambaNova have entered into a multi-year strategic collaboration to deploy high-performance, cost-efficient AI inference solutions [1.] tailored for AI-native firms, enterprises, and government sectors. This global initiative leverages Intel® Xeon® infrastructure, with Intel Capital further signaling commitment through participation in SambaNova’s $350M Series E financing round. The collaboration will give customers a powerful alternative to GPU‑centric solutions, offering optimized performance for leading open‑source models with predictable throughput and total cost of ownership. Founded in 2017, the Palo Alto, CA company specializes in AI chips and software. SambaNova’s Chairman is Lip-Bu Tan, who is also the CEO of Intel!
Note 1. AI inferencing is the process of using a trained AI model to make real-time predictions, decisions, or generate content from new, previously unseen data. It transforms inputs (a query, image, sensor reading) into useful results (a sentence, classification, alert). Unlike training and language models, inference is about prompt execution, often requiring low-latency (speed) and high efficiency. AI Inference chips have attracted intense investor interest following a wave of deal making around rivals to Nvidia, as AI companies seek faster and more efficient hardware. See References below for more information.
………………………………………………………………………………………………………………………………………………………………………………………………………………………………….
For high-scale AI workloads, the integration of Intel CPUs with SambaNova’s specialized AI platform was said to offer a high-efficiency rack-level inference alternative. This partnership serves as a strategic bridge as Intel scales its independent GPU-based offerings. Intel remains fully committed to its internal GPU roadmap, continuing aggressive investment across architecture, software, and systems. This collaboration enhances Intel’s edge-to-cloud strategy without altering its competitive trajectory in the GPU market. By combining Xeon processors, Intel networking, and SambaNova systems, the two companies are positioned to capture a significant share of the multi-billion-dollar inference market through heterogeneous data center architectures.
As part of the collaboration, Intel plans to make a strategic investment in SambaNova to accelerate the rollout of an Intel‑powered AI cloud. The collaboration is expected to span three key areas:
- AI Cloud Expansion – Scaling SambaNova’s vertically integrated AI cloud, built on Intel Xeon‑based infrastructure and optimized for large language and multimodal models. The platform will deliver low‑latency, high‑throughput AI services, supported by reference architectures, deployment blueprints, and partnerships with system integrators and software vendors.
- Integrated AI Infrastructure – Combining SambaNova’s systems with Intel’s CPUs, accelerators, and networking technologies to power scalable, production‑ready inference for reasoning, code generation, multimodal applications, and agentic workflows.
- Go‑to‑Market Execution – Joint co‑selling and co‑marketing through Intel’s global enterprise, cloud, and partner channels to accelerate adoption across the AI ecosystem.
Together, SambaNova and Intel aim to shape the next generation of heterogeneous AI data centers — integrating Intel Xeon processors, Intel GPUs, Intel networking and storage, and SambaNova systems — to unlock a multi‑billion‑dollar inference market opportunity.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………
SambaNova also announced its SN50 AI chip, which boasts a max speed that’s 5X faster than competitive chips, according to the company.
Image Credit: SambaNova
Positioned as the most efficient chip for agentic AI, the SN50 chip offers enterprises a 3X lower total cost of ownership – a powerful foundation to scale fast inference and bring autonomous AI agents into full production. The SN50 will be shipping to customers later this year. To quickly scale and distribute SN50, SambaNova is collaborating with Intel, and has obtained $350 million in strategic Series E financing to expand manufacturing and cloud capacity.
“AI is no longer a contest to build the biggest model,” said Rodrigo Liang, co‑founder and CEO of SambaNova. “With the SN50 and our deep collaboration with Intel, the real race is about who can light up entire data centers with AI agents that answer instantly, never stall, and do it at a cost that turns AI from an experiment into the most profitable engine in the cloud.”
“Customers are asking for more choice and more efficient ways to scale AI,” said Kevork Kechichian, EVP, General Manager, Data Center Group, Intel. “By combining Intel’s leadership in compute, networking, and memory with SambaNova’s full-stack AI systems and inference cloud platform, we are delivering a compelling option for organizations looking for GPU alternatives to deploy advanced AI at scale.”
The SN50 delivers five times more compute per accelerator and four times more network bandwidth than the previous generation. It links up to 256 accelerators over a multi‑terabyte‑per‑second interconnect, cutting time‑to‑first‑token and supporting larger batch sizes. The result: Enterprises can deploy bigger, longer‑context AI models with higher throughput and responsiveness — while keeping performance high and costs and latency under control.
“AI is moving from a software story to an infrastructure story,” said Landon Downs, co-founder and managing partner at Cambium Capital. “SN50 is engineered for the real-world latency and economic requirements that will determine who successfully deploys agentic AI at scale.”
Built on SambaNova’s Reconfigurable Data Unit (RDU) architecture, SN50 delivers:
- Instant AI Experiences – Ultra‑low latency delivers real‑time responsiveness for next‑gen enterprise apps like voice assistants.
- Unmatched Scale and Concurrency – Power thousands of simultaneous AI sessions with consistent high performance.
- Breakthrough Model Capacity – Three‑tier memory architecture unlocks 10T+ parameter models and 10M+ context lengths for deeper reasoning and richer outputs.
- Maximum Efficiency at Scale – Higher hardware utilization lowers cost‑per‑token, driving greater performance and ROI.
- Smarter Memory, Smarter Efficiency – Resident multi‑model memory and agentic caching optimize the three‑tier architecture, cutting infrastructure costs for enterprise‑scale AI deployments.
“The new SambaNova SN50 RDU changes the tokenomics of AI inference at scale. By delivering both high performance and high throughput with a chip that uses existing power and is air cooled, SambaNova is changing the game,” said Peter Rutten, Research Vice-President Performance Intensive Computing at analyst firm IDC.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………
SoftBank Corp. will be the first customer to deploy SN50 within its next‑generation AI data centers in Japan. The deployment will power low‑latency inference services for sovereign and enterprise customers across Asia‑Pacific, supporting both open‑source and proprietary frontier models with aggressive latency and throughput requirements.
“With SN50, we are building an AI inference fabric for Japan that can serve our customers and partners with the speed, resiliency and sovereignty they expect from SoftBank,” said Hironobu Tamba, Vice President and Head of the Data Platform Strategy Division of the Technology Unit at SoftBank Corp. “By standardizing on SN50, we gain the ability to deliver world‑class AI services on our own terms — with the performance of the best GPU clusters, but with far better economics and control.”
The SN50 deployment deepens SambaNova’s existing relationship with SoftBank Corp., which already hosts SambaCloud to provide ultra‑fast inference for developers in the region. By anchoring its newest clusters on SN50, SoftBank positions SambaNova as the inference backbone for its sovereign AI initiatives and future large‑scale agentic services.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………
References:
Nvidia AI-RAN survey results; AI inferencing as a reinvention of edge computing?
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Groq and Nvidia in non-exclusive AI Inference technology licensing agreement; top Groq execs joining Nvidia
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Custom AI Chips: Powering the next wave of Intelligent Computing
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
OpenAI and Broadcom in $10B deal to make custom AI chips
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
U.S. export controls on Nvidia H20 AI chips enables Huawei’s 910C GPU to be favored by AI tech giants in China
Superclusters of Nvidia GPU/AI chips combined with end-to-end network platforms to create next generation data centers
Analysis: Rakuten Mobile and Intel partnership to embed AI directly into vRAN
Today, Rakuten Mobile and Intel announced a partnership to embed Artificial Intelligence (AI) directly into the virtualized Radio Access Network (vRAN) stack. While vRAN currently represents a small percentage of the total RAN market (Dell’Oro Group recently forecasts vRAN to account for 5% to 10% of the total RAN market by 2026), this partnership could boost increase that percentage as it addresses key adoption hurdles—performance, power, and AI integration. Key areas of innovation include:
- Enhanced Wireless Spectral Efficiency: Optimizing spectrum utilization for superior network performance and capacity.
- Automated RAN Operations: Streamlining network management and reducing operational complexities through intelligent automation.
- Optimized Resource Allocation: Dynamically allocating network resources for maximum efficiency and subscriber experience.
- Increased Energy Efficiency: Significantly reducing power consumption in the RAN, contributing to sustainable network operations.
The partnership essentially aims to make vRAN superior in performance and TCO (Total Cost of Ownership) compared to traditional, proprietary, purpose built RAN hardware.
“We are incredibly excited to expand our collaboration with Intel to pioneer truly AI-native RAN architectures,” said Sharad Sriwastawa, co-CEO and CTO, Rakuten Mobile. “Together, we are validating transformative AI-driven innovations that will not only shape but define the future of mobile networks. This partnership showcases how intelligent RAN can be achieved through the seamless and efficient integration of AI workloads directly within existing vRAN software stacks, delivering unparalleled performance and efficiency.”
Rakuten Mobile and Intel are engaged in rigorous testing and validation of cutting-edge RAN AI use cases across Layer 1, Layer 2, and comprehensive RAN operation and network platform management. A core objective is the seamless integration of AI directly into the RAN stack, meticulously addressing integration challenges while upholding carrier-grade reliability and stringent latency requirements.
Utilizing Intel FlexRAN reference software, the Intel vRAN AI Development Kit, and a robust suite of AI tools and libraries, Rakuten Mobile is collaboratively training, optimizing, and deploying sophisticated AI models specifically tailored for demanding RAN workloads. This collaborative effort is designed to realize ultra-low, real-time AI latency on Intel Xeon 6 SoC, capitalizing on their built-in AI acceleration capabilities, including AVX512/VNNI and AMX.
“AI is transforming how networks are built and operated,” said Kevork Kechichian, Executive Vice President and General Manager of the Data Center Group, Intel Corporation. “Together with Rakuten, we are demonstrating how AI benefits can be achieved in vRAN. Intel Xeon processors power the majority of commercial vRAN deployments worldwide, and this transformation momentum continues to accelerate. Intel is providing AI-ready Xeon platforms that allow operators like Rakuten to design AI-ready infrastructure from the ground up, with built-in acceleration capabilities.”
Rakuten says they are “poised to unlock new levels of RAN performance, efficiency, and automation by embedding AI directly into the RAN software stack, this AI-native evolution represents the future of cloud-native, AI-powered RAN – inherently software-upgradable and built on open, general-purpose computing platforms. Additionally, the extended collaboration between Rakuten Mobile and Intel marks a significant step toward realizing the vision of autonomous, self-optimizing networks and powerfully reinforces both companies’ commitment to open, programmable, and intelligent RAN infrastructure worldwide.”
……………………………………………………………………………………………………………………………………………………………………..
- AI-Native Efficiency & Performance: The collaboration focuses on integrating AI to improve network performance and energy efficiency, which is a major pain point for operators. By embedding AI directly into the vRAN stack, they are enhancing wireless spectral efficiency, reducing power consumption, and automating RAN operations.
- Leveraging High-Performance Hardware: The initiative utilizes Intel® Xeon® 6 processors with built-in vRAN Boost. This eliminates the need for external, power-hungry accelerator cards, offering up to 2.4x more capacity and 70% better performance-per-watt.
- Validation of Large-Scale Commercial Viability: Rakuten Mobile operates the world’s first fully virtualized, cloud-native network. Its continued collaboration with Intel to make the vRAN AI-native provides a proven blueprint for other operators, reducing the perceived risk of adopting vRAN, particularly in brownfield (existing) networks.
- Acceleration of Open RAN Ecosystem: The collaboration supports the broader push towards Open RAN, which is expected to see a significant rise in market share, doubling between 2022 and 2026.
………………………………………………………………………………………………………………………………………………………………
- Market Share Shift: Omdia forecasts that vRAN’s share of the RAN baseband subsector will reach 20% by 2028. That’s a significant jump from its current low single-digit percentage.
- Explosive CAGR: The global vRAN market is projected to grow from approximately $16.6 billion in 2024 to nearly $80 billion by 2033, representing a 19.5% CAGR.
- Small Cell Dominance: By the end of 2026, it is estimated that 77% of all vRAN implementations will be on small cell architectures, a key area where Rakuten and Intel have demonstrated success.
References:
https://corp.mobile.rakuten.co.jp/english/news/press/2026/0210_01/
Virtual RAN gets a boost from Samsung demo using Intel’s Grand Rapids/Xeon Series 6 SoC
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
vRAN market disappoints – just like OpenRAN and mobile 5G
LightCounting: Open RAN/vRAN market is pausing and regrouping
Dell’Oro: Private 5G ecosystem is evolving; vRAN gaining momentum; skepticism increasing
https://www.mordorintelligence.com/industry-reports/virtualized-ran-vran-market
https://www.grandviewresearch.com/industry-analysis/virtualized-radio-access-network-market-report
Virtual RAN gets a boost from Samsung demo using Intel’s Grand Rapids/Xeon Series 6 SoC
Samsung is the fifth largest worldwide RAN equipment vendor, behind Huawei, Ericsson, Nokia and ZTE. This week, the South Korean conglomerate claimed to have reached a virtual RAN (vRAN) milestone with the completion of a commercial phone call using Granite Rapids – Intel’s Xeon 6700P-B SoC processor series. The call took place on the network of a large, undisclosed U.S. network operator, but apparently Verizon. Samsung said, “this builds upon the company’s previous achievement in 2024, when it completed the industry-first end-to-end call in a lab environment with Intel Xeon 6 SoC.”
Samsung’s cloud-native vRAN with Intel’s latest Xeon SoC ran on a single commercial off-the-shelf (COTS) server from Hewlett Packard Enterprise with a cloud platform from Wind River. This milestone, coming only a few months after the first wave of Intel Xeon 6 SoC was made commercially available, presents an innovative pathway for single-server vRAN deployments for next-generation networks.
The commercial readiness of vRAN technology promises to give network operators the ability to run RAN and AI workloads on fewer, more powerful servers.
Samsung wrote: “As operators accelerate their transition to software-driven, flexible architectures while seeking more sustainable infrastructure, the ability to run RAN and AI workloads on fewer, more powerful servers becomes critical, On a single server of Samsung’s AI-powered vRAN with enhanced processors, operators can consolidate software-driven network elements such as mobile core, radio access, transport and security, which traditionally required multiple servers, significantly simplifying the management of complex site configuration.”
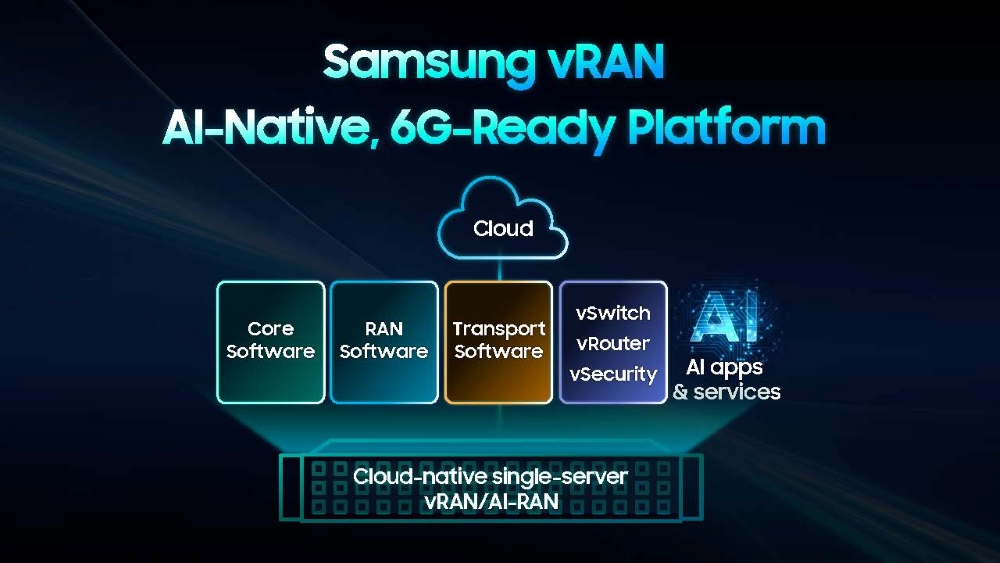
Image Credit: Samsung
“This breakthrough represents a major leap forward in network virtualization and efficiency. It confirms the real-world readiness of this latest technology under live network conditions, demonstrating that single-server vRAN deployments can meet the stringent performance and reliability standards required by leading carriers,” said June Moon, Executive Vice President, Head of R&D, Networks Business at Samsung Electronics. “We are not only deploying more sustainable, cost-effective networks, but also laying the foundation to fully utilize AI capabilities more easily and prepare for 6G with our end-to-end software-driven network solutions.”
Samsung’s vRAN leverages the latest Intel Xeon 6 SoC with Intel Advanced Matrix Extensions (Intel AMX), Intel vRAN Boost and up to 72 cores, delivering significant improvements in AI processing, memory bandwidth and energy efficiency compared to the previous generation.
“With Intel Xeon 6 SoC, featuring higher core counts and built-in acceleration for AI and vRAN, operators get the compute foundation for AI native, future ready networks,” said Cristina Rodriguez, VP and GM, Network & Edge, Intel. “This collaborative achievement with Samsung, HPE and Wind River enables greater consolidation of RAN and AI workloads, lowering power and total cost while speeding innovation.”
Samsung has been leading the deployment of vRAN solutions with major network operators worldwide and has achieved many industry breakthroughs, including the industry’s first call on a commercial network and large-scale deployments utilizing Intel Xeon processors with Intel vRAN Boost. The company continues to push the boundaries of network virtualization, working closely with ecosystem partners like Intel to deliver solutions that help operators build networks that are more efficient and sustainable.
“This successful first call is an important milestone for the industry,” said Daryl Schoolar, Analyst and Director at Recon Analytics. “By demonstrating multiple network functions running on next-generation processing technology, Samsung is showing what future networks look like — more cloud-native, more scalable and significantly more efficient. This achievement moves the industry beyond theoretical performance gains and into practical, deployable innovation that operators around the world can leverage to modernize their networks, accelerate automation and better support AI-driven use cases.”
“With Samsung’s vRAN and Intel’s Xeon 6 SoC running on a single server, Samsung expects enhanced cost savings for operators,” said a Samsung spokesperson via email to Light Reading, when asked what cost impact Granite Rapids would have. “The ability to consolidate multiple network functions including RAN, core, transport and security onto a single, high-performance COTS server reduces hardware footprint, simplifies site design and lowers power consumption.”
Vodafone is one Samsung customer that now expects to benefit from the availability of Granite Rapids. In November, Paco Pignatelli, Vodafone’s head of open RAN, told Light Reading that the new Intel platform offers “much better capacity and efficiency” than its predecessors. That was several weeks after the telco had announced plans to deploy Samsung’s virtual RAN technology in Germany and other European markets, starting in 2026.
…………………………………………………………………………………………………………………………………….
vRAN Market Assessment:
Virtual RAN still accounts for a very small share of the entire market. In 2023, data from Omdia put its market share at just 3% of the total RAN market which generates If vRAN is considered as part of the subsector for baseband RAN, its share was about 10% that year, implying baseband represents about 30% of the total expenditure on RAN products.
Hardware still dominates the RAN equipment business, but there is a rapid shift toward Commercial Off-The-Shelf (COTS) servers, particularly those using Intel’s Xeon 6 processors. Regional Dominance: North America and Asia-Pacific are expected to remain the largest markets in 2026, together accounting for over 70% of global vRAN revenue
- Dell’Oro Group:
- 2026 Stability: Predicts overall RAN revenues will remain “mostly stable” in 2026, but identifies AI-RAN, Cloud RAN, and Open RAN as favorable growth segments within that flat topline.
- Market Share: Expects vRAN to account for 5% to 10% of the total RAN market by 2026.
- Private Wireless: Forecasts that private wireless campus network RAN revenue will surpass USD 1 billion in 2026.
- Omdia:
- Growth Surge: Anticipates a doubling of vRAN’s market share by 2028. Specifically, it expects Open vRAN to reach a 16% share of the total RAN market in 2026, up from 7% in 2022.
- Automation Focus: Forecasts the Service Management and Orchestration (SMO) category to grow at a massive 99% CAGR through 2030 as operators align with O-RAN architectures.
- Research and Markets:
- Estimates the global Open RAN market size will reach between USD 5.0 billion and USD 10.0 billion by 2026, driven by aggressive greenfield deployments.
…………………………………………………………………………………………………………………………
References:
https://www.lightreading.com/5g/intel-and-samsung-add-to-pressure-on-purpose-built-5g
vRAN market disappoints – just like OpenRAN and mobile 5G
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
LightCounting: Open RAN/vRAN market is pausing and regrouping
Dell’Oro: Private 5G ecosystem is evolving; vRAN gaining momentum; skepticism increasing
Heavy Reading: How network operators will deploy Open RAN and cloud native vRAN
Intel to spin off its Networking & Edge Group into a stand-alone business
As originally reported by CRN, Intel revealed its plan to spin off its Network and Edge Group in a memo addressed to customers and said it will seek outside investment for the business unit. Intel will be an anchor investor in the stand-alone business. The memo, seen by CRN, was authored by Sachin Katti, who has led the Network and Edge Group, abbreviated as NEX, since early 2023. He was given the extra role of chief technology and AI officer by Intel CEO Lip-Bu Tan in April to lead the chipmaker’s AI strategy. An Intel spokesperson confirmed the contents of the memo to CRN.
“We plan to establish key elements of our Networking and Communications business as a stand-alone company and we have begun the process of identifying strategic investors,” the representative said in a statement. “Like Altera, we will remain an anchor investor enabling us to benefit from future upside as we position the business for future growth,” the spokesperson added.
The NEX spin-off plan was announced to Intel customers and employees the same day the semiconductor giant revealed more changes under Tan’s leadership, including a 15% workforce reduction and a more conservative approach to its foundry business. “We are laser-focused on strengthening our core product portfolio and our AI roadmap to better serve customers,” Tan said in a statement.
In Katti’s memo, he said Intel “internally announced” on Thursday its plan to “establish its NEX business as a stand-alone company.” This will result in a “new, independent entity focused exclusively on delivering leading silicon solutions for critical communications, enterprise networking and ethernet connectivity infrastructure,” he added.
Katti did not give a timeline for when Intel could spin off NEX, which has been mainly focused on networking and communications products after the company moved its edge computing business to the Client Computing Group last September. Intel also shifted its integrated photonics solutions to the Data Center Group that same month. Similar to other businesses Intel has spun off, the company plans to maintain a stake in the stand-alone NEX company as it seeks out other investors, according to Katti. “While Intel will remain an anchor investor in the new company, we have begun the process of identifying additional strategic and capital partners to support the growth and development of the new company,” he wrote.
Katti said the move is “rooted in our commitment to serving” Intel’s customers better and promised that there will be “no change in service or the support” they rely on. He added that it will also help NEX “expand into new segments more effectively. Backed by Intel, this new, independent company will be positioned to accelerate its customer-facing strategy and product road map by innovating faster and investing in new offerings.”
Katti said he expects the transition to be “seamless” for Intel’s customers. “What we expect to change is our ability to operate with greater focus, speed and flexibility—all to better meet your needs,” he wrote.
…………………………………………………………………………………………………………………………………………………..
Intel was rumored to be looking for a buyer for its Network and Edge group in May. This business produced $5.8 billion in revenue in 2024.
This strategy seems similar to the company’s decision to spin off RealSense, its former stereoscopic imaging technology business, earlier this month. Intel decided to spin RealSense out during former CEO Pat Gelsinger’s tenure and the company struck out on its own with $50 million in venture funding.
…………………………………………………………………………………………………………………………………………………..
Shortly after Tan became Intel’s CEO in March, the leader made clear that he would seek to spin off businesses he considers not core to its strategy. Then in May, Reuters reported that the company was exploring a sale of the NEX business unit as part of that plan.
While Tan didn’t reference Intel’s decision to spin off NEX in the company’s Thursday earnings call, he discussed other actions it has taken to monetize “non-core assets,” including the sale of a portion of Intel’s stake in Mobileye earlier this month.
The company is also expected to complete its majority stake sale of the Altera programmable chip business to private equity firm Silver Lake by late September, according to Tan. Silver Lake will gain a 51 percent stake in the business while Intel will own the remaining 49%. “I will evaluate other opportunities as we continue to sharpen our focus around our core business and strategy,” Tan said on the earnings call.
………………………………………………………………………………………………………………………………………………………….
In 2019, Apple acquired the majority of Intel’s smartphone modem business for $1 billion. This deal included approximately 2,200 Intel employees, intellectual property, equipment, leases, and over 17,000 wireless technology patents. The acquisition allowed Apple to accelerate its development of 5G modem technology for its iPhones, reducing reliance on third-party suppliers like Qualcomm. Intel, in turn, refocused its 5G efforts on areas like network infrastructure, PCs, and IoT devices
References:
https://www.crn.com/news/networking/2025/intel-reveals-plan-to-spin-off-networking-business-in-memo
https://techcrunch.com/2025/07/25/intel-is-spinning-off-its-network-and-edge-group/
https://www.lightreading.com/semiconductors/intel-sale-of-networks-sounds-like-an-ericsson-problem
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Massive layoffs and cost cutting will decimate Intel’s already tiny 5G network business
Nokia utilizes Intel technology to drive greater 5G SA core network energy savings
Nokia selects Intel’s Justin Hotard as new CEO to increase growth in IP networking and data center connections
Nokia selects Intel’s Justin Hotard as new CEO to increase growth in IP networking and data center connections
Nokia today announced that their President and Chief Executive Officer, Pekka Lundmark will be replaced on April 1st by 50 year old Justin Hotard who currently leads Intel’s Data Center & AI Group. Hotard joins Nokia with more than 25 years’ experience with global technology companies, driving innovation, technology leadership and delivering revenue growth. Prior to Intel, he held several leadership roles at large technology companies, including Hewlett Packard Enterprise (more below) and NCR Corporation. He will be based at Nokia’s headquarters in Espoo, Finland.
“Leading Nokia has been a privilege. When I returned to Nokia in 2020, I called it a homecoming, and it really has felt like one. I am proud of the work our brilliant team has done in re-establishing our technology leadership and competitiveness, and positioning the company for growth in data centers, private wireless and industrial edge, and defense. This is the right time for me to move on. I have led listed companies for more than two decades and although I do not plan to stop working, I want to move on from executive roles to work in a different capacity, such as a board professional. Justin is a great choice for Nokia and I look forward to working with him on a smooth transition,” said Nokia’s President and CEO Pekka Lundmark.
“I am delighted to welcome Justin to Nokia. He has a strong track record of accelerating growth in technology companies along with vast expertise in AI and data center markets, which are critical areas for Nokia’s future growth. In his previous positions, and throughout the selection process, he has demonstrated the strategic insight, vision, leadership and value creation mindset required for a CEO of Nokia,” said Sari Baldauf, Chair of Nokia’s Board of Directors.
“I am honored by the opportunity to lead Nokia, a global leader in connectivity with a unique heritage in technology. Networks are the backbone that power society and businesses, and enable generational technology shifts like the one we are currently experiencing in AI. I am excited to get started and look forward to continuing Nokia’s transformation journey to maximize its potential for growth and value creation,” said Justin Hotard.
Rumors started to swirl in September, after a report in the Financial Times newspaper, that Nokia was seeking a replacement for Lundmark, who by then had been its CEO for about four years. Nokia said in a statement: “The Board fully supports President and CEO Pekka Lundmark and is not undergoing a process to replace him.”
–>How seriously should the FT and all other media now take the company’s public statements?
Lundmark had told Nokia’s board months earlier, in the spring of 2024, that he would consider stepping down once “the repositioning of the business was in a more advanced stage.” This author certainly does not think that “advanced stage” has been reached yet. “The current CEO has not got to grips with the growth problem. The top line has not increased since the Alcatel-Lucent takeover,” said a shareholder.
Nokia’s share price is now only 10% of its peak $260 Billion valuation in 2000 peak (that’s a 90% decline in price over almost 25 years- buy and hold?). However, the company has gained almost 40% in the last year after operational improvements and signs that construction of AI data centers could be a significant growth opportunity for Nokia’s network infrastructure business group, its second-biggest unit. In his leaving video, Lundmark drew attention to the sales growth rate of 9% for the final quarter of 2024 and the operating margin of 19.1%, Nokia’s best in a decade.
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
“We’re at the start of a super cycle with AI,” said Hotard. “One that I see [as] very similar to the one we saw a couple of decades ago with the internet. In these major market transitions new winners are created and incumbents either reinvent themselves or fail… My focus will be to accelerate the transformation journey.”
During the Nokia conference call Q&A Hotard was defensive to questions about his plans for the company. He did say that networking comes second only to compute hardware when it comes to share of AI datacenter investment and he looks forward to the completion of the $2.1 billion Infinera acquisition. “The hundreds of billions of dollars being invested in data centers today from a technology standpoint of course start with compute accelerators and GPUs [graphical processing units], but the second thing is the network and the connectivity and further it is not just the connectivity inside the data center but the connectivity across data centers,” said Hotard on today’s call. That implies an increased emphasis Nokia will place on optical networking within and between data centers.
Indeed, IP networking and data center connectivity are becoming a fast-growing part of Nokia’s network infrastructure unit that provides the connectivity inside those data centers, recently landing deals with Microsoft and UK-headquartered Nscale. The hoped-for return is an additional €1 billion ($1.03 billion) in revenues by 2028. The Infinera acquisition, announced in June 2024 and expected to be finalized in the next few weeks, is also partly a data center play, bolstering Nokia’s portfolio of optical networking assets.
On Nokia’s Q3 2024 earnings call in October, Lundmark said, “Across Nokia, we are investing to create new growth opportunities outside of our traditional communications service provider market. We see a significant opportunity to expand our presence in the data center market and are investing to broaden our product portfolio in IP Networks to better address this. There will be others as well, but that will be the number one. This is obviously in the very core of our strategy.” At that time, Lundmark said Nokia’s telco total addressable market (TAM) is €84 billion, while its data center total addressable market is currently at €20 billion. “I mean, telco TAM will never be a significant growth market,” he added to no one’s surprise.
On today’s call, Lundmark drew attention to its revival and strength when asked to compare Nokia with Ericsson. “Of course, we respect them as a competitor in radio networks. We are slightly behind them in terms of market share, but we have had great deal momentum recently – you’ll have seen some of the deal announcements – and, very importantly, the feedback we are receiving from our customers is that we are now fully competitive in terms of our portfolio.”
During the past year Hotard has headed up Intel’s Datacenter & AI Group. Prior to that he was at HPE for nine years heading up the High Performance Computing, AI & Labs group.
“Networks are the backbone that power society and businesses, and enable generational technology shifts like the one we are currently experiencing in AI. I am excited to get started and look forward to continuing Nokia’s transformation journey to maximize its potential for growth and value creation,” said Justin Hotard.
What will Hotard led Nokia’s future commitment be to a shrinking market for mobile networks? Revenues generated by the global mobile market are estimated to have fallen about $5 billion last year, to $35 billion, after a $5 billion drop in 2023, according to Omdia (an Informa owned market research firm), as network operators cut spending. But an exit would rid Nokia of a business still responsible for 40% of total sales just as smaller rivals appear to be struggling.
Nokia seems to value Hotard’s U.S. background and experience in the data center and AI market. “If you look at the market and look at the world, the U.S. is an important market for us and so that is one element we consider – experience from that technology business there,” said Sari Baldauf, Nokia’s chair, when asked on today’s call why an external candidate was preferred to an internal appointment.
……………………………………………………………………………………………………………………………………………………………………………………………………………..
Telecoms.com Scott Bicheno offered his opinion: “Hotard reckons Nokia’s telco customer base gives it an advantage when it comes to AI datacenters, which are increasingly built near to sources of power, often in remote locations. So, while this does feel like a promising strategic pivot for Nokia, those telco customers might be worried about mobile being deprioritized as a consequence. The appointment of someone from a company with an appalling track record in that sector is unlikely to ease that concern.”
……………………………………………………………………………………………………………………………………………………………………………………………………………..
References:
https://www.telecoms.com/ai/nokia-signals-a-move-away-from-mobile-and-europe-with-new-ceo
https://www.ft.com/content/5f086aee-91b9-421a-9f32-c33e67b1af7f
Initiatives and Analysis: Nokia focuses on data centers as its top growth market
Nokia to acquire Infinera for $2.3 billion, boosting optical network division size by 75%