AI in Networks Market
Oracle Integrates NVIDIA and Google AI Accelerators with its High-Performance Cloud Networking Infrastructure
Disclaimer: ChatGPT was used extensively for research included in this article.
…………………………………………………………………………………………………………………………………………………………………
Introduction:
Oracle’s multiple announcements on October 27th illustrate how AI cloud infrastructure is evolving beyond simply providing access to GPUs. Oracle Cloud Infrastructure (OCI) is combining NVIDIA’s latest AI computing systems, Google’s Tensor Processing Units (TPUs), and its Acceleron networking architecture to support increasingly demanding AI training, inference and agentic workloads.
The strategy reflects a fundamental change in the requirements for large-scale AI: accelerator performance alone is insufficient. The network connecting those accelerators, the movement of data between compute and storage, and the ability to sustain performance across very large clusters are equally important.
NVIDIA Vera Rubin systems target large-scale AI workloads:
Oracle and NVIDIA announced that NVIDIA Vera Rubin NVL72 systems and Vera CPUs are generally available on OCI. They also outlined plans to expand OCI Superclusters using Vera Rubin systems to multi-gigawatt scale. Oracle says its Superclusters can scale across hundreds of thousands of GPUs.
The NVL72 architecture connects 72 GPUs within a rack using NVIDIA NVLink scale-up networking. Beyond the rack, Oracle uses an Ethernet-based network fabric to connect systems into much larger clusters.
This distinction between scale-up and scale-out networking is critical. Scale-up interconnects provide high-bandwidth communication among closely coupled accelerators. Scale-out fabrics must move data between racks while managing congestion, latency, failures and the traffic generated by thousands of parallel computing devices.
Large AI training jobs are particularly sensitive to communication delays. Because many operations synchronize across accelerators, a congested link or a slow communication path can leave otherwise productive GPUs waiting for data or results from other GPUs.
Oracle’s challenge is therefore not simply to provide more computing capacity, but to keep that capacity productively utilized as clusters grow.
Google TPUs introduce an alternative AI computing architecture:
In a separate announcement, Oracle and Google said Google’s TPUs will become available through OCI, making Oracle the first hyperscale cloud provider outside Google to offer the accelerators.
Google’s eighth-generation TPU portfolio includes two architectures with different priorities:
- TPU 8t: Designed primarily for large-scale AI training.
- TPU 8i: Designed for inference, including workloads involving iterative reasoning and AI agents.
Google’s TPUs are purpose-built accelerators supported by Google’s software ecosystem. Oracle plans to provide the data-center infrastructure, power, cooling and networking needed to deploy them at scale.
However, the service will not be immediately available: Oracle says TPU availability will begin in calendar 2027 and ramp over multiple years.
The addition of TPUs gives OCI customers another option alongside NVIDIA-based infrastructure. Different accelerators can have different performance characteristics, memory architectures, software requirements and economics, depending on the model and workload.
This does not mean the systems are interchangeable. Moving an application between accelerator platforms may require changes to software, kernels, frameworks, deployment tools and performance optimization. The practical value of choice will depend on how easily customers can adapt their workloads and achieve competitive performance.
Oracle Acceleron addresses the networking challenge:
Oracle’s third major development is its continued expansion of Acceleron, OCI’s networking and infrastructure technology portfolio.
Oracle describes an architecture combining high-performance Ethernet networking, remote direct memory access (RDMA), host-level acceleration and multipath network designs. Its NVIDIA-based infrastructure incorporates Spectrum-X Ethernet switches and other NVIDIA networking components alongside Oracle’s own network architecture and services. RDMA enables systems to transfer data between memories with less intervention from host CPUs than conventional networking approaches. This can reduce overhead and improve communication efficiency in tightly synchronized distributed workloads.
Oracle also describes a multiplanar network architecture that distributes traffic across multiple paths. Its Multipath Reliable Connection (MRC) transport can spread packets across many paths, helping the network respond to congestion or unstable paths without relying on a single route. The objective is to maintain predictable communication performance as clusters grow. A network failure or congestion event can affect far more than one connection when thousands of accelerators participate in a coordinated training job.
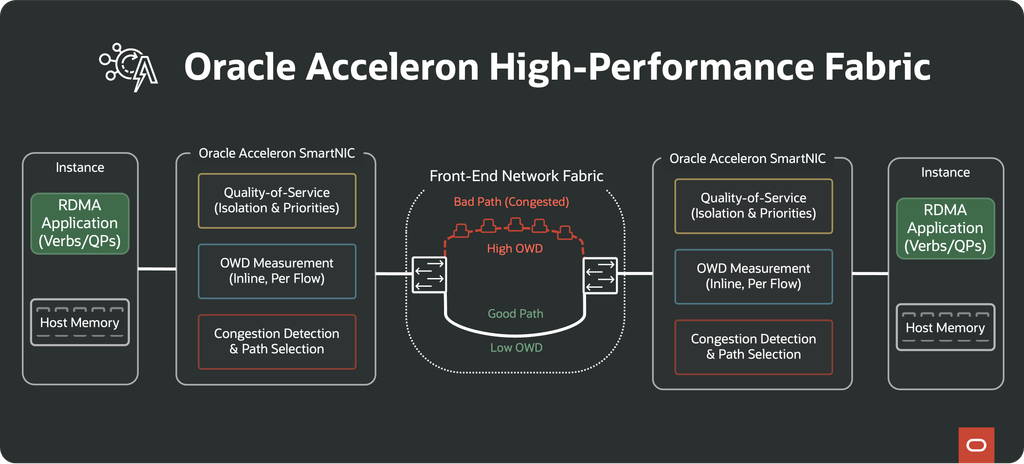
Image Credit: Oracle
Oracle’s October 27 networking announcement also describes improvements in storage connectivity, congestion management and network resilience. These capabilities are intended to keep distributed AI workloads operating efficiently while improving security and supporting multitenant cloud environments.
The company presents these capabilities as ways to reduce network friction and improve utilization. Their actual benefits will depend on workload characteristics, network configuration, software implementation and operational conditions; independent, comparable benchmarks would be needed to quantify the advantages over competing architectures.
What does this mean for AI cloud architecture?
The combined announcements point to a broader industry shift: AI infrastructure is increasingly designed as an integrated system rather than a collection of independent hardware products.
Three technical issues will be especially important:
1. Communication becomes a limiting factor. As accelerator counts increase, the ability to exchange data efficiently can constrain overall performance. Network topology, congestion control, latency and fault recovery can be as consequential as raw link bandwidth.
2. Heterogeneous computing creates opportunities and complexity. Offering NVIDIA GPUs and Google TPUs allows OCI customers to evaluate different architectures for training and inference. However, software portability, developer tools, model compatibility and operational complexity will influence whether that choice delivers practical benefits.
3. Utilization determines system efficiency. Expensive accelerators generate value only when they are doing useful work. Faster data movement, efficient collective communication, resilient networking and appropriate workload placement can help reduce idle time. The same principle applies to power consumption: infrastructure efficiency must be evaluated across the complete system, not just individual chips.
Oracle is also extending its infrastructure strategy to CPUs and specialized accelerators for inference and agentic applications. That reflects the growing importance of the work surrounding model execution, including tool calls, code execution, data retrieval and orchestration—not just the computation performed inside an AI model.
Oracle’s AI cloud infrastructure integrates accelerator hardware, high-density computing systems and high-performance networking to support distributed AI workloads:
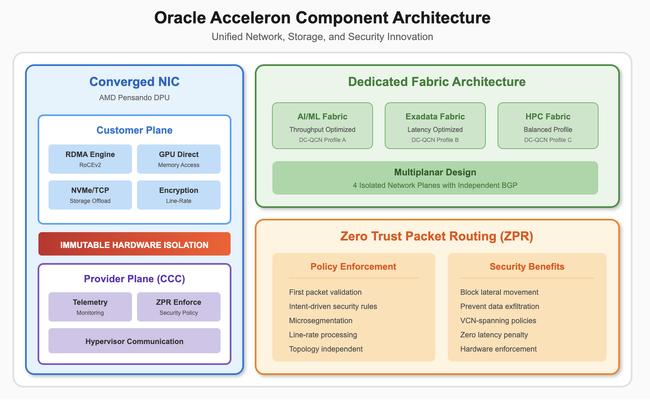
Image Credit: ChatGPT
……………………………………………………………………………………………………………………………………………………………………………………………………………………….
Conclusions:
Oracle’s October 27th announcements bring together three elements of its AI cloud strategy: NVIDIA’s latest accelerator systems, Google’s alternative TPU architecture, and Oracle’s high-performance cloud networking:
The NVIDIA systems combine NVLink scale-up interconnects with Ethernet-based scale-out fabrics, while Google’s TPU architecture integrates custom silicon, high-bandwidth memory and specialized interconnects. Oracle Acceleron adds RDMA connectivity, congestion control, multipath traffic distribution and automatic failover to help sustain performance across large, distributed AI clusters.
The important technical question is whether these components can deliver reliable, scalable and cost-effective performance for real AI workloads. Hardware specifications and announced deployment capacity are useful starting points, but customers ultimately need end-to-end benchmarks measuring training throughput, inference latency and cost per token, network utilization, storage performance, software compatibility, fault recovery, and power efficiency. For distributed training in particular, goodput—the proportion of time a cluster spends performing productive computation rather than waiting on communication or recovering from failures—is a more meaningful measure than peak compute performance alone.
The competitive battleground is no longer just the AI chip. It is the complete cloud computing and networking system: accelerators, memory, interconnects, Ethernet fabrics, storage and software working together to maximize useful computation per dollar and per watt.
Google says TPU chip-to-chip traffic uses ICI and OCS, while Oracle Acceleron connects TPU capacity to the rest of OCI. That differs from the NVIDIA NVLink scale-up and RoCE scale-out arrangement. Offering both accelerator families through OCI therefore should not be read as establishing a common GPU–TPU interconnect or transparent mixed-accelerator training.
Sidebar – Larry Ellison’s remarkable change of direction on cloud computing:
Oracle’s current AI infrastructure ambitions are particularly striking given Larry Ellison’s earlier skepticism about cloud computing. In 2008, Ellison publicly criticized cloud computing as a repackaging of established technologies under a fashionable label. Oracle’s business at the time centered on enterprise databases, business applications, software licensing and support. Its traditional model depended heavily on customers running Oracle software in their own data centers.
At an Oracle event I attended in spring 2011, that strategy remained intact: Oracle proposed licensing its software to cloud developers rather than becoming a cloud infrastructure provider. “We do not plan to become a cloud service provider,” the Oracle representative told the audience.
That began to change in a big way. In October 2011, Oracle introduced its public cloud, offering Oracle software and development services over the internet. In 2012, Ellison articulated a broader cloud strategy, although he continued to argue that cloud computing was an evolution of existing technology rather than a fundamentally new computing paradigm.
Oracle’s transformation subsequently accelerated. In 2016, the company launched its modern-generation cloud infrastructure platform, competing more directly with established infrastructure providers such as Amazon Web Services (AWS) and Microsoft Azure. The strategic change went well beyond delivering existing Oracle software as an online service. Oracle invested in compute, storage, networking, data centers and infrastructure designed for demanding enterprise workloads. Its later expansion into large-scale AI infrastructure has taken that evolution further.
Today, Oracle is deploying NVIDIA’s newest AI systems, preparing to offer Google’s TPUs, and developing networking capabilities intended to support distributed AI clusters at enormous scale. The historical irony is clear: a company long associated with proprietary enterprise software and database licensing has become a major contender in the infrastructure underpinning modern AI.
Whatever the merits of Ellison’s initial criticism of cloud terminology, Oracle’s subsequent decision to build and operate cloud infrastructure and provide cloud services reversed the position its representative had communicated to attendees in spring 2011. Ellison’s evolution also illustrates an important lesson in technology strategy. A company need not accept every new technology label or prevailing industry narrative to recognize that customer requirements and competitive economics are changing. But adapting successfully may ultimately require much more than adding new products to an existing business—it can require rebuilding the business around a different infrastructure model.
………………………………………………………………………………………………………………………………………………………………………………………………
References:
Oracle and NVIDIA — Vera Rubin systems and Vera CPUs on OCI
https://blogs.oracle.com/cloud-infrastructure/nvidia-vera-rubin-vera-cpus-oci
2. Oracle and Google — Bringing Google TPUs to Oracle Cloud Infrastructure
https://www.oracle.com/news/announcement/ai-world-oracle-brings-google-tpus-to-oracle-cloud-infrastructure-2026-10-27/
3. Oracle — Acceleron networking innovations for AI
https://www.oracle.com/europe/news/announcement/ai-world-oracle-unveils-new-cloud-networking-innovations-for-ai-2026-10-27/
https://blogs.oracle.com/cloud-infrastructure/first-principles-networking-for-ai-scale
https://blogs.oracle.com/cloud-infrastructure/wp-content/uploads/sites/83/2026/10/HP-Fabric-01-1024×464.png
4. WIRED — “Ellison Answers Benioff With Oracle Cloud” (October 2011)
https://www.wired.com/2011/10/ellison-answers-benioff-with-oracle-cloud/
Editorial note: The first three links cover the technical announcements. The WIRED article provides historical context for the sidebar on Larry Ellison’s changing position on cloud computing. Oracle’s official October 27th networking announcement is also available here: https://www.oracle.com/europe/news/announcement/ai-world-oracle-unveils-new-cloud-networking-innovations-for-ai-2026-10-27/
Custom AI Silicon: OpenAI, Anthropic, Hyperscalers and the Battle with Nvidia, AMD and Broadcom
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
2026 OCP Summit: Full-Stack AI Networking Silicon from Nvidia/Cisco and Broadcom; Ethernet vs InfiniBand Interconnects
Huawei’s Ascend Silicon Roadmap Extends From AI Chips to Cluster-Scale Infrastructure
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
AWS, Google, Microsoft, Oracle win $9B DoD cloud computing contract (JWCC)
Oracle and Microsoft Enhance Interoperability of their Cloud Platforms (facilitating multi-cloud)
AI-RAN Push: NVIDIA, Nokia, and Operators Drive Towards Distributed Compute Platforms
Introduction:
A massive industry consortium spearheaded by NVIDIA, Nokia, and leading global telecom operators has announced an expanded ecosystem initiative aimed at transforming traditional radio access network (RAN) sites into converged, distributed intelligence platforms. While vendor marketing frequently leans on the ambiguous hype of “AI-RAN,” this specific alignment underscores a tangible structural shift: the push to monetize edge network infrastructure by hosting centralized AI inference and processing workloads directly within the carrier’s decentralized footprint.
The coalition, which includes T-Mobile US, Deutsche Telekom, Orange, and SoftBank, is actively deploying multi-vendor frameworks to validate whether cell sites can simultaneously manage real-time layer-1/layer-2 radio scheduling and high-throughput external AI workloads on a single, unified hardware fabric.
Multi-Vendor Validation and Live Network Milestones:
Rather than remaining confined to isolated laboratory benchmarks, the initiative highlighted several live-network implementation milestones:
-
- T-Mobile US Commercial Network Execution: T-Mobile completed a live AI-RAN call within a commercial production environment, leveraging Nokia’s cloud-native RAN software integrated with NVIDIA’s accelerated computing architecture. The trial successfully demonstrated dynamic, real-time compute resource allocation between standard cellular traffic and concurrent AI applications.
- European Operator Deployment Frameworks: Deutsche Telekom and Orange are initiating deep architectural trials across their European footprints. These validation tests focus explicitly on multi-tenant control planes and the orchestration of heterogeneous GPU resources across legacy and greenfield environments.
- SoftBank Industrial Clusters: Moving past speculative trials, SoftBank is designing localized edge computing clusters that treat cell towers as distributed mini-data centers, targeted directly at hosting low-latency, localized autonomous vehicle and industrial robotics workloads.
Globally, nearly 20 telecom operators have publicly announced AI-RAN collaborations using Nokia anyRAN software and NVIDIA ARC.
- T-Mobile recently marked the world’s first AI-RAN call on its commercial network in Bellevue, Washington, running on commercial ARC servers, Nokia’s NVIDIA CUDA-accelerated RAN software and massive multiple-input multiple-output radios, and connected to an existing 5G Standalone core and a commercial smartphone.
- BT is planning live AI-RAN trials in Birmingham, England, with Nokia and NVIDIA in 2027.
- Deutsche Telekom has validated Nokia and NVIDIA’s commercial AI-RAN platform in Bonn and Oulu labs, including AI-enhanced uplink channel estimation to improve uplink user throughput, with plans to move to field trials in 2027.
- Elisa simultaneously ran voice, mobile data and video analytics on the NVIDIA ARC platform, marking a European first in Elisa’s over-the-air field environment using 5G spectrum. The trial clears the way for distributed deployment and commercial AI-RAN services in 2027.
- Orange is testing Nokia 5G software on NVIDIA ARC, focusing on AI-RAN spectral efficiency improvements and support for edge services in live networks.
NVIDIA is introducing two ARC configurations — MGX 2U and MGX 4U — designed for dense, high-capacity intelligence and radio workloads, typically deployed at centralized RAN sites. Powered by NVIDIA RTX PRO™ 6000 Blackwell Server Edition GPUs, the configurations will offer x86 and NVIDIA Vera CPU options. Dell Technologies, Quanta Cloud Technology and Supermicro will offer ARC-ready servers.
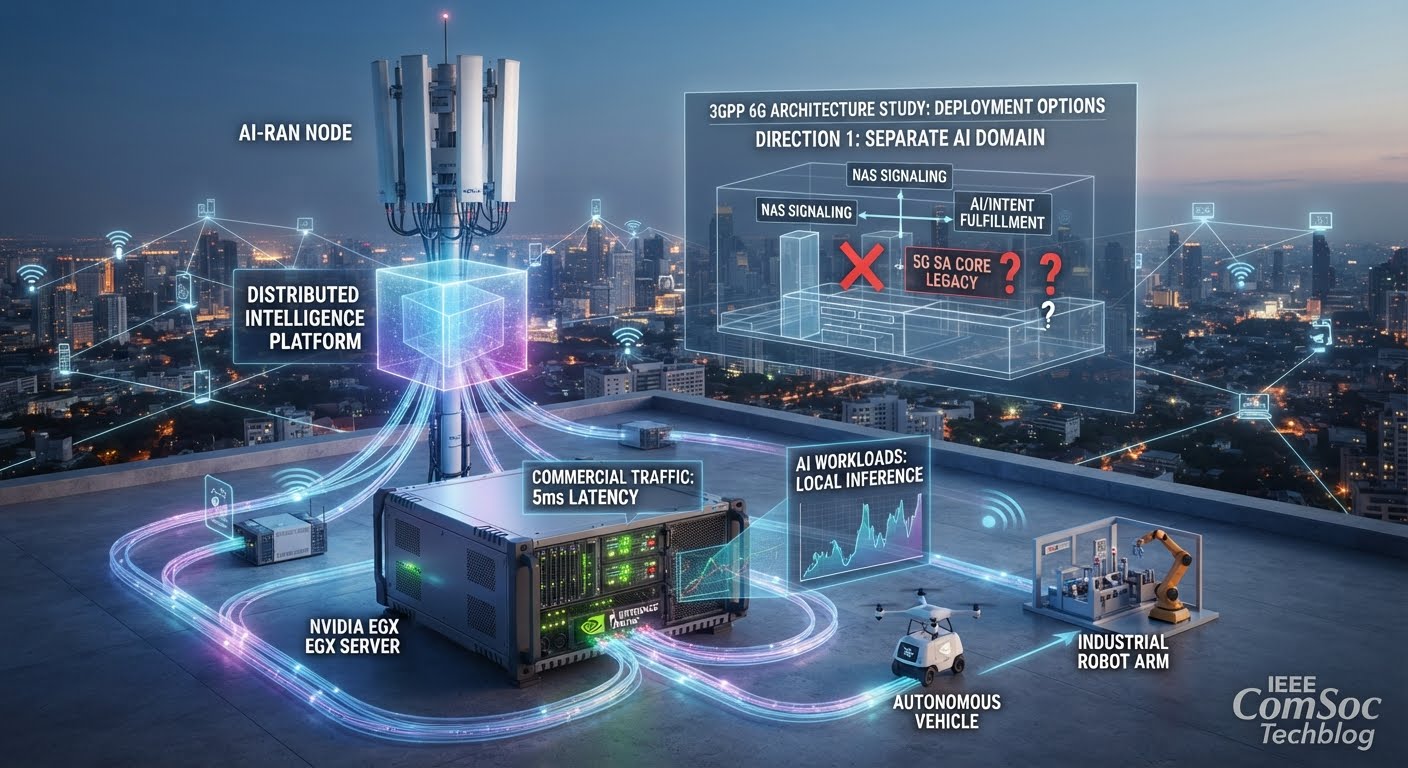
Image generated by Google Gemini
………………………………………………………………………………………………………………………………………………………………………………………
6G Splinter Risk – Will AI-RAN Interoperability Outpace the 6G SA Core?
This real-world push for decentralized AI-RAN execution exposes a critical timing and protocol gap within the broader standardization landscape. As vendors accelerate hardware deployments, the 3GPP SA2 Working Group remains technically fractured over how to formalize the underlying 6G core architecture. Rather than standardizing deterministic state behaviors, the current 6G study phase risks repeating the exact implementation voids that crippled 5G Standalone (SA) interoperability. Today’s commercial push for AI integration highlights the three architectural paths currently splintering 3GPP SA2:
-
- Direction 1 (Separate AI Domain): Anchors the core to the existing 5G Service-Based Architecture (SBA). It utilizes a dedicated AI domain for intent handling via the Service-Based Interface (SBI) while routing Non-Access Stratum (NAS) signaling through the AMF. Backed strongly by Western operators and vendors (including T-Mobile, Deutsche Telekom, Nokia, and NVIDIA), this path preserves 5G infrastructure investments but shifts the burden of multi-vendor integration directly to the device client.
- Direction 2 (AI Functionality in 6G NFs): Integrates machine learning natively within dedicated, standardized 6G network functions following legacy pipeline procedures.
- Direction 3 (Agent-Handled Connectivity): Eliminates traditional structural silos by deeply embedding autonomous AI agents directly into control and user plane procedures, bypassing the AMF entirely via a new Signaling Routing Function (SRF). This introduces massive procedural disruption to baseband silicon and core security frameworks.
………………………………………………………………………………………………………………………………………………………….
Conclusions – Bridging the Hype Gap:
The core engineering risk is that AI and machine learning models are fundamentally non-deterministic. If 3GPP restricts its focus to defining logical API endpoints rather than mandating strict behavioral state-machine realization, open agent-to-agent telemetry, and standardized model interchange formats, 6G will degenerate into a hyper-complex web of proprietary black boxes.
•Telcos have historically struggled to compete with hyperscalers (AWS, Azure, Google Cloud) on raw cloud storage and compute. AI-RAN could possibly the game because of physical close proximity and deterministic latency. By hosting AI workloads at the edge of the connectivity path, network operators might offer “Sovereign AI” and ultra-low-latency processing which centralized hyperscaler data centers physically cannot match.
As detailed in several previous IEEE Techblog posts (see References below), the telecom industry cannot afford another capital expenditure cycle driven by speculative lab benchmarks. By transforming cell towers into high-margin compute platforms, this distributed intelligence alliance offers carriers a concrete pathway to monetize low-latency edge workloads. However, for AI-RAN to achieve true multi-vendor utility, the engineering community must force 3GPP to bridge the gap between paper standards and deterministic software reality. We cannot afford to build another ghost in the machine.
………………………………………………………………………………………………………………………………………………………….
References:
6G Architecture and Economics: Core Network Evolution, AI Integration and Business Case
Warning: 6G core network must not repeat the 5G SA 3GPP architecture specs vs lack of interoperable standards
Sept 2026 3GPP meeting updates for 5G Advanced and 6G planning (with timeline for submisson to ITU-R WP 5D via ATIS)
Roles of 3GPP and ITU-R WP 5D in the IMT 2030/6G standards process
3GPP approves timelines for Release 21 which will specify 6G RAN, Core and 5G Advanced
Dell’Oro: RAN Market Stabilized in 2025 with 1% CAG forecast over next 5 years; Opinion on AI RAN, 5G Advanced, 6G RAN/Core risks
Ericsson leads SK Telecom AI RAN vs. NVIDIA’s GPU centric AI RAN Alliance
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Dell’Oro: AI RAN revenue forecast: $35B from 2026-to-2030; 3 types of AI RAN explained
Deutsche Telekom: Device-to-Cloud AI Traffic Won’t Force RAN Upgrades or Increase CAPEX
Introduction:
Deutsche Telekom is in the process of “upgrading mid-range plans,” according to Dhananjay Mirchandani, DT’s senior VP for group controlling and the group’s next CFO from May 1, 2027. “I cannot recall a single conversation in which Alex Jenbar [CTO of Telekom Deutschland] … or somebody else approached us and said, ‘in addition to whatever we currently have on our roadmaps for RAN modernization, that there is an incremental requirement for an investment to be able to prepare ourselves for additional uplink/AI-related traffic,'” he said. “[That’s] just to give you a sense of the degree of confidence we have in terms of our own capex planning, specifically related to mobile network capacity,” he added.
His assessment on medium-term mobile capacity is bound to be sobering for its radio access network (RAN) vendors in Germany: Ericsson, Huawei and Nokia.
The rise of agentic and physical AI could upend decades of mobile network design that dedicates most bandwidth to download speeds (i.e., downlink) and much less to the data channels for uploads (i.e., uplink). It’s not certain how or when traffic patterns will change in a big way, but telcos are talking about preparing for a wave of AI-fueled traffic coming from smartphones, smart glasses or robots.
The Reality Check – No Incremental RAN Capex:
During an investor event, financial analysts directly pressed Deutsche Telekom’s incoming CFO, Srinivas Mirchandani, on whether capital intensity would escalate after 2027 to handle the upstream traffic generated by physical AI, wearables, and smartphone-based LLM queries.
• The Stand: Mirchandani honestly noted that he could not recall a single internal conversation where the CTO of Telekom Deutschland (Alex Jenbar) requested incremental investment beyond their existing radio access network (RAN) modernization roadmaps to handle AI uplink traffic.
• The Baseline Numbers: DT’s long-term guidance (established at its 2024 Capital Markets Day) mandates that capital spending outside the U.S. and spectrum will sit at 21% of service revenue by 2027. While DT is trading slightly above that now, it is entirely due to heavy fiber-optic rollouts in Germany, not mobile radio expansions.
| Attribute | Deutsche Telekom (Europe Group) | T-Mobile US |
|---|---|---|
| Capex Stance | Rigid cap on mobile intensity; excess savings diverted strictly to German landline fiber infrastructure. | Confirmed network architecture expansion funded via standardized 5G-Advanced cycles. |
| AI Traffic Philosophy | Believes traffic peaks are manageable within existing, scheduled modernization roadmaps. | Views the network explicitly as the “connective tissue for physical AI and AI wearables.” |
| Uplink Solutions | Delaying heavy structural changes; emphasizing spectrum efficiency under legacy boundaries. | Implementing Uplink Carrier Aggregation, Uplink MIMO, and Transmit Switching under 5G-Advanced. |
- Delaying Capex via Software: Panelists from across the telco ecosystem—including Turkcell and Deutsche Telekom’s own group partnering division—noted that AI is actually delaying capex cycles rather than accelerating them. Operators are deploying AI algorithms inside the radio access network to optimize power consumption, conduct predictive capacity planning, and boost edge throughput. In short: AI software is making existing hardware last longer.
- The Opex ROI Conundrum: Telcos are seeing immediate financial returns from “AI for the network” (e.g., DT projects €2.5 billion in cumulative cost savings by 2030 through AI automation). However, the business model for a “network for AI”—where consumers or enterprise clients pay a premium for high-speed, low-latency uplink to feed remote LLMs—remains entirely unproven.
- The 6G Boundary Wall: Based on this author’s carrier checks, most Tier-1 network operators now view massive, structural upstream re-architecting as a “6G-era investment narrative” rather than an immediate 5G sub-6GHz demand. Until dedicated enterprise use cases validate moving further up the value chain, hardware vendors will have to wait for a significant revenue lift from device-to-cloud AI traffic.

Source: Deutsche Telekom, Photo: Norbert Ittermann
…………………………………………………………………………………………………………….
Conclusions:
Deutsche Telekom (DT) indicates that rising device-to-cloud traffic volumes will not necessitate premature radio access network (RAN) upgrades. Technical analyses suggest that upcoming capacity demands driven by agentic AI may not immediately accelerate RAN capital expenditure.
DT does not see AI uplink traffic driving an incremental increase to its RAN capex plans in the medium term. DT is holding a rigid perimeter around its long-term financial guidance. By 2027, capital intensity (excluding the U.S. and spectrum) is strictly capped at 21% of service revenues. Excess capital is not being funneled into expanding cell site capacities for upstream AI traffic; it is being aggressively diverted toward landline fiber-optic buildouts in Germany.
-
- Uplink Carrier Aggregation (CA): Allows the network to combine multiple frequency bands (e.g., mid-band and low-band) exclusively for the upstream path. This maximizes the utilization of already-deployed spectrum without requiring operators to acquire or build new macro tower infrastructure.
- Uplink MIMO & Transmit Switching: Enhances data throughput from consumer AI wearables and smartphones back to the cloud by multiplying the data paths between the device and the tower antenna arrays. [
- Network Slicing: Under 5G SA, carriers can allocate a virtualized, highly efficient “slice” of the existing spectrum explicitly for low-latency AI queries. Slicing can improve resource allocation and protect selected service requirements, but it is not a substitute for sufficient uplink capacity. However, it isolates upstream data paths without needing incremental physical hardware upgrades.
References:
https://www.openranforum.com/home
AI-RAN and Agentic AI get real: Ericsson, Nokia, Verizon & other operators enter into a new network automation era
Cisco Execs: New “Network Supercycle” as Agentic AI Workloads Reshape Telecom Infrastructure
Cisco report: Agentic AI to reshape WAN traffic, AI inference will be ~25% of total traffic by 2035
Nokia’s AI Applications Study: “Physical AI” may require RAN redesign to support high‑volume, low‑latency uplink traffic
STL Partners webinar: Agentic AI needed for RAN autonomy & efficiency
The Financial Trap of Autonomous Networks: Scaling Agentic AI in the Telecom Core
AT&T’s 600 MHz Deployment with Ericsson: Turning Low-Band Spectrum Into Coverage and Uplink Capacity
SoftBank’s Transformer AI model boosts 5G AI-RAN uplink throughput by 30%, compared to a baseline model without AI
T‑Mobile achieves record 5G Uplink speed with 5G NR Dual Connectivity
Telstra achieves 340 Mbps uplink over 5G SA; Deploys dynamic network slicing from Ericsson
Finland’s Elisa, Ericsson and Qualcomm test uplink carrier aggregation on 5G SA network
AI-Native 6G RAN in Practice: Research and Validation Insights from 6G-MIRAI-HARMONY
By Shammi Thakur, Research Director, MarkNtel Advisors with Shazia Hasnie, PhD
Introduction:
A wireless AI model can perform well in the laboratory and still face a very different test once the radio environment changes. However, propagation conditions shift as users move. Traffic loads vary. Devices and carrier frequencies differ. Hardware introduces imperfections that a clean simulation may not capture. Distributed RANs add another complication because a decision made at one network element can affect conditions elsewhere.
A recent 5G trial shows why the distinction matters. In August 2026, SoftBank and Ericsson reported vendor results from a single commercial-network validation of an AI-native scheduler for link adaptation on SoftBank’s 5G network in Japan. The companies evaluated spectral efficiency, downlink user throughput, robustness, and stability under live network conditions. Average gains across the evaluated areas were about 10% for both spectral efficiency and downlink user throughput, while the highest reported gains reached approximately 25% and 50%, respectively. [1]
Commercial-network testing adds something a controlled simulation cannot: exposure to the variability that the system is expected to handle.
IEEE ComSoc TechBlog has already examined the move from AI as an overlay in 5G toward AI-native 6G, along with the developing IMT-2030 requirements and the role of AI in future RANs. [2][3] This article takes a narrower view. It examines how AI-native RAN functions can be trained, coordinated, and tested when wireless conditions, hardware, data, and network topology all change.
6G-MIRAI-HARMONY provides a concrete research setting for that question. The EU-Japan program connects realistic channel and hardware modeling, AI-based physical-layer functions, distributed coordination, AI-ready RAN architecture, and common approaches to data management, benchmarking, and validation. [4][5]
The Research Challenge for AI-Native 6G RAN:
Training data quietly becomes part of an AI model’s operating assumptions. Conventional wireless algorithms are generally built around assumptions that engineers can state explicitly. Machine learning adds another dependency: the examples used during training and evaluation influence what the model learns to recognize as normal.
A model can consequently look robust while remaining sensitive to conditions absent from its training environment.
Wireless conditions can change without the underlying network function changing. Users move through different propagation environments. Traffic loads rise and fall. Carrier frequencies and device characteristics vary. Hardware can introduce quantization, RF impairments, and converter limitations.
Distributed RANs add another layer. Measurements used by one function may come from elsewhere in the network. Beamforming and scheduling decisions can affect later decision cycles. Fronthaul capacity can determine how much information reaches another processing point before a coordinated action has to be taken.
An AI function therefore cannot always be judged as an isolated block. Network behavior around the function can influence the result just as much as the model architecture itself.
6G-MIRAI-HARMONY: Research Approach and Scope:
6G-MIRAI began on April 1, 2025, and runs for 36 months through March 2028 under Horizon Europe and the Smart Networks and Services Joint Undertaking. Grant Agreement 101192369 lists total project costs of €3,188,935 and an EU contribution of €2,979,966.50. Ericsson France is the coordinating organization. [5]
The European consortium includes Ericsson France, Fraunhofer, Telefónica, IS-Wireless, Sequans, Apple Technology Engineering, KU Leuven, CNIT, and the University of Pisa. The associated HARMONY work in Japan brings in organizations including the University of Tokyo, Kyocera, NEC Networks & System Integration, Shimizu, Tokyo University of Agriculture and Technology, and KDDI Research. [6]
Five Research and Technology Items connect the technical work:
- Realistic models and datasets covering channel, hardware, and measurement conditions.
- AI/ML for physical-layer components, including learning-based approaches to wireless functions.
- AI-driven coordination for distributed and cell-free deployments.
- AI-ready 6G-RAN architecture covering where intelligence, data, and computing are placed.
- Data management, testing, and validation for common scenarios and reproducible evaluation. [4][5]
The sequence matters because each part affects the next. Data conditions influence AI training. AI functions interact with distributed coordination. Architecture determines where models can run and what information they can access. Benchmarking and validation determine how the resulting measurements can be compared.
Realistic Models and AI-Based Physical-Layer Functions:
The wireless environment represented in an experiment becomes part of the AI system whether researchers intend it or not.
6G-MIRAI-HARMONY’s methodology combines link- and system-level modeling with analytical evaluation and later laboratory- or prototype-oriented validation. QuaDRiGa is identified for spatially and temporally consistent channel generation, while Sionna supports differentiable communication-system modeling. Measurement data and experimental RAN data provide additional routes toward less idealized evaluation conditions. [4]
Three parts of the modeling chain deserve particular attention:
- The channel: Propagation, mobility, and spatial variation determine the conditions presented to the model.
- The hardware: RF impairments, quantization, finite-resolution converters, and other non-idealities can alter physical-layer behavior.
- The data: Training and test datasets determine which situations the model encounters and which remain unseen.
Those conditions matter for functions such as channel estimation, CSI prediction and compression, neural receivers, precoding, power control, and link adaptation.
Independent research is addressing similar issues. A 2026 study of CNN-based hybrid precoding for cell-free massive MIMO evaluates imperfect CSI, phase noise, channel aging, molecular absorption, and transceiver hardware nonidealities in a THz simulation environment. The reported results include spectral-efficiency gains against several conventional approaches, while the study also measures the effect of individual hardware impairments on performance. [7]
Physical-layer intelligence therefore has to be tested against the radio conditions it is expected to encounter. An improvement under one channel or hardware assumption does not establish the same improvement under another.
Distributed Intelligence for Cell-Free Massive MIMO:
Distributed access points can work together, but the information needed to coordinate them is distributed as well. Beamforming decisions affect interference seen by other users. Scheduling changes the traffic mix entering later decision cycles. Power-control decisions can alter the conditions under which subsequent optimization takes place.
Fronthaul places a direct limit on how much information can be exchanged. Fully centralized processing can require substantial CSI and data transfer as the number of access points and users grows. Practical designs therefore have to balance cooperation against available transport and processing resources.
Independent cell-free massive MIMO research continues to address that scalability problem. A 2025 IEEE Access study describes network overloading and scalability as major design challenges and evaluates a joint pilot and access-point assignment method in systems tested with up to 150 access points. [8] The paper notes that fully centralized processing can create significant fronthaul signaling and computational demands as deployments expand.
Synchronization adds another requirement. Coherent joint processing depends on suitable phase and frequency alignment across distributed access points. A 2024 IEEE Open Journal of the Communications Society study examines phase misalignment among access points in cell-free massive MIMO and evaluates a partially coherent transmission framework designed to reduce the need for network-wide phase alignment. [9]
AI-driven coordination has to operate inside those constraints. Improving beamforming or scheduling is only part of the problem when the information required for that decision is delayed, compressed, or unavailable at the point where the model runs.
Designing an AI-Ready 6G RAN:
Where the model runs can be as important as what the model does.
A latency-sensitive control loop may need processing close to the network element generating the measurements. Another workload may benefit from a larger computational environment with access to a wider network view. Data access, inference latency, model updates, and control interfaces all affect that choice.
Four practical questions follow:
- Where does inference run?
- Which measurements reach the model?
- How frequently are those measurements updated?
- What happens when the required information sits elsewhere in the RAN?
O-RAN already has work addressing part of this problem. Its WG2 specifications cover the Non-Real-Time RAN Intelligent Controller, A1 and R1 interfaces, AI/ML learning and deployment, and the AI/ML workflow. [10]
O-RAN’s current work does not define the final architecture for 6G. It does show where AI lifecycle and deployment questions are already being addressed in today’s RAN architecture. 6G-MIRAI-HARMONY takes those concerns into a research setting that also includes distributed and potentially disaggregated 6G architectures. [4]
Common Data, Benchmarking and Validation:
Performance figures become difficult to compare when the experiments behind them use different conditions. Two studies might report higher spectral efficiency while using different datasets, channel assumptions, training procedures, hardware models, and test conditions. Without those details, the numbers are difficult to interpret.
The 6G-MIRAI-HARMONY D3.1 deliverable addresses this problem directly. It provides the project’s first consolidated framework for benchmarking and validation, data-management principles, and common scenarios. The document places particular emphasis on repeatability, traceability, comparability, data quality, and reuse. It also defines KPI/KVI considerations and protocols for training, evaluation, and generalization. [11] The evaluation chain is shown in Figure 1.
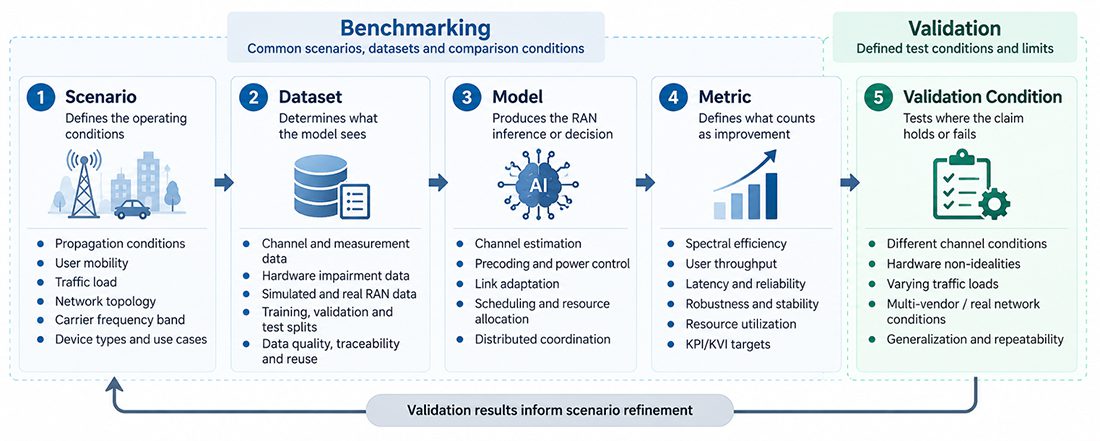
Figure 1. The evaluation chain for AI-native RAN research.
The scenario defines the conditions represented in the experiment. The dataset determines what the model sees. The model is evaluated through selected metrics and then tested under stated validation conditions.
Changing one part of that chain can change the result. An unseen propagation condition may expose a generalization problem. A realistic hardware model may reduce the gain seen with ideal hardware. A different metric may favor a different approach. Benchmarking and validation also answer different questions. Benchmarking establishes common conditions for comparing approaches. Validation examines whether the resulting system behaves as required under defined conditions.
D3.1 is an existing project output. Later deliverables are intended to add datasets and results covering common scenarios, validation, and benchmarking. Those later outputs should remain described as project work rather than completed findings until the corresponding evidence is published. [11][12]
From Research Validation to Standardization:s
ITU-R’s IMT-2030 work has already moved beyond the initial framework.
Recommendation ITU-R M.2160 established the framework and overall objectives for IMT-2030 in November 2023. The framework includes six usage scenarios, among them Artificial Intelligence and Communication (AIAC), and identifies ubiquitous intelligence as one of its overarching design principles. [13]
In February 2026, ITU-R Working Party 5D completed the draft report on minimum technical performance requirements for IMT-2030 radio interfaces. The draft defines 20 minimum technical performance requirements and provides a consistent basis for specification and evaluation. The draft has been submitted to Study Group 5 for consideration in December 2026. [14] In June 2026, Working Party 5D also completed the draft guidelines for evaluating candidate IMT-2030 radio interface technologies. The guidelines define three evaluation methods—simulation, analytical evaluation, and inspection—and specify seven test environments. The draft has likewise been submitted to Study Group 5 for approval in December 2026. [14]
ITU-R’s candidate radio-interface technology submission process is scheduled to begin in February 2027, with the candidate-submission window extending through February 2029. [14] 3GPP is pursuing AI/ML work within the RAN in parallel. TR 38.745, “Study on Artificial Intelligence (AI)/Machine Learning (ML) for NG-RAN Phase 3,” was created for Release 20 on September 5, 2025, and was placed under change control on March 19, 2026. [15]
Research results do not become standards simply because an algorithm performs well in one experiment. The useful evidence includes the conditions behind the result: the scenario, dataset, metrics, validation method, limitations, and reproducibility of the test.
Conclusions:
AI-native 6G RAN will require more than putting machine learning inside individual RAN functions.
Propagation changes. Hardware is imperfect. Network intelligence becomes distributed. Fronthaul and synchronization can limit coordinated processing. Architecture determines where data and computation are available. Training and evaluation conditions affect what an AI result actually shows.
6G-MIRAI-HARMONY brings these issues into one research program by connecting realistic wireless models, AI-based PHY techniques, cell-free coordination, AI-ready RAN architecture, and common approaches to data, benchmarking, and validation. The work points to a practical requirement for AI-native RAN research: performance results need enough information around them to show how they were produced, where they hold, and what changes when the underlying conditions change.
References:
- SoftBank Corp. and Ericsson, “SoftBank Corp. and Ericsson conduct Japan’s first trial of Ericsson AI in RAN on a 5G commercial network,” August 20, 2026.
https://www.ericsson.com/en/press-releases/2/2026/softbank-corp-and-ericsson-conduct-japans-first-trial-of-ericsson-ai-in-ran-on-5g-commercial-network - IEEE ComSoc Technology Blog, “Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020),” January 15, 2026.
https://techblog.comsoc.org/2026/01/15/comparing-ai-native-mode-in-6g-imt-2030-vs-ai-overlay-add-on-status-in-5g-imt-2020/ - IEEE ComSoc Technology Blog, “IMT-2030 (‘6G’) Minimum Technology Performance Requirements for Radio Interface Technologies,” March 17, 2026. https://techblog.comsoc.org/2026/03/17/update-imt-2030-6g-minimum-technology-performance-requirements/
- 6G-MIRAI-HARMONY, “Concept and Methodology,” 2026.
https://6g-mirai-harmony.eu/concept-and-methodology/ - European Commission, CORDIS, “Machine Intelligence based Radio Access Infrastructure (6G-MIRAI),” Grant Agreement No. 101192369.
https://cordis.europa.eu/project/id/101192369 - 6G-MIRAI-HARMONY, “Consortium and Objectives,” 2026.
https://6g-mirai-harmony.eu/consortium-and-objectives/ - Tadele A. Abose and Thomas O. Olwal, “Hardware-Impairment-Aware CNN-Based Hybrid Precoding for Cell-Free Massive MIMO Systems Under Imperfect CSI in Terahertz-Enabled 6G Networks,” Telecom, vol. 7, no. 3, 2026.
https://www.mdpi.com/2673-4001/7/3/70 - Mhammad B. Hmayed and Ali H. Bastami, “Scalable Cell-Free Massive MIMO System: Joint Optimal Pilot and Access Point Assignment,” IEEE Access, vol. 13, pp. 201778–201788, 2025. DOI: 10.1109/ACCESS.2025.3638655
https://ieeexplore.ieee.org/document/11271199 - Unnikrishnan Kunnath Ganesan, Tung Thanh Vu, and Erik G. Larsson, “Cell-Free Massive MIMO With Multi-Antenna Users and Phase Misalignments: A Novel Partially Coherent Transmission Framework,” IEEE Open Journal of the Communications Society, vol. 5, pp. 1639–1655, 2024.
DOI: 10.1109/OJCOMS.2024.3373170.
https://ieeexplore.ieee.org/document/10459246 - O-RAN Alliance, “WG2: Non-Real-time RAN Intelligent Controller and A1,” Technical Work Group scope.
https://www.o-ran.org/technical-groups/wg2 - 6G-MIRAI-HARMONY, “D3.1 — Definition of Initial Common Scenarios, Data Management and Benchmarking Methodology,” 2026.
https://6g-mirai-harmony.eu/wp-content/uploads/2026/02/6G-MIRAI_Deliverable_D3.1_Scenarios_Data_Bench_v1.0.pdf - 6G-MIRAI-HARMONY, “Deliverables, Publications and Workshops,” 2026.
https://6g-mirai-harmony.eu/deliverables-publications-and-workshops/ - ITU-R Recommendation M.2160-0, “Framework and overall objectives of the future development of IMT for 2030 and beyond,” November 2023.
https://www.itu.int/rec/R-REC-M.2160-0-202311-I/en - ITU-R, “IMT towards 2030 and beyond (IMT-2030),” current development, evaluation, and submission process.
https://www.itu.int/en/ITU-R/study-groups/rsg5/rwp5d/imt-2030/pages/default.aspx - 3GPP, TR 38.745, “Study on Artificial Intelligence (AI)/Machine Learning (ML) for NG-RAN Phase 3,” Release 20.
https://portal.3gpp.org/desktopmodules/Specifications/SpecificationDetails.aspx?specificationId=4445
Author Bio:
Shammi Thakur is Research Director at MarkNtel Advisors, with more than 15 years of experience in strategic market intelligence, industry forecasting, and competitive analysis. He leads research initiatives across global technology and communications markets, overseeing the development of market studies and strategic research frameworks. His work focuses on translating complex industry developments into evidence-based insights, with particular experience in emerging technologies, market evolution, and the forces shaping next-generation communication systems.
Website: MarkNtel Advisors
Telcos don’t have an AI problem; they have a voice estate visibility problem
By Satish Barot, Co-founder and CTO, Klearcom with Shazia Hasnie
AI is increasing telecom interdependence
This author has spent around twenty years building telephony products, and the last few watching what happens when AI gets added to them. The models are usually fine, but the voice estates around them are not.
Explanation: The voice estate is everything a voice call touches: the number dialed, the carriers delivering it, the menu that answers, the systems behind it, and in every country/location served.
NVIDIA’s February 2026 survey of roughly one thousand telecom respondents found that sixty percent of organizations are using or evaluating generative AI, up from forty nine percent in its 2024 edition. The voice call that once met a gateway and a queue now meets speech recognition, a language model, a synthetic voice, and also identity checks.
Every one of those can be healthy while the call goes wrong. So the useful test is whether you can prove, from outside your own network, that a real customer’s call still ends the way it should.
Why AI amplifies operational complexity
Old fashioned faults announce themselves: a line drops and something logs it. AI is quieter, and it fails in ways worth naming. It gets worse quietly: a model loses accuracy on one kind of request and nothing reports an error. It’s also confidently wrong. WildASR tested seven speech recognition systems on recordings degraded the way phone audio is. When a caller is cut off mid word, by a network delay or by the system deciding they had finished, the models fill in words nobody said. Further down the line that looks like a clean answer. The same benchmark makes a broader point: robustness measured in one language can substantially mispredict behavior in another, so a release validated in one market tells you little about the next.
Speed fails at the edges, not the average. A system that usually answers in under a second, but takes two and a half seconds on one call in ten, feels broken to those callers and healthy on every voice testing team chart. Nor is the result repeatable: EVA-Bench tested twelve systems and found a wide gap between passing once and passing every time, which undoes testing against a single expected answer.
Then the ones nobody looks at: the fallback menu that takes over when the AI gives up is usually the least maintained thing you own, and it runs exactly when things go wrong. None of this turns a light red on a contact center voice dashboard.
The other exposure is a number that anybody can dial. OWASP ranks prompt injection first among risks to applications built on language models, and a voice channel is an open microphone into the instruction path itself: a caller talks the model out of what it was built and told to do. Mitigations exist and they are worth naming. Treat caller speech as untrusted input and keep the transcript out of the context that carries instructions, constrain what the model can emit to a defined set of intents and slots rather than free text, and require confirmation for anything that moves money, changes credentials, or reads account data back.
The customer journey as the real test environment
Take a composite example, assembled from patterns that recur across multi country voice estates rather than drawn from one operator. An operator runs support numbers in fourteen countries behind one AI system. On Friday the team delivers an updated model and a new synthetic voice. Both pass in testing, no issues. By Monday, the share of calls handled without an agent is up by six points, complaints are up in three countries where the release went live first, and every dashboard is green. Nobody knows why.
The new voice made the menus two seconds longer, and nobody adjusted the window in which the system listens for a caller to stop talking. Callers spoke too early, the system heard fragments, filled the gaps, and guessed just confidently enough to keep a person out of the call.
The headline number improved because failures had stopped escalating. Every part did its job, so nothing raised an alarm. What broke was the outcome, and no single part owns the outcome. People given those same recordings transcribed them easily.
Those failures are not hypothetical. Test calls run by my own team over the past two years have found a global biopharmaceutical company whose menu prompts ran into each other faster than callers could answer, a financial services provider whose speech recognition intermittently failed on the word “agent”, so the route to a human worked on some calls and failed on others, and a healthcare data provider whose misrouted number reached an AI assistant that was never meant to answer it. In every case the systems carrying the call reported nothing wrong.
From system monitoring to outcome validation
Monitoring looks inward: are my systems up? Validation looks outward. It places a real call in country and checks the result against what should have happened: is a customer in this country, on this network, right now, getting the right answer?
Monitoring only sees what you own, and these failures hide inside the part causing them. So the two work together: validation tells you something is wrong and where, monitoring tells you why. Three changes follow. Report three numbers where you currently report one: calls the AI resolved correctly, calls it escalated correctly, and calls it failed. Report the slower calls alongside the average ones, and report by country and carrier instead of one global figure.
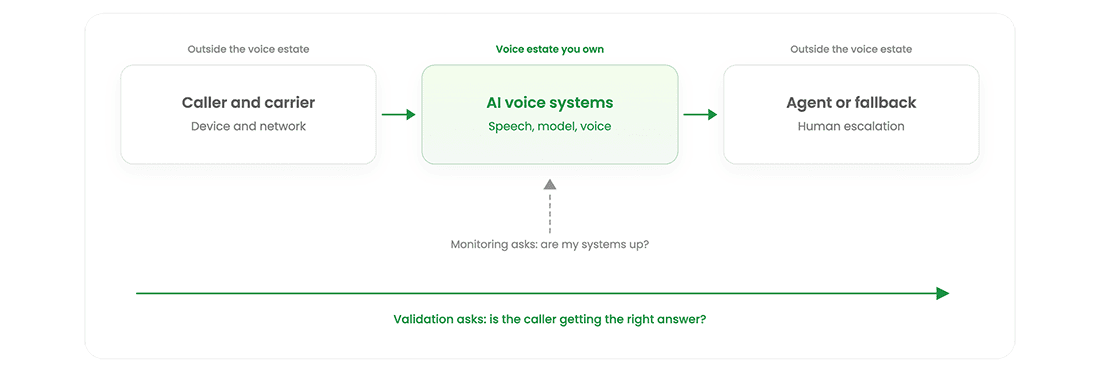
Figure 1. A single call crosses the voice estate an operator owns and systems it does not. Monitoring covers only the shaded stage. Validation traverses the whole path from the caller’s side.
Continuous testing as an assurance layer
The industry already has vocabulary for this. TM Forum’s autonomous network levels give operators a shared scale for how much of the “operate, assure and optimize” loop runs without people, and the same NVIDIA survey places 88% of organizations at Levels 1 to 3 on a scale of 0 to 5. Moving up that scale rests on evidence about delivered outcomes.
If the journey is what breaks, the journey is what you test. That means dialing the real public number, from a real device, on a real carrier in the country the customer is calling from, rather than looping a call back inside your own data center. It means testing from the outside in, and it means doing it on a schedule, across every country and carrier your customers use, fixed and mobile.
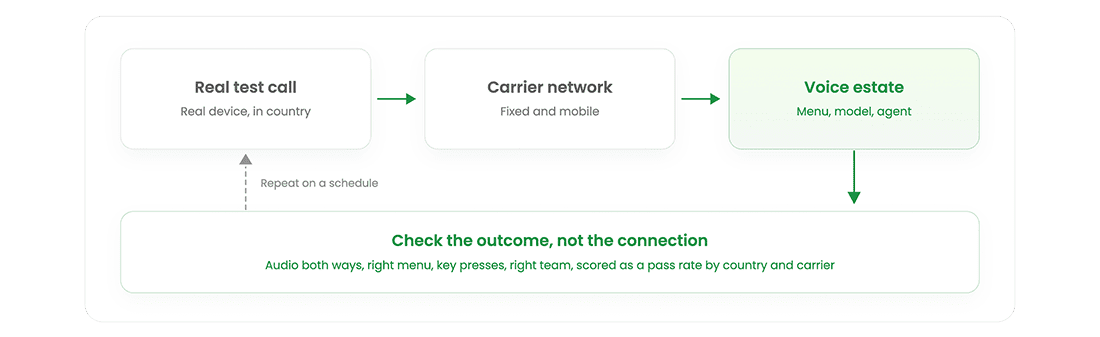
Figure 2. Testing the journey from the outside in. A scheduled call dialed from a real device in the country the customer calls from, scored on the delivered outcome.
Check outcomes, not connections: audio clear both ways, the right menu, key presses registered, the caller reaching the right team with their details intact. Score it across many calls with a library of realistic phrases, accepting a pass rate rather than an exact match, so decline shows as a trend. Treat a model update like a network change: try it on a few numbers first, then pull it back if the pass rate drops.
Several approaches are in this category. Synthetic transaction monitoring from operator owned probes, carrier side test call generation and crowdsourced testing on real handsets all produce outside in evidence, and they trade off differently on country coverage, cost and how closely the test resembles a real customer’s call. The common requirement is that the evidence originates outside the systems being assured, on a call placed in the country where the customer is dialing from.
Practical implications
Keep human escalation as a safety valve, not a number to drive down: cutting it without checking correctness makes the metric look better while the service gets worse. Then give the outcome an owner. Gartner’s June 2025 forecast that over 40% of agentic AI projects will be canceled by the end of 2027 attributes those cancellations to escalating costs, unclear business value and inadequate risk controls. Model capability doesn’t appear anywhere on that list. This is organizational before it’s technical.
These failures are seams between systems that break without producing an error, and monitoring your own equipment cannot see them: the gap sits between what your systems report and what your customer gets. Networks have been tested end to end for decades rather than trusted part by part. Voice estates deserve the same.
References
- NVIDIA (2026) State of AI in Telecommunications: 2026 Trends. Fourth annual survey report, published 19 February 2026, based on responses from 1,038 telecom professionals worldwide. Summary of findings: Survey Reveals AI Advances in Telecom.
- Tay, G., Ma, W., Lee, J., Tang, Y., Lee, D., Yin, W., Shen, D., Meng, S., Zhu, Y., Li, M. and Smola, A. (2026) Back to Basics: Revisiting ASR in the Age of Voice Agents. Boson AI. arXiv preprint arXiv:2603.25727, 26 March 2026. Introduces the WildASR benchmark. Dataset and code: bosonai/WildASR.
- Bogavelli, T., Gauthier Melançon, G., Stankiewicz, K., Bamgbose, O., Riols, F., Nguyen, H.H., Mehndiratta, R., Brin, L.D., Marinier, J., Subramani, H., Madamala, A., Nemala, S.K. and Sunkara, S. (2026) EVA-Bench: A New End-to-end Framework for Evaluating Voice Agents. arXiv preprint arXiv:2605.13841, 13 May 2026, revised 27 May 2026. DOI: 10.48550/arXiv.2605.13841.
- OWASP GenAI Security Project (2025) OWASP Top 10 for LLM Applications 2025. OWASP Foundation. Prompt injection is listed first, as LLM01.
- Gartner (2025) Gartner Predicts Over 40% of Agentic AI Projects Will Be Canceled by End of 2027. Press release, Sydney, 25 June 2025.
- TM Forum (2025) Autonomous Networks Framework v2.0.0 (IG1218F). Introductory Guide, published 20 March 2025, TM Forum Approved 9 May 2025. Levels of autonomy 0 to 5. Evaluation criteria for assigning a level are in Autonomous Network Levels Evaluation Methodology (IG1252).
-
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
………………………………………………………………………………………………………………………………………………………………………..
About the author:
Satish Barot is co-founder and CTO of Klearcom. He has spent around twenty years building telephony products and leads the engineering team behind Klearcom’s voice testing platform.
Bain: AI to greatly increase network operator expenses; network re-engineering needed!
Introduction by Bain:
“Over the next three to five years, the operating cost structure used by telecom operators is likely to undergo one of the most significant shifts in decades. As AI agents become embedded across customer care, network operations, software engineering, and enterprise functions, tokens will account for a growing share of operating expenditures.”
Key Points:
- Unless telcos proactively manage their costs, scaling up AI will simply add expenses to an already-heavy legacy base.
- An agentic operating model is emerging: a 70-to-30 ratio of legacy to AI costs, with AI automating or augmenting work across processes.
- Cost traps lurk: cheaper AI models, bigger bills; bolting AI onto legacy processes; and demos mistaken for transformation.
- Telco leaders can take five key actions today to avoid the traps.
Executive Summary:
Telecom operators are extending AI agents across network operations as they pursue higher levels of autonomy, but the shift could introduce a significant new operating-cost burden unless legacy processes, tooling and organizational structures are retired alongside the automation, according to Bain & Company.
Bain’s warning comes as operators accelerate plans for autonomous networks. TM Forum reported in June that 81% of 80 surveyed operators are targeting Level 4 autonomous networks or higher by 2030, and 20% expect to reach that threshold by 2027.
Under TM Forum’s Autonomous Networks framework, Level 4 moves beyond rule-based or preconfigured automation toward closed-loop, intent-driven decision-making within defined network domains. Current Level 4 work includes deployment of closed-loop operations in production networks, agent-based operating architectures, and metrics intended to quantify the operational and business value of autonomous-network use cases.
-
- Lagging Returns: According to Bain’s Automation and AI Pathfinder Survey, nearly 40% of companies saw AI cost savings land below 10%.
- Growing Budgets: Despite missing initial savings targets, 90% of these companies are still increasing their AI budgets.
- Autonomous Agents: Only 7% of companies currently run fully autonomous AI agents in production. Data access remains the top barrier to progress.
- AI Summaries: Bain’s research on Zero-Click Search shows that 80% of consumers rely on AI-written results for at least 40% of their searches.
- Fewer Clicks: About 60% of searches now end without the user clicking through to another website. This shift reduces organic web traffic by 15% to 25%.
Bain estimates that AI agents and associated token consumption could represent 20% to 30% of a telecom operator’s operating-cost base within the next three to five years, leaving conventional operating costs at 70% to 80%.
As AI spending rises, telcos risk increasing total costs without generating proportional gains in productivity or growth.
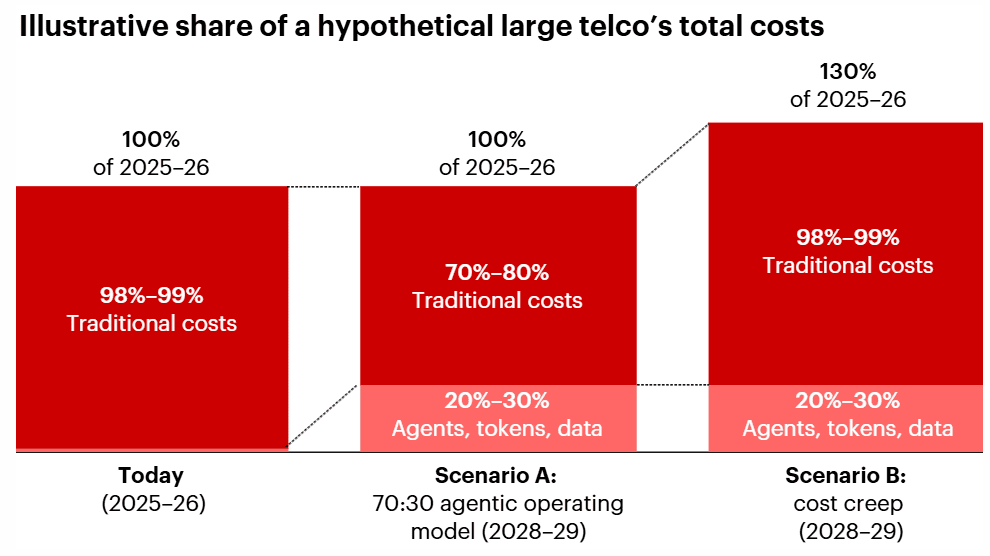
Notes: Illustration doesn’t incorporate absolute value changes; traditional costs are fully loaded, including costs from traditional software-as-a-service and cloud infrastructure, agency/outsourcing, depreciation, and more. Source: Bain estimates
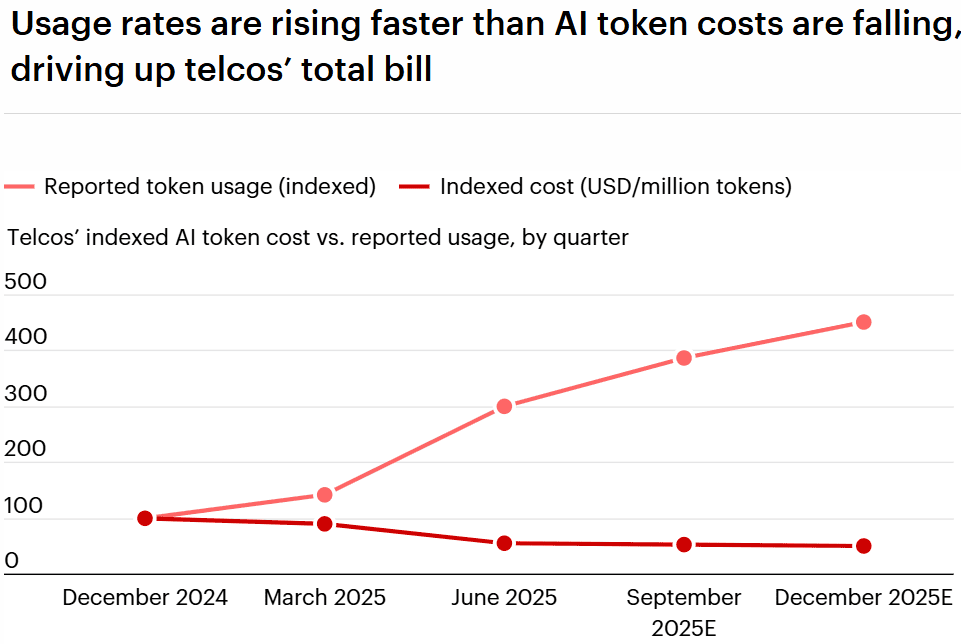
Sources: Wells Fargo (October 2025); Barclays (November 2025); company websites; news and industry reports; Bain analysis.
…………………………………………………………………………………………………………………………………………………………………………………..
However, cost is not the main issue. The principal risk is that network operators can create a parallel operating model when they layer agentic AI onto established network-operations processes without eliminating the people, software, outsourced functions and infrastructure those processes were designed to support.
In that scenario, AI compute, model inference and agent orchestration become incremental expenses, while legacy network operations centers, monitoring platforms, user-facing software licenses, managed-service arrangements and manual operational handoffs remain largely intact.
Network Re-engineering Required:
Avoiding this outcome requires process re-engineering rather than task-level automation. Bain recommends that operators redesign end-to-end workflows around the work agents assume, including:
-
Reducing manual monitoring, ticket triage and operational handoffs.
-
Reassessing workforce requirements as agents absorb repeatable diagnostic and remediation tasks.
-
Reviewing software, tooling and managed-service contracts when agents begin performing functions previously executed through conventional applications or outsourced processes.
-
Removing redundant operational steps rather than simply automating them.
-
Measuring the cost of an operational outcome, rather than the unit cost of model inference or token consumption.
This distinction is especially important in network operations, where an agent may continuously ingest alarms, correlate events, retrieve telemetry, diagnose faults, select a remediation action, trigger network tools, validate results and escalate exceptions to human operators. Each stage can add cost.
Inference is therefore only one component of the AI operating model. A production-grade agentic workflow may also require orchestration, tool and API calls, runtime evaluation, observability, data storage, policy enforcement, security controls, human-in-the-loop escalation and supporting compute infrastructure.
Bain argues that operators should evaluate the complete cost of the resolved operational event. For a service-affecting incident, that includes the total cost of detection, triage, diagnosis, remediation, validation and any remaining human intervention—not simply the marginal cost of the model invocation.
Closed-Loop Operations and Opex Reduction:
Bain cited Vivo in Brazil as an example of an operator redesigning a complete network workflow around AI-enabled automation rather than applying automation to discrete tasks. As part of Telefónica’s Autonomous Network Journey program, Vivo implemented a self-healing mechanism for its virtualized standalone 5G core.
The implementation monitors network-function performance, detects anomalies, identifies root causes and applies corrective actions automatically. It then validates whether the action restored normal operation and can progress to an additional remediation level when required.
Telefónica said the system correlates events across logical and physical infrastructure and completes the detect-to-resolve sequence without human intervention. For the targeted incidents, the company reported a 30-minute reduction in mean time to resolution.
The deployment also reduces repetitive work and manual intervention, while improving the use of computational resources. Telefónica has not disclosed a monetary estimate of the operating-cost savings associated with the implementation, however.
The significance of the Vivo deployment is architectural as much as operational. It integrates detection, correlation, diagnosis, remediation and verification into a closed-loop workflow. That is materially different from deploying an AI assistant within an otherwise unchanged operating model.
Other operator deployments illustrate the potential conventional opex benefits associated with higher autonomy. In a TM Forum case study, China Mobile reported that intelligent agents helped its network operations center achieve Level 4 autonomy under its self-assessment using TM Forum’s Autonomous Networks Levels framework.
China Mobile reported:
-
More than 30% reduction in backend operations-and-maintenance manpower.
-
More than 5% savings in frontline installation-and-maintenance manpower.
-
An average 30% reduction in mean time to repair for network faults and customer complaints.
An earlier TM Forum autonomous-network case study involving China Mobile reported O&M efficiency improvements of 10% to 20%, service-provisioning time reductions of 30% to 50%, and energy-consumption reductions of 3% to 5% across participating internet data centers and base stations.
The reported figures are operator-reported results published through TM Forum case studies. They demonstrate the possible efficiency gains from closed-loop automation, but they do not eliminate the need to account for AI-specific costs such as inference, orchestration, tool execution, supporting infrastructure and operational governance.
Measure Autonomous Networks by Outcomes:
TM Forum is also developing mechanisms to measure the value generated by autonomous-network deployments. In July, it approved version 2.0 of its Autonomous Networks High-Value Scenarios Effectiveness Indicators guide, intended to help operators quantify the impact of Level 4 autonomous-network scenarios.
This outcome-based approach aligns with Bain’s recommendation. For network operations, operators should move beyond narrow AI measures such as token counts, model cost per query or inference latency. Those measures remain operationally useful, but they do not establish whether an AI deployment improves the economics of network operation.
The most relevant measures include:
An operator may accept higher AI spending per workflow if it meaningfully reduces outage duration, truck rolls, customer-impacting incidents, workforce requirements or service-activation delays. Conversely, a deployment that lowers model-inference costs but leaves manual handoffs, duplicate monitoring tools and legacy support structures unchanged may offer limited net operating benefit.
AI Consumption at Telecom Scale:
AT&T has illustrated the potential scale of enterprise AI consumption, although its reported figures span AI workloads across the business and are not limited to autonomous network operations. The operator said in July that it processes an average of 45 billion tokens per day.
AT&T uses an AI gateway to route tasks among models based on cost, latency and expected output quality. The company said the platform can switch models during multi-turn interactions and has reduced costs for certain AI workloads by as much as 90%, producing multimillion-dollar savings.
The operating principle is relevant to telecom network automation: only a minority of tasks require the most capable—and most expensive—models. Routine classification, alarm enrichment, knowledge retrieval, configuration validation and other bounded operational tasks may be suitable for smaller models, purpose-built models or conventional deterministic automation. More capable reasoning models can be reserved for ambiguous, multi-domain or exception-heavy cases.
Bain similarly recommends matching model capability to task complexity rather than applying a single model class across every AI workload. Operators should establish dedicated compute budgets, instrument workflow-level economics and treat inference capacity as an operational resource that requires active governance.
Governing Agentic Network Operations:
Agent behavior itself can become a material source of cost and operational risk. Poorly designed agents may repeatedly transmit large context windows, loop without completing a task, invoke overlapping diagnostic tools or conduct duplicative checks that add token and infrastructure consumption without improving the result.
Bain recommends guardrails that limit both expenditure and runtime. In a telecom network-operations environment, those controls could include:
-
Maximum token, compute and tool-call budgets per incident or workflow.
-
Time limits before an agent must escalate an unresolved task to a human operator.
-
Context-management rules that prevent unnecessary repetition of telemetry, alarms and historical ticket data.
-
Controls to consolidate overlapping diagnostic checks and duplicate agent activity.
-
Policy constraints governing which network changes an agent may propose, execute or validate autonomously.
-
Continuous monitoring for model drift, abnormal agent behavior, spending anomalies and degraded operational outcomes.
-
Explicit business and financial ownership for each production agent and workflow.
The central issue is that autonomous networks will not necessarily lower opex simply because they reduce manual work. Operators must also remove the legacy cost structures that agentic systems replace. Otherwise, AI agents risk becoming an additional layer of expense on top of existing network operations rather than the foundation for a more efficient operating model.
……………………………………………………………………………………………………………………………………….
References:
Bain & Co, McKinsey & Co, AWS suggest how telcos can use and adapt Generative AI
McKinsey: AI infrastructure opportunity for telcos? AI developments in the telecom sector
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
5G infrastructure moves from coverage and speeds to cloud-native, orchestration, automation and AI-assisted networks
Analysis: Nvidia–MediaTek Deepen AI Platform Collaboration -What it Means for AI RAN & DCI
Executive Summary:
Nvidia has expanded its partnership with Taiwan based semiconductor firm MediaTek, committing $3.5 billion to a bond investment the two companies describe as a deepening of their “longstanding collaboration to build the next generations of AI computing platforms.” The move extends Nvidia’s pattern of strategic capital deployment across its compute ecosystem, this time reaching into custom silicon and advanced packaging.
According to the announcement, the collaboration couples Nvidia’s accelerated computing, AI, graphics, and software stack with MediaTek’s capabilities in custom silicon, high-performance computing (HPC), system-on-chip (SoC) design, and advanced packaging. MediaTek vice chairman and CEO Rick Tsai framed the investment as reinforcing a relationship spanning “cloud AI infrastructure, local AI computing and automotive in the era of physical AI,” combining Nvidia’s accelerated-computing and AI software ecosystem with MediaTek’s AI technology portfolio and custom-silicon resources.
Over the past several years, MediaTek has repositioned itself from a supplier of predominantly mid- and low-tier handset chipsets into a presence across smartphones, AI data centers, automotive, and IoT. Securities firm Yuanta Financial Holdings expects the closer alignment to accelerate MediaTek’s transition from edge AI into data-center infrastructure, device-based AI computing, and automotive platforms. Trading in MediaTek shares was suspended on the Taipei exchange Tuesday after the stock hit its daily 10% upside limit. The shares closed at NT$4,315 (about US$136.05), reflecting investor enthusiasm for the deepening of the collaboration.
NVIDIA and MediaTek are collaborating in three major areas:
- AI infrastructure: MediaTek will work with NVIDIA’s NVLink Fusion ecosystem to enable customers to develop custom AI infrastructure designed to integrate with NVIDIA rack-scale systems and AI factories.
- Local AI computing: The companies will continue to collaborate on multiple generations of NVIDIA RTX Spark™ and DGX Spark™ PC chips, powering consumer PCs, AI developer supercomputers and enterprise-class workstations, that integrate NVIDIA GPUs with MediaTek SoCs.
- Automotive: MediaTek and NVIDIA will continue developing platforms for AI-powered, software-defined vehicles in the era of physical AI.
“AI is transforming every computing platform — from the world’s largest AI factories to the PC and the car,” said Jensen Huang, founder and CEO of NVIDIA. “MediaTek is one of the world’s great semiconductor companies, with exceptional expertise in system-on-chip design, connectivity, leading performance and power efficiency. Together, we’re building platforms that bring NVIDIA accelerated computing to new markets and give customers the freedom to create differentiated AI systems at enormous scale.”
“MediaTek and NVIDIA share a vision for making advanced AI computing pervasive across the technology landscape,” said Rick Tsai, vice chairman and CEO of MediaTek. “NVIDIA’s investment strengthens a collaboration that spans cloud AI infrastructure, local AI computing and automotive in the era of physical AI. By combining NVIDIA’s leadership in accelerated computing and AI software ecosystem with MediaTek’s expertise in a diverse AI technology portfolio from edge to cloud, and our leadership position in custom silicon, we can accelerate innovation for our customers.”
Custom AI Infrastructure and NVLink Fusion:
Yuanta identified MediaTek’s participation in Nvidia’s NVLink Fusion as the most consequential element of the arrangement. Through that linkage, MediaTek could support the design of custom AI chips for clients while connecting them directly into Nvidia’s AI infrastructure — a complementary rather than competing role alongside the GPU vendor’s proprietary interconnect fabric.
The scale of the bond purchase also signals Nvidia’s long-term commitment to the relationship. Nvidia, currently the world’s most valuable company at roughly a $5 trillion market capitalization, has been deploying capital aggressively across both upstream and downstream partners. This latest deal, however, inevitably risks overlapping with other Nvidia investments — notably its $2 billion partnership with Marvell, which is also heavily oriented around NVLink Fusion and pitch-for the RAN with a one-chip architecture.
NVLink Fusion vs. Ethernet Scale-Out Interconnect:
NVLink Fusion and Ethernet-based scale-out interconnects target fundamentally different layers of the AI fabric, and the distinction turns on memory semantics rather than raw link rate. NVLink Fusion sits in the scale-up domain: it delivers memory-coherent, tightly coupled attachment for custom XPUs into Nvidia’s rack-scale NVLink fabric, with point-to-point GPU/XPU-to-GPU/XPU connectivity and an integrated high-bandwidth-memory interface (NVHBM) that trades die area and power for latency and bandwidth. It is proprietary, closed, and full-coherency by design — precisely the properties that make it hard for open standards to clone. Ethernet scale-out, by contrast, is the scale-out workhorse governing traffic between racks, pods, and clusters; it is loss-based, coarser-grained, and standardized through Ultra Ethernet and the broader IEEE 802.3 ecosystem.
The real contest is not NVLink against Ethernet so much as how much of the memory-coherent scale-up domain Ethernet-based challengers can capture. Standards-backed alternatives — UALink 2.0, Ultra Ethernet, and Broadcom’s Scale-Up Ethernet (SUE) — are pressing into scale-up territory, but they lack NVLink’s memory coherency and direct XPU-to-XPU connectivity, and SUE explicitly does not wire GPUs directly to GPUs. Meanwhile Nvidia’s strategy with NVLink Fusion is to co-opt custom XPUs (AWS Trainium4, and now MediaTek- and Marvell-designed silicon) into its fabric rather than let them migrate to those open scale-up paths. The practical outcome in the data center is a layered model — Ethernet surging in scale-out, and NVLink Fusion consolidating the latency-sensitive, memory-coherent scale-up spine — with Nvidia working to keep its proprietary layer the mandatory gateway that custom accelerators must pass through to reach the wider Ethernet-based world.
The $3.5 billion convertible-bond investment is best read not as a portfolio decision but as a defensive move within the AI rack-scale interconnect stack. The technical centerpiece is MediaTek’s adoption of the NVLink Fusion platform. Nvidia positions it as the connectivity technology and intellectual property that lets hyperscalers and AI-native operators drop custom accelerators (“XPUs”) and CPUs directly into its NVLink scale-up fabric.
MediaTek will now build against the three subsystems that define NVLink Fusion: the NVLink Fusion chiplet, which bridges a customer’s custom XPU to the NVLink scale-up domain over photonic or electrical interconnects (the chiplet itself carries up to ~1.8 TB/s of bidirectional bandwidth); NVLink-C2C, the high-bandwidth die-to-die link between XPUs, Nvidia’s Vera/Rosa CPUs, and other compatible processors; and NVHBM, a customized high-bandwidth-memory interface that trades off die area and power efficiency. The strategic significance is that Nvidia is effectively licensing its interconnect and memory layer as a licensable subsystem rather than enforcing a closed, all-Nvidia island — which lets it absorb “frenemy” silicon into the fabric instead of fighting it.
Two implications stand out for interconnect strategy:
-
A hedge on hyperscaler in-house silicon. AWS has already integrated its Trainium4 custom ASICs with NVLink Fusion for rack-scale deployment, and Google, Meta, Microsoft, and OpenAI are all advancing private accelerators. By standardizing the interface (NVLink Fusion, NVLink-C2C, NVHBM, chiplets, and rack-scale integration) that these custom XPUs must speak, Nvidia keeps chiplets, packages, memory, and racks—the connective infrastructure itself—inside its own revenue funnel. MediaTek, in turn, becomes the design conduit that helps hyperscalers and frontier model firms get to that tape-out without building an independent scale-up stack.
-
The scale-up vs. scale-out contest sharpens. NVLink remains essentially the only mature, memory-coherent scale-up fabric in production, whereas Ethernet is consolidating its dominance in scale-out (front-end and increasingly AI back-end) fabrics, and standards like Ultra Ethernet, UALink, and Broadcom’s Scale-Up Ethernet (SUE) are pressing into the scale-up domain. UALink and SUE, notably, lack NVLink’s memory coherency and point-to-point GPU-to-GPU connectivity, so NVLink Fusion’s positioning — co-opting custom XPUs rather than competing with them — lowers the attack surface those open standards could otherwise exploit.
The buy-in therefore consolidates Nvidia’s grip on the two layers that are hardest to commoditize: the latency-sensitive scale-up interconnect and the custom-silicon design flow that feeds it. What operators and chip partners give up is architectural independence — the bond structure and NVLink Fusion licensing effectively bind MediaTek into Nvidia’s ecosystem rather than allowing it to become an independent AI data-center silicon house.
What It Means for AI-RAN:
For the RAN, this is arguably a more consequential signal than the data-center economics. Nvidia’s AI-RAN play, via the AI Aerial software-defined accelerated-computing platform and its founding role in the AI-RAN Alliance, is built on having vRAN and AI workloads share the same GPU-accelerated infrastructure — what the community variously calls “AI for RAN,” “AI on RAN,” and “AI-and-RAN” on common hardware.nvidia+1
Here the MediaTek deal intersects directly with Nvidia’s earlier $2 billion Marvell partnership, which last year wired Marvell into the same NVLink Fusion platform for both the AI factory and AI-RAN ecosystem — Marvell supplying custom XPUs and NVLink Fusion-compatible scale-up networking, while Nvidia contributes the Vera CPU, ConnectX NICs, BlueField DPUs, Spectrum-X switches, and the rack-scale AI compute. The two arrangements are complementary in practice but overlapping in intent: Marvell owns the scale-up networking and the “one-chip-to-rule-the-RAN” custom silicon angle, while MediaTek brings SoC design, advanced packaging, and stronger reach into edge, automotive, and device-grade silicon. Together they give Nvidia two design houses capable of producing custom XPUs that plug into both data-center racks and AI-RAN infrastructure.
The operative question for IEEE readers is whether this broadens the AI-RAN supplier base going forward. Ericsson and Samsung have indicated their vRAN software built for Intel could be ported to AMD or Arm silicon with relatively modest effort, and Dell’Oro projections already have AI-RAN taking a significant share of the broader RAN market. Nvidia’s strategy is to ensure that, however the RAN silicon shakes out, the scale-up fabric and the custom-XPU design path remain NVLink Fusion-based — extending its data-center interconnect franchise into the radio access domain itself. The risk, flagged in the news report, is over-concentration: stacking Marvell and MediaTek onto the same NVLink Fusion foundation concentrates architectural leverage in Nvidia’s hands and could crowd out the open, multi-vendor fabric choices that O-RAN advocates would prefer to see served by standard Ethernet and UALink-style paths.
References:
https://www.lightreading.com/finance/nvidia-tips-3-5b-into-mediatek-in-latest-tech-partnership
Analysis: Nvidia’s $2 billion investment in Marvell; NVLink Fusion ecosystem & RAN vendor silicon strategy
Ericsson and MediaTek Demonstrate 3GPP-Based GNSS RTK Positioning with Sub-30cm Accuracy Over a Commercial 5G Network
5G infrastructure moves from coverage and speeds to cloud-native, orchestration, automation and AI-assisted networks
MediaTek overtakes Qualcomm in 5G smartphone chip market
Structured Error Analysis: The Missing Pre-Deployment Step for Machine Learning in Telecom Operations
By Priyank Jain with Alan J Weissberger
Introduction:
Machine learning now sits inside telecom operations. Models predict equipment failures before they become outages, forecast traffic for capacity planning, flag telemetry anomalies, and estimate quality of experience from indirect signals—decisions that carry real financial weight. Yet most teams still approve a model for deployment on a single number: accuracy, AUC, or a concordance index computed once on a held-out set. That number is a poor predictor of production behavior. This post argues that structured error analysis belongs before deployment, and walks through five failure modes a single aggregate metric reliably hides.
Terms:
Training fits parameters on historical data; inference applies the fitted model to new data in production. These are two different software environments, and that difference causes more production failures than bad modeling does. Train-serve skew is any gap between training and serving conditions [10]. A fault-prediction model trained on offline-cleaned, gap-filled, five-minute telemetry may encounter a streaming collector that handles missing samples differently and closes its window a few seconds early. A feature named mean_utilization_5m exists in both places and means something slightly different in each. Nothing errors; accuracy just quietly drops.
Censoring matters whenever a model predicts time-to-event. An asset that has not failed yet is censored: we know it survived to now, not how long it will last. Censored observations are legitimate training data; mislabeled ones are poison [4], [5]. Data drift is a change in the model’s inputs—a firmware release that changes how a counter is reported [1], [2]. Concept drift is a change in the underlying relationship—say, a topology change that makes a predictive signal meaningless [3]. Both degrade a validated model, and neither appears in the original evaluation. The residual—the gap between prediction and outcome for one case—is the raw material of error analysis.
Five Failure Modes:
Environment mismatch. Models rarely fail because the mathematics was wrong; they fail because training misrepresented production. A feature computed one way offline and another online, a timezone off by an hour, a normalization constant recomputed over the wrong window—each is trivial, and together they are the most common reason validated performance does not survive deployment. The defense is computing features once and consuming them in both paths. Where that is impossible, run an automated comparison: sample cases, compute features through both paths, and assert agreement within tolerance. Sharing one feature pipeline and persisting trained preprocessors prevents this.
Wrong population. A time-to-failure model over a fleet defines the population by a rule such as “decommission date is empty.” That looks reasonable but is wrong whenever a status field and a date field disagree. An asset marked failed that never had a decommission date written satisfies the rule; the model treats it as healthy and learns that dead things are alive. Survival estimates come out optimistic, worst where data hygiene is worst. Every model-side metric looks fine because the model faithfully learns its labels. When a result contradicts domain knowledge, interrogate the population definition before touching the model.
Metric too good. If a feature table is assembled alongside the outcome, the outcome—or a near-copy such as observed duration—can end up in the feature set, and the model reports near-perfect discrimination. The same happens with fields populated only after the event, such as a diagnostic code set once a fault is confirmed. These are not predictive features; they are the answer arriving late. Treat an unexpectedly excellent score as a bug report and audit whether each feature would be available at scoring time and could have been influenced by the outcome.
The average hid the failure. A single metric over an evaluation set is an average, and averages destroy structure. An anomaly detector at 94% accuracy nationally is consistent with 97% on dense urban sites and 61% on rural sites with sparse telemetry. The aggregate is not wrong; it just does not answer where the model can be trusted. Networks are heterogeneous—multiple hardware generations, uneven telemetry coverage—and model performance is almost never uniform across that variation. The weakest segments usually have the least training data and matter most operationally.
Wrong objective. A model minimizes a loss that stands in for the outcome you care about. When the two drift apart, the model optimizes the stand-in faithfully and fails the objective—Goodhart’s law inside a training loop [6], [7]. In operations the common form is class imbalance: a maintenance model drives aggregate loss down by predicting no failure for a rarely failing class, learning to ignore the cases it was deployed to find [8], [9]. A subtler form ignores cost asymmetry—a missed fault causing an outage and a false alarm wasting a site visit are not equally expensive, but a symmetric loss treats them as equal. State the operational objective in plain language before training, then ask whether the loss actually rewards it.
The Procedure:
Structured error analysis characterizes where and how a model is wrong, not how often. The output is a map of competence. Five steps: build an evaluation set that looks like production, deliberately including every hardware generation, site class, and traffic regime; score and keep everything—prediction, outcome, residual, and full feature vector; stratify by operationally meaningful dimensions and recompute performance within each segment; cluster the residuals to find signatures in data quality, configuration, or thinly sampled regions; and write a disposition for each cluster—fix, accept and document, or exclude from operating scope. That document, the explicit statement of where the model can and cannot be trusted, is the actual artifact of validation.
The artifact also builds operator trust. Engineers dispatching a crew want to know when to believe the model; an aggregate figure is not actionable. A ranked risk score with its two or three drivers attached becomes a claim network operators can check, agree with, or push back on. Models are ignored far more often for being unexplainable than for being inaccurate.
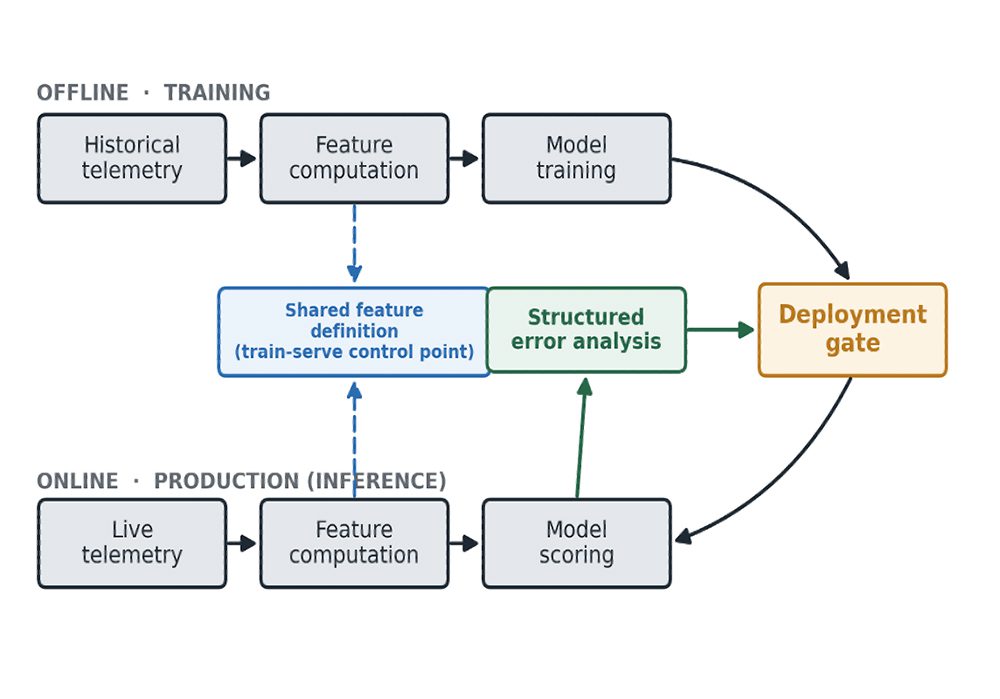
Figure 1. Validation architecture. Features are defined once and consumed by both the training and inference paths (the train-serve control point). Model scoring feeds structured error analysis, whose results decide whether a model clears the deployment gate.
Conclusions:
If a model reports a quantity over a horizon longer than the observed data, part is measurement and part is assumption—report the split, test against several tail assumptions, and decline horizons where extrapolation dominates. That omission matters because the two parts carry very different risk: a precise-looking figure can be almost entirely assumption, and any decision anchored to it—capital planning, replacement schedules, contractual commitments—inherits a fragility nobody has accounted for. Reporting the split is the difference between acting on evidence and acting on a guess wearing a decimal point.
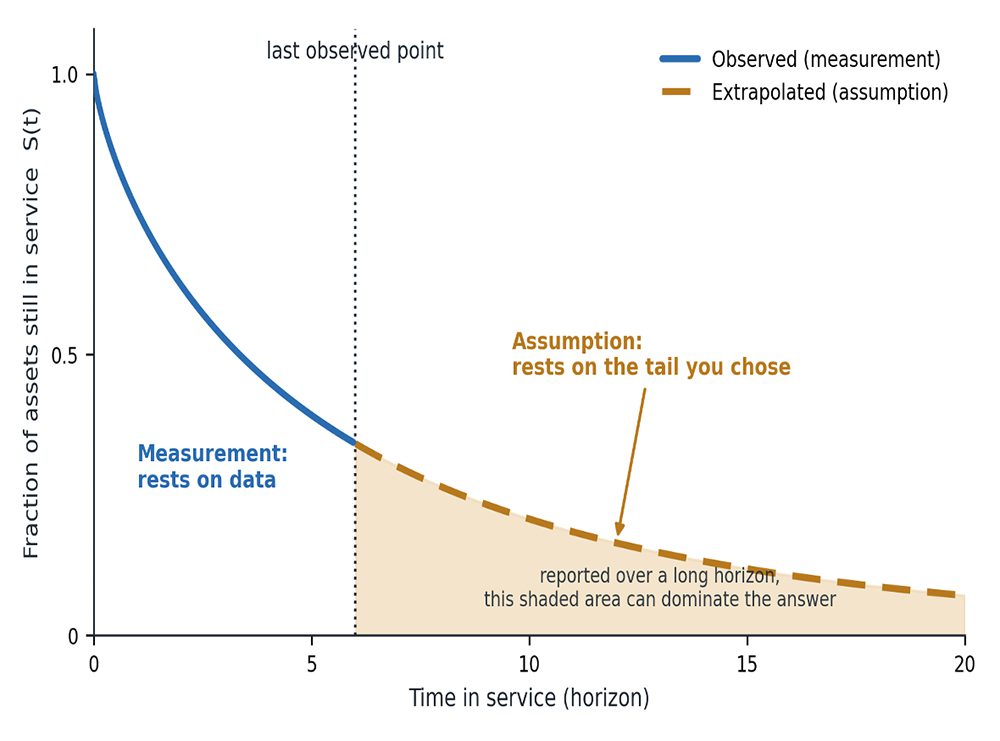
Figure 2. Reporting beyond the observed window, shown for an equipment time-to-failure (survival) model. Up to the last observed point the fraction of assets still in service rests on data (solid); beyond it, the curve rests on a chosen tail assumption (dashed). When such a model reports remaining useful life over a long horizon, the assumed portion can dominate the reported number.
Second, validation expires: because of drift, a model is only validated as of a date. Repeat the error analysis on a fixed cadence against recent data, compare segment-level results to baseline, and give every deployed model a named owner, a review date, and documented dependencies [10], [11]. The absence of a decommissioning plan turns a stale model into a permanent liability.
For telecom operations, where networks are heterogeneous and the consequential cases are usually the rare ones, the recommendation is blunt: require the error map, not the accuracy number, before deployment.
About the Author:
Priyank Jain is a Data Scientist II at Boost Mobile, where he builds production machine learning across retail and telecom, including subscriber survival and churn models, demand and traffic forecasting, and location recommendation systems. He has over seven years in applied machine learning, is an IEEE graduate student member, and has authored peer-reviewed journal and conference papers.
LinkedIn: https://www.linkedin.com/in/priyankjn7/
………………………………………………………………………………………………………………….
References:
[1] “What is data drift in ML, and how to detect and handle it,” Evidently AI, Jan. 9, 2025. [Online]. Available: https://www.evidentlyai.com/ml-in-production/data-drift
[2] “What is data drift in machine learning,” Chalk AI, Apr. 9, 2026. [Online]. Available: https://chalk.ai/blog/data-drift
[3] “Concept drift,” Wikipedia. [Online]. Available: https://en.wikipedia.org/wiki/Concept_drift
[4] “Survival analysis and interpretation of time-to-event data,” PMC/NIH, Jul. 13, 2018. [Online]. Available: https://pmc.ncbi.nlm.nih.gov/articles/PMC6110618/
[5] “Survival analysis,” Wikipedia. [Online]. Available: https://en.wikipedia.org/wiki/Survival_analysis
[6] “Measuring Goodhart’s law,” OpenAI, Apr. 13, 2022. [Online]. Available: https://openai.com/index/measuring-goodharts-law/
[7] “On Goodhart’s law, with an application to value alignment,” arXiv:2410.09638, Oct. 12, 2024.
[8] “Class-imbalanced datasets,” Google Machine Learning Crash Course. [Online]. Available: https://developers.google.com/machine-learning/crash-course/overfitting/imbalanced-datasets
[9] “5 effective ways to handle imbalanced data in machine learning,” MachineLearningMastery, Apr. 20, 2025. [Online]. Available: https://machinelearningmastery.com/5-effective-ways-to-handle-imbalanced-data-in-machine-learning/
[10] “MLOps: Continuous delivery and automation pipelines in machine learning,” Google Cloud, Aug. 28, 2024. [Online]. Available: https://docs.cloud.google.com/architecture/mlops-continuous-delivery-and-automation-pipelines-in-machine-learning
[11] “MLOps lifecycle: Stages, workflow, and best practices,” LaunchDarkly, May 30, 2026. [Online]. Available: https://launchdarkly.com/blog/mlops-lifecycle/
South Korean startup Rebellions to use open source software for carriers to quickly build AI stacks with its AI inferencing chips
South Korean chip startup Rebellions builds purpose-engineered Al accelerators to redefine energy-efficiency and scale in the age of large-scale Al. It aims to deliver the best performance per dollar per watt possible for inferencing and lower both capex and opex associated with running AI infrastructure. The company has been very selective about where it has established office locations and staffing: Korea, Japan, Singapore, Saudi Arabia and the United States.
Their flagship semiconductor product is the Rebel100, which uses a predictive, software-controlled DMA engine tightly coupled with an on-chip mesh to prefetch KV data proactively. This enbales 2.7TB/s effective bandwidth and reduces token-level latency in 32K+ context LLMs.
Image Credit: Rebellions
Gaining valuable experience in building an AI stack with SK Telecom, it’s pairing its field experience with an open source-first software strategy it said can help carriers move faster without locking scarce engineering talent into yet another proprietary AI stack. The company says it’s dedicated to using open-source software – everything from vLLM and OpenShift to PyTorch – with a “no forks” rule. The rule is designed to help customers avoid skills issues and ensure engineers don’t have to learn non-transferrable skills just to use its equipment.
Rebellions’ work with SK Telecom (SKT) has served as a foundational pillar of its engagement with other operators, according to Marshall Choy, Rebellions’ Chief Business Officer (CBO). The company is in conversations with between 10 and 20 operators around the world.
“Our systems have been deployed at SKT for nearly three years,” Choy said. “What does that mean? It means three years of lessons learned, institutional knowledge gain, product improvement and deep engagement with an end user customer working on real problems… It’s three years of blood sweat and tears that has become institutional knowledge,” he added.
The network operators in its pipeline are in “different stages of engagement and deployment” with Rebellions, Choy said, saying there will be “more to come on that.” While SK Telecom has been its most publicized partner to date, Choy said over the next 12 months Rebellions plans to highlight more of what has been going on under cover. That includes work with other telecom operators as well as neocloud operators, enterprises and governments.
According to Choy, the architecture prioritizes low-latency, high-throughput compute infrastructure. From a cost-efficiency perspective, the company targets a price-to-performance ratio that is two to three times more cost-effective than comparable Nvidia hardware. Furthermore, Rebellions delivers significantly higher energy efficiency. While an Nvidia DGX GB200 NVL72 system consumes upwards of 120 kilowatts per rack, Rebellions averages 4 kilowatts per system, or approximately 20 kilowatts per rack.
Choy noted that this power reduction yields a 6x savings in operational expenditure (OpEx). It also enables telecommunications providers to deploy Rebellions infrastructure in edge environments with stringent power constraints, such as legacy central offices. By retrofitting these distributed facilities with modern inference compute to serve LLM tokens, operators can maximize the lifecycle and return on investment (ROI) of their existing physical assets.
“Our goal is to reduce the unit economics of AI inferencing to near zero,” Choy said. While he admitted that sounds strange coming from an AI inferencing chip company, Choy explained that it’s all about making AI accessible for even more use cases – the ones where the math doesn’t work out today. “If you’re a telephone operator and you have an existing line card of services you provide, I can make you more profitable because I can lower your costs. But more strategically, what I can do is I can enable you to introduce a lower tier of services at a lower cost, which then makes AI inferencing accessible to a whole set of applications where it was previously too expensive,” he added.
It should be noted that Groq and SambaNova (see References below) are similarly working on chips to reduce the cost of inferencing. OpenAI appears to be moving in a similar direction with its Jalapeño chip.
Through its work with SK Telecom and others (unnamed), Choy said Rebellions has learned that customers aren’t just looking for hardware or software but for fully optimized infrastructure that cuts across both. That’s where Rebellions’ open-source ethos comes into play. “We didn’t want to have this mainframe model where everything is custom and bespoke and we’re this weird thing off in the side of the data center that doesn’t get touched by anything else,” Choy said. “It’s all about interoperability and integration.”
In conclusion, Choy opined, “Let’s be honest, the telcos don’t necessarily have all the right skills in place. So, being able to spread that across more of an open-source ecosystem means they can be in service and productive faster.”
References:
https://rebellions.ai/company/about/
https://rebellions.ai/category/blogs/
https://rebellions.ai/rebellions-product/rebel100/
SambaNova targets AI inference boom with chips built for existing data centers
Intel and AI chip startup SambaNova partner; SN50 AI inferencing chip max speed said to be 5X faster than competitive AI chips
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
Custom AI Chips: Powering the next wave of Intelligent Computing
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
Superclusters of Nvidia GPU/AI chips combined with end-to-end network platforms to create next generation data centers
Ericsson leads SK Telecom AI RAN vs. NVIDIA’s GPU centric AI RAN Alliance
Executive Summary:
Ericsson says it has been selected as the sole global technology partner in SK Telecom’s consortium for Korea’s Hyper-AI Network Infrastructure Demonstration Project, a South Korea government-backed initiative led by the Ministry of Science and ICT and the National Information Society Agency. The program is intended to validate AI-RAN pilot networks as a cornerstone of Korea’s national “AI Highway” strategy and its longer-term 6G roadmap.
Ericsson’s contribution [1.] to this project centers on the RAN and the automation layer that surrounds it. According to Ericsson, its role in the project includes 5G Standalone expertise, AI-in-RAN capabilities, and intelligent network automation through the Ericsson Intelligent Automation Platform (EIAP) and AI-powered rApps, enabling autonomous control, resource orchestration, and real-time optimization for physical AI services. Ericsson is not being positioned as a general AI infrastructure provider, but as the core network technology partner bringing telco-grade RAN, automation, and orchestration into a live industrial validation environment. Ericsson will contribute what it calls an “end-to-end network foundation” to the project that is intended to connect and continuously optimize intelligent machines and autonomous industrial operations. In the second phase of the project, Ericsson’s AI-RAN pilot network is expected to be applied to a real-world logistics environment at KG Mobility’s Pyeongtaek plant.
Note 1. It’s interesting to note that Ericsson is a founding member of the Nvidia GPU centric AI-RAN Alliance, contributing the operator-centric “AI-for-RAN” perspective by embedding telco-grade AI into basebands and radios to improve network performance, automation, and energy efficiency. The company’s delegates hold leadership roles in the alliance’s working groups and technical committees.
For telecom operators, the significance is not just radio performance but the shift toward a network architecture that can support physical AI use cases with tighter latency, stronger uplink capacity, and higher service assurance. SK Telecom plans to demonstrate AI-RAN pilots through 2027 across scenarios such as autonomous transport, industrial safety monitoring, and humanoid robotics, with a second-phase deployment targeted for KG Mobility’s Pyeongtaek plant.
Sibel Tombaz, Head of Customer Unit Korea, Ericsson, says: “Being selected as a key global technology partner in this government-backed Hyper-AI Network consortium is a significant recognition of Ericsson’s technology leadership and our long-term partnership with SK Telecom. Korea is moving with clear ambition to shape the future of AI-native networks and 6G, and Ericsson is proud to contribute our global expertise in 5G, AI-RAN, orchestration, and intelligent network automation to this important national initiative. We look forward to working closely with SK Telecom and the consortium partners to help turn Korea’s 6G vision into real industrial value.”
Takki Yu, VP and Head of Network R&D at SK Telecom, says: “As a key national project supporting Korea’s Hyper-AI Network strategy, SK Telecom is pleased to collaborate with Ericsson as a key technology partner to advance AI-RAN technology through global cooperation. Together, we aim to build a strategic win-win partnership, demonstrate real industrial value, and help strengthen Korea’s AI-RAN technology capabilities and ecosystem for the future.”
Comparison with NVIDIA GPU centric AI-RAN Alliance:
The SK Telecom–Ericsson initiative and the NVIDIA-led AI-RAN ecosystem share a common thesis: the RAN is evolving into a distributed compute platform that can host or coordinate AI workloads closer to where data is generated. But they emphasize different layers of the stack. SK Telecom’s Ericsson-led project is centered on operator-grade RAN validation, network autonomy, and physical AI service delivery in industrial settings, while NVIDIA’s effort is broader and more compute-centric, tied to AI factories, GPU infrastructure, and open 6G ecosystem development.
- NVIDIA is a founding member of the AI-RAN Alliance and acts as one of its most visible technical drivers, contributing reference architectures and accelerated-computing platforms for AI-RAN.
- Ericsson is the operator-focused RAN technology partner proving AI-RAN in live telco and industrial network deployments.
The practical takeaway is that Ericsson’s role is more narrowly telecom-native, while NVIDIA’s consortium is more infrastructure- and compute-oriented. For 6G, the two approaches are complementary rather than contradictory: one is proving how the network behaves as a deterministic industrial platform, the other is building the compute substrate that can feed AI-native services into that platform.ericsson+2
Why it matters:
SKT announced the Hyper-AI Network Infrastructure Development project last month, and at the time Ericsson, Nokia, Samsung and private mobile networking specialist HFR were named as those providing the kit and related network and software solutions.
South Korea has become one of the most advanced and competitive mobile markets, and this makes it a useful proving ground for AI-RAN. If the SK Telecom pilot succeeds, it could strengthen the case that future mobile networks must support not only connectivity, but distributed inference, orchestration, and machine control for robots, vehicles, and industrial systems.
From a standards and market perspective, the more interesting question is how these pilots influence the eventual division of labor between RAN, edge compute, and centralized AI infrastructure in 6G-era networks. That is where the SK Telecom–Ericsson model, with its operator-led network validation, may prove especially influential.
…………………………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.ericsson.com/en/press-releases/2026/8/skt-hyper-ai-consortium
https://www.telecoms.com/ai/ericsson-named-sole-global-vendor-for-sk-telecom-s-hyper-ai-consortium
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Dell’Oro: AI RAN revenue forecast: $35B from 2026-to-2030; 3 types of AI RAN explained
Dell’Oro: RAN Market Stabilized in 2025 with 1% CAG forecast over next 5 years; Opinion on AI RAN, 5G Advanced, 6G RAN/Core risks
Dell’Oro: Analysis of the Nokia-NVIDIA-partnership on AI RAN
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
Dell’Oro: AI RAN to account for 1/3 of RAN market by 2029; AI RAN Alliance membership increases but few telcos have joined
Dell’Oro: RAN revenue growth in 1Q2025; AI RAN is a conundrum