AI/ML
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Introduction:
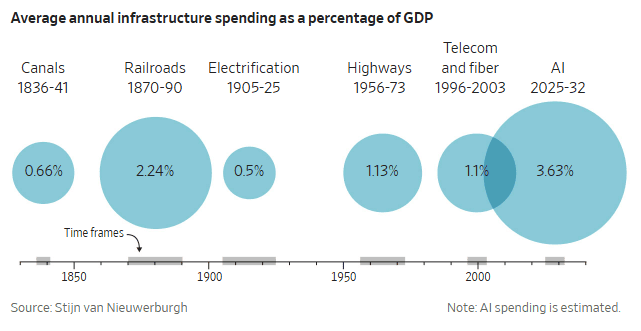
According to the Wall Street Journal, the AI build-out is rapidly becoming the largest concentrated infrastructure investment cycle in modern American economic history. Unlike earlier national build-outs—railroads, interstate highways, electrification, or the commercial internet—this cycle is being driven largely by a small group of cloud platforms deploying highly specialized compute, networking, power, cooling, and semiconductor infrastructure at unprecedented speed. Economist Stijn van Nieuwerburgh estimates that U.S. spending on data centers and related AI infrastructure could reach $10.3 trillion [1.] between 2025 and 2032, equivalent to an average of 3.6% of annual GDP. The estimate encompasses far more than conventional enterprise data centers: it reflects the industrial-scale infrastructure needed to train and serve frontier AI models, including GPU and accelerator clusters, high-bandwidth memory, advanced packaging, optical interconnects, high-capacity Ethernet and InfiniBand fabrics, grid interconnection, substations, backup generation, liquid cooling, and long-haul fiber connectivity.
Note 1. The $10.3 trillion number is a scenario-based estimate of U.S. AI infrastructure investment during 2025–2032—not a forecast of announced corporate spending. The Brookings analysis behind it assumes that about 183 GW of new data-center capacity will be completed through 2032, versus a 509-GW announced/planned pipeline. A representative 200-MW AI campus is estimated to cost about $8.2 billion: $5.6 billion for IT equipment, $2.2 billion for the facility, and $0.4 billion for power infrastructure. Thus, most of the investment is in compute and networking hardware rather than buildings. The scale creates a major financing challenge: the five largest hyperscalers are projected to spend about $800 billion on capex in 2026, exceeding their combined operating cash flow. Under the Brookings assumptions, the resulting infrastructure would need roughly $3.7 trillion of annual revenue by 2032 to produce a 10% unlevered return. The key economic issue, therefore, is whether future AI revenue and utilization can justify the enormous capital investment.
From Cloud Data Centers to AI Factories:
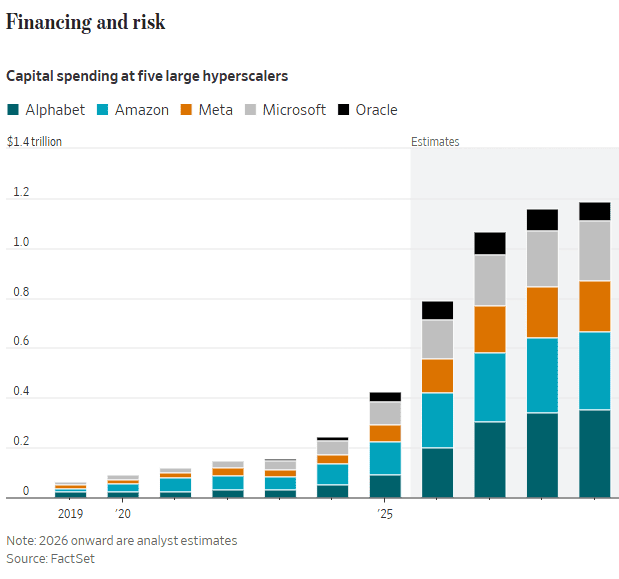
The defining characteristic of this AI buildout investment cycle is its concentration. The five U.S. hyperscalers (Alphabet, Amazon, Meta, Microsoft, and Oracle) are collectively expected to invest roughly $4.2 trillion in capital expenditures during the four years ending in 2029, according to FactSet estimates cited in the source material. Increasingly, this capital is directed toward AI-optimized facilities: campuses designed around megawatt-scale accelerator pods, dense GPU clusters, high-radix network fabrics, and power delivery systems capable of supporting workloads whose energy and cooling profiles differ sharply from those of traditional cloud computing.
Those five major hyperscalers increased combined capital expenditures from approximately $97 billion in 2020 to more than $400 billion in 2025, with the paper projecting approximately $800.5 billion in 2026. That 2026 figure is significant because it exceeds their combined operating cash flow of approximately $707.1 billion. In other words, projected capex is about 113% of operating cash flow. Pacific Software Ventures That creates a MAJOR financing problem: AI infrastructure investment is becoming too large to be financed entirely from hyperscaler internally generated cash.
AI infrastructure is not simply an expansion of conventional cloud capacity. Large-model training and inference create a distinct systems-engineering problem. Training AI frontier foundation models requires thousands to hundreds of thousands of tightly coupled accelerators. Those accelerators must exchange model parameters, activation data, and gradients at extremely high rates. Network performance therefore becomes a first-order determinant of usable compute capacity. A GPU cluster can deliver poor economics if its fabric introduces congestion, latency, packet loss, or inadequate bisection bandwidth during distributed training.
That requirement is accelerating deployment of:
-
GPU- and AI-accelerator servers with high-bandwidth memory and advanced semiconductor packaging.
-
High-speed scale-up interconnects within accelerator nodes and scale-out fabrics across clusters.
-
400 GbE, 800 GbE, and emerging 1.6 TbE Ethernet architectures, along with InfiniBand deployments for tightly coupled training environments.
-
Optical transceivers, co-packaged optics research, photonic switching, and expanded fiber density within and between data-center campuses.
-
AI-aware workload scheduling, distributed storage, data pipelines, checkpointing systems, and network telemetry.
-
Direct-to-chip liquid cooling, rear-door heat exchangers, chilled-water systems, and other thermal-management systems required by high-density AI racks.
-
New transmission lines, substations, transformers, gas generation, battery systems, and other power infrastructure needed to support multi-hundred-megawatt and gigawatt-scale campuses.
In effect, hyperscalers are building what are increasingly described as AI factories: integrated physical and digital production systems that convert electricity, capital equipment, data, and semiconductor capacity into trained models, inference tokens, and AI-enabled cloud services.
A Historically Large Capital Concentration:
AI investment is projected to reach 1.9% of U.S. GDP in 2026, according to Goldman Sachs estimates cited in the source material. The late-19th-century railroad boom was the last period in which a single new infrastructure category represented a larger share of the U.S. economy.
The comparison is useful, but incomplete. Railroads connected physical markets over decades. The AI build-out is being deployed on a far more compressed timetable and is dependent on global supply chains for leading-edge accelerators, high-bandwidth memory, advanced substrates, optical components, power equipment, and data-center construction capacity.
This creates a reinforcing investment loop:
-
Foundation-model developers require more compute to train larger or more capable models.
-
Cloud providers build additional accelerator capacity to support training and inference demand.
-
Semiconductor vendors, memory suppliers, networking companies, optical-component manufacturers, and power-equipment suppliers expand production.
-
Data-center developers secure land, power contracts, grid interconnections, fiber routes, water or cooling capacity, and financing.
-
Enterprises adopt AI services, increasing inference demand and reinforcing hyperscaler investment.
The strategic question is whether revenue from AI applications, enterprise subscriptions, API usage, advertising optimization, software agents, automation, and industry-specific deployments will scale fast enough to justify the capital intensity of the underlying infrastructure.
Financial and Infrastructure Risks:
The scale of investment introduces material financial-system risk. A growing portion of AI-related infrastructure is being financed through debt, including special-purpose entities and off-balance-sheet structures that may have limited public disclosure. These structures can allow technology companies and infrastructure developers to finance data-center construction, equipment purchases, and long-term capacity commitments without placing all obligations directly on corporate balance sheets.
That can be economically rational when capacity utilization is high and long-term AI demand is durable. However, it also creates exposure if expected AI revenues, cloud bookings, or accelerator utilization fail to materialize.
The central risk is not merely that an individual model underperforms. It is that a synchronized reduction in AI capital expenditure could affect multiple interconnected sectors at once:
-
Data-center developers and construction firms.
-
Semiconductor, memory, storage, and server suppliers.
-
Optical networking and switching vendors.
-
Utilities, independent power producers, and grid-equipment manufacturers.
-
Banks, private-credit funds, infrastructure lenders, and equipment-finance providers.
-
Commercial real-estate markets in data-center-heavy regions.
A sudden pause in hyperscaler spending would therefore have broader consequences than a typical technology downcycle. It could reduce orders across a deeply interdependent industrial supply chain while exposing leveraged infrastructure vehicles to weaker cash flows.
IT Product Inflation, Power, and Network Capacity:
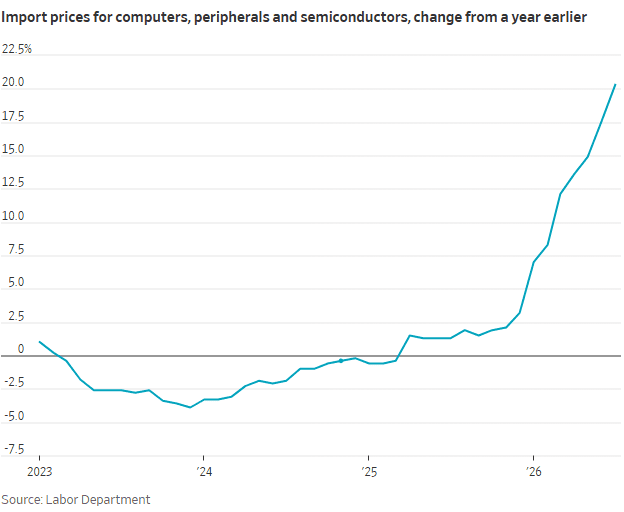
The AI build-out is also creating supply-side pressure in strategic technology markets. Demand for data-center equipment—especially memory, advanced semiconductors, servers, optics, and power-delivery equipment—has tightened supply and raised costs. The source material notes that prices paid by importers for computers, peripherals, and semiconductors were 20% higher in August than a year earlier.
That inflation can propagate beyond the data center. Higher component prices can increase the cost of consumer electronics, including smartphones, PCs, gaming systems, and storage products. Enterprises may also face higher prices for servers, networking equipment, cloud services, and AI-enabled software.
Power is an equally important constraint. AI data centers concentrate demand geographically, often creating large and relatively inflexible new loads on regional grids. A single large campus may require hundreds of megawatts, while the next generation of AI campuses could require gigawatt-scale capacity. This is driving demand for new generation, transmission capacity, substations, transformers, energy storage, and grid-management technologies.
The result is a collision between digital infrastructure planning and energy-system planning. Data-center capacity is no longer determined primarily by real estate, fiber connectivity, or server availability. In many markets, the gating factor is now the ability to obtain firm power, complete interconnection studies, procure transformers and switchgear, and finance new grid infrastructure.
Conclusions:
For IEEE Techblog readers, the central issue is not whether AI demand is real. It is whether the industry can build an economically sustainable, energy-efficient, resilient, and interoperable infrastructure stack at the required scale.
That challenge spans multiple engineering domains:
-
Semiconductor architecture, packaging, memory bandwidth, and energy efficiency.
-
Data-center electrical design, cooling, rack density, and operational resiliency.
-
High-performance networking, congestion control, optical interconnects, and distributed-system design.
-
AI software optimization, including model efficiency, quantization, sparsity, scheduling, and inference optimization.
-
Grid integration, power electronics, demand response, and energy-aware workload placement.
-
Security, supply-chain assurance, and operational management across increasingly autonomous infrastructure.
The AI boom may indeed become the defining infrastructure investment cycle of this era. Its long-term success, however, will depend less on headline capital-expenditure totals than on whether the industry can translate massive spending on accelerators and data centers into durable productivity gains, commercially viable AI services, and infrastructure that does not impose unsustainable costs on power systems, supply chains, consumers, or the financial sector.
………………………………………………………………………………………………………………………………………………
References:
Dell’Oro: Data Center capex grew 92% in 2Q-2026 (caveats galore)
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Bain: AI to greatly increase network operator expenses; network re-engineering needed!
Introduction by Bain:
“Over the next three to five years, the operating cost structure used by telecom operators is likely to undergo one of the most significant shifts in decades. As AI agents become embedded across customer care, network operations, software engineering, and enterprise functions, tokens will account for a growing share of operating expenditures.”
Key Points:
- Unless telcos proactively manage their costs, scaling up AI will simply add expenses to an already-heavy legacy base.
- An agentic operating model is emerging: a 70-to-30 ratio of legacy to AI costs, with AI automating or augmenting work across processes.
- Cost traps lurk: cheaper AI models, bigger bills; bolting AI onto legacy processes; and demos mistaken for transformation.
- Telco leaders can take five key actions today to avoid the traps.
Executive Summary:
Telecom operators are extending AI agents across network operations as they pursue higher levels of autonomy, but the shift could introduce a significant new operating-cost burden unless legacy processes, tooling and organizational structures are retired alongside the automation, according to Bain & Company.
Bain’s warning comes as operators accelerate plans for autonomous networks. TM Forum reported in June that 81% of 80 surveyed operators are targeting Level 4 autonomous networks or higher by 2030, and 20% expect to reach that threshold by 2027.
Under TM Forum’s Autonomous Networks framework, Level 4 moves beyond rule-based or preconfigured automation toward closed-loop, intent-driven decision-making within defined network domains. Current Level 4 work includes deployment of closed-loop operations in production networks, agent-based operating architectures, and metrics intended to quantify the operational and business value of autonomous-network use cases.
-
- Lagging Returns: According to Bain’s Automation and AI Pathfinder Survey, nearly 40% of companies saw AI cost savings land below 10%.
- Growing Budgets: Despite missing initial savings targets, 90% of these companies are still increasing their AI budgets.
- Autonomous Agents: Only 7% of companies currently run fully autonomous AI agents in production. Data access remains the top barrier to progress.
- AI Summaries: Bain’s research on Zero-Click Search shows that 80% of consumers rely on AI-written results for at least 40% of their searches.
- Fewer Clicks: About 60% of searches now end without the user clicking through to another website. This shift reduces organic web traffic by 15% to 25%.
Bain estimates that AI agents and associated token consumption could represent 20% to 30% of a telecom operator’s operating-cost base within the next three to five years, leaving conventional operating costs at 70% to 80%.
As AI spending rises, telcos risk increasing total costs without generating proportional gains in productivity or growth.
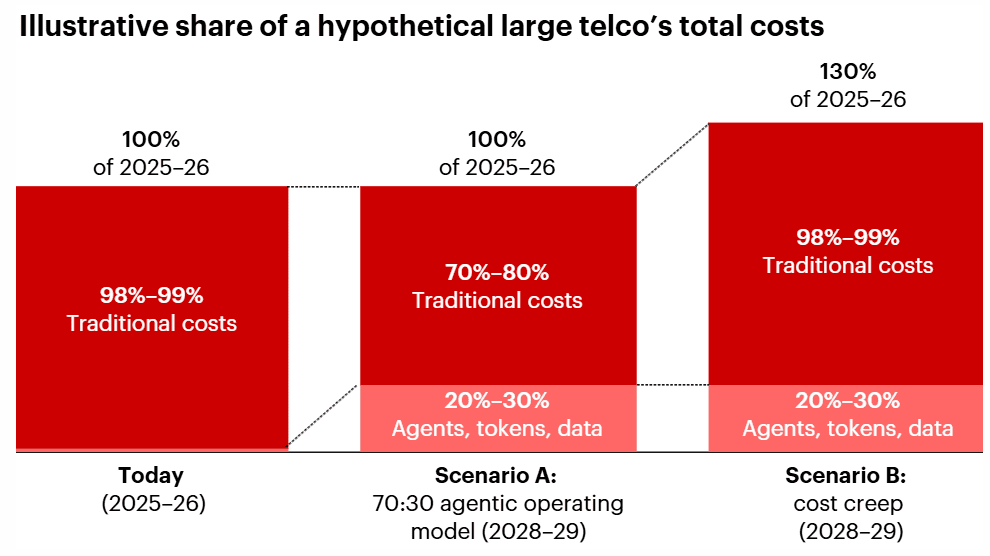
Notes: Illustration doesn’t incorporate absolute value changes; traditional costs are fully loaded, including costs from traditional software-as-a-service and cloud infrastructure, agency/outsourcing, depreciation, and more. Source: Bain estimates
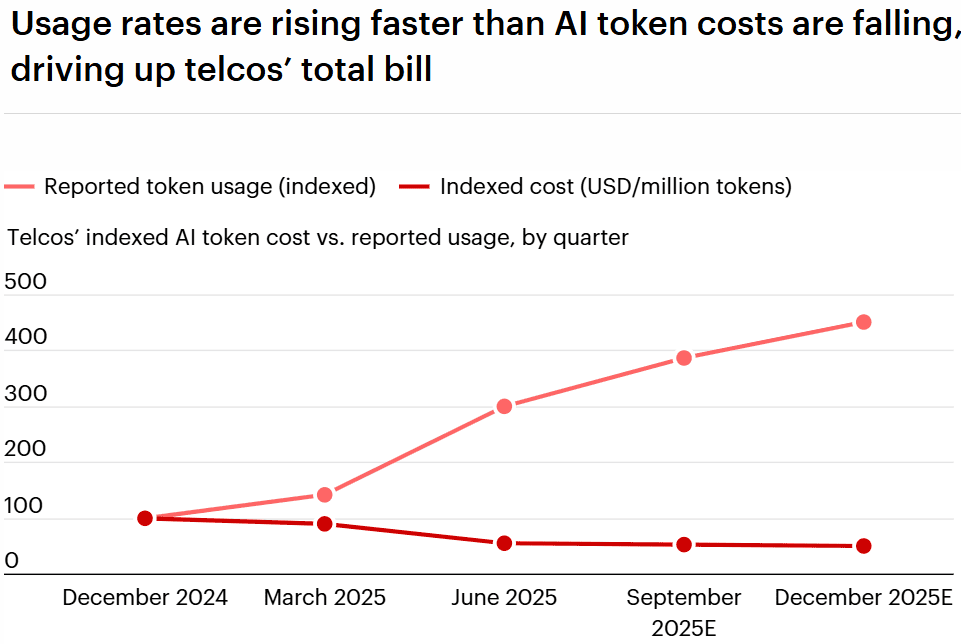
Sources: Wells Fargo (October 2025); Barclays (November 2025); company websites; news and industry reports; Bain analysis.
…………………………………………………………………………………………………………………………………………………………………………………..
However, cost is not the main issue. The principal risk is that network operators can create a parallel operating model when they layer agentic AI onto established network-operations processes without eliminating the people, software, outsourced functions and infrastructure those processes were designed to support.
In that scenario, AI compute, model inference and agent orchestration become incremental expenses, while legacy network operations centers, monitoring platforms, user-facing software licenses, managed-service arrangements and manual operational handoffs remain largely intact.
Network Re-engineering Required:
Avoiding this outcome requires process re-engineering rather than task-level automation. Bain recommends that operators redesign end-to-end workflows around the work agents assume, including:
-
Reducing manual monitoring, ticket triage and operational handoffs.
-
Reassessing workforce requirements as agents absorb repeatable diagnostic and remediation tasks.
-
Reviewing software, tooling and managed-service contracts when agents begin performing functions previously executed through conventional applications or outsourced processes.
-
Removing redundant operational steps rather than simply automating them.
-
Measuring the cost of an operational outcome, rather than the unit cost of model inference or token consumption.
This distinction is especially important in network operations, where an agent may continuously ingest alarms, correlate events, retrieve telemetry, diagnose faults, select a remediation action, trigger network tools, validate results and escalate exceptions to human operators. Each stage can add cost.
Inference is therefore only one component of the AI operating model. A production-grade agentic workflow may also require orchestration, tool and API calls, runtime evaluation, observability, data storage, policy enforcement, security controls, human-in-the-loop escalation and supporting compute infrastructure.
Bain argues that operators should evaluate the complete cost of the resolved operational event. For a service-affecting incident, that includes the total cost of detection, triage, diagnosis, remediation, validation and any remaining human intervention—not simply the marginal cost of the model invocation.
Closed-Loop Operations and Opex Reduction:
Bain cited Vivo in Brazil as an example of an operator redesigning a complete network workflow around AI-enabled automation rather than applying automation to discrete tasks. As part of Telefónica’s Autonomous Network Journey program, Vivo implemented a self-healing mechanism for its virtualized standalone 5G core.
The implementation monitors network-function performance, detects anomalies, identifies root causes and applies corrective actions automatically. It then validates whether the action restored normal operation and can progress to an additional remediation level when required.
Telefónica said the system correlates events across logical and physical infrastructure and completes the detect-to-resolve sequence without human intervention. For the targeted incidents, the company reported a 30-minute reduction in mean time to resolution.
The deployment also reduces repetitive work and manual intervention, while improving the use of computational resources. Telefónica has not disclosed a monetary estimate of the operating-cost savings associated with the implementation, however.
The significance of the Vivo deployment is architectural as much as operational. It integrates detection, correlation, diagnosis, remediation and verification into a closed-loop workflow. That is materially different from deploying an AI assistant within an otherwise unchanged operating model.
Other operator deployments illustrate the potential conventional opex benefits associated with higher autonomy. In a TM Forum case study, China Mobile reported that intelligent agents helped its network operations center achieve Level 4 autonomy under its self-assessment using TM Forum’s Autonomous Networks Levels framework.
China Mobile reported:
-
More than 30% reduction in backend operations-and-maintenance manpower.
-
More than 5% savings in frontline installation-and-maintenance manpower.
-
An average 30% reduction in mean time to repair for network faults and customer complaints.
An earlier TM Forum autonomous-network case study involving China Mobile reported O&M efficiency improvements of 10% to 20%, service-provisioning time reductions of 30% to 50%, and energy-consumption reductions of 3% to 5% across participating internet data centers and base stations.
The reported figures are operator-reported results published through TM Forum case studies. They demonstrate the possible efficiency gains from closed-loop automation, but they do not eliminate the need to account for AI-specific costs such as inference, orchestration, tool execution, supporting infrastructure and operational governance.
Measure Autonomous Networks by Outcomes:
TM Forum is also developing mechanisms to measure the value generated by autonomous-network deployments. In July, it approved version 2.0 of its Autonomous Networks High-Value Scenarios Effectiveness Indicators guide, intended to help operators quantify the impact of Level 4 autonomous-network scenarios.
This outcome-based approach aligns with Bain’s recommendation. For network operations, operators should move beyond narrow AI measures such as token counts, model cost per query or inference latency. Those measures remain operationally useful, but they do not establish whether an AI deployment improves the economics of network operation.
The most relevant measures include:
An operator may accept higher AI spending per workflow if it meaningfully reduces outage duration, truck rolls, customer-impacting incidents, workforce requirements or service-activation delays. Conversely, a deployment that lowers model-inference costs but leaves manual handoffs, duplicate monitoring tools and legacy support structures unchanged may offer limited net operating benefit.
AI Consumption at Telecom Scale:
AT&T has illustrated the potential scale of enterprise AI consumption, although its reported figures span AI workloads across the business and are not limited to autonomous network operations. The operator said in July that it processes an average of 45 billion tokens per day.
AT&T uses an AI gateway to route tasks among models based on cost, latency and expected output quality. The company said the platform can switch models during multi-turn interactions and has reduced costs for certain AI workloads by as much as 90%, producing multimillion-dollar savings.
The operating principle is relevant to telecom network automation: only a minority of tasks require the most capable—and most expensive—models. Routine classification, alarm enrichment, knowledge retrieval, configuration validation and other bounded operational tasks may be suitable for smaller models, purpose-built models or conventional deterministic automation. More capable reasoning models can be reserved for ambiguous, multi-domain or exception-heavy cases.
Bain similarly recommends matching model capability to task complexity rather than applying a single model class across every AI workload. Operators should establish dedicated compute budgets, instrument workflow-level economics and treat inference capacity as an operational resource that requires active governance.
Governing Agentic Network Operations:
Agent behavior itself can become a material source of cost and operational risk. Poorly designed agents may repeatedly transmit large context windows, loop without completing a task, invoke overlapping diagnostic tools or conduct duplicative checks that add token and infrastructure consumption without improving the result.
Bain recommends guardrails that limit both expenditure and runtime. In a telecom network-operations environment, those controls could include:
-
Maximum token, compute and tool-call budgets per incident or workflow.
-
Time limits before an agent must escalate an unresolved task to a human operator.
-
Context-management rules that prevent unnecessary repetition of telemetry, alarms and historical ticket data.
-
Controls to consolidate overlapping diagnostic checks and duplicate agent activity.
-
Policy constraints governing which network changes an agent may propose, execute or validate autonomously.
-
Continuous monitoring for model drift, abnormal agent behavior, spending anomalies and degraded operational outcomes.
-
Explicit business and financial ownership for each production agent and workflow.
The central issue is that autonomous networks will not necessarily lower opex simply because they reduce manual work. Operators must also remove the legacy cost structures that agentic systems replace. Otherwise, AI agents risk becoming an additional layer of expense on top of existing network operations rather than the foundation for a more efficient operating model.
……………………………………………………………………………………………………………………………………….
References:
Bain & Co, McKinsey & Co, AWS suggest how telcos can use and adapt Generative AI
McKinsey: AI infrastructure opportunity for telcos? AI developments in the telecom sector
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
5G infrastructure moves from coverage and speeds to cloud-native, orchestration, automation and AI-assisted networks
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
Executive Summary:
Google parent Alphabet’s emerging business of selling artificial intelligence (AI) accelerator chips is twice as large as a cloud computing rival, Google executive Thomas Kurian claimed Tuesday at a Goldman Sachs investors conference.
On July 22, Google reported second-quarter cloud-computing revenue of $24.77 billion, up 82% year over year, driven by artificial intelligence workloads, handily beating estimates of $22.46 billion. For the first time, Google included third-party sales of AI accelerator chips, called tensor-processing units, in cloud revenue.
Kurian, head of Google’s cloud business, made these remarks at Goldman Sachs’ Communacopia conference:
“We offer the best computational infrastructure for AI, and we offer 3 types of silicon. NVIDIA GPUs, our own Tensor Processing Units (TPUs), custom ARM silicon. [As AI models generate code awe also offer our own Arm processors to run that code.] We offer 2.7x better price performance for training, 80% better price performance for inference, 30% better price performance for CPUs. All of that allows us to differentiate our portfolio from other providers. It allows us to offer solutions to financial markets and capital markets.”
“The size of our accelerator business, our TPU business, is more than twice that of the next-largest hyperscaler.”
“Our platform is called Gemini Enterprise. It is used by over 90% of the Fortune 100 and thousands of small businesses. It’s used in a very specific way. People want to use it as a reasoning agent. So break the plan, understand the steps that are needed, reason on it and execute the steps. So it uses a reasoning agent to understand all the information in the company to then automate that workflow process. And when it does it, you want strong controls. What kinds of controls? Companies are worried about security. They’re worried about auditing, what these agents are doing. They want to manage costs and set budget caps. We have all those controls. And we allow people to use the right model for the right task. So you don’t have to always use the most expensive model, saving people a lot of money in doing so. We have a range of companies from insurance.”
–>You can read the entire transcript here. For more on Google’s TPUs please see:
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Google’s TPU photo
……………………………………………………………………………………………………………………………………………………
Kurian added that Google monetizes TPU systems through three business models. One is letting companies rent TPU processing at its own cloud business. Also, Google sells TPU systems directly for deployment in customers’ data centers. One such customer is Anthropic. Third, Google also sells TPUs through a Blackstone cloud computing joint venture.
Google’s AI Chip Business:
In May, Google introduced Ironwood, its eighth-generation of TPUs. The Ironwood TPUs target both training of AI models and “inferencing” — processing AI workloads.
In a report published Aug. 24, Morgan Stanley analyst Brian Nowak estimated that Google cloud could garner $84 billion in “first party” — meaning non-cloud rental — TPU sales in 2027.
“We are raising our TPU sale estimates to $27 billion selling at a 30% gross margin,” Nowak said. “In all, we now expect Google to sell 0.3 gigawatts of TPU systems in the second half of 2026, 3.2 gigawatts in 2027 and 4.2 gigawatts in 2028. This translates into $84 billion/$108 billion of TPU-related Google cloud revenue in 2027 and 2028.”
In Q2-2026, Google said its cloud computing order backlog jumped to $514 billion, up from $460 billion in Q1. The backlog is converted into realized revenue as new data centers come online and crunch artificial intelligence-related workloads — training AI models and processing AI apps.
Google has increased its 2026 capital spending guidance to a range of $195 billion to $205 billion. Most of the spendings is going toward AI data centers and AI model development. In Q2, capital spending jumped 100% from a year earlier to $44.9 billion.
Kurian, a former top executive at Oracle, took over as the cloud-computing unit’s CEO in November 2018. When Kurian arrived, Google’s cloud customers were mostly other tech companies. Under Kurian, Google has targeted enterprise customers with cloud-based data-analytics and artificial intelligence tools.
Hyperscaler Custom Silicon: Meta, Microsoft, Oracle, and the Shift to In-House AI Accelerators:
While Google’s TPU business has reached a scale that Kurian says is more than twice that of the next-largest hyperscaler, other cloud and platform operators are rapidly expanding their own custom AI silicon programs to reduce dependence on Nvidia GPUs and optimize cost, power, and workload-specific performance.
Amazon.com has developed in-house Trainium AI accelerators while Microsoft has developed Maia AI chips. Amazon is further ahead than Microsoft in selling AI chips to outside customers, analysts say.
Meta – MTIA Family Targets Inference at Scale:
Meta has moved aggressively into custom silicon with its Meta Training and Inference Accelerator (MTIA) family, announcing four new chips — MTIA 300, 400, 450, and 500 — in March 2026 as part of a strategy to diversify hardware sources and lower AI infrastructure costs. The MTIA 300 entered production in mid-2026, with subsequent generations rolling out on an approximately six-month cadence through 2027.
Meta’s MTIA chips are manufactured by TSMC and co-developed with Broadcom under a multi-year partnership extending through 2029. The roadmap spans ranking and recommendation training (MTIA 300), combined generative AI and ranking workloads (MTIA 400), and decode-optimized generative AI inference (MTIA 450 and 500), with mass deployment of the flagship MTIA 500 planned for late 2027. Meta plans to put its own AI chip into production in September and is aiming to roughly double the computing capacity across its data centres.
By mid-2026, Meta, Amazon, Microsoft, and OpenAI have each closed the gap on the three key AI inputs — custom chips, power, and models — that only Google held in 2021.
Microsoft: Maia 200 and the Push to External Customers:
Microsoft unveiled its first custom AI accelerator, Maia 100, at Hot Chips 2024, followed by the inference-optimized Maia 200 in January 2026. Maia 200, built on TSMC’s 3 nm process with more than 140 billion transistors, 216 GB of HBM3e, and over 10 PFLOPS of FP4 compute within a 750 W SoC TDP, is designed to deliver 30% better performance per dollar for AI token generation.blogs.
Maia 200 will serve multiple models, including OpenAI’s GPT-5.2, and support Microsoft Foundry, Microsoft 365 Copilot, and reinforcement learning workflows. Microsoft plans to unveil next-gen Maia 300 AI chip in September, aiming to lower costs for in-house and OpenAI models while actively courting major enterprise customers. Anthropic is reportedly in talks with Microsoft to rent the company’s custom AI server chips as it looks to expand computing capacity.blogs.
Oracle: Partner-Led AI Clusters Rather Than Custom Silicon:
Oracle has taken a different path, opting not to develop its own AI accelerator but instead building large-scale AI clusters using third-party chips from Nvidia and AMD. Oracle plans to install the first MI450-equipped Helios racks in its OCI data centers during the third quarter of 2026, with an initial deployment targeting 50,000 MI450 processors.
Oracle’s AI strategy emphasizes rapid deployment of massive GPU-based clusters to serve anchor tenants like OpenAI under a reported $300 billion, five-year cloud computing contract beginning in 2027. In parallel, OpenAI is diversifying its supply of compute by designing its own chips with partners like Broadcom, with the first custom AI inference chips expected to deploy in the second half of 2026.
Market Implications:
By 2026, five of six major AI players — Google, Meta, Amazon, Microsoft, and OpenAI — now control at least two of the three critical AI inputs (chips, power, models), down from only Google in 2021. This vertical integration trend is reshaping the AI infrastructure market, with hyperscalers increasingly using custom silicon to optimize cost and performance for specific workloads while maintaining strategic flexibility through multi-vendor GPU procurement.
Google’s TPU v7, Amazon’s Trainium 3, Microsoft’s Maia 2, and Meta’s MTIA 2 all ramped into volume production in 2025–2026, signaling a maturation of the hyperscaler custom silicon ecosystem. Meta is also the first commercial gigawatt AMD MI450 deployment in H2 2026, illustrating a hybrid approach that combines in-house accelerators with third-party GPUs.
…………………………………………………………………………………………………………………………………………………..
References:
https://www.investors.com/news/technology/google-stock-cloud-kurian-ai-chip-business/
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Google announces Gemini: it’s most powerful AI model, powered by TPU chips
Google Cloud and Verizon Expand Strategic Partnership to Scale Enterprise AI and Autonomous Network Operations
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
Meta’s “Iris” AI Chip for MTIA: Implications for Telecom-Grade Optical Networking, DCI and High Capacity Ethernet Fabrics
Custom AI Chips: Powering the next wave of Intelligent Computing
AI Compute Has a Switchboard Problem: Orchestration & Data Center Fabric Explained
South Korean startup Rebellions to use open source software for carriers to quickly build AI stacks with its AI inferencing chips
Autonomous customer experience required for AI-Native 6G and distributed intelligence at the network edge
Executive Sumary:
Communications service providers (CSPs) have historically competed on network-centric KPIs—coverage, capacity, reliability, and price—anchored in 3GPP performance and management frameworks (e.g., TS 28-series, TS 23.501 QoS models). However, these metrics alone are no longer sufficient to sustain differentiation in increasingly saturated and capital-intensive markets, according to Chantel Cary, Product Marketing Senior Manager at Oracle Communications [1],
“The battleground has shifted,” Cary told Capacity Global. “Today, customer experience is becoming the clearest point of differentiation, and in many cases, the most important driver of growth.”
This shift is unfolding alongside structural constraints: flat ARPU, rising capex associated with 5G standalone, fiber access (FTTx), and edge cloud expansion, and increasing customer acquisition and retention costs. At the same time, customer expectations—benchmarked against hyperscaler-grade digital platforms—are becoming uniformly high across mobile and fixed broadband services.
“They do not compare a telecom provider only to other providers,” she said. “They compare every experience to the best experience they have anywhere.”
…………………………………………………………………………………………………………………………………………………………………………………………………………………..
Note 1. Oracle Communications is a dedicated global business unit and product portfolio fully owned and operated by Oracle. It provides enterprise software and infrastructure designed specifically for telecommunications service providers (like AT&T or Verizon) and large enterprises. Their solutions manage everything from network routing, security, and signaling (including 5G) to back-office billing, revenue management, and customer experience operations,
…………………………………………………………………………………………………………………………………………………………………………………………………………………..
Analysys Mason reports that 97% of operators view AI-powered automation as essential for survival and growth, reinforcing alignment with TM Forum’s Autonomous Networks framework and the broader industry transition toward AI-native system design.
AI-Native Customer Experience Architecture:
Cary’s concept of “autonomous customer experience” maps directly to the emerging paradigm of AI-native networks, where intelligence is embedded across both network and service layers rather than applied as an overlay. “It is not about removing the human element from engagement,” she explained. “It is about using AI to continuously orchestrate the customer lifecycle in ways that humans alone cannot manage at scale.”
In wireless networks, this evolution is reflected in 3GPP-defined enablers such as the Network Data Analytics Function (NWDAF, TS 23.288), which provides real-time analytics to optimize policy control, mobility, and QoS. In parallel, O-RAN Alliance architectures introduce the near-real-time and non-real-time RAN Intelligent Controllers (near-RT RIC, non-RT RIC), enabling AI-driven control loops for radio resource management and service optimization.
Image Credit: Aisera
In wireline and converged networks, similar principles are emerging through SDN-based control planes, broadband network gateways (BNG) with telemetry streaming, and ITU-T frameworks (e.g., Y.3172 for machine learning in future networks), enabling closed-loop optimization across access, aggregation, and core domains.
However, Cary notes that most OSS/BSS environments remain fragmented, limiting the ability to operationalize these capabilities at the customer experience layer. Data silos, batch-oriented processing, and loosely coupled workflows constrain real-time, cross-domain orchestration.
AI Across Commercial and Network Domains:
Cary identifies three primary domains of impact, increasingly converging with network intelligence:
-
Marketing: AI-driven personalization is evolving toward real-time, context-aware engagement informed by both customer behavior and network conditions (e.g., location, QoS state, congestion). This aligns with event-driven architectures and customer data platforms integrated with network analytics (e.g., NWDAF exposure via APIs). “Personalisation shifts from broad audiences to the individual,” she said, adding that relevance is now “a prerequisite for attention.”
-
Sales: AI enables next-best-action and dynamic offer generation, incorporating network-aware insights such as service availability, slice characteristics (in 5G SA), and fiber capacity constraints. Integration with policy control (3GPP TS 23.203) and service orchestration frameworks supports closed-loop order capture and fulfillment. “That combination of higher conversion and lower friction is valuable,” she said.
-
Service: AI-driven assurance is transitioning from reactive fault management to predictive and intent-based service assurance across both wireless and wireline domains. Telemetry from RAN, transport, and fixed access networks feeds AI models that anticipate degradation and trigger remediation before customer impact. “Human agents still play a central role,” Cary said, “but they can be augmented with real-time recommendations, contextual history and autonomous processes that improve both speed and consistency.”
Scaling Challenges in AI-Native Transformation:
Despite progress in AI models and domain-specific analytics, Cary highlights a systemic gap in operationalization.
“What it lacks, in many cases, is the ability to turn fragmented customer data into real-time decisions that can actually be executed across marketing, sales and service,” she said.
Analysys Mason data indicates that only 6% of operators achieve ROI above 25% from AI initiatives, while 60% advance just 20% of proofs of concept into production. This reflects challenges in integrating heterogeneous data sources across OSS, BSS, and network domains, as well as limitations in MLOps and real-time orchestration frameworks.
Fragmentation is compounded in converged networks, where wireless (3GPP-based) and wireline (e.g., Broadband Forum TR-369/USP, TR-383 for disaggregated BNG) ecosystems often evolve independently. Additionally, 93% of operators cite multi-vendor complexity as increasing total cost of ownership, underscoring the need for interoperable, standards-based integration across AI, network, and IT domains.
“That creates an unfortunate pattern across the industry,” she said, “promising AI initiatives that demonstrate value in isolation but fail to scale because they are not connected to the data, systems and processes where real work happens.”
Toward Fully AI-Native Operations:
Cary emphasizes that the target state is not incremental automation but fully AI-native operations, where intelligence is embedded into both network control loops and customer engagement workflows.
“This is why the future of customer experience in communications is not about layering AI onto the edge of the enterprise,” Cary said. “It is about making AI operational at the core of engagement.”
This vision aligns with emerging 6G research directions, where AI is treated as a native design primitive across RAN, core, and service layers, as well as with TM Forum’s Open Digital Architecture (ODA), which promotes composable, API-driven integration between OSS, BSS, and AI components.
Oracle’s approach reflects this convergence by unifying customer data, embedding AI into engagement and orchestration layers, and integrating these capabilities with telecom operational systems across both wireless and wireline domains.
Implementation Suggestions:
Cary said that network providers do not need to transform everything at once. She recommends starting by unifying customer data across touchpoints to establish a trusted, real-time view, before activating high-value AI use cases across marketing, sales and service. From there, providers can embed AI into workflows so insight translates into action rather than sitting in dashboards, eventually connecting those capabilities into end-to-end orchestration.
Indeed, Cary advocates a phased approach consistent with AI-native transformation:
-
Establish a unified, real-time data fabric spanning customer, service, and network domains.
-
Deploy high-value AI use cases (e.g., next-best-action, churn prediction, predictive assurance) leveraging both IT and network telemetry.
-
Embed AI into execution workflows to enable closed-loop, intent-driven orchestration across the customer lifecycle.
This progression reflects the broader industry trajectory toward converged, AI-native networks, where customer experience is no longer an overlay on connectivity, but a direct outcome of tightly coupled intelligence across wireless and wireline infrastructures.
“The communications providers that lead in the years ahead will not be the ones that simply adopt more AI tools. They will be the ones that use AI to rethink how customer engagement works across the enterprise. AI is not just enhancing customer experience,” she added. “It is redefining how customer experience is delivered, and in communications, that shift is likely to separate the providers that keep pace from the ones that set the pace.”
………………………………………………………………………………………………………………………………
Editorial Analysis:
Cary’s vision aligns with IMT 2030/6G’s shift from AI as an overlay to AI as an architectural primitive, spanning the air interface, semantic service handling, and distributed edge intelligence across wireless and wireline domains. The cleanest way to map her suggestions into 6G is to treat “autonomous customer experience” as the service-layer expression of an AI-native network stack: AI decisions would no longer sit only in OSS/BSS, but would be distributed across RAN, transport, core, and edge applications, with closed-loop control spanning wireless and wireline domains. That maps well to current AI-native 6G proposals that emphasize model interdependencies, distributed intelligence, and AI embedded directly in the architecture rather than layered on top.
For the AI native air interface, the link is to AI-assisted radio control, where the network uses learned models to optimize scheduling, mobility, beam management, and QoS-aware policy decisions in real time. In a 6G framing, that extends beyond today’s AI for RAN optimization and toward an AI-native air interface in which the radio stack itself is designed for machine-driven adaptation, including distributed control loops between UE, RAN, and core. For your article, this supports language that customer experience is increasingly shaped by network intelligence at the point of access, not just by back-office engagement systems.ieeexplore.ieee+2
Semantic communications maps to the idea that the network should optimize for meaning or task relevance, not simply bit delivery. In practice, that means a 6G service layer could prioritize the semantic value of an interaction—such as whether a customer is trying to resolve an outage, confirm a move order, or change a plan—and allocate resources accordingly across wireless and wireline paths. The relevance to Cary’s argument is that customer experience becomes more contextual and intent-aware when the network itself can distinguish between low-value traffic and high-importance service interactions.
Distributed intelligence at the network edge is the most direct bridge between CSP operations and 6G design. In a converged wireless-wireline environment, edge AI can fuse RAN telemetry, fixed access metrics, subscriber context, and service history to trigger local decisions such as proactive care, dynamic QoS adjustment, or preemptive fault mitigation. That makes the experience layer more autonomous because the decision point moves closer to where the event occurs, reducing dependence on centralized, slower, batch-oriented processing.
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.nokia.com/6g/unlocking-the-full-potential-of-ai-native-6g-through-standards/
Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020)
SHIELD-6G with AI-native cyber threat intelligence platform to enhance cybersecurity for Europe’s future 6G networks
AT&T and Ericsson boost Cloud RAN performance with AI-native software running on Intel Xeon 6 SoC
Ericsson and Intel collaborate to accelerate AI-Native 6G; other AI-Native 6G advancements at MWC 2026
NVIDIA and global telecom leaders to build 6G on open and secure AI-native platforms + Linux Foundation launches OCUDU
AT&T and Ericsson boost Cloud RAN performance with AI-native software running on Intel Xeon 6 SoC
Huawei’s AI-Centric Network Vision: Six Imperatives for the Next Decade; Critical Questions for IEEE Techblog Community
The Case for AI-Native Networks:
At MWC Shanghai 2026 [1.], David Wang, Deputy Chairman of the Board and Rotating Chairman of Huawei, outlined a strategic roadmap for AI-native mobile networks, positioning artificial intelligence as the cornerstone of industry growth over the next decade.
Note 1. MWC Shanghai 2026 was held June 24–26, 2026 at the Shanghai New International Expo Center (SNIEC), with Huawei showcasing products and solutions in Hall N1.
Over the past 40 years, innovation in mobile technology from each generation to the next has been key to the industry’s success. “With each generation, we have pushed the limits of spectral efficiency and performance,” said Wang. “Network architecture has gradually flattened, with new application scenarios and services emerging left and right. This has consistently expanded the boundaries of communications, helping carriers translate network capabilities into commercial value,” he added.
Huawei argues that traditional telecom infrastructure built around data traffic is no longer sufficient. As the global digital ecosystem transitions toward real-time interactions with AI applications and intelligent agents, mobile and transport networks must be completely redesigned to support both communication and computing. According to Huawei, an AI-native architecture transforms networks from simple communication utilities into revenue-generating engines while helping operators transition to Level-4 and Level-5 network autonomy
Huawei’s Six Strategic Imperatives:
Wang identified six imperatives to guide the industry through the age of intelligence:
-
Developing new services and capabilities for future mobile communications systems
-
Integrating AI with mobile communications to build three distinct layers of intelligence
-
Building network architecture for integrated satellite-ground communications
-
Advocating for sustainable and future-oriented spectrum planning and allocation
-
Clearly defining the specifications of AI-native core networks
-
Exploring new business models and application scenarios for mobile services

Photo Credit: Huawei
Innovations Unveiled: Byte and Token Monetization:
Huawei released a portfolio of innovations targeting both services and infrastructure. On the services side, in collaboration with China’s three major carriers, the company announced advances in 5G-Advanced (5G-A) high-uplink and experience monetization, AI-powered business upgrades, and token monetization.
For infrastructure, Huawei launched the AI-centric target network, designed to enhance carrier competitiveness in byte and token monetization. This architecture comprises three layers:
-
Basic Communications Network: A shift from traffic-centric to real-time interaction networking, offering guaranteed connectivity with high uplink and downlink capabilities alongside advanced QoS mechanisms.
-
Computing Network: A transition from traffic transport to network-wide compute scheduling and supply, where “connecting to the network is equivalent to accessing compute.”
-
AI Computing Infrastructure: High-performance, efficient compute with support for open-source and open ecosystems.
5G-Advanced: 100 Million Users and Beyond:
The global 5G-A (based on 3GPP Release 18) user base has surpassed 100 million. Huawei is now working with network operators worldwide to advance 5G-A experience monetization and integrate it into installed base operations, targeting mid-range and high-end user retention, ARPU growth, and sustainable revenue expansion.
High Uplink Speed: The New Frontier for AI Applications:
High uplink capacity is critical for token monetization. Emerging AI applications—such as multimodal AI glasses for real-time translation and augmented exhibitions—demand uplink speeds of 20 Mbps or higher. In 2026, leading carriers globally are piloting commercial high-uplink services with guaranteed peak speeds, latency, and universal uplink performance.
Upper-6 GHz: The Next Golden Band:
The proliferation of AI agents is expected to drive rapid growth in token services, requiring ultra-broadband networks with high uplink, high reliability, and low latency. Upper-6 GHz (U6 GHz) is positioned as the next-generation golden frequency band for this purpose.
-
More than 20 countries and regions have designated U6 GHz for IMT, covering nearly 80% of the global population.
-
2026 marks the commercial debut of U6 GHz, with the Middle East expected to deploy the world’s first commercial 5G-A network on U6 GHz.
-
Select carriers in Hong Kong and Macao will also initiate commercial U6 GHz deployment.
AI-Native B2C and B2B Services:
Huawei plans to collaborate with carriers in Guangdong, Shanghai, Hebei, and other regions in 2026 to reengineer B2C and B2H services with AI, targeting consumer applications such as smart home assistants, personal communication assistants, and integrated consumer-home services. In the B2B segment, the focus is on AI computing services centered on compute-network integration, unlocking new business growth avenues.
Path to Level-4 Autonomous Networks:
Huawei is advancing AI-native technologies toward Level-4 autonomous networks by developing domain-specific intelligence. In 2026, the company will work with carriers to deploy domain-specific intelligence across wireless and transmission network domains in key regions. This will enable cross-domain synergy in maintenance, optimization, energy efficiency, and user experience, enhancing network quality and enabling differentiated products for high-speed rail, event venues, and campuses.
Critical Questions:
Huawei’s AI-centric network vision positions AI not as an incremental improvement to mobile networks but as a foundational network architecture. That vision raises several critical questions for the IEEE community and IEEE Techblog readers:
-
Interoperability: How does Huawei’s AI-centric target network align—or conflict—with AI-RAN Alliance initiatives and O-RAN specifications?
-
Vendor Comparison: How does Huawei’s AI-centric target network compare with Ericsson’s cloud RAN strategy and Nokia’s Altiplano/Corteca agentic AI platforms in terms of technical architecture and commercial viability?
- Specifications and Standards: What role will 3GPP and ITU-R play in standardizing AI-native core network specifications, particularly for token monetization and compute-network integration?
- Autonomous Networks: How do Huawei’s domain-specific intelligence approaches compare with vendor-neutral SMO/rApp ecosystems, and what are the implications for multi-vendor interoperability?
-
Are carriers adequately prepared for the operational and cultural shifts required to transition from traffic monetization to token monetization?
-
How will U.S./European regulatory frameworks (e.g. spectrum policy, AI governance, data sovereignty) shape the deployment of AI-native networks compared to China’s more centralized approach?
- Spectrum Policy: With Upper 6 GHz emerging as a key enabler for AI-driven token services, what are the regulatory and coexistence challenges, particularly in regions yet to designate Upper 6 GHz for IMT 2030? What will WRC 2027 decide?
Conclusions:
Huawei’s roadmap underscores the ICT industry’s rapid shift towards AI token monetization, positioning 5G-Advanced high-uplink, AI-native networks, and Upper 6 GHz spectrum as the foundational pillars for the next decade of growth. The success of this vision depends not only on technological feasibility but also on standards alignment, regulatory support, and carrier willingness to reinvent business models—a complex challenge that warrants close scrutiny from the IEEE technical community.
……………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.huawei.com/en/news/2026/6/mwcs-ai-byte-token
https://carrier.huawei.com/minisite/mwcs2026/en/
https://www.huawei.com/en/news/2026/6/mwcs-gsma-asac-5g-advanced
Huawei unveils AI Centric Network roadmap, U6 GHz products, 5G Advanced strategy and SuperPoD cluster computing platforms
Huawei FY2025: 2.2% YoY revenue increase; strategic pivot to AI and intelligent automotive solutions
Huawei, Qualcomm, Samsung, and Ericsson Leading Patent Race in $15 Billion 5G Licensing Market
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
Huawei launches CloudMatrix 384 AI System to rival Nvidia’s most advanced AI system
U.S. export controls on Nvidia H20 AI chips enables Huawei’s 910C GPU to be favored by AI tech giants in China
Huawei Cloud Review and Global Sales Partner Policies for 2026
Huawei’s “FOUR NEW strategy” for carriers to be successful in AI era
Huawei to revolutionize network operations and maintenance
Huawei’s Electric Vehicle Charging Technology & Top 10 Charging Trends
Bloomberg: Meta to sell AI compute in a new cloud services offering
Disclaimer: Perplexity.ai was used for research resulting in this article.
Executive Summary:
According to Bloomberg, Meta Platforms is advancing plans to commercialize its internal AI infrastructure through a new cloud services offering, signaling a strategic expansion beyond its traditional hyperscale consumer platforms into the competitive AI infrastructure market. This initiative would position Meta alongside established cloud providers such as Amazon Web Services (AWS), Microsoft Azure, and Google Cloud, while also overlapping with emerging GPU-centric “neocloud” providers. Meta’s move represents a significant evolution in the AI infrastructure landscape, with potential ripple effects across data center architecture, optical transport networks, and the broader telecom ecosystem.
At the core of this strategy is the monetization of Meta’s rapidly expanding AI compute footprint. The company has aggressively invested in large-scale data center infrastructure—reportedly including multi-hundred-billion-dollar campus developments—to support training and inference for its proprietary large language models (LLMs) and recommendation systems. As these deployments scale, Meta appears to be seeking to externalize surplus capacity, transforming a cost center into a revenue-generating platform.
The proposed service portfolio is expected to span two primary layers. First, Meta may expose access to hosted AI models via APIs, analogous to AWS Bedrock or Azure AI Services, enabling enterprises to integrate generative AI and foundation model capabilities without managing underlying infrastructure. Second, Meta is exploring the provision of raw compute capacity—primarily GPU-accelerated workloads—mirroring the infrastructure-as-a-service (IaaS) model offered by neocloud providers such as CoreWeave. This dual-layer approach would allow Meta to compete both in higher-margin AI platform services and in lower-level compute provisioning.
Telecom & Networking Implications:
From a telecom and network infrastructure perspective, this development has several implications. Hyperscale AI workloads are increasingly bandwidth-intensive, requiring high-capacity, low-latency interconnects within and between data centers. Meta’s investments are therefore likely to drive demand for advanced optical networking technologies, including coherent pluggable optics (e.g., 400ZR/800ZR), data center interconnect (DCI) architectures, and AI-optimized fabric designs leveraging Ethernet-based scale-out topologies. In addition, the geographic placement of these data centers—often in power-abundant, rural locations—introduces new requirements for long-haul fiber connectivity and edge aggregation.
The initiative, internally referred to as “Meta Compute,” reflects a broader industry shift toward vertically integrated AI infrastructure stacks, where hyperscalers tightly couple compute, networking, and software frameworks. For telecom operators and infrastructure vendors, this trend underscores the growing convergence between cloud, AI, and network domains, particularly as AI-driven workloads begin to influence traffic patterns, peering strategies, and edge deployment models.
Strategically, Meta’s entry into the AI cloud market raises competitive pressure across multiple fronts. Unlike traditional cloud providers, Meta brings extensive experience in hyperscale distributed systems and open-source AI frameworks (e.g., PyTorch), but lacks a mature enterprise cloud ecosystem. Its success will likely depend on its ability to translate internal infrastructure efficiencies into externally consumable services, while addressing enterprise requirements for reliability, security, and service-level agreements.
Meta’s cloud push is best viewed as a network-and-infrastructure strategy as much as a software business, because monetizing AI capacity depends on how well it can expose compute, move data, and preserve performance at hyperscale. The telecom significance is that Meta is turning internal AI infrastructure into a market-facing platform, which increases the importance of optical transport, data-center interconnect, and low-latency backbone engineering.
From a telecom perspective, the key issue is not simply that Meta may sell AI models or GPU capacity; it is that the company is building a service layer on top of a very large, power- and bandwidth-intensive distributed system. Reuters reported that Meta is considering both hosted model access and raw compute sales, with the former resembling an AI platform service and the latter looking more like neocloud infrastructure.That means the network becomes part of Meta’s product offering. Large AI inference and training environments require high-bisection fabrics inside the data center, plus dense east-west traffic handling, which pushes demand for faster Ethernet switching, advanced optical modules, and carefully engineered rack-to-rack and site-to-site interconnects. Meta’s AI cloud ambitions reinforce a broader shift: hyperscalers are no longer treating networking as a background utility, but as a primary constraint on scale.
Network World’s coverage of Meta Compute notes that Meta has unified data center and network oversight and is planning multi-gigawatt AI buildouts, underscoring how tightly power, fiber, switching, and facility design are now linked.
For network operators and vendors, that translates into stronger demand for long-haul fiber, DCI platforms, low-latency transport, and high-radix switching. It also raises the strategic value of metro and regional interconnect corridors that can support AI clusters, especially when capacity must be spread across multiple sites for power, land, or resiliency reasons.
Meta’s potential move into raw compute sales is especially relevant to telecom because it resembles the economics of infrastructure-heavy cloud and colocation models. In practice, the service quality will depend on how efficiently Meta can provision GPU clusters, maintain deterministic performance, and avoid congestion across the transport layer connecting those clusters. That implies growing importance for:
-
Coherent optical transport and scalable DCI.
-
High-capacity Ethernet fabrics for AI clusters.
-
Open-rack and disaggregated infrastructure designs.
-
Network automation that can track workload placement and traffic hotspots.
These are not just cloud concerns; they are telecom-grade capacity-planning problems. As AI clusters become larger and more distributed, network planning starts to look more like core network engineering than conventional enterprise hosting.

Image Credits: Gabby Jones/Bloomberg / Getty Images
……………………………………………………………………………………………………………………………………………………………………..
Conclusions:
Meta’s entry would not only compete with AWS, Azure, and Google Cloud, but could also pressure specialized neocloud providers more directly. Reuters noted that Meta’s spare capacity could matter more to neo-cloud vendors than to the largest hyperscalers, because those providers rely on access to external GPU supply and managed infrastructure growth. For telecom analysts, that suggests the competitive battleground is shifting from “who has the best model” to “who can deliver the most resilient compute-network-power stack.” The winners will likely be those that can couple AI accelerators with fiber-rich sites, robust interconnect, and energy-secure data center footprints.
Meta’s move reflects the convergence of cloud, AI, and transport networks. The story is less about Meta becoming a generic cloud vendor and more about hyperscale AI infrastructure evolving into a new class of network-dependent utility. Indeed, Meta’s cloud initiative highlights a broader industry reality — in the AI era, compute is valuable, but connectivity, optical scale, and power-aware architecture increasingly determine whether compute can be monetized at all.
……………………………………………………………………………………………………………………………………….
References:
Meta, like SpaceX, looks to turn excess AI compute into cash
https://www.cnbc.com/2026/05/27/mark-zuckerberg-says-meta-starting-cloud-business-on-the-table.html
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
OCP 2025 Meta keynote: Scaling the AI Infrastructure to Data Center Regions
TechCrunch: Meta to build $10 billion Subsea Cable to manage its global data traffic
AI Frenzy Backgrounder; Review of AI Products and Services from Nvidia, Microsoft, Amazon, Google and Meta; Conclusions
Bharti Airtel and Meta extend 2Africa Pearls subsea cable system to India
Is AI the driving force behind the metaverse?
Analysis: Nvidia’s rumored new 6G AI-RAN – likely features/functions and industry impact
Executive Summary:
According to Light Reading, Nvidia is working on a GPU combo chip that would sit directly in the 6G radio unit [1.], extending its AI-RAN push from baseband/server into the radio itself. It’s reported to be a more hardware-integrated, sub-100W embedded design rather than just GPU acceleration in centralized RAN compute.
Note 1. 6G/IMT 2030 Radio Interface Technologies (RITs) have yet to be defined, let alone specified by 3GPP or ITU-R WP5D. They won’t be solidified until the end of 2030 so any specific silicon design won’t be completed until then or 2031!
……………………………………………………………………………………………………………………………………………………….
Light Reading’s headline frames it as a “radical new AI-RAN plan and they wrote that “the move was confirmed by knowledgeable sources, with Nvidia saying GPUs in more advanced radios will become “essential” in future. It marks a dramatic new development in the GPU giant’s “AI-RAN” strategy.”
If accurate, this would be a notable shift for Nvidia, because it would let them influence the whole RAN stack, not just centralized compute. That could matter for performance, power efficiency, and AI-native functions such as sensing, spectrum optimization, and real-time signal processing. Nvidia’s broader 6G messaging already emphasizes AI-native wireless, integrated sensing and communications, and spectrum agility as core themes.
The unconfirmed report fits Nvidia’s existing telecom roadmap rather than appearing out of nowhere. Nvidia has already announced an AI-native wireless stack for 6G with partners including Cisco, MITRE, Booz Allen, ODC, and T-Mobile, and it has promoted AI-RAN as a way to combine connectivity, computing, and sensing on one platform. It also aligns with the company’s recent partnership with Nokia, where Nvidia introduced the ARC-Pro 6G-ready accelerated computing platform and described it as a software-upgradable path from 5G-Advanced to 6G. That makes the rumored radio-chip move look like a vertical extension of the same strategy.
For wireless network operators, a radio-unit chip from Nvidia would be significant only if it improves cost, power, or flexibility versus incumbent RU silicon. The practical test will be whether it can deliver enough RF, baseband, and AI function integration to justify another architecture layer at the edge. It would also intensify competition in the radio-access supply chain and reinforce the trend toward AI-native, software-defined RANs. It also suggests Nvidia wants to shape not only the compute layer but the physical radio layer of 6G networks.
Possible AI Silicon Features and Functions:
Nvidia would most likely add AI-for-RAN features into radio silicon first, because those map directly to signal processing and link adaptation rather than to generic “AI at the edge.” Nvidia’s own AI-RAN materials emphasize embedding AI/ML into the radio signal-processing layer to improve spectral efficiency, coverage, capacity, and performance. Here are a few likely AI features/functions for the rumored 6G AI Nvidia super chip:
-
Neural channel estimation and equalization, to infer cleaner channel state from noisy RF observations and improve link reliability. Nvidia’s open-source Aerial release specifically calls out advanced neural models for channel estimation.
-
Real-time beam management, including beam selection, beam tracking, and beam refinement for massive MIMO and mmWave/upper-midband deployments. These are natural AI-RAN use cases because they depend on fast adaptation to changing propagation conditions.
-
Spectrum agility and interference mitigation, such as identifying jammed or congested resource blocks and dynamically avoiding them. NVIDIA and partners have already described spectrum agility applications that freeze only affected frequencies while keeping the rest of the system online.
-
Dynamic resource scheduling, using learned traffic and channel patterns to allocate PRBs, power, and compute more efficiently in real time. Nvidia describes AI-RAN as improving spectral efficiency and dynamic traffic handling through AI.
-
Integrated sensing and communications support, where the radio helps detect objects, motion, or environmental context in parallel with communication. Nvidia has already highlighted ISAC-style applications with camera/RF fusion and object tracking.
-
Edge inference hooks, letting the RU expose real-time PHY data to AI applications or a dApp-style framework. Nvidia’s open-source Aerial stack says third-party apps can access physical-layer data through secure APIs and modify RAN behavior in real time.
-
Self-optimization and closed-loop control, where the radio silicon learns local conditions and continuously retunes thresholds, coding, MCS selection, and precoding policies. That fits Nvidia’s broader framing of AI-native networks as software-defined and continuously adaptable.
The most plausible first wave is not a fully autonomous “AI radio,” but a hybrid RU chip that accelerates selected PHY functions and exposes telemetry/data paths to the rest of the AI-RAN stack. Nvidia’s current messaging emphasizes software-defined infrastructure, deterministic performance, and layered AI-RAN capabilities rather than replacing the entire RAN with a black-box model.
The real differentiator would be whether Nvidia can combine RF signal processing with its GPU/CUDA ecosystem, so the same platform handles channel learning, inference, and orchestration across RU/DU/CU tiers. That would let operators optimize for spectral efficiency and OPEX while still keeping a software-upgrade path to 6G. Radio electronics is constrained by power, latency, determinism, and certification, so Nvidia would need to prove these AI features help without destabilizing PHY timing. That is why the likely starting point is assistive AI inside the signal chain, not a fully learned end-to-end radio.
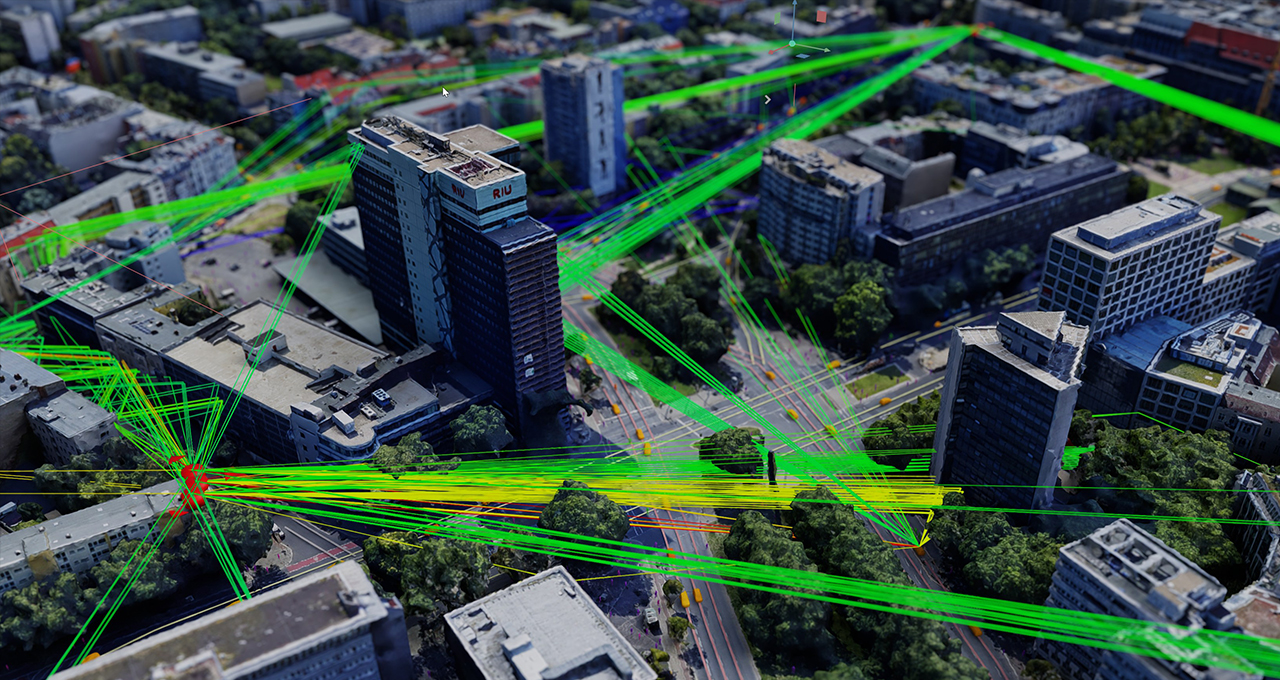
Image Credit: Nvidia
…………………………………………………………………………………………………………………………………………………………………………………………………………..
Competitive Analysis:
Nvidia’s reported move into a 6G radio-unit chip is most threatening to Marvell and Qualcomm at the silicon layer, while it is more of a strategic architecture challenge to Nokia and Ericsson at the system level. The immediate effect is less about a single chip and more about Nvidia trying to pull compute, connectivity, and AI deeper into the RAN value chain
Qualcomm is the closest direct competitor if Nvidia is trying to put silicon into the radio or near-radio layer. Qualcomm already has a Layer 1 strategy that combines silicon and software in SmartNIC/server-adjacent form factors, so Nvidia would be moving into a space where Qualcomm has both telecom credibility and established IP.
The risk for Qualcomm is that Nvidia can use its AI brand, CUDA ecosystem, and hyperscale relationships to redefine what “performance” means in RAN silicon, especially if AI-native functions become a buying criterion. The counterpoint is that Qualcomm still has a strong edge in wireless-specific silicon integration and standards heritage, which matters if the 6G radio path remains RF- and modem-centric.
Nokia looks less exposed in the short term because it is already partnering with Nvidia rather than treating it as a pure adversary. Nvidia and Nokia have publicly framed their relationship as an AI-native 5G-Advanced/6G platform effort, and Nokia says it will add NVIDIA-powered commercial AI-RAN products to its RAN portfolio.
Nonetheless, a Nvidia radio-chip push could still compress Nokia’s differentiation over time if more of the RAN stack becomes software-defined and GPU-centric. The strategic question is whether Nokia remains the integrator and operator-facing systems vendor, or whether Nvidia gradually becomes the architectural center of gravity.
Ericsson is the most structurally interesting case because it sits at the high end of global RAN share and has been more cautious about Nvidia as a Layer 1 option. Light Reading notes Ericsson is currently dismissive of Nvidia as a Layer 1 choice, even while the broader ecosystem explores AI-RAN collaboration.
For Ericsson, the threat is not immediate revenue loss from a single chip; it is erosion of the traditional assumption that RAN leadership comes from proprietary radio and baseband stacks. If Nvidia can make AI-native RAN a default design paradigm, Ericsson may be forced to defend its software and systems value rather than simply its box-selling model.
Samsung Electronics contacted Light Reading after their story was published to point out that it also works with AMD as a chip partner. “Samsung supports full Layer 1 (L1) processing using Intel’s telco CPUs (e.g., Xeon 6 Granite Rapids) and lookaside accelerator approach and in addition has successfully demonstrated full L1 processing on AMD’s CPUs without relying on dedicated L1 accelerators,” a Samsung spokesperson said via email.
Marvell is the most exposed chip supplier in this story because its telecom position is more concentrated in custom Layer 1 silicon. Light Reading specifically points out that Marvell is a critical supplier to Nokia in Layer 1, which makes a Nvidia radio-chip effort a direct substitution threat in portions of the stack.
If Nvidia succeeds, Marvell faces a two-sided squeeze: loss of design wins in telecom silicon and a narrative shift toward AI-native programmable platforms that favor Nvidia’s broader ecosystem. Marvell’s defense is that telecom operators still care about power, latency, and deterministic functionality, areas where custom silicon can remain more efficient than a generalized AI-compute approach.
…………………………………………………………………………………………………………………………………………………………………………
Summary Table:
| Company | Impact level | Why |
|---|---|---|
| Qualcomm | High | Direct silicon adjacency and overlapping Layer 1 ambitions. |
| Marvell | High | Telecom custom-silicon exposure, especially Layer 1. |
| Ericsson | Medium | Strategic and architectural threat more than immediate chip displacement. |
| Nokia | Medium to low near term | Partnered with Nvidia, so risk is more about future dependence and stack control. |
Source: Perplexity.ai
…………………………………………………………………………………………………………………………………………………………………………
Conclusions:
It’s unknown whether Nvidia’s rumored radio chip becomes a product, a reference design, or just an extension of its AI-RAN platform. If it ships, watch for operator trials, power-envelope disclosures, and whether it targets RU integration, DU acceleration, or a hybrid AI-RAN endpoint. If it stays at the partnership/reference-design level, the market impact will be more narrative than revenue-relevant.
Another unanswered question is whether Nokia and Ericsson keep treating Nvidia as a collaborator while preserving their own Physical layer control, or whether they start to see Nvidia as a platform owner in the making. That boundary will determine whether this is a tactical ecosystem play or the beginning of a deeper industry reset.
…………………………………………………………………………………………………………………………………………………………………………
References:
https://www.lightreading.com/6g/nvidia-has-a-radical-new-ai-ran-plan-a-6g-radio-unit-chip
https://www.lightreading.com/6g/analyst-insight-6g-coming-into-focus
https://www.nvidia.com/en-us/industries/telecommunications/ai-ran/
RAN Silicon Rethink- Part II; vRAN and General-Purpose Compute
Orange, Nokia, Nvidia, and Intel debate: ASICs vs. GPUs vs. General-Purpose CPUs for RAN Baseband Processing
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
Dell’Oro: Analysis of the Nokia-NVIDIA-partnership on AI RAN
Nvidia pays $1 billion for a stake in Nokia to collaborate on AI networking solutions
Inside Nokia’s new AI Networking Innovation Lab
Analysis: Nvidia’s $2 billion investment in Marvell; NVLink Fusion ecosystem & RAN vendor silicon strategy
Marvell shrinking share of the RAN custom silicon market & acquisition of XConn Technologies for AI data center connectivity
Cisco report: Agentic AI to reshape WAN traffic, AI inference will be ~25% of total traffic by 2035
Executive Summary:
Consumer-driven AI traffic [1.] currently represents a marginal share of aggregate Internet traffic. However, accelerating adoption of agentic AI is expected to materially reshape traffic composition over the next decade. In its “AI Impact on Wide Area Networks” report, Cisco projects that AI will emerge as the dominant driver of network traffic growth. As consumer AI adoption approaches “near-universal usage,” AI and agentic AI are forecast to increase consumer-driven network traffic by approximately 6.6× by the mid-2030s (see chart below).
Cisco estimates that this AI expansion will account for roughly 63% of incremental traffic growth relative to non-AI scenarios. The study focuses specifically on WAN implications, rather than data center or GPU infrastructure, and provides guidance on network design and capacity planning. Methodologically, the report integrates real-world traffic observations (via Cisco Crosswork Assurance User Experience), third-party industry datasets, and controlled laboratory evaluations of AI agents to characterize how AI-generated traffic diverges from conventional web traffic patterns.
Token-consumption data shows nearly 10x year-over-year growth, while in some service provider measurements Cisco is seeing ~4x growth in just eight months. Sustained growth at these rates means AI traffic will become a meaningful component of overall network traffic by 2035.
Note 1. Consumer AI traffic has a few defining technical traits: it is still dominated by short text-based exchanges, but it is becoming more stateful, more upstream-heavy, and more latency-sensitive as users move from simple prompts to agentic workflows and multimodal interactions. Today’s consumer AI traffic is still overwhelmingly text-oriented, which is one reason the aggregate bandwidth impact remains modest despite rapid adoption. Comcast’s network observation is a useful real-world proxy: 97.1% of AI traffic was text-based, while images accounted for 2.6% and video only 0.3%. The key technical implication is that current traffic volumes are often limited more by conversation frequency and session behavior than by very large payloads, though that changes quickly as users adopt image, audio, and video generation.
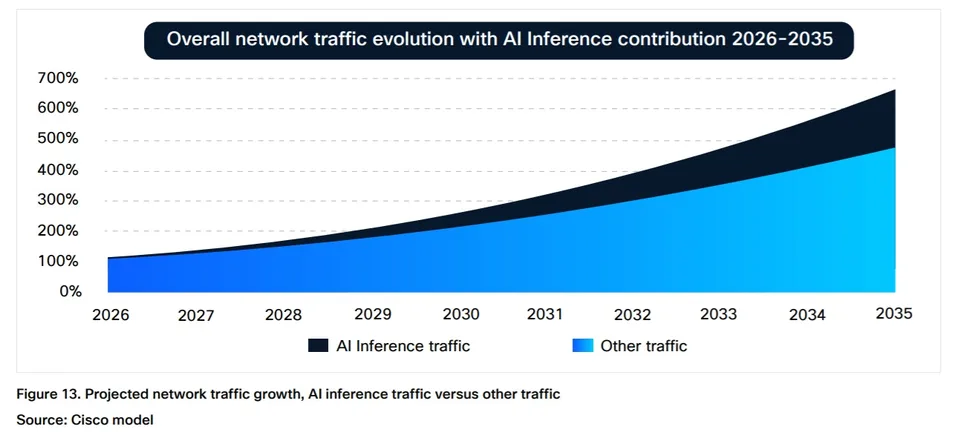
Although AI inference traffic is currently “negligible” relative to dominant categories such as video streaming, Cisco projects it will comprise approximately 25% of total network traffic by 2035 (see chart below). At that point, AI traffic is expected to represent a “meaningful component” of overall network load. Importantly, AI-generated traffic exhibits distinct characteristics: inference flows are approximately twice the duration of typical web transactions, demonstrate higher upstream bandwidth demand, and operate at “software speed” rather than human interaction rates.
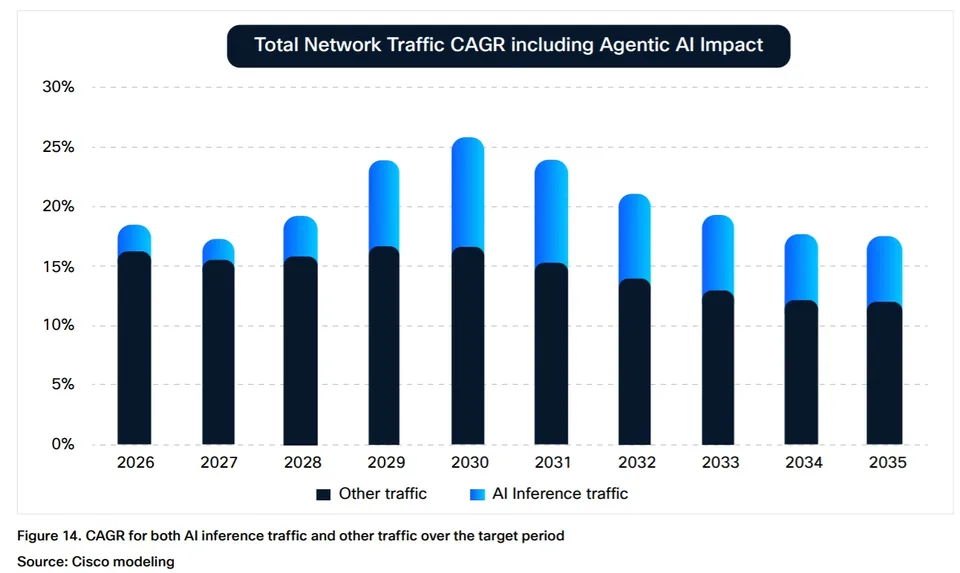
The emergence of AI agents as “power users” further amplifies these dynamics. Cisco notes that agent-executed tasks can generate up to 450% more traffic per task compared to human-driven interactions. This shift is expected to drive operator adoption of “flow-aware network and security systems” as traffic patterns become increasingly machine-driven and less predictable.
Cisco’s broader framing is that AI traffic “isn’t just adding traffic,” but is changing the shape of traffic, with inference flows running about twice as long as typical web transactions and, in some cases, generating up to 450% more traffic per task when an agent executes the workload. AI inference sessions tend to hold resources longer, create more sustained flows, and push operators to think in terms of flow-aware behavior rather than only peak-throughput sizing. Cisco also notes that about 9% of AI inference flows carry more upstream than downstream traffic, versus about 0.5% for typical web traffic, which is a meaningful shift for access and broadband networks. Cisco reports that approximately 9% of AI inference flows are upstream-dominant, compared to roughly 0.5% for traditional web traffic, with this divergence expected to widen alongside increased agentic AI utilization. In parallel, latency sensitivity is anticipated to become a more critical performance parameter for AI-driven applications.
Latency and symmetry:
AI traffic is also more sensitive to latency than many ordinary consumer web transactions because the user experience is often conversational and interactive, with the expectation of near-immediate turn-taking. Cisco describes AI inference as operating at “software speed” rather than human speed, which means small delays can be more noticeable and operationally important. At the same time, upstream demand becomes more significant because prompts, context, attachments, and agent-generated actions can increase return-path traffic, especially as multimodal inputs and agentic tool use expand.
Multimodal growth:
The biggest step-up in technical impact comes when consumer AI shifts from text-only prompting to multimodal generation and agent-driven workflows. In those cases, each task can involve multiple model calls, retrieval steps, tool invocations, and richer media payloads, which expands both flow count and bytes per session. Cisco’s study suggests that this is why AI traffic will increasingly require “flow-aware network and security systems,” because the traffic profile is not just larger, but structurally different from conventional browsing.
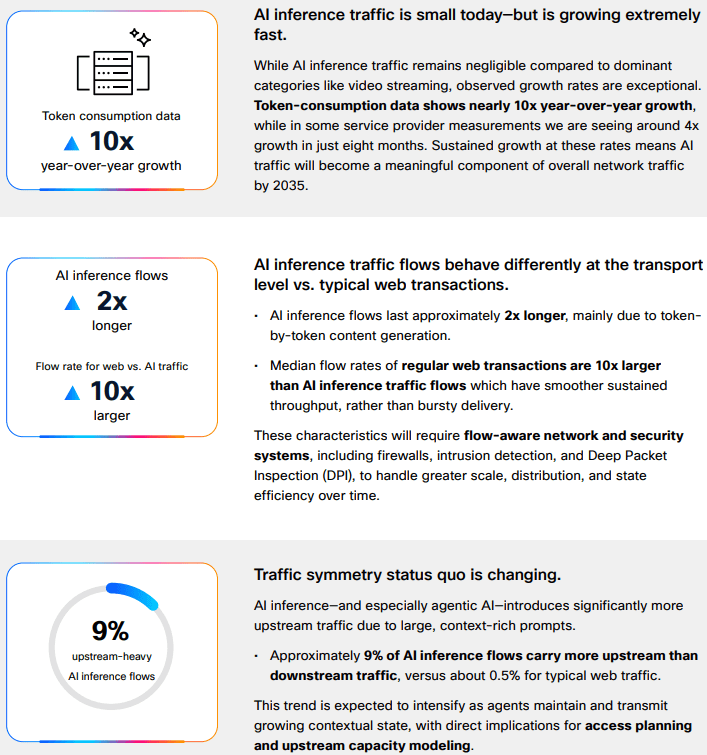
Infrastructure Implications:
Telecom infrastructure is becoming “increasingly intertwined with hyperscale infrastructure, not because operators are leading AI investment, but because they are becoming part of the ecosystem that supports it,” analyst firm MTN Consulting said in an April 27th research note. “Demand for optical transport, data-center interconnect, and edge infrastructure is rising as telecom networks carry growing volumes of cloud and AI-driven traffic,” the firm said.
“AI network traffic is already reshaping infrastructure needs. What we are seeing is clear: AI isn’t just adding traffic. It’s changing the shape of traffic,” Javier Antich, principal product management engineer in the CTO office of Cisco’s provider connectivity group, and Gurudatt Shenoy, SVP, product management, provider connectivity, explained in this blog post.
These shifts are beginning to influence access network evolution. Fiber networks already provide relatively symmetric throughput and low latency, while cable operators are advancing similar capabilities through DOCSIS upgrades. Mid-split and high-split architectures increase upstream spectrum allocation, enabling more balanced capacity profiles. Concurrently, Tier 1 operators such as Comcast and Charter Communications are introducing low-latency enhancements within DOCSIS networks.
Operational data reflects early-stage impacts. Comcast Chief Network Officer Elad Nafshi noted at the Cable Next-Gen event in March that approximately 97.1% of AI traffic on Comcast’s network remains text-based, with images accounting for 2.6% and video just 0.3%, indicating that bandwidth-intensive multimodal AI traffic has yet to scale materially.
Network design impact:
For broadband and access networks, the immediate engineering issues are upstream traffic capacity, queue behavior, and latency consistency rather than raw total throughput alone. Symmetry upgrades (such as DOCSIS mid-split and high-split for MSOs), along with low-latency capabilities, are relevant because consumer AI creates more return-path pressure and more time-sensitive sessions. In other words, the challenge is not simply to carry more bytes; it is to carry more interactive sessions with predictable performance, especially as multimodal and agentic usage scales.
………………………………………………………………………………………………………………………………………………………………………………………………………….
References:
Will the wave of AI generated user-to/from-network traffic increase spectacularly as Cisco and Nokia predict?
Telecom operators investing in Agentic AI while Self Organizing Network AI market set for rapid growth
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Cisco CEO sees great potential in AI data center connectivity, silicon, optics, and optical systems
The Financial Trap of Autonomous Networks: Scaling Agentic AI in the Telecom Core
Ericsson integrates Agentic AI into its NetCloud platform for self healing and autonomous 5G private networks
STL Partners webinar: Agentic AI needed for RAN autonomy & efficiency
Nokia to showcase agentic AI network slicing; Ericsson partners with Ookla to measure 5G network slicing performance
Agentic AI and the Future of Communications for Autonomous Vehicles (V2X)
Telecom data centers must be redesigned for the AI era with rack scale architectures, enhanced power & cooling requirements
Is the “far edge” a bridge to far to cross for AI inferencing? What about “Distributed AI Grids”?
T-Mobile US announces new broadband wireless and fiber targets, 5G-A with agentic AI and live voice call translation
Intel and AI chip startup SambaNova partner; SN50 AI inferencing chip max speed said to be 5X faster than competitive AI chips
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Telecom data centers must be redesigned for the AI era with rack scale architectures, enhanced power & cooling requirements
- Gigawatt-Scale Power and Liquid Cooling: Next-generation AI clusters require unprecedented power density, often exceeding 40kW to 100kW per rack. Telcos cannot simply drop these into existing facilities; they require entirely new or heavily retrofitted data centers featuring advanced liquid cooling architectures to prevent thermal throttling.
- The Fragmented Edge vs. Centralized Fortresses: Operators are realizing that centralized hyperscale data centers (like AWS or Azure clusters in Virginia) cannot support latency-sensitive “Physical AI” or real-time agentic workflows. To make AI-native networking work, carriers must deploy high-density compute racks directly at the network edge, a highly complex and capital-intensive roll-out.
- Neutral Interconnection Hubs: Multi-cloud setups and distributed training workloads are putting immense pressure on backbones. The expansion rate of neutral interconnect hubs (like Equinix and Digital Realty) is directly gating how fast enterprises and telcos can orchestrate data between fragmented training clusters and edge inference nodes.
- Rack-scale architecture is rapidly emerging as the primary deployment unit as enterprises transition from discrete servers to fully integrated systems capable of supporting the power density, thermal constraints, and interconnect requirements of production-scale AI workloads.
Image Credit: AMD
……………………………………………………………………………………………………………………………………………………………………………………………
AI data centers supporting telecom networks require fundamentally different power and cooling infrastructure compared to legacy enterprise facilities. The transition to generative AI and real-time edge processing has pushed power density per rack from an average of 5–10 kW up to 40–100+ kW.
Dell Technologies Inc. has been strategically aligning its portfolio to this shift, and at Dell Technologies World 2026, the company introduced an expanded PowerRack portfolio that integrates compute, networking, and storage within a unified rack-scale platform. This evolution underscores a broader transition in system design priorities—from server-centric architectures to tightly coupled, rack-level systems—driven by the escalating demands of AI infrastructure. As Arun Narayanan, senior vice president of compute and networking product management at Dell, indicated, increasing power density and system complexity are making rack-level architectural optimization not just advantageous, but essential.
“Go back two years ago, the largest, most powerful rack was 80 kilowatts,” Narayanan said. “Come to Vera Rubin, you’re going to get racks of 235 kilowatts, and then get to the next generation of Rubin Ultra and Kyber, you’re going to very quickly get to one megawatt racks. You have to fundamentally redesign everything from power distribution to cooling.”
-
- Medium-Voltage Power Distribution: Traditional facilities step utility power down to 480V AC far from the rack. High-density AI data centers run medium-voltage or power directly down to the row or container level before stepping down. This minimizes conduction losses through the heavy copper busbars.
- The Move to 48V DC Busbars: Within the server chassis, power shelf architectures are shifting from traditional 12V DC distribution to DC busbars. A delivery architecture reduces the current required to deliver the same wattage by a factor of four. Resistive power loss occurs when electrical energy is converted into heat due to the inherent opposition to current flow in a conductor. The formula (P{loss} = I^2 R dictates that this power dissipation is highly sensitive to current changes. Therefore, cutting the current to one-fourth reduces internal rack heat and conduction power losses by 93.75%
- Grid Interconnection and Substation Constraints: A single rack-scale AI cluster (such as a cluster of 32 or 64 interconnected nodes) can easily pull 2 to 3 Megawatts (MW). Operators are bypassing traditional local distribution grids entirely. They are building dedicated on-site substations tied directly to transmission-level lines to guarantee upstream capacity.
       [ Liquid Cooling Architectures for AI Racks ]

 ┌───────────────────────────┐      ┌───────────────────────────┐
 │       Direct-to-Chip      │      │     Immersion Cooling     │
 ├───────────────────────────┤      ├───────────────────────────┤
 │ Closed loop micro-channels│      │ Entire server submerged   │
 │ bolted directly onto GPUs │      │ in dielectric fluid tank  │
 │                           │      │                           │
 │     [ GPU ] ──► [ Liquid] │      │    ┌───┐ ┌───┐ ┌───┐      │
 │   Cold Plate   Coolant    │      │    │GPU│ │CPU│ │RAM│      │
 │    Circuit     Circuit    │      │    └───┴─┴───┴─┴───┘      │
 └───────────────────────────┘      └───────────────────────────┘
-
- Direct-to-Chip (Cold Plate) Cooling: This is the primary architecture for 2026 deployments. A closed-loop copper block with micro-channels is bolted directly onto high-thermal-flux components like the GPU or CPU. A specialized dielectric or water-glycol fluid circulates through the block. This absorbs heat directly from the silicon via conduction and pumps it away to a secondary heat exchanger.
- Immersion Cooling (Single-Phase and Two-Phase):
-
- Single-Phase: The entire server blade is submerged in a bath of non-conductive, hydrocarbon- or synthetic-based dielectric fluid. The fluid circulates through the chassis via natural convection or pumps to remove heat.
- Two-Phase: The dielectric fluid has a low boiling point (\(50^{\circ }\text{C}\)). The heat from the chips boils the fluid into a vapor. The vapor rises to a condenser coil at the top of the sealed tank, condenses back into liquid, and falls back into the pool. This utilizes the latent heat of vaporization, making it highly efficient.
-
- Cooling Distribution Units (CDUs): High-density loops rely on CDUs to act as the barrier between the internal facility water loops (which can be lower quality) and the ultra-pure, treated water circuit flowing directly through the server cold plates.
References:
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Lumen Technologies to connect Prometheus Hyperscale’s energy efficient AI data centers
Merry-go-round of dog chasing its tail: Relationship between U.S. hyperscalers and private Gen AI companies
1. Hyperscalers’ earnings growth this quarter was boosted by an unusually large contribution from “other income,” which was actually mark-ups of their equity stakes in private Gen AI companies. For example:
- Nearly half of Alphabet’s (Google) record $62.6 billion profit—about $28.7 billion—did not come from search ads, cloud services or any of its products at all. It came from Alphabet updating the value of the equity it owns in private AI companies, primarily Anthropic. Alphabet holds a 14% stake before the announcement of an additional $40 billion commitment last week.
- Amazon’s earnings release stated that first-quarter net income “includes pre-tax gains of $16.8 billion included in non-operating income from our investments in Anthropic”—more than half of Amazon’s pre-tax income (or profit) for the quarter.
- Alphabet and Amazon generated “other income” totaling $53 billion in Q1 2026, which accounted for nearly 60% of those two companies’ total net income in Q1 and 34% of the total $155 billion in income this quarter. Of this $53 billion in “other income,” $49 billion was explicitly due to equity stakes in private AI companies.
- Microsoft reported “only” $942mn of other income in the first three months of the year, but this line item has now made $7.2bn over the past nine months.
- Under U.S. accounting rules, publicly traded firms must adjust and report the assessed value of their private equity holdings every quarter. Because private AI start-ups like Anthropic experienced meteoric valuation updates (e.g., Anthropic climbing to an estimated $380 billion), both Alphabet and Amazon were required to record those massive “on-paper” gains directly to their bottom-line net income.
- When the AI bubble finally bursts (and it will) the private AI companies assessed market value will collapse, resulting in “impairment write-downs” and huge earnings declines for the hyperscalers, e.g. Amazon, Google/Alphabet, Microsoft, FB/Meta, and Oracle.
2. Now here’s the merry-go-round/ dog chasing its tail relationship:
Not only have private investments and increasingly engorged funding rounds become a meaningful driver of the hyperscalers’ aggregate earnings, but the money the hyperscalers have pumped into the likes of Anthropic and OpenAI has allowed those private AI companies to sign huge computing deals with Alphabet’s Google Cloud, Microsoft’s Azure and Amazon Web Services (AWS). OpenAI and Anthropic now make up about half of the entire cloud computing order books at Oracle, Alphabet, Amazon and Microsoft!
Indeed, AI startups have loaded up hyperscalers with unprecedented long-term financial commitments.
–>OpenAI and Anthropic make up over $1 trillion of the estimated $2 trillion cumulative revenue backlog currently held by major cloud service providers!
- OpenAI to Microsoft Azure: Internal documents show OpenAI’s massive server rentals have generated more than $23 billion in direct cloud spending for Microsoft.
- Anthropic to Google Cloud: Anthropic signed a contract committing to spend $200 billion over five years on Google’s cloud infrastructure and TPU chips.
- Anthropic to AWS: In tandem with a fresh $5 billion investment from Amazon, Anthropic committed to spend over $100 billion over the next decade on AWS technologies.
Image Generated by Chat GPT
……………………………………………………………………………………………………………………………………………………………
-
- Backlog Percentage: Over 40%. Anthropic‘s $200 billion Multi-Year Commitment accounts for nearly half of Google Cloud’s total disclosed $240 billion revenue backlog.
- Current Revenue Share: Estimated 12% to 15% of its current $20 billion quarterly revenue run-rate is driven directly by AI infrastructure consumption from startups (both frontier labs and over 40 mid-tier AI companies built on Google Cloud Vertex AI).
-
- Current Revenue Share: Estimated 15% to 18%. Microsoft’s annualized AI revenue run-rate hit $37 billion. A massive chunk of Azure’s overall 40% growth rate is anchored directly by OpenAI’s compute demands and the commercialization of OpenAI-tied products.
- Current Revenue Share: Estimated 6% to 8%. While AWS has the largest overall cloud scale ($150 billion annual run rate), its revenue is traditionally diversified across enterprise SaaS and retail. However, Anthropic’s new $100 billion infrastructure commitment means AWS’s revenue mix is aggressively shifting toward AI startups. [1, 2, 3, 4]
–>This is another sign of just how incestuously codependent the big tech industry is to astronomically valued private AI start-ups.
…………………………………………………………………………………………………………………………………………………………..
4. Another example of this codependency is Oracle and OpenAI’s massive, debt-fueled financial loop. In September 2025, the two companies signed a staggering five-year, $300 billion cloud-computing contract. This single deal radically transformed both companies’ financial profiles, binding their survival together as inextricably tied.
-
- For Oracle: The $300 billion contract instantly added to Oracle’s Remaining Performance Obligations (RPO), which skyrocketed 359% to $455 billion. This accounting metric allowed Oracle to position itself as a dominant “hyperscaler,” pushing its market cap upward.
- For OpenAI: The contract allowed OpenAI to claim it had secured the long-term compute capacity needed to achieve Artificial General Intelligence (AGI). This backed up its massive valuations, enabling OpenAI to close a historic $122 billion funding round in March 2026 at an $852 billion valuation.
- Oracle is a Financial Proxy for OpenAI: If OpenAI faces a “credit event” or cash crunch, Oracle’s stock directly plummets. Critics note that Oracle signed a contract with a startup that historically burns far more cash than it takes in, making OpenAI’s ability to actually pay the $300 billion highly volatile.
- The Debt Spiral: To physically fulfill OpenAI’s compute demands, Oracle has gone on a massive, debt-fueled construction spree. Oracle raised $18 billion in bonds in late 2025 and an additional $30 billion in early 2026. Its capital expenditures have eclipsed operating cash flows, leading to deeply negative free cash flow and over $134 billion in total corporate debt.
-
- Project Finance Bottlenecks: Major commercial banks have struggled to syndicate the massive multi-billion-dollar construction loans Oracle needs to build out the required data centers (such as its 4.5-gigawatt capacity goals).
- Bank Limits: The sheer volume of debt concentrated around this single enterprise relationship has pushed several Wall Street institutions against their regulatory exposure limits for a single corporate partnership.
……………………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.ft.com/content/be97df0a-76b1-4cb0-9ba4-d1117d8d1450
https://fortune.com/2026/04/30/google-amazon-ai-profits-anthropic-stake-bubble-earnings-2026/
https://finance.yahoo.com/sectors/technology/articles/google-amazon-biggest-profit-driver-170449859.html
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Expose: AI is more than a bubble; it’s a data center debt bomb
Amazon’s Jeff Bezos at Italian Tech Week: “AI is a kind of industrial bubble”
Open AI raises $8.3B and is valued at $300B; AI speculative mania rivals Dot-com bubble
China’s open source AI models to capture a larger share of 2026 global AI market
OpenAI and Broadcom in $10B deal to make custom AI chips
Generative AI Unicorns Rule the Startup Roost; OpenAI in the Spotlight