AI
Verizon and Ericsson Advance AI-Native RAN Operations with Nationwide EIC Rollout
Executive Summary:
Verizon and Ericsson are expanding their longstanding collaboration to introduce AI-native automation into Radio Access Network (RAN) operations. The companies plan a nationwide deployment of Ericsson Intelligent Controller (EIC) [1.], a software platform for running RAN applications (rApps) co-developed by Ericsson and Verizon.
The initiative is intended to improve mobile network performance, automate network optimization and advance Verizon’s longer-term objective of achieving Level 4 (L4) network autonomy. The companies have demonstrated EIC and associated rApps in a live network environment, using AI-based cell shaping and traffic steering to optimize Massive Multiple-Input Multiple-Output (Massive MIMO) antenna operation.
According to Ericsson and Verizon, field deployment of the Advanced Antenna System (AAS) Cell Shaper rApp produced throughput gains of up to 8.9% in downlink data radio bearer (DRB) throughput and up to 8% in uplink user equipment (UE) throughput.
The collaboration has three principal objectives:
- RAN autonomy: Building on open, programmable interfaces to automate network operations and optimization.
- AI-based optimization: Deploying rApps to improve radio performance, traffic distribution and operational efficiency.
- Operator-controlled innovation: Enabling Verizon to develop and deploy its own rApps alongside Ericsson applications rather than relying exclusively on vendor-developed network optimization software.
Note 1. “Ericsson Intelligent Controller (EIC) is a new product part of the Ericsson Intelligent Automation Platform (EIAP) which is Ericsson’s Open RAN aligned service management and orchestration (SMO) solution. EIAP provides multivendor RAN automation, management, and orchestration of Cloud and Open Radio access networks. Ericsson differentiator is the extended support to purpose-built radio access networks.” SOURCE: Ericsson
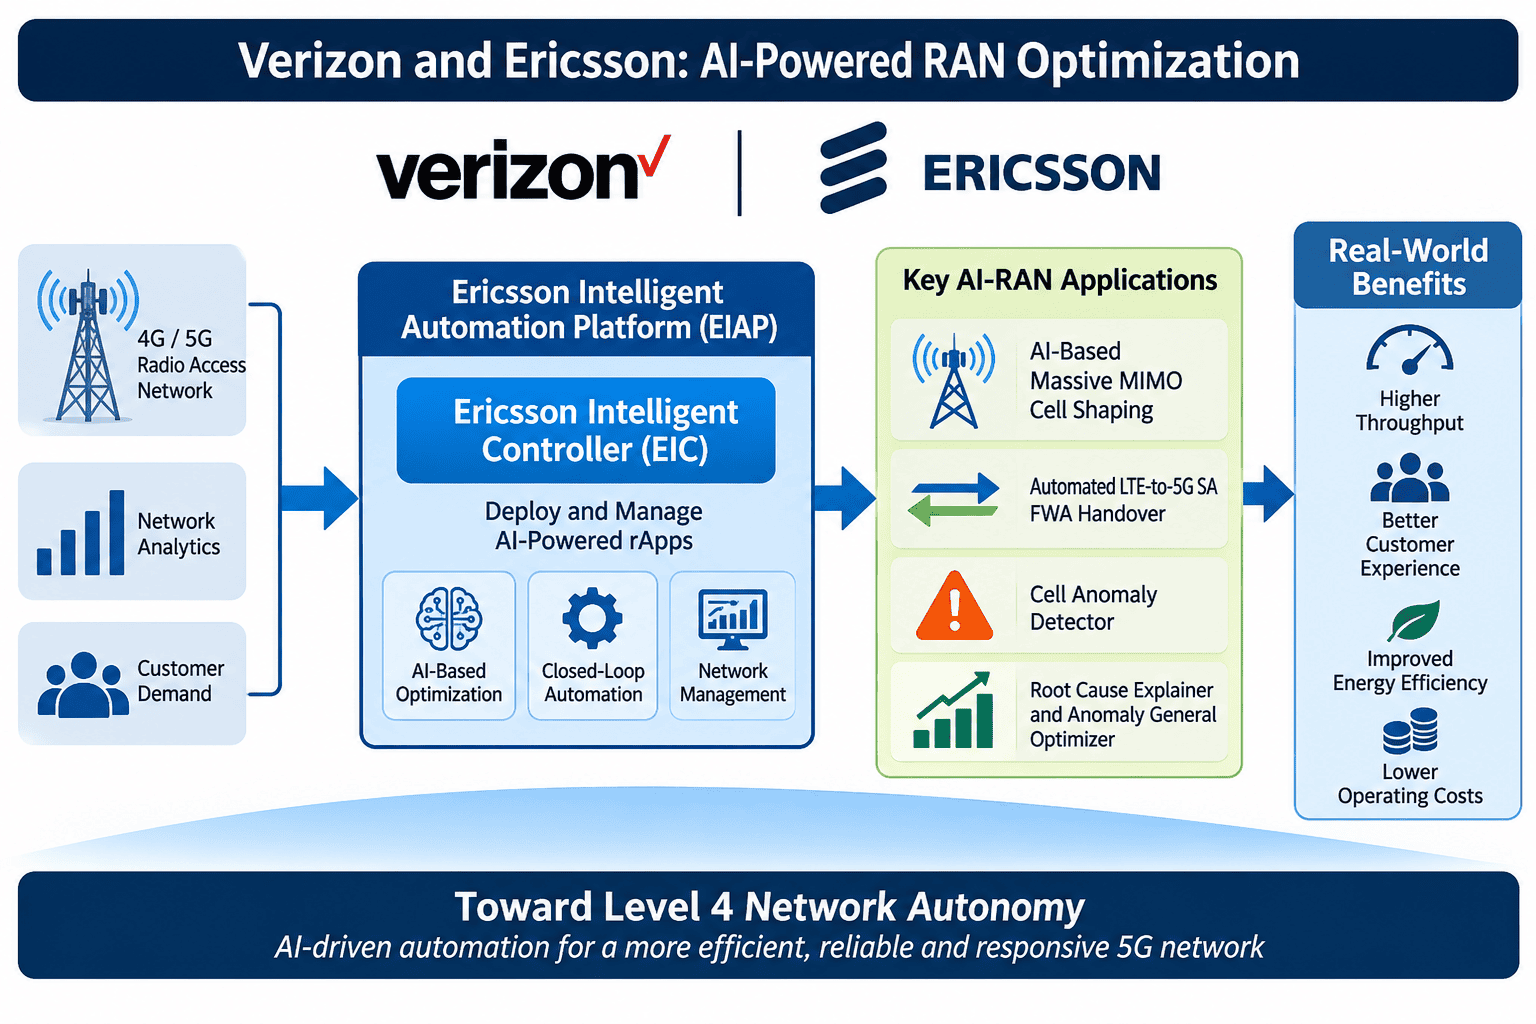
Image generated by ChatGPT which was also used for research and writing this article.
………………………………………………………………………………………………………………………………………………………………………………………………………….
AI-Native RAN Automation and Massive MIMO Optimization:
A central component of the collaboration is the application of AI to Massive MIMO antenna systems. Massive MIMO uses large antenna arrays at 5G base stations to transmit and receive multiple spatially separated data streams. Through beamforming, the radio system can concentrate transmitted energy toward individual users or groups of users rather than radiating power uniformly in all directions. Combined with spatial multiplexing, this can improve spectral efficiency, increase network capacity and extend coverage.
However, optimizing Massive MIMO performance across a large mobile network is complex. Radio propagation conditions, user locations, traffic demand, interference, antenna configuration and mobility patterns change continuously. A configuration that improves performance in one cell or at a particular time of day may not be optimal under different network conditions.
Ericsson’s Advanced Antenna System (AAS) Cell Shaper rApp applies AI-based optimization to antenna operation and cell coverage. Its purpose is to adjust radio coverage characteristics and traffic distribution to better match changing network conditions.
Cell shaping and traffic steering are particularly important in densely populated areas where neighboring cells may experience significantly different traffic loads. Intelligent adjustment of antenna coverage and traffic distribution can help balance demand, reduce congestion and improve utilization of available radio resources.
These reported throughput improvements demonstrate the potential to improve the utilization of existing radio infrastructure through software-based optimization. However, the companies have not disclosed the geographic scope, test duration, baseline conditions, radio configurations or measurement methodology underlying the maximum reported gains. Consequently, the results should not be interpreted as nationwide average improvements or as evidence that equivalent gains will be achieved throughout Verizon’s network.
Automating Fixed Wireless Access Mobility:
Another application demonstrated by Verizon addresses mobility problems affecting Fixed Wireless Access (FWA) devices transitioning between LTE and 5G Standalone (SA) networks.
Verizon implemented a Connected Mode Inter-Radio Access Technology (Inter-RAT) handover methodology to address failed transitions from LTE to 5G SA for FWA devices. According to the companies, the automated methodology eliminates the need for manual intervention when these handover failures occur.
In this scenario, Inter-RAT mobility involves transitioning a device between different radio access technologies: 4G LTE and 5G NR.
Conventional 5G Non-Standalone (NSA) deployments use an LTE anchor, with 5G NR added as a secondary radio access technology (5G NSA is essentially 4G LTE with a 5GNR RAN interface). It relies on the LTE/Evolved Packet Core (EPC) architecture. By contrast, 5G SA uses a 5G NR radio access network connected directly to a 5G Core (5GC), without requiring an LTE anchor. Only 5G SA can realize the 5G features and functions defined by 3GPP’s 5G Architecture specs.
–>A successful 5G NSA to 5G SA transition therefore requires appropriate mobility procedures, network configuration and coordination between the LTE and 5G SA environments.
This application illustrates how programmable RAN automation can address specific operational problems through targeted software applications rather than relying exclusively on conventional network-management procedures and manual troubleshooting. It also demonstrates that RAN automation can address mobility management, network reliability and operational efficiency beyond radio-throughput optimization
Expanding the rApp Ecosystem and Network Autonomy:
Verizon plans to deploy EIC nationally during 2026 and introduce additional rApps developed both internally and by Ericsson. Planned applications include:
- Cell Anomaly Detector: Identifies abnormal cell behavior that may affect network performance.
- Root Cause Explainer: Helps identify potential causes of network problems, supporting more efficient troubleshooting and service restoration.
- Anomaly General Optimizer: Supports network optimization in response to detected anomalies.
The names of these applications suggest different stages of the network assurance and optimization lifecycle. Anomaly detection identifies departures from expected network behavior; root-cause analysis helps determine potential underlying problems; and optimization applications can initiate corrective actions.
When integrated into a coordinated automation framework, these functions can form a closed-loop operational process:
- Monitor: Collect network performance measurements, alarms, configuration data and other operational information.
- Detect: Identify abnormal conditions or performance degradation using analytics and AI/ML models.
- Diagnose: Analyze network data to identify potential root causes.
- Optimize: Determine appropriate corrective actions based on network policies and operating constraints.
- Actuate: Apply approved changes to network configuration or operating parameters.
- Verify: Monitor subsequent network performance to determine whether the corrective action achieved the intended result.
This feedback process is fundamental to autonomous network operations. It allows network optimization to continue without requiring human intervention for every individual adjustment, while retaining appropriate operator oversight and control.
The companies have not provided detailed technical specifications for the three planned applications, so their precise functions, interfaces and degrees of automation remain to be established.
Ericsson Intelligent Automation Platform and Open Interfaces:
The Ericsson Intelligent Controller is a component of the Ericsson Intelligent Automation Platform (EIAP), Ericsson’s open network management and automation environment designed for multivendor, multi-technology networks.
Key platform capabilities include:
- Support for 4G and 5G Radio Access Networks and Ericsson core networks.
- A Non-RT RIC execution environment for rApps.
- Standardized interfaces, including the O-RAN R1 interface.
- Application lifecycle management and deployment.
- Network data collection, analytics and AI/ML workflow capabilities.
- Policy management and coordination of network optimization activities.
- Controlled application execution and network actuation.
Ericsson reports that EIAP’s ecosystem includes more than 100 available rApps from over 100 ecosystem members, supporting different stages of the network automation lifecycle.
The ability for Verizon to develop its own rApps is particularly important. It gives the operator an opportunity to create network-specific optimization functions based on its traffic patterns, spectrum holdings, radio configurations and operational requirements, while also drawing on Ericsson’s broader rApp ecosystem.
An open application environment can reduce dependence on proprietary, vendor-specific optimization functions and encourage third-party application development.
However, the availability of open interfaces and a broad rApp ecosystem should not be confused with a fully interoperable multivendor RAN deployment. Ericsson describes EIAP as supporting multivendor networks, including purpose-built radio access networks. This means that deploying EIC and using O-RAN-aligned interfaces does not, by itself, establish that Verizon is replacing its existing RAN equipment with Open RAN equipment.
The distinction is important: Open RAN automation interfaces and an open application ecosystem can be deployed alongside conventional, purpose-built radio infrastructure.
The Road to Level 4 Network Autonomy:
The nationwide EIC deployment represents another step toward more autonomous RAN operations. Verizon’s longer-term objective is Level 4 (L4) network autonomy, in which network functions can perform increasingly complex operational and optimization tasks with minimal human intervention.
The TM Forum’s Autonomous Networks framework defines L4 as a highly autonomous network capability involving predictive decision-making and active closed-loop management of service-driven and customer-experience-driven networks, supported by AI modeling and continuous learning.
Achieving L4 autonomy requires considerably more than deploying AI applications. It requires:
- Reliable, continuous monitoring of network conditions and performance.
- Accurate AI/ML models that can operate under changing radio and traffic conditions.
- Closed-loop optimization with measurable performance verification.
- Coordination among multiple applications and network domains.
- Policy enforcement, security controls and safeguards against unintended network changes.
- Appropriate human oversight and the ability to intervene when automated actions produce unexpected results.
The distinction between automating individual network functions and achieving end-to-end autonomous network operations is important. An operator may successfully deploy several autonomous rApps without having achieved L4 autonomy across its entire RAN.
Furthermore, the TM Forum autonomy levels are assessed against specific network scenarios and operational domains. Achieving L4 in one function or network domain does not necessarily mean that the entire nationwide network has reached that level.
Verizon’s collaboration with Ericsson provides a programmable software platform and an expanding application ecosystem to support that transition. Whether it ultimately delivers L4 autonomy will depend on the scope of automation, the reliability of closed-loop operations and the integration of these capabilities across Verizon’s network.
Conclusions:
The Verizon-Ericsson initiative illustrates how AI-based software applications, open interfaces and closed-loop control can improve the operation of existing 4G and 5G radio access networks. The reported Massive MIMO throughput improvements and automated LTE-to-5G SA FWA handover demonstrate practical applications beyond AI experimentation. The EIC deployment also provides Verizon with a platform for developing proprietary rApps while leveraging Ericsson’s broader application ecosystem.
The larger challenge will be scaling these capabilities across a nationwide network while maintaining interoperability, reliability, security and measurable improvements in customer experience and network economics. Ultimately, the success of AI-native RAN automation should be judged by sustained improvements in network performance, spectral efficiency, energy consumption and operating costs—not simply by the number of AI applications deployed.
……………………………………………………………………………………………
References:
Verizon and Ericsson Partner to Transform AI-Native Autonomous Networks — November 3, 2026
https://www.ericsson.com/en/portfolio/cross-portfolio/rapp-directory
Autonomous Networks Mission and Levels Taxonomy — TM Forum
About Ericsson Intelligent Controller
About Ericsson Intelligent Automation Platform
AI-RAN and Agentic AI get real: Ericsson, Nokia, Verizon & other operators enter into a new network automation era
Private 5G’s Business Model Shifts: Ericsson’s Move Signals a Market Reset
Ericsson signs MoU’s with Murata and Sumitomo to progress next-gen mobile network infrastructure
4.8 GHz to 4.9 GHz frequency band uses & Verizon Wireless experimental license for testing ISAC with Ericsson
Ericsson leads SK Telecom AI RAN vs. NVIDIA’s GPU centric AI RAN Alliance
Dell’Oro: Private Wireless Revenue Growth Prospects and Challenges
Infineon PSoC MCUs Expand TinyML into a Broader Range of Edge AI Applications
Disclaimer: ChatGPT helped research and write this article, but the author checkpointed the AI repeatedly and had the final say on what to include/exclude in this blog post.
…………………………………………………………………………………………………………………….
Introduction:
Artificial intelligence (AI) running on embedded devices is evolving beyond the relatively narrow range of machine-learning applications traditionally associated with TinyML [1.], rather than Large Language Models (LLMs). Newer microcontrollers (MCUs) are beginning to support a broader class of Edge AI workloads, including speech recognition, natural-language processing, computer vision, optical character recognition (OCR), selected translation applications and increasingly sophisticated voice interfaces. Many selected AI workloads can now be executed locally on embedded MCUs, reducing or eliminating the need for cloud processing for those particular functions.
Note 1. Traditional TinyML (Tiny Machine Learning) focuses on relatively small, task-specific machine-learning models running on resource-constrained embedded devices. The newer development is the ability to supplement those workloads with compact language models and more sophisticated speech and vision inference.
…………………………………………………………………………………………………………………………………………………………………………………
Infineon’s PSoC™ Edge family of microcontrollers illustrates this transition. By combining heterogeneous Arm processors, dedicated neural-network accelerators, substantial memory resources, graphics capabilities and embedded AI software, these MCUs provide a platform for intelligent devices capable of performing more complex AI processing locally.
Infineon states: “The relevant question is not whether an MCU can replicate an 8B LLM, but whether it can deliver useful AI experiences within the power, cost, and latency constraints of edge products. For many real-world edge applications, PSOC™ Edge is not merely capable, it is often a more appropriate solution than a higher-(processing) power MPU-based architecture.”
Let’s examine that assertion and consider Edge AI applications that can be supported by the Infineon PSoC MCUs.
Edge AI Applications supported by Infineon PSoC MCUs:
Infineon’s PSoC Edge MCUs support TinyML, which consists of low-latency, deterministic AI models that process sensor, audio, and vision data locally. The hardware is designed for applications requiring battery-powered execution, sub-1 milliwatt wake states, and zero cloud dependency.
From Infineon: PSoC Edge AI Applications include:
Audio & Voice Processing:
- Speech-to-Intent: Converting spoken commands directly into system actions (e.g., “Turn on the fan”) without needing to transcribe speech into text first.
- Acoustic Event Detection: Identifying specific environmental sounds such as glass breaking, baby crying, gunshots, or alarms.
- Beamforming & Noise Reduction: Using neural networks to filter out background noise in communication devices and smart wearables.
Low-Power Vision (TinyVision):
- Presence & Gesture Detection: Recognizing if a human is in front of a device or interpreting basic hand movements for touchless control.
- Object & Face Counting: Tracking things like people entering a room or basic inventory sorting on a conveyor belt.
- Defect Classification: Performing basic visual quality inspections in automated manufacturing lines.
Smart Sensing & Predictive Maintenance:
- Vibration and Anomaly Detection: Monitoring industrial motors, pumps, or consumer appliances to predict mechanical failure before it happens.
- Sensor Fusion: Combining data from multiple sensors (e.g., temperature, pressure, humidity, and gas sensors) to evaluate environmental conditions or air quality index (AQI) changes in real time.
- Biometric Tracking: Processing health metrics locally in fitness trackers, such as advanced heart-rate variability and sleep stage classification.
The table below illustrates how the PSoC Edge E84 matches these workloads by splitting tasks between its distinct processing domains:
| Workload Type | Active Hardware Component | Typical Power/Performance State |
| Always-On Passive Listening | Cortex-M33 + NNLite microNPU | Ultra-low power, sub-1 mW state waiting for wake words or threshold anomalies. |
| Active Machine Learning Inference | Cortex-M55 + Arm Ethos-U55 NPU | High performance, using 128 MACs/cycle execution to compute vision or audio matrices instantly. |
Source (for the information in this section and the table): Infineon
………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
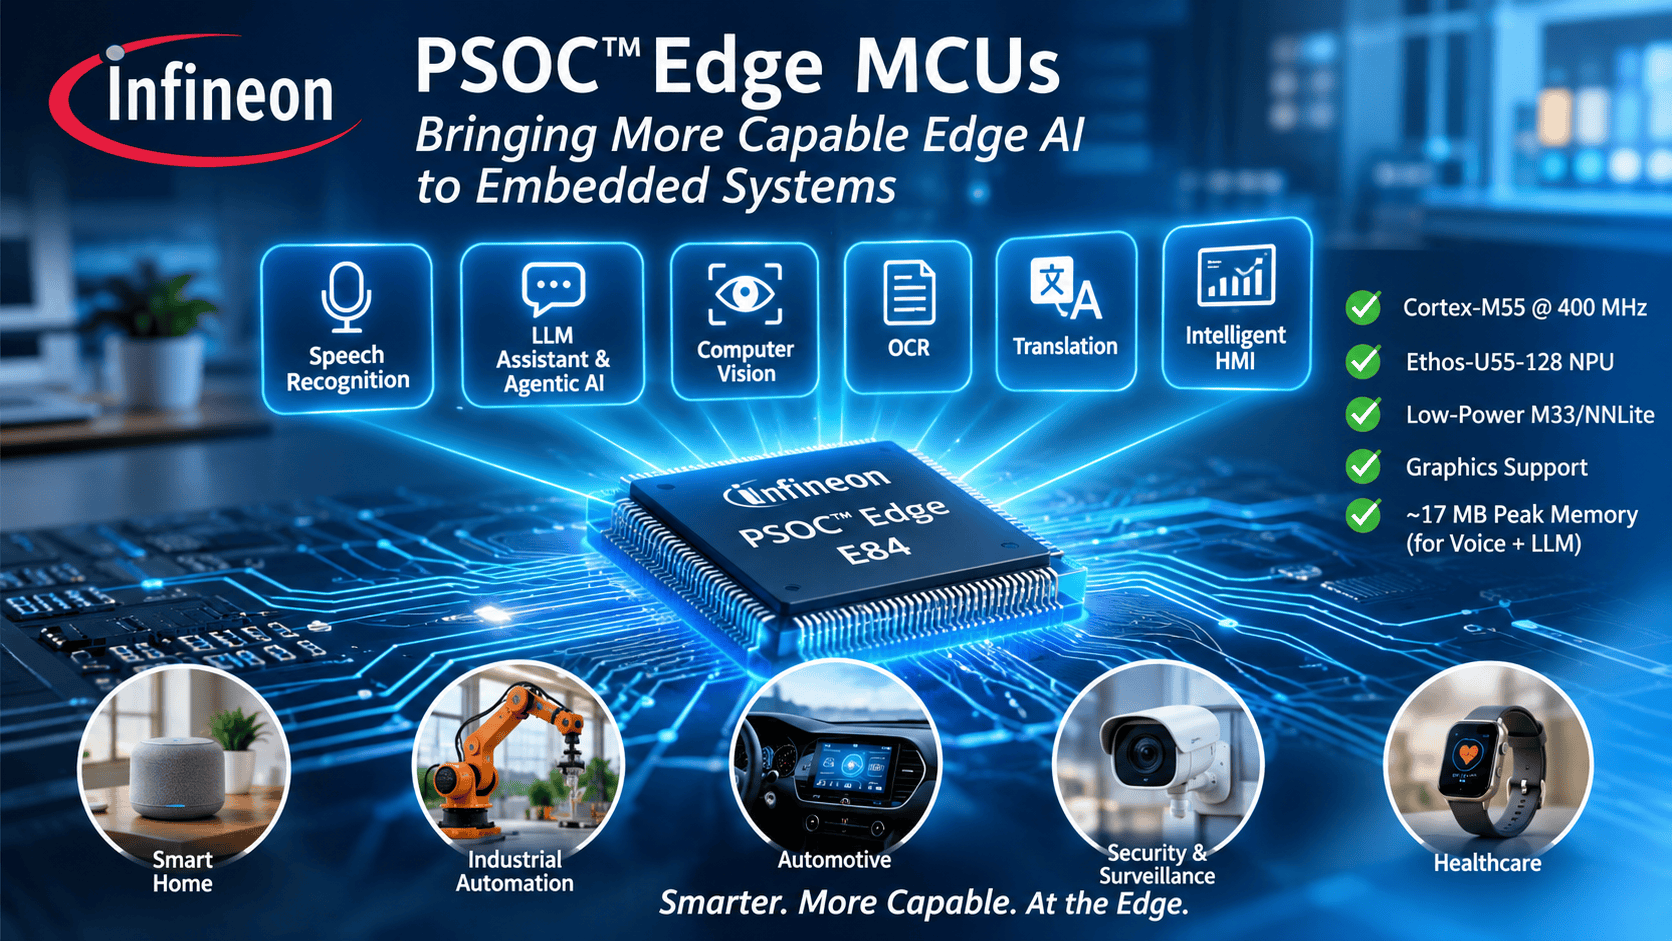
Infineon PSOC Edge MCUs bring more capable AI processing to embedded devices, supporting applications ranging from speech recognition and compact language models to computer vision and intelligent human-machine interfaces. Image generated by ChatGPT.
……………………………………………………………………………………………………………………………………………………………………………….
PSoC Edge: A Heterogeneous Architecture for Embedded AI:
The PSoC Edge family is designed to combine high-performance AI inference with low-power, always-on processing. Its multi-domain architecture enables different processors and neural accelerators to handle workloads according to their performance and power requirements.
The PSOC Edge E84, used in the EWNA demonstration, incorporates:
- Arm Cortex-M55: A 400 MHz processor with Helium DSP extensions for signal processing and machine-learning workloads.
- Arm Ethos-U55-128 NPU: A dedicated neural processing unit for accelerating neural-network inference.
- Arm Cortex-M33: A separate, lower-power processor operating at up to 200 MHz.
- Infineon NNLite: A dedicated neural-network accelerator associated with the Cortex-M33 domain for low-power, always-on AI applications.
The E84 also provides up to 6 MB of system SRAM, 512 KB of resistive RAM (RRAM), external-memory interfaces and a low-power 2.5D graphics processor. Its display controller supports MIPI-DSI/DBI interfaces and resolutions up to 1024 × 768. Multiple digital audio interfaces support multi-microphone applications, including far-field voice interaction. Connectivity includes USB, 10/100 Ethernet, CAN-FD, SPI, UART, I2C, I3C and I2S.
This heterogeneous architecture provides two important processing domains:
- High-performance domain: The Cortex-M55 and Ethos-U55 combination handles more computationally demanding AI workloads, including full voice inference and more complex neural-network applications.
- Low-power domain: The Cortex-M33 and NNLite combination supports continuous, energy-efficient processing, including wake-word detection and other always-on machine-learning functions.
This arrangement is particularly useful for intelligent voice interfaces. The lower-power domain can monitor for an activation phrase without requiring the higher-performance processing resources to remain continuously active. Once activated, more demanding speech-recognition and language-model workloads can use the higher-performance domain.
The result is a flexible MCU architecture that combines conventional embedded processing with multiple levels of AI acceleration.
PSOC Edge family: Different configurations for different AI workloads:
Not all PSOC Edge devices offer identical AI and HMI capabilities. Infineon’s product comparison identifies the following differences:
| MCU | AI acceleration | Voice AI | Vision AI | Graphics |
|---|---|---|---|---|
| E84 | NNLite + Ethos-U55-128 | Full voice inference | Presence, gesture, motion | Yes |
| E83 | NNLite + Ethos-U55-128 | Full voice inference | Presence, gesture, motion | No |
| E82 | NNLite | Wake-word detection | Not listed | Yes |
| E81 | NNLite | Wake-word detection | Not listed | No |
Source: Infineon data sheets
The E84 offers the broadest combination of the capabilities listed above, including full voice inference, vision functions and graphics. This differentiation is important when evaluating the family for embedded AI designs. The appropriate MCU depends on the workload, processing requirements, Human Machine Interface (HMI) complexity, memory resources and power budget.
………………………………………………………………………………………………………………………………………………………………
Infineon Demo At Embedded World North America (EWNA) 2026:
At EWNA 2026 [September 22–24, 2026 in Anaheim CA], Infineon demonstrated an on-device Edge AI application using the PSOC™ Edge E84. The demonstration integrated a 6.5-million-parameter Nexus Ember task-oriented language model, with a 512-token context window, and a 16-million-parameter FastConformer streaming speech-to-text engine, together with graphics support. The application demonstrated local speech recognition and language-model inference without requiring cloud processing for those functions.
Of particular interest, Infineon supplied detailed measurements of the implementation, including model size, memory utilization, language-model generation speed, speech-recognition latency and power consumption. These provide useful engineering data for evaluating the feasibility of executing compact language models and multiple AI workloads on MCU-class hardware.
Its reported measurements—18 generated tokens per second, a 0.36-second language-model time to first token, approximately 17 MB peak memory usage for the 16M voice-control pipeline excluding graphics buffers, and 92.6 mW active SoC power—provide useful evidence of what is achievable with a compact MCU-based AI implementation.
The broader application opportunities include advanced speech recognition, interactive voice interfaces, task-oriented language models, selected translation workloads, computer vision, gesture recognition, OCR and industrial monitoring.
These MCUs will not replace application processors (see Addendum below), embedded Linux systems or cloud-based AI infrastructure for large language models and computationally intensive multimodal applications. Their significance is different: an expanding range of useful AI functions can now be performed locally on increasingly capable microcontroller platforms. For embedded-system designers, that can mean reduced dependence on cloud services, improved data privacy, lower communication requirements, faster interaction and potentially lower system cost and power consumption.
Paradigm Shift: Why Localized AI Execution Matters (Source: Google Gemini):
- Deterministic Latency & Reliability: By removing reliance on cellular, Wi-Fi, or cloud backends, critical applications suffer zero network dropouts (1:14). Latency drops to a deterministic sub-second window, which is vital for industrial machinery interfaces or responsive consumer electronics (0:11).
- Ironclad Data Privacy: Because processing happens entirely on the local silicon chip, sensitive voice data, visual captures, and text streams never leave the device boundary (0:25). This inherently complies with privacy frameworks and eliminates consumer data exposure risks.
- Drastic Power Savings: Transitioning an RF radio into high-throughput transmit mode to stream audio or video payload data to the cloud consumes significant energy. Offloading neural processing locally to a highly optimized NPU cuts total system energy consumption drastically, extending battery life and making “always-on” edge devices sustainable
Conclusions:
The important development is that Edge AI is no longer limited to narrowly defined TinyML inference. Infineon’s PSOC Edge family demonstrates how microcontrollers can increasingly support intelligent, voice-enabled, vision-aware and language-model-driven embedded applications.
The combination of heterogeneous processing, neural-network acceleration, graphics and memory resources enables a broader range of applications, including conversational interfaces, speech recognition, computer vision, OCR, selected translation workloads and industrial monitoring. The E84 demonstration provides concrete evidence that compact language models and streaming speech recognition can operate together locally, with relatively low power consumption.
Although MCU-based Edge AI will not replace more powerful application processors or cloud-based AI for demanding workloads, it can reduce cloud dependence, improve privacy and responsiveness, and lower system costs for many embedded applications. The opportunity is to bring useful AI capabilities directly into devices that traditionally relied on much simpler embedded processing.
……………………………………………………………………………………………………………………………………………………………………..
Addendum:
Google Gemini suggests using dedicated Application Processors (MPUs) or Edge Accelerators for open ended AI at the edge.
To support more demanding, general-purpose generative AI at the edge applications than the Infineon PSoC Edge MCUs, designers will typically need to move beyond MCU architectures to application processors (MPUs) or dedicated AI accelerators with substantially greater memory capacity and bandwidth. Microcontrollers lack the extreme memory bandwidth and capacity (such as High Bandwidth Memory or large external LPDDR buses) required to execute unconstrained, open-ended generative text and vision models.
| Processor Category | Example Hardware | Generative AI Capabilities |
|---|---|---|
| High-End Edge NPU Modules | NVIDIA Jetson Orin Nano / NX | Runs 1B to 3B parameter models locally with fast token generation. Uses shared unified LPDDR5 VRAM to fit small LLMs (e.g., Llama 3.2 3B or Qwen 2.5 3B) entirely on the device. |
| Application Processors | NXP i.MX 95 / STMicroelectronics STM32MP2 | Can handle highly optimized, tiny text models or text-to-speech tasks, but constrained by memory bandwidth. Ideal for structured, deterministic multi-modal smart interfaces rather than open-ended text gen. |
| Dedicated AI Accelerators | Hailo-8 / Raspberry Pi AI Kit | Excellent for offloading complex vision and neural network computations if paired with a capable host CPU. Designed for highly power-efficient mathematical processing (up to 26 TOPS) but lacks on-chip external DRAM for massive LLM weight pools. |
| Product | Official vendor hyperlink |
|---|---|
| NVIDIA Jetson Orin Nano / NX | NVIDIA Jetson Modules |
| NXP i.MX 95 | NXP i.MX 95 Applications Processor |
| STMicroelectronics STM32MP2 | STMicroelectronics STM32MP2 Series |
| Hailo-8 | Hailo AI Products |
| Raspberry Pi AI Kit | Raspberry Pi AI Kit |
Note: The original Raspberry Pi AI Kit uses the Hailo-8L (13 TOPS), not the Hailo-8 (26 TOPS) in the first “Overview of Edge AI Hardware Tiers.. Raspberry Pi’s official documentation confirms this distinction.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………………..
Architectural Deep Dive: Why These Distinctions Matter:
The Memory Wall Constraint: Single-stream token generation for language models is heavily throttled by memory bandwidth rather than raw TOPS compute. This is why High-End NPU Modules with high-throughput unified memory architectures excel at localized LLM tasks over general-purpose application processors.
Coprocessor Offloading: Dedicated accelerators like the Hailo-8 require a powerful host CPU (like an ARM Cortex-A) because the accelerator manages the parallelized weight matrices for neural layers while the host handles system OS routines, memory routing, and basic context token tracking.
……………………………………………………………………………………………………………………………………………………………………………………………………………………..
References:
https://www.infineon.com/products/microcontroller/32-bit-psoc-arm-cortex/32-bit-psoc-edge-arm
Blaize and Winmate Forge Strategic Partnership to Accelerate Edge AI Integration in Ruggedized Systems
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Is the “far edge” a bridge to far to cross for AI inferencing? What about “Distributed AI Grids”?
T-Mobile’s Strategy of Deploying Multi-Vendor AI-RAN on “Kinetic Edge” using AWS Pillars
Will “AI at the Edge” transform telecom or be yet another telco monetization failure?
Custom AI Silicon: OpenAI, Anthropic, Hyperscalers, Huawei and the Battle with Nvidia, AMD and Broadcom
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
Custom AI Silicon: OpenAI, Anthropic, Hyperscalers, Huawei and the Battle with Nvidia, AMD and Broadcom
Disclaimer: ChatGPT was used extensively to write this article.
Executive Summary:
Custom AI silicon is entering a new phase. Google, Amazon, Microsoft and Meta have established proprietary accelerator programs, while OpenAI has introduced its first custom inference chip, Jalapeño, and Anthropic is assembling an in-house chip-design team.
These developments extend the industry trend examined in earlier IEEE Techblog articles, Custom AI Chips: Powering the Next Wave of Intelligent Computing and Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies (see References for more).
The important new development is the entry of AI-model developers themselves into chip architecture and design. OpenAI is attempting to optimize hardware around the demands of its models and inference services, while Anthropic plans to pursue closer hardware-software co-design for Claude.
The competitive consequences extend beyond Nvidia and AMD. Broadcom and Marvell stand to benefit from demand for custom application-specific integrated circuits (ASICs), while Intel and specialized accelerator developers pursue alternative architectures.
The central question is whether custom silicon can deliver a sustained advantage in cost per AI token, energy efficiency and latency without sacrificing the flexibility and software ecosystem of merchant GPUs.
OpenAI – From Chip Partnership to Working Silicon:
OpenAI’s October 2025 agreement with Broadcom established a multiyear $10 billion custom-chip program for 10 gigawatts of OpenAI-designed accelerators and associated networking systems. Since then, the project has advanced from a development partnership to working silicon. On June 24, 2026, the companies unveiled Jalapeño, OpenAI’s first custom AI inference accelerator, designed specifically for large language models (LLMs). OpenAI designed the architecture, while Broadcom provides silicon implementation and networking expertise, and Celestica supports board and rack integration. TSMC will manufacture the chips. Engineering samples are running machine-learning workloads in the laboratory at targeted operating frequency and power. Initial deployment is planned for the end of 2026, followed by expansion over multiple generations.
In August 2026, OpenAI published initial benchmark results claiming substantial performance-per-watt and latency advantages over competing systems. These are company-reported results, not yet independent proof of a sustained production-scale advantage over Nvidia’s latest accelerators. Jalapeño is optimized for inference rather than general-purpose AI training, and OpenAI’s immediate priority is to meet its own rapidly growing computing demand.
The strategic significance is that OpenAI is extending its capabilities beyond AI models and software into custom hardware. By co-designing the chip, software kernels, memory movement, networking and serving systems, it aims to lower inference costs and improve responsiveness across ChatGPT, Codex and its API services. For Broadcom, the partnership reinforces the opportunity to supply custom silicon and networking technology to major AI developers without having to compete directly with Nvidia across the entire GPU market.
The distinction is significant: this is no longer simply a plan to develop proprietary silicon. OpenAI reported that engineering samples were running machine-learning workloads in its laboratories at production-target frequency and power.
Jalapeño is designed around large language model (LLM) inference rather than adapting a general-purpose GPU architecture. Its design emphasizes minimizing data movement and balancing compute, memory and networking resources. These considerations become increasingly important when serving interactive AI applications and agents that must generate responses quickly and execute multiple steps.
OpenAI designed the architecture, while Broadcom contributes silicon implementation and networking technology, and Celestica supports board and rack integration. OpenAI plans an initial deployment in small volumes near the end of 2026, with more substantial deployment expected in 2027.
The business rationale is straightforward. OpenAI operates ChatGPT, Codex and its API services at considerable computing scale. Even relatively modest improvements in inference efficiency could translate into meaningful savings if deployed across a large installed base.
However, Jalapeño’s initial benchmarks do not establish that it will outperform Nvidia’s latest systems across all workloads. Nor do they yet demonstrate its production-scale cost advantage. The relevant comparison must include complete systems, utilization, software development, power, cooling and operating costs.
The critical test is whether Jalapeño can deliver better economics at production scale. OpenAI must demonstrate that its claimed efficiency gains translate into lower total costs per AI token after accounting for manufacturing, memory, networking, power, cooling, utilization and software engineering. The initial results are promising, but the competitive outcome remains to be established.
Sources: OpenAI’s Jalapeño announcement and August benchmark results.
Author’s Note: The claims about Jalapeño’s performance are explicitly attributed to OpenAI.
……………………………………………………………………………………………………………………………………………
Anthropic – Building an Internal Design Capability:
Anthropic announced in August 2026 that it was forming an internal chip-design team to develop hardware optimized for Claude. The initiative reflects the same strategic logic as OpenAI’s: understanding a model’s architecture, inference patterns and software stack can help guide the design of more efficient processors.
Anthropic is not starting from a position of hardware independence. It already uses accelerators from Nvidia, Google and Amazon, among others. Its planned custom-silicon effort is an additional element of a multivendor strategy, not evidence that it is abandoning external suppliers.
The distinction between the two AI developers is important. OpenAI has demonstrated working silicon and published initial benchmarks; Anthropic is building a design organization and has not announced a production-ready proprietary accelerator or deployment timetable.
Designing advanced chips also requires substantial capital, specialized engineering talent and access to manufacturing and packaging capacity. Anthropic must ultimately demonstrate that the benefits justify those investments.
Source: Reuters on Anthropic’s chip-design team.
……………………………………………………………………………………………………………………………………………………..
Hyperscalers: Established Programs, Different Economics:
The major hyperscalers have already developed proprietary accelerators, as discussed in our September article. Their competitive positions differ according to the maturity of their hardware programs, their internal workloads and their ability to sell or rent computing capacity to external customers.
| Company | Custom silicon | Strategic emphasis |
|---|---|---|
| Tensor Processing Units (TPUs) | Training and inference, including external cloud customers | |
| Amazon | Trainium and Inferentia | AWS computing economics and customer choice |
| Microsoft | Maia | Azure AI inference and internal services |
| Meta | MTIA | Recommendation systems and generative AI inference |
| OpenAI | Jalapeño | LLM inference optimized around its models and serving software |
| Anthropic | In-house design initiative | Future hardware-software co-design for Claude |
Google’s position is particularly notable because it has an established TPU ecosystem and sells access to its accelerators beyond its own operations. Amazon similarly offers Trainium through AWS, giving customers an alternative to Nvidia-based infrastructure.
Microsoft and Meta are expanding their own programs, although proprietary silicon does not eliminate their need for merchant GPUs. Different workloads, development schedules and capacity requirements favor a mix of processors.
The broader point is that these companies are not necessarily trying to replace Nvidia everywhere. They are attempting to optimize selected workloads, diversify supply and improve the economics of operating AI infrastructure.
……………………………………………………………………………………………………………………………………………….
Huawei: Building an Alternative AI Silicon and Networking Ecosystem:
Huawei represents a different competitive challenge to NVIDIA, AMD and U.S. hyperscalers. Through its Ascend AI processors, HiSilicon semiconductor-design subsidiary, CANN software stack and high-speed interconnect technologies, Huawei is developing an integrated AI computing platform intended to reduce China’s dependence on foreign chips and software.
Huawei’s strategy extends beyond individual accelerators to cluster-scale infrastructure. Its September 2026 roadmap includes the Ascend 960DT, planned for the first quarter of 2027, and Ascend 960PR, planned for the third quarter 2026, followed by Ascend 970 and 980 generations in 2028 and 2029. Its UnifiedBus interconnect architecture is designed to connect processors, memory and storage across tightly coupled SuperPoD systems and larger AI clusters, potentially scaling to hundreds of thousands or even one million neural processing units (NPUs), according to Huawei’s announced architecture. These are roadmap and design targets, not independently verified production-scale performance results.
Manufacturing constraints: Huawei has also reported insufficient production capacity to meet domestic demand. That is a practical deployment constraint beyond the chip-design and software challenges.
Huawei’s principal challenge is translating this ambitious system architecture into competitive real-world performance. Advanced-chip manufacturing access, high-bandwidth memory (HBM) supply, power efficiency and the maturity of its CANN software ecosystem remain important constraints. NVIDIA benefits from a substantial lead in accelerator performance and a deeply established CUDA ecosystem, while AMD and hyperscalers pursue their own hardware and software strategies.
Nevertheless, Huawei is strategically significant because it combines AI silicon, interconnects, networking, storage and software within a broader computing and telecommunications portfolio. Its progress could reshape China’s domestic AI infrastructure market even if its chips do not match NVIDIA’s leading products on a per-accelerator basis. The competitive comparison must therefore consider total cluster performance, system availability, software compatibility, power consumption and cost—not chip specifications alone.
Huawei’s roadmap underscores a broader point: the AI-silicon competition is not simply a contest among chip designers. It is also a race to build complete, scalable computing platforms with the networking and software required to make thousands of accelerators work efficiently together.
Other AI Developers and Specialized Chip Companies:
The custom-silicon movement extends beyond OpenAI and Anthropic, but announced interest should not be confused with established production programs.
Alibaba’s T-Head and Baidu’s Kunlunxin are examples of Chinese semiconductor-development efforts associated with domestic AI and cloud infrastructure. Their importance includes reducing reliance on foreign suppliers amid restrictions on advanced semiconductor exports.
Among smaller AI-model developers, the strategic choices vary. A company can optimize models, compilers and kernels for existing processors without designing a chip of its own. Developing proprietary silicon becomes more attractive when workloads are large and predictable enough to justify substantial upfront investment.
Specialist chip companies pursue different alternatives to conventional GPUs:
- Cerebras uses a wafer-scale architecture designed to place substantial computing resources on a single silicon wafer.
- Groq developed a specialized architecture targeting low-latency inference and has entered a broader ecosystem that includes partnerships and technology integration.
- Intel offers its Gaudi accelerator family as an alternative AI-computing platform.
These vendors compete through different combinations of architecture, software, throughput, latency and system economics. They should not be treated as interchangeable with hyperscaler ASICs or general-purpose merchant GPUs.
……………………………………………………………………………………………………………………………………………..
Image from ChatGPT:
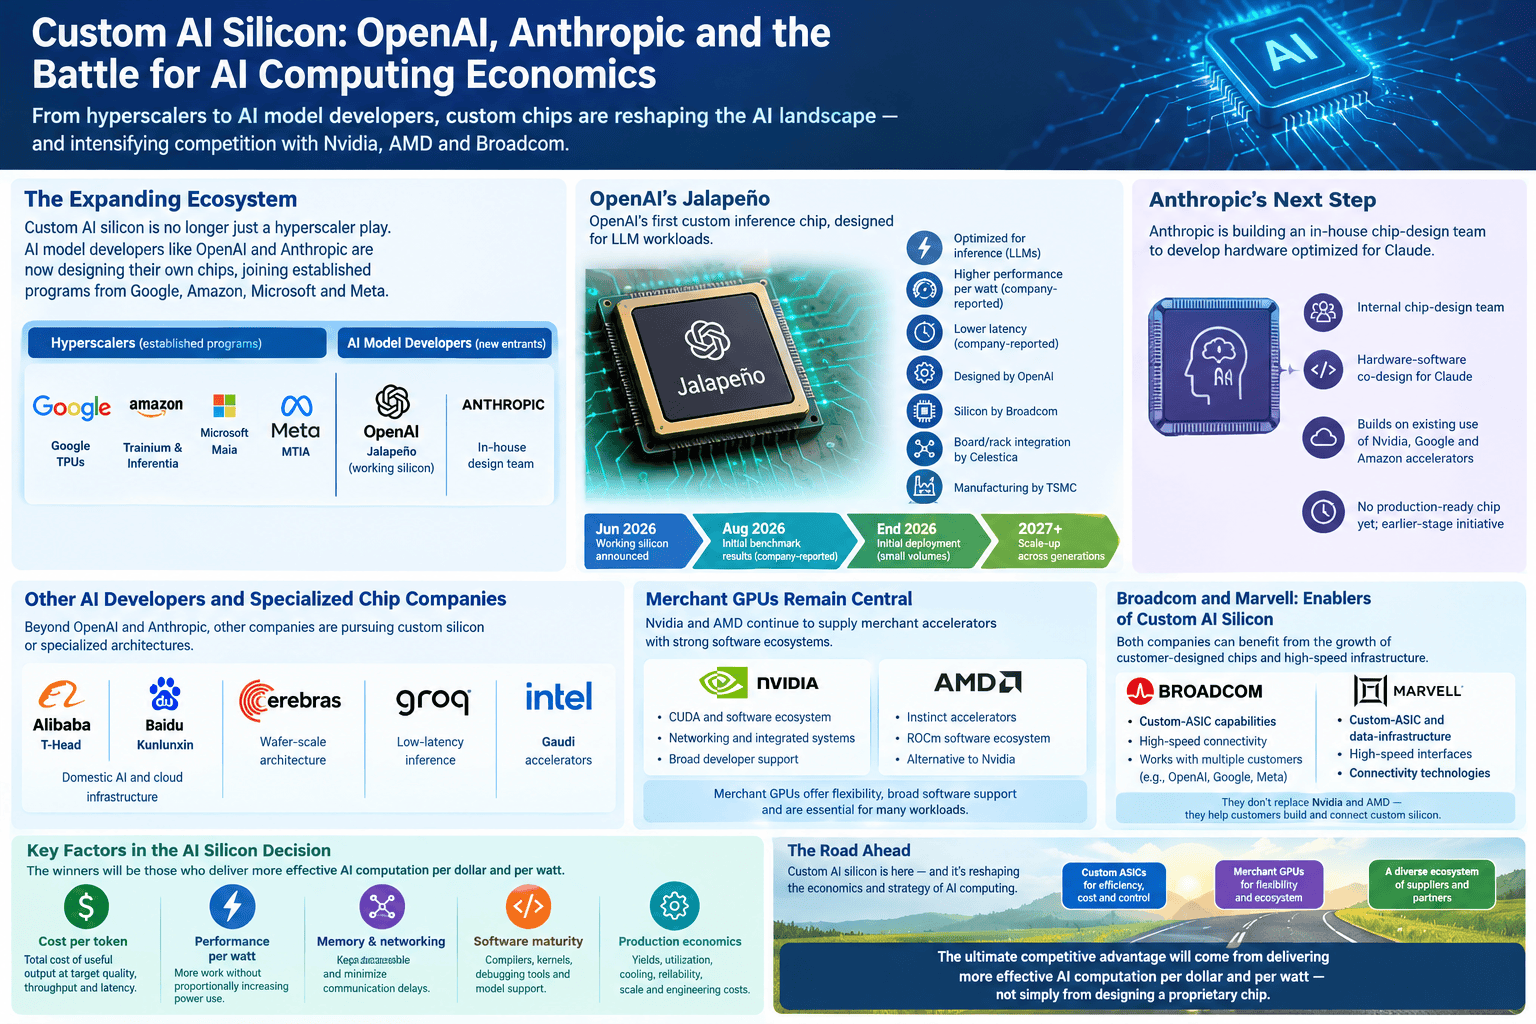
…………………………………………………………………………………………………………………………………………………………………………
Merchant Market AI Accelerator Chips from Nvidia and AMD :
Nvidia’s competitive advantage extends well beyond its GPU hardware. CUDA, optimized libraries, developer tools, networking and integrated rack-scale systems make its platform difficult to displace. Customers also benefit from a broad software ecosystem and the ability to use the same general platform across many workloads.
Nvidia’s vulnerability is that large AI operators have incentives to reduce costs and dependence on a single supplier. Custom ASICs can be attractive when workloads are sufficiently stable and deployment volumes justify specialized engineering.
AMD provides a second major merchant-GPU platform through its Instinct accelerators and ROCm software ecosystem. It offers customers another source of advanced computing capacity and an alternative to Nvidia’s platform.
AMD faces the challenge of expanding software adoption and competing against Nvidia’s established ecosystem. Nevertheless, the availability of multiple accelerator suppliers is strategically valuable to cloud providers and AI developers.
Neither company is likely to be displaced solely because a few major customers introduce proprietary chips. Merchant GPUs remain useful for new models, changing workloads and applications for which custom silicon is not yet economically justified.
Broadcom and Marvell – Beneficiaries of the Custom-ASIC Trend:
Broadcom occupies a particularly important position because it can benefit from the growth of customer-designed silicon without relying exclusively on sales of a proprietary general-purpose AI accelerator.
Its custom-ASIC capabilities, high-speed connectivity and networking products support the development of customer-specific AI systems. Its work with OpenAI and Meta illustrates how chip designers can retain control of their architectures while relying on semiconductor partners for implementation and infrastructure.
Marvell offers another set of custom-ASIC and data-infrastructure capabilities, including high-speed interfaces and connectivity technologies. It can benefit as companies develop specialized processors and build the systems needed to connect them.
The distinction from Nvidia and AMD is fundamental:
- Nvidia and AMD sell merchant accelerators to a broad customer base.
- Broadcom and Marvell help customers develop customized silicon and the associated data infrastructure.
- Hyperscalers and AI developers use their knowledge of workloads to decide where proprietary hardware can improve performance or economics.
These roles can overlap. Broadcom’s custom-chip business, for example, can benefit from a customer moving some workloads away from merchant GPUs. But custom silicon does not eliminate the need for advanced manufacturing, memory, packaging, networking or other semiconductor suppliers.
…………………………………………………………………………………………………………………………………………
What Will Determine the Winners?
The decisive metric is not peak computing performance alone. AI operators need to know how much useful work a complete system can deliver at an acceptable cost and latency.
Five factors will be especially important:
- Cost per token: Total cost of generating useful AI output at specified quality, throughput and response time.
- Performance per watt: The ability to serve more workloads without proportionally increasing electricity consumption.
- Memory and networking: The ability to keep model data accessible and minimize communication delays.
- Software maturity: The availability of compilers, optimized kernels, debugging tools and support for changing models.
- Production economics: Manufacturing yields, system utilization, cooling, reliability, deployment scale and engineering costs.
Custom ASICs are most compelling when a company has large, repeatable workloads and can optimize the model, software and hardware together. Merchant GPUs remain attractive when flexibility, rapid deployment and broad software support outweigh the potential benefits of specialization.
Power availability is an additional constraint. A more efficient processor can increase the useful computing capacity delivered by a given data-center power budget, although total electricity consumption may still rise as AI demand expands.
………………………………………………………………………………………………………………………………………
Conclusions:
Custom AI silicon is becoming a more important part of the industry’s computing strategy. The entry of OpenAI and Anthropic into chip design extends a trend already established by Google, Amazon, Microsoft and Meta.
OpenAI’s Jalapeño is a meaningful milestone because it has progressed from a partnership announcement to working silicon and published initial performance results. Anthropic’s initiative remains at an earlier stage. Both illustrate the growing interest in co-designing AI models, software and hardware.
The market is likely to remain heterogeneous. Nvidia and AMD will continue supplying merchant accelerators, while Broadcom and Marvell can benefit from demand for customer-specific silicon and high-speed networking. Specialized architectures will compete for workloads where their performance and cost advantages are compelling.
The ultimate competitive advantage will come from delivering more effective AI computation per dollar and per watt—not simply from designing a proprietary chip.
……………………………………………………………………………………………………………………………………
References:
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
Custom AI Chips: Powering the next wave of Intelligent Computing
OpenAI and Broadcom in $10B deal to make custom AI chips
Meta’s “Iris” AI Chip for MTIA: Implications for Telecom-Grade Optical Networking, DCI and High Capacity Ethernet Fabrics
2026 OCP Summit: Full-Stack AI Networking Silicon from Nvidia/Cisco and Broadcom; Ethernet vs InfiniBand Interconnects
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Custom AI Silicon: OpenAI, Anthropic, Hyperscalers and the Battle with Nvidia, AMD and Broadcom
OpenAI, Anthropic, and Their Hyperscaler Partners: Huge Financial Risks and Open-Weight Competition
Hyperscaler AI Revenue Hurdle:
In an analysis released last month, Jared Bernstein estimated that the big-spending hyperscalers need $13-$18 trillion in revenues over the next 10 years to justify their AI-infrastructure investments. This is, by definition, speculative work, requiring judgment calls on technical aspects of the analysis, such as discount rates, depreciation schedules, taxes, and revenue paths. So, we were happy to see that several other analysts and researchers have, independently, been working on the same problem. Callum Williams of the Economist, whose produced his own excellent analysis on the topic, put together a comparison of these different estimates, including theirs.
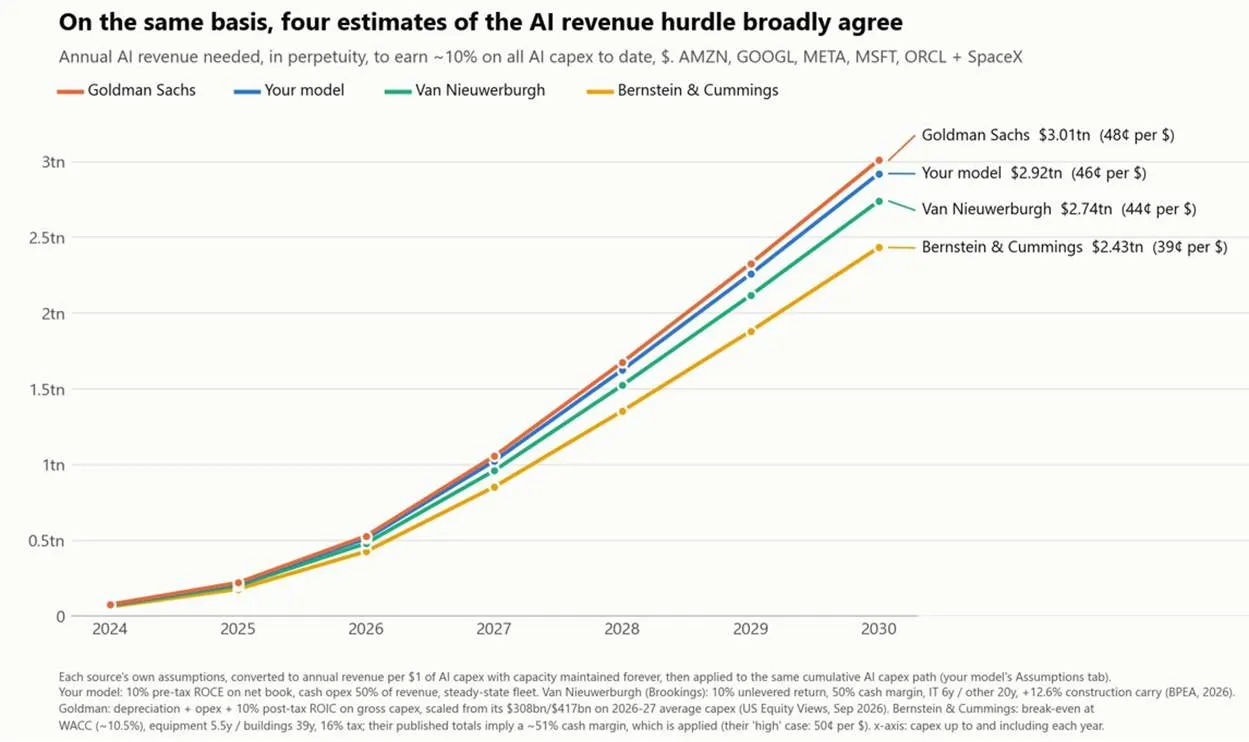
What’s striking is how close each of the estimates are: firms will need between $2.4-3.0 trillion in annual incremental AI revenues by 2030 to justify their big spending; this is about 5-6 times more than they are currently making under the most general possible assumptions. They may clear that hurdle. Ryan Cummings told Axios:
“Can all these people eventually turn this into something profitable? I think they will…I’m not sure who’s going to do that, but I do think there will be trillions of dollars of profits that are up for grabs in the future, but just not in this super-accelerated timeline that is required to justify the investments.”
Hyperscaler Debt & Capex Projections (2026–2027):
- 2026 Debt Issuance: Projected between $220 billion and $250+ billion for major US hyperscalers (Alphabet / Google, Amazon, Meta, Microsoft, and Oracle), with broader AI-related market debt reaching up to $570 billion.
- 2027 Forecast: Goldman Sachs projects direct hyperscaler debt issuance to nearly double to around $400 billion (Jeff Pu estimates $419 billion) as companies finance over a third of their infrastructure needs.
- Aggregate Capex: Combined capital expenditures are expected to hit roughly $940 billion in 2026 and scale past $1.3 trillion in 2027.
- Market Share: Hyperscaler investment-grade bond sales have jumped from roughly 2% of total US supply (2022–2024) to roughly 9% in 2026.
- Credit Impact: Credit spreads on a 10-year hyperscaler credit basket have widened from historical 40–75bp ranges toward 90bp+, driven by leverage concerns.
- Cash Flow Outlook: S&P Global Ratings expects all major hyperscalers to run negative free operating cash flow through 2026 and 2027, with a cash-flow inflection point not projected until 2028–2029.
………………………………………………………………………………………………………………………………………………………………………………………………………..
Hidden Risks for the AI Lab Giants:
Anthropic and OpenAI belong to the group of frontier AI model developers commonly known as “the AI labs.” Their financial performance provides a more direct view of AI business economics than that of the hyperscalers discussed above. Unlike diversified technology companies, whose established businesses can offset AI-related spending and complicate profitability analysis, these firms concentrate their operations on developing and commercializing AI. Their results therefore offer a clearer indication of whether revenue from AI products and services can support the costs of model development, computing infrastructure, and commercialization.
Public disclosures about these privately held companies are consequently valuable. Recent reporting on Anthropic and the Financial Times (FT) [paywall] June 16, 2026 report on OpenAI [1.] provide insight into their revenues, spending, and losses. OpenAI’s reported results also illustrate the importance of distinguishing operating costs from noncash accounting charges when assessing the economics of its underlying business. Substantial losses do not, by themselves, establish that AI is a financial bubble. They do, however, reinforce concerns about whether revenue growth can justify the sector’s spending commitments and valuations.
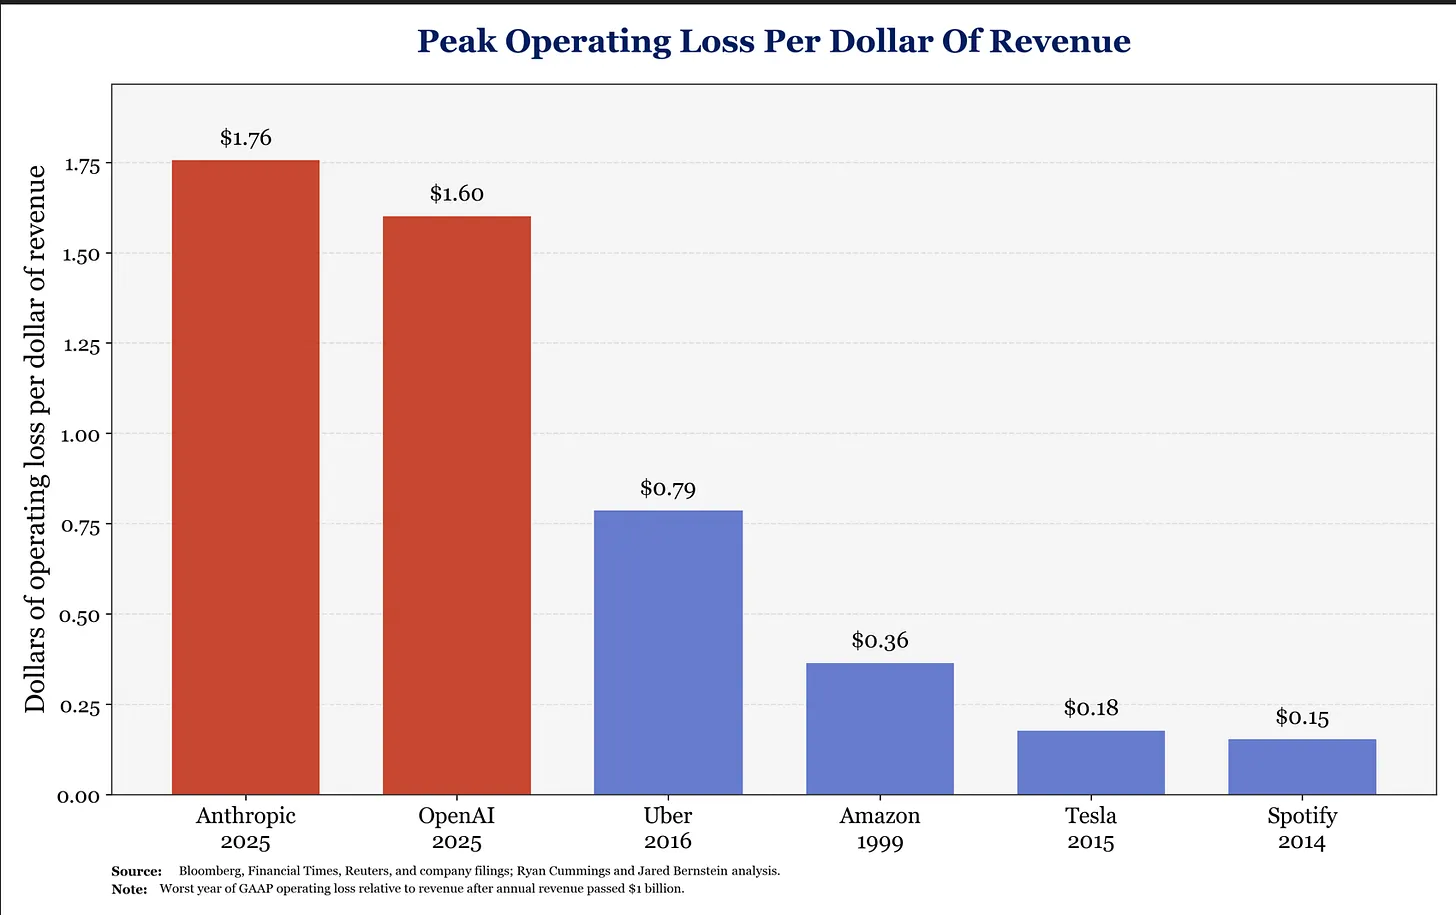
Note 1. The referenced June 16, 2026, FT report covers OpenAI’s 2025 results and distinguishes its approximately $39 billion net loss from losses of approximately $8 billion after excluding specified noncash items. It does not directly substantiate the stated $1.60 loss per revenue dollar.
AI proponents point to Amazon, Uber, and Tesla as examples of companies that sustained years of losses before becoming profitable. The relevant comparison, however, is not simply whether a company loses money, but the magnitude of those losses relative to revenue and its prospects for improving margins. As shown in the chart below, Anthropic and OpenAI reportedly lost more than $1.76 and $1.60, respectively, for every dollar of revenue in the year examined—more than twice Uber’s loss-to-revenue ratio in 2016 and more than five times Amazon’s in 1999. These comparisons underscore the scale of the challenge: rapid revenue growth must ultimately translate into a sustainable cost structure, rather than continued dependence on external financing.
Underestimated Competition:
Despite their prominence in the AI industry, the frontier-model developers face questions about whether their competitive position can support sustained profitability. They depend heavily on external providers of computing infrastructure, and their ability to convert enterprise adoption into sufficient revenue and margins remains uncertain. Customers are also scrutinizing AI costs more closely, particularly as resource-intensive AI agents increase computing requirements and operating expenses. Efforts to control those costs could constrain the labs’ revenue growth even as AI usage expands.economist
Competition from open-weight models adds to that pressure. AT&T, for example, reported increasing the share of its AI use served by open models from 20 percent in May to 40 percent by September, with savings of up to 80 percent compared with earlier in the year. Such models can offer enterprises greater deployment flexibility and reduce reliance on proprietary-model providers. Although model weights may be available without charge, deployment, inference, integration, and ongoing operation are not cost-free. The competitive issue for OpenAI and Anthropic is therefore whether their proprietary offerings deliver enough additional value to justify a price premium.
The AI labs also lack the diversified earnings base available to hyperscalers. Alphabet, for example, can draw on its established advertising business to support investments in Google DeepMind, custom processors, and data centers. OpenAI and Anthropic have no comparable non-AI profit pool. Until their AI businesses generate sufficient cash flow, they remain dependent on external capital to finance expansion and absorb losses—a funding model whose sustainability depends on investor confidence as well as technical progress.
……………………………………………………………………………………………………………………………………………………………………
| Dimension | Proprietary AI Labs (OpenAI / Anthropic) | Cloud Hyperscalers (Google / Microsoft / AWS) | Open-Weight Alternatives (Meta / Enterprise In-House) |
|---|---|---|---|
| Financial Engine | Purely AI-dependent; high loss-to-revenue ratios. | Diversified profit pools (Ads, Cloud, SaaS). | Subsidized by core business (e.g., Meta’s ad network). |
| Pricing Leverage | High premium; under constant pressure to justify value. | Tied to broader ecosystem infrastructure and compute sales. | Zero licensing costs; infrastructure/deployment costs only. |
| Strategic Vulnerability | High infrastructure dependence and lack of safety cushion. | Massive aggregate ROI requirements to justify $T infrastructure bets. | Cost of long-term deployment, fine-tuning, and specialized engineering. |

………………………………………………………………………………………………………………………………………………………………………………………
References:
https://econjared.substack.com/p/a-budding-consensus-on-ai-revenues
https://econjared.substack.com/p/ai-companies-are-in-a-race-against
AI Debt Wave Implications: Higher interest rates with enormous AI sales required for ROI
Broadcom lending Anthropic up to $42 billion in yet another AI circular financing deal
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Deutsche Telekom: Device-to-Cloud AI Traffic Won’t Force RAN Upgrades or Increase CAPEX
Introduction:
Deutsche Telekom is in the process of “upgrading mid-range plans,” according to Dhananjay Mirchandani, DT’s senior VP for group controlling and the group’s next CFO from May 1, 2027. “I cannot recall a single conversation in which Alex Jenbar [CTO of Telekom Deutschland] … or somebody else approached us and said, ‘in addition to whatever we currently have on our roadmaps for RAN modernization, that there is an incremental requirement for an investment to be able to prepare ourselves for additional uplink/AI-related traffic,'” he said. “[That’s] just to give you a sense of the degree of confidence we have in terms of our own capex planning, specifically related to mobile network capacity,” he added.
His assessment on medium-term mobile capacity is bound to be sobering for its radio access network (RAN) vendors in Germany: Ericsson, Huawei and Nokia.
The rise of agentic and physical AI could upend decades of mobile network design that dedicates most bandwidth to download speeds (i.e., downlink) and much less to the data channels for uploads (i.e., uplink). It’s not certain how or when traffic patterns will change in a big way, but telcos are talking about preparing for a wave of AI-fueled traffic coming from smartphones, smart glasses or robots.
The Reality Check – No Incremental RAN Capex:
During an investor event, financial analysts directly pressed Deutsche Telekom’s incoming CFO, Srinivas Mirchandani, on whether capital intensity would escalate after 2027 to handle the upstream traffic generated by physical AI, wearables, and smartphone-based LLM queries.
• The Stand: Mirchandani honestly noted that he could not recall a single internal conversation where the CTO of Telekom Deutschland (Alex Jenbar) requested incremental investment beyond their existing radio access network (RAN) modernization roadmaps to handle AI uplink traffic.
• The Baseline Numbers: DT’s long-term guidance (established at its 2024 Capital Markets Day) mandates that capital spending outside the U.S. and spectrum will sit at 21% of service revenue by 2027. While DT is trading slightly above that now, it is entirely due to heavy fiber-optic rollouts in Germany, not mobile radio expansions.
| Attribute | Deutsche Telekom (Europe Group) | T-Mobile US |
|---|---|---|
| Capex Stance | Rigid cap on mobile intensity; excess savings diverted strictly to German landline fiber infrastructure. | Confirmed network architecture expansion funded via standardized 5G-Advanced cycles. |
| AI Traffic Philosophy | Believes traffic peaks are manageable within existing, scheduled modernization roadmaps. | Views the network explicitly as the “connective tissue for physical AI and AI wearables.” |
| Uplink Solutions | Delaying heavy structural changes; emphasizing spectrum efficiency under legacy boundaries. | Implementing Uplink Carrier Aggregation, Uplink MIMO, and Transmit Switching under 5G-Advanced. |
- Delaying Capex via Software: Panelists from across the telco ecosystem—including Turkcell and Deutsche Telekom’s own group partnering division—noted that AI is actually delaying capex cycles rather than accelerating them. Operators are deploying AI algorithms inside the radio access network to optimize power consumption, conduct predictive capacity planning, and boost edge throughput. In short: AI software is making existing hardware last longer.
- The Opex ROI Conundrum: Telcos are seeing immediate financial returns from “AI for the network” (e.g., DT projects €2.5 billion in cumulative cost savings by 2030 through AI automation). However, the business model for a “network for AI”—where consumers or enterprise clients pay a premium for high-speed, low-latency uplink to feed remote LLMs—remains entirely unproven.
- The 6G Boundary Wall: Based on this author’s carrier checks, most Tier-1 network operators now view massive, structural upstream re-architecting as a “6G-era investment narrative” rather than an immediate 5G sub-6GHz demand. Until dedicated enterprise use cases validate moving further up the value chain, hardware vendors will have to wait for a significant revenue lift from device-to-cloud AI traffic.

Source: Deutsche Telekom, Photo: Norbert Ittermann
…………………………………………………………………………………………………………….
Conclusions:
Deutsche Telekom (DT) indicates that rising device-to-cloud traffic volumes will not necessitate premature radio access network (RAN) upgrades. Technical analyses suggest that upcoming capacity demands driven by agentic AI may not immediately accelerate RAN capital expenditure.
DT does not see AI uplink traffic driving an incremental increase to its RAN capex plans in the medium term. DT is holding a rigid perimeter around its long-term financial guidance. By 2027, capital intensity (excluding the U.S. and spectrum) is strictly capped at 21% of service revenues. Excess capital is not being funneled into expanding cell site capacities for upstream AI traffic; it is being aggressively diverted toward landline fiber-optic buildouts in Germany.
-
- Uplink Carrier Aggregation (CA): Allows the network to combine multiple frequency bands (e.g., mid-band and low-band) exclusively for the upstream path. This maximizes the utilization of already-deployed spectrum without requiring operators to acquire or build new macro tower infrastructure.
- Uplink MIMO & Transmit Switching: Enhances data throughput from consumer AI wearables and smartphones back to the cloud by multiplying the data paths between the device and the tower antenna arrays. [
- Network Slicing: Under 5G SA, carriers can allocate a virtualized, highly efficient “slice” of the existing spectrum explicitly for low-latency AI queries. Slicing can improve resource allocation and protect selected service requirements, but it is not a substitute for sufficient uplink capacity. However, it isolates upstream data paths without needing incremental physical hardware upgrades.
References:
https://www.openranforum.com/home
AI-RAN and Agentic AI get real: Ericsson, Nokia, Verizon & other operators enter into a new network automation era
Cisco Execs: New “Network Supercycle” as Agentic AI Workloads Reshape Telecom Infrastructure
Cisco report: Agentic AI to reshape WAN traffic, AI inference will be ~25% of total traffic by 2035
Nokia’s AI Applications Study: “Physical AI” may require RAN redesign to support high‑volume, low‑latency uplink traffic
STL Partners webinar: Agentic AI needed for RAN autonomy & efficiency
The Financial Trap of Autonomous Networks: Scaling Agentic AI in the Telecom Core
AT&T’s 600 MHz Deployment with Ericsson: Turning Low-Band Spectrum Into Coverage and Uplink Capacity
SoftBank’s Transformer AI model boosts 5G AI-RAN uplink throughput by 30%, compared to a baseline model without AI
T‑Mobile achieves record 5G Uplink speed with 5G NR Dual Connectivity
Telstra achieves 340 Mbps uplink over 5G SA; Deploys dynamic network slicing from Ericsson
Finland’s Elisa, Ericsson and Qualcomm test uplink carrier aggregation on 5G SA network
AI-Native 6G RAN in Practice: Research and Validation Insights from 6G-MIRAI-HARMONY
By Shammi Thakur, Research Director, MarkNtel Advisors with Shazia Hasnie, PhD
Introduction:
A wireless AI model can perform well in the laboratory and still face a very different test once the radio environment changes. However, propagation conditions shift as users move. Traffic loads vary. Devices and carrier frequencies differ. Hardware introduces imperfections that a clean simulation may not capture. Distributed RANs add another complication because a decision made at one network element can affect conditions elsewhere.
A recent 5G trial shows why the distinction matters. In August 2026, SoftBank and Ericsson reported vendor results from a single commercial-network validation of an AI-native scheduler for link adaptation on SoftBank’s 5G network in Japan. The companies evaluated spectral efficiency, downlink user throughput, robustness, and stability under live network conditions. Average gains across the evaluated areas were about 10% for both spectral efficiency and downlink user throughput, while the highest reported gains reached approximately 25% and 50%, respectively. [1]
Commercial-network testing adds something a controlled simulation cannot: exposure to the variability that the system is expected to handle.
IEEE ComSoc TechBlog has already examined the move from AI as an overlay in 5G toward AI-native 6G, along with the developing IMT-2030 requirements and the role of AI in future RANs. [2][3] This article takes a narrower view. It examines how AI-native RAN functions can be trained, coordinated, and tested when wireless conditions, hardware, data, and network topology all change.
6G-MIRAI-HARMONY provides a concrete research setting for that question. The EU-Japan program connects realistic channel and hardware modeling, AI-based physical-layer functions, distributed coordination, AI-ready RAN architecture, and common approaches to data management, benchmarking, and validation. [4][5]
The Research Challenge for AI-Native 6G RAN:
Training data quietly becomes part of an AI model’s operating assumptions. Conventional wireless algorithms are generally built around assumptions that engineers can state explicitly. Machine learning adds another dependency: the examples used during training and evaluation influence what the model learns to recognize as normal.
A model can consequently look robust while remaining sensitive to conditions absent from its training environment.
Wireless conditions can change without the underlying network function changing. Users move through different propagation environments. Traffic loads rise and fall. Carrier frequencies and device characteristics vary. Hardware can introduce quantization, RF impairments, and converter limitations.
Distributed RANs add another layer. Measurements used by one function may come from elsewhere in the network. Beamforming and scheduling decisions can affect later decision cycles. Fronthaul capacity can determine how much information reaches another processing point before a coordinated action has to be taken.
An AI function therefore cannot always be judged as an isolated block. Network behavior around the function can influence the result just as much as the model architecture itself.
6G-MIRAI-HARMONY: Research Approach and Scope:
6G-MIRAI began on April 1, 2025, and runs for 36 months through March 2028 under Horizon Europe and the Smart Networks and Services Joint Undertaking. Grant Agreement 101192369 lists total project costs of €3,188,935 and an EU contribution of €2,979,966.50. Ericsson France is the coordinating organization. [5]
The European consortium includes Ericsson France, Fraunhofer, Telefónica, IS-Wireless, Sequans, Apple Technology Engineering, KU Leuven, CNIT, and the University of Pisa. The associated HARMONY work in Japan brings in organizations including the University of Tokyo, Kyocera, NEC Networks & System Integration, Shimizu, Tokyo University of Agriculture and Technology, and KDDI Research. [6]
Five Research and Technology Items connect the technical work:
- Realistic models and datasets covering channel, hardware, and measurement conditions.
- AI/ML for physical-layer components, including learning-based approaches to wireless functions.
- AI-driven coordination for distributed and cell-free deployments.
- AI-ready 6G-RAN architecture covering where intelligence, data, and computing are placed.
- Data management, testing, and validation for common scenarios and reproducible evaluation. [4][5]
The sequence matters because each part affects the next. Data conditions influence AI training. AI functions interact with distributed coordination. Architecture determines where models can run and what information they can access. Benchmarking and validation determine how the resulting measurements can be compared.
Realistic Models and AI-Based Physical-Layer Functions:
The wireless environment represented in an experiment becomes part of the AI system whether researchers intend it or not.
6G-MIRAI-HARMONY’s methodology combines link- and system-level modeling with analytical evaluation and later laboratory- or prototype-oriented validation. QuaDRiGa is identified for spatially and temporally consistent channel generation, while Sionna supports differentiable communication-system modeling. Measurement data and experimental RAN data provide additional routes toward less idealized evaluation conditions. [4]
Three parts of the modeling chain deserve particular attention:
- The channel: Propagation, mobility, and spatial variation determine the conditions presented to the model.
- The hardware: RF impairments, quantization, finite-resolution converters, and other non-idealities can alter physical-layer behavior.
- The data: Training and test datasets determine which situations the model encounters and which remain unseen.
Those conditions matter for functions such as channel estimation, CSI prediction and compression, neural receivers, precoding, power control, and link adaptation.
Independent research is addressing similar issues. A 2026 study of CNN-based hybrid precoding for cell-free massive MIMO evaluates imperfect CSI, phase noise, channel aging, molecular absorption, and transceiver hardware nonidealities in a THz simulation environment. The reported results include spectral-efficiency gains against several conventional approaches, while the study also measures the effect of individual hardware impairments on performance. [7]
Physical-layer intelligence therefore has to be tested against the radio conditions it is expected to encounter. An improvement under one channel or hardware assumption does not establish the same improvement under another.
Distributed Intelligence for Cell-Free Massive MIMO:
Distributed access points can work together, but the information needed to coordinate them is distributed as well. Beamforming decisions affect interference seen by other users. Scheduling changes the traffic mix entering later decision cycles. Power-control decisions can alter the conditions under which subsequent optimization takes place.
Fronthaul places a direct limit on how much information can be exchanged. Fully centralized processing can require substantial CSI and data transfer as the number of access points and users grows. Practical designs therefore have to balance cooperation against available transport and processing resources.
Independent cell-free massive MIMO research continues to address that scalability problem. A 2025 IEEE Access study describes network overloading and scalability as major design challenges and evaluates a joint pilot and access-point assignment method in systems tested with up to 150 access points. [8] The paper notes that fully centralized processing can create significant fronthaul signaling and computational demands as deployments expand.
Synchronization adds another requirement. Coherent joint processing depends on suitable phase and frequency alignment across distributed access points. A 2024 IEEE Open Journal of the Communications Society study examines phase misalignment among access points in cell-free massive MIMO and evaluates a partially coherent transmission framework designed to reduce the need for network-wide phase alignment. [9]
AI-driven coordination has to operate inside those constraints. Improving beamforming or scheduling is only part of the problem when the information required for that decision is delayed, compressed, or unavailable at the point where the model runs.
Designing an AI-Ready 6G RAN:
Where the model runs can be as important as what the model does.
A latency-sensitive control loop may need processing close to the network element generating the measurements. Another workload may benefit from a larger computational environment with access to a wider network view. Data access, inference latency, model updates, and control interfaces all affect that choice.
Four practical questions follow:
- Where does inference run?
- Which measurements reach the model?
- How frequently are those measurements updated?
- What happens when the required information sits elsewhere in the RAN?
O-RAN already has work addressing part of this problem. Its WG2 specifications cover the Non-Real-Time RAN Intelligent Controller, A1 and R1 interfaces, AI/ML learning and deployment, and the AI/ML workflow. [10]
O-RAN’s current work does not define the final architecture for 6G. It does show where AI lifecycle and deployment questions are already being addressed in today’s RAN architecture. 6G-MIRAI-HARMONY takes those concerns into a research setting that also includes distributed and potentially disaggregated 6G architectures. [4]
Common Data, Benchmarking and Validation:
Performance figures become difficult to compare when the experiments behind them use different conditions. Two studies might report higher spectral efficiency while using different datasets, channel assumptions, training procedures, hardware models, and test conditions. Without those details, the numbers are difficult to interpret.
The 6G-MIRAI-HARMONY D3.1 deliverable addresses this problem directly. It provides the project’s first consolidated framework for benchmarking and validation, data-management principles, and common scenarios. The document places particular emphasis on repeatability, traceability, comparability, data quality, and reuse. It also defines KPI/KVI considerations and protocols for training, evaluation, and generalization. [11] The evaluation chain is shown in Figure 1.
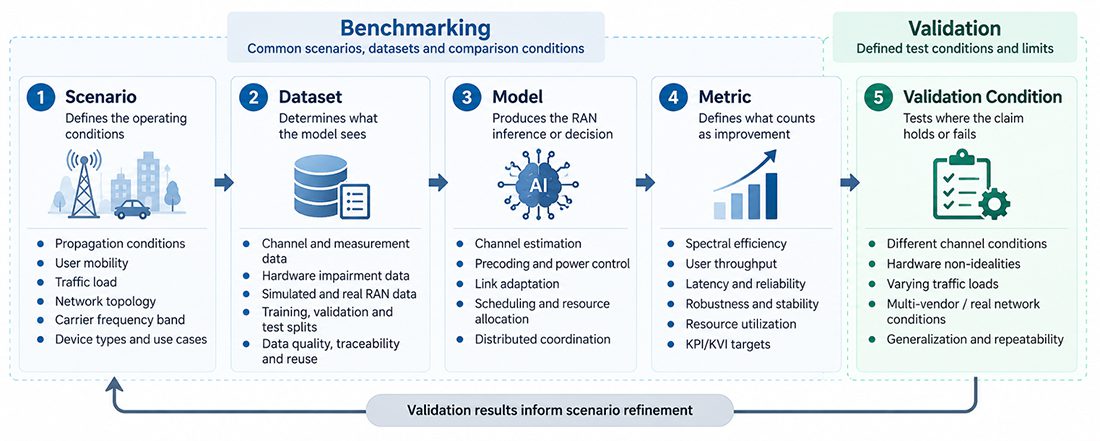
Figure 1. The evaluation chain for AI-native RAN research.
The scenario defines the conditions represented in the experiment. The dataset determines what the model sees. The model is evaluated through selected metrics and then tested under stated validation conditions.
Changing one part of that chain can change the result. An unseen propagation condition may expose a generalization problem. A realistic hardware model may reduce the gain seen with ideal hardware. A different metric may favor a different approach. Benchmarking and validation also answer different questions. Benchmarking establishes common conditions for comparing approaches. Validation examines whether the resulting system behaves as required under defined conditions.
D3.1 is an existing project output. Later deliverables are intended to add datasets and results covering common scenarios, validation, and benchmarking. Those later outputs should remain described as project work rather than completed findings until the corresponding evidence is published. [11][12]
From Research Validation to Standardization:s
ITU-R’s IMT-2030 work has already moved beyond the initial framework.
Recommendation ITU-R M.2160 established the framework and overall objectives for IMT-2030 in November 2023. The framework includes six usage scenarios, among them Artificial Intelligence and Communication (AIAC), and identifies ubiquitous intelligence as one of its overarching design principles. [13]
In February 2026, ITU-R Working Party 5D completed the draft report on minimum technical performance requirements for IMT-2030 radio interfaces. The draft defines 20 minimum technical performance requirements and provides a consistent basis for specification and evaluation. The draft has been submitted to Study Group 5 for consideration in December 2026. [14] In June 2026, Working Party 5D also completed the draft guidelines for evaluating candidate IMT-2030 radio interface technologies. The guidelines define three evaluation methods—simulation, analytical evaluation, and inspection—and specify seven test environments. The draft has likewise been submitted to Study Group 5 for approval in December 2026. [14]
ITU-R’s candidate radio-interface technology submission process is scheduled to begin in February 2027, with the candidate-submission window extending through February 2029. [14] 3GPP is pursuing AI/ML work within the RAN in parallel. TR 38.745, “Study on Artificial Intelligence (AI)/Machine Learning (ML) for NG-RAN Phase 3,” was created for Release 20 on September 5, 2025, and was placed under change control on March 19, 2026. [15]
Research results do not become standards simply because an algorithm performs well in one experiment. The useful evidence includes the conditions behind the result: the scenario, dataset, metrics, validation method, limitations, and reproducibility of the test.
Conclusions:
AI-native 6G RAN will require more than putting machine learning inside individual RAN functions.
Propagation changes. Hardware is imperfect. Network intelligence becomes distributed. Fronthaul and synchronization can limit coordinated processing. Architecture determines where data and computation are available. Training and evaluation conditions affect what an AI result actually shows.
6G-MIRAI-HARMONY brings these issues into one research program by connecting realistic wireless models, AI-based PHY techniques, cell-free coordination, AI-ready RAN architecture, and common approaches to data, benchmarking, and validation. The work points to a practical requirement for AI-native RAN research: performance results need enough information around them to show how they were produced, where they hold, and what changes when the underlying conditions change.
References:
- SoftBank Corp. and Ericsson, “SoftBank Corp. and Ericsson conduct Japan’s first trial of Ericsson AI in RAN on a 5G commercial network,” August 20, 2026.
https://www.ericsson.com/en/press-releases/2/2026/softbank-corp-and-ericsson-conduct-japans-first-trial-of-ericsson-ai-in-ran-on-5g-commercial-network - IEEE ComSoc Technology Blog, “Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020),” January 15, 2026.
https://techblog.comsoc.org/2026/01/15/comparing-ai-native-mode-in-6g-imt-2030-vs-ai-overlay-add-on-status-in-5g-imt-2020/ - IEEE ComSoc Technology Blog, “IMT-2030 (‘6G’) Minimum Technology Performance Requirements for Radio Interface Technologies,” March 17, 2026. https://techblog.comsoc.org/2026/03/17/update-imt-2030-6g-minimum-technology-performance-requirements/
- 6G-MIRAI-HARMONY, “Concept and Methodology,” 2026.
https://6g-mirai-harmony.eu/concept-and-methodology/ - European Commission, CORDIS, “Machine Intelligence based Radio Access Infrastructure (6G-MIRAI),” Grant Agreement No. 101192369.
https://cordis.europa.eu/project/id/101192369 - 6G-MIRAI-HARMONY, “Consortium and Objectives,” 2026.
https://6g-mirai-harmony.eu/consortium-and-objectives/ - Tadele A. Abose and Thomas O. Olwal, “Hardware-Impairment-Aware CNN-Based Hybrid Precoding for Cell-Free Massive MIMO Systems Under Imperfect CSI in Terahertz-Enabled 6G Networks,” Telecom, vol. 7, no. 3, 2026.
https://www.mdpi.com/2673-4001/7/3/70 - Mhammad B. Hmayed and Ali H. Bastami, “Scalable Cell-Free Massive MIMO System: Joint Optimal Pilot and Access Point Assignment,” IEEE Access, vol. 13, pp. 201778–201788, 2025. DOI: 10.1109/ACCESS.2025.3638655
https://ieeexplore.ieee.org/document/11271199 - Unnikrishnan Kunnath Ganesan, Tung Thanh Vu, and Erik G. Larsson, “Cell-Free Massive MIMO With Multi-Antenna Users and Phase Misalignments: A Novel Partially Coherent Transmission Framework,” IEEE Open Journal of the Communications Society, vol. 5, pp. 1639–1655, 2024.
DOI: 10.1109/OJCOMS.2024.3373170.
https://ieeexplore.ieee.org/document/10459246 - O-RAN Alliance, “WG2: Non-Real-time RAN Intelligent Controller and A1,” Technical Work Group scope.
https://www.o-ran.org/technical-groups/wg2 - 6G-MIRAI-HARMONY, “D3.1 — Definition of Initial Common Scenarios, Data Management and Benchmarking Methodology,” 2026.
https://6g-mirai-harmony.eu/wp-content/uploads/2026/02/6G-MIRAI_Deliverable_D3.1_Scenarios_Data_Bench_v1.0.pdf - 6G-MIRAI-HARMONY, “Deliverables, Publications and Workshops,” 2026.
https://6g-mirai-harmony.eu/deliverables-publications-and-workshops/ - ITU-R Recommendation M.2160-0, “Framework and overall objectives of the future development of IMT for 2030 and beyond,” November 2023.
https://www.itu.int/rec/R-REC-M.2160-0-202311-I/en - ITU-R, “IMT towards 2030 and beyond (IMT-2030),” current development, evaluation, and submission process.
https://www.itu.int/en/ITU-R/study-groups/rsg5/rwp5d/imt-2030/pages/default.aspx - 3GPP, TR 38.745, “Study on Artificial Intelligence (AI)/Machine Learning (ML) for NG-RAN Phase 3,” Release 20.
https://portal.3gpp.org/desktopmodules/Specifications/SpecificationDetails.aspx?specificationId=4445
Author Bio:
Shammi Thakur is Research Director at MarkNtel Advisors, with more than 15 years of experience in strategic market intelligence, industry forecasting, and competitive analysis. He leads research initiatives across global technology and communications markets, overseeing the development of market studies and strategic research frameworks. His work focuses on translating complex industry developments into evidence-based insights, with particular experience in emerging technologies, market evolution, and the forces shaping next-generation communication systems.
Website: MarkNtel Advisors
Broadcom lending Anthropic up to $42 billion in yet another AI circular financing deal
Backgrounder:
According to Reuters, which obtained Anthropic’s IPO prospectus, the Big Tech giants are depicted in multiple ways in the IPO filing- as distribution partners, financial backers, computer suppliers, and competitors, all at once. They uncovered the clearest view yet of how circular the AI world really is, and how much an AI lab’s success depends on the giants it’s also competing against.
Reuters was able to calculate that Anthropic pays roughly 16% of every dollar it earns from its cloud partners (Amazon, Google, Microsoft) back to those same big tech partners. It counts the full value of contracts sold through a cloud marketplace as revenue, then treats the cloud platform’s cut of revenue as a marketing cost.
OpenAI does the opposite by only counting what it keeps after the cloud partner takes its share. That difference matters for understanding the big numbers floating around, and how to actually compare the two rivals’ toplines as they both eye the public market.
Broadcom’s relationship with Anthropic spans compute supply, equipment leasing and financing — giving the semiconductor company a central role in Anthropic’s infrastructure buildout. That differentiates it from other major partners and investors such as Amazon which primarily provide cloud infrastructure and distribution for Anthropic’s AI model Claude.
As part of that complex relationship, revealed in the IPO filing, Broadcom has agreed to lend Anthropic up to $42 billion to finance infrastructure spending. In turn, Anthropic stands to become the largest customer in Broadcom’s entire chip design business next year, making their relationship a prime example of the reciprocal spending that has animated AI skeptics on Wall Street, even as the AI lab readies a public offering that could see it valued at $2 trillion.
“It feels that there’s quite a concentrated bet right now on two companies being able to generate enough revenues to support all the financing that’s happened,” said Robert Leitao, managing partner of Rothschild & Co.
Anthropic disclosed that Broadcom’s role in supplying hardware and acting as a financing partner creates “potential conflicts of interest” that might affect Anthropic’s ability to access the computing power needed for its work, according to the prospectus.
The AI lab also warned that Broadcom’s decisions around pricing and hardware could affect its ability to procure enough computing infrastructure. Broadcom did not comment. Anthropic declined to comment to Reuters.
In April, Anthropic announced it was teaming up with Broadcom and Google for a deal that would see Google provide its Tensor Processing Unit (TPU) chip capacity to Anthropic, with the supply coming online in 2027. Broadcom designs Google’s TPUs that are manufactured by TSMC in Taiwan.

A Broadcom circuit board for chip testing is pictured during a lab tour as Broadcom prepares to launch new optical chip tech to fend off Nvidia in San Jose, California, U.S., September 5, 2025. Brittany Hosea-Small · REUTERS via Yahoo Finance.
Anthropic is also relying on Broadcom for equipment leasing and financing. Broadcom could designate a financing partner, and the debt instruments could be converted into Anthropic shares. Anthropic said in its filing it doesn’t expect any notes to be sold before it completes its IPO. The convertible note Anthropic would issue could finance about a third of the $125.2 billion commitment the AI lab has made for a five-year lease of tensor processing unit (TPU) computing capacity.
Other Players:
Broadcom rivals Nvidia and AMD have also provided funding to their own customers, including OpenAI and Anthropic, which the labs then used to pay for access to the companies’ high-powered chips. The concern about such circular financial schemes is that if one domino in the row falls, it will cause a chain reaction that will decimate the AI trade and, as a result, the global equities markets that have benefited from and come to rely on AI firms and hyperscalers.
As to the circularity of all of this financing, the BIS notes (via FT Alphaville):
“… circular relationships make reported demand partly endogenous to firms’ own financing decisions. For example, when a supplier finances a customer, part of the supplier’s revenue growth reflects its own capital investment, rather than organic final demand. This makes it harder for investors, lenders and supervisors to gauge what part of the current AI boom is based on organic demand.”
“The parallel with the telecom boom of the late 1990s is instructive: upstream equipment vendors financed network operators so they could buy the vendors’ equipment. This meant that part of the equipment vendors’ reported sales was being funded by the vendors themselves. For a time, as operators expanded their networks, equipment orders also expanded and vendors booked both the sales and loans as assets. However, when operators’ own revenues failed to materialize or slowed, they could neither repay the loans nor sustain the equipment purchases. Equipment vendors then sustained both financial losses and a loss of sales. Such dynamics may also play out in AI if revenue growth and end user demand fall short of firms’ expectations.”
……………………………………………………………………………………………………………………………………………………………………………………………..
- 2026 Debt Issuance: Projected between $220 billion and $250+ billion for major US hyperscalers (Alphabet / Google, Amazon, Meta, Microsoft, and Oracle), with broader AI-related market debt reaching up to $570 billion.
- 2027 Forecast: Goldman Sachs projects direct hyperscaler debt issuance to nearly double to around $400 billion (Jeff Pu estimates $419 billion) as companies finance over a third of their infrastructure needs.
- Aggregate Capex: Combined capital expenditures are expected to hit roughly $940 billion in 2026 and scale past $1.3 trillion in 2027.
- Market Share: Hyperscaler investment-grade bond sales have jumped from roughly 2% of total US supply (2022–2024) to roughly 9% in 2026.
- Credit Impact: Credit spreads on a 10-year hyperscaler credit basket have widened from historical 40–75bp ranges toward 90bp+, driven by leverage concerns.
- Cash Flow Outlook: S&P Global Ratings expects all major hyperscalers to run negative free operating cash flow through 2026 and 2027, with a cash-flow inflection point not projected until 2028–2029.
Source: Google Gemini
…………………………………………………………………………………………………………………………………………………………
References:
https://www.ft.com/content/87875b20-4081-4511-9afe-4ee389409742
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs (07/23)
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Telcos don’t have an AI problem; they have a voice estate visibility problem
By Satish Barot, Co-founder and CTO, Klearcom with Shazia Hasnie
AI is increasing telecom interdependence
This author has spent around twenty years building telephony products, and the last few watching what happens when AI gets added to them. The models are usually fine, but the voice estates around them are not.
Explanation: The voice estate is everything a voice call touches: the number dialed, the carriers delivering it, the menu that answers, the systems behind it, and in every country/location served.
NVIDIA’s February 2026 survey of roughly one thousand telecom respondents found that sixty percent of organizations are using or evaluating generative AI, up from forty nine percent in its 2024 edition. The voice call that once met a gateway and a queue now meets speech recognition, a language model, a synthetic voice, and also identity checks.
Every one of those can be healthy while the call goes wrong. So the useful test is whether you can prove, from outside your own network, that a real customer’s call still ends the way it should.
Why AI amplifies operational complexity
Old fashioned faults announce themselves: a line drops and something logs it. AI is quieter, and it fails in ways worth naming. It gets worse quietly: a model loses accuracy on one kind of request and nothing reports an error. It’s also confidently wrong. WildASR tested seven speech recognition systems on recordings degraded the way phone audio is. When a caller is cut off mid word, by a network delay or by the system deciding they had finished, the models fill in words nobody said. Further down the line that looks like a clean answer. The same benchmark makes a broader point: robustness measured in one language can substantially mispredict behavior in another, so a release validated in one market tells you little about the next.
Speed fails at the edges, not the average. A system that usually answers in under a second, but takes two and a half seconds on one call in ten, feels broken to those callers and healthy on every voice testing team chart. Nor is the result repeatable: EVA-Bench tested twelve systems and found a wide gap between passing once and passing every time, which undoes testing against a single expected answer.
Then the ones nobody looks at: the fallback menu that takes over when the AI gives up is usually the least maintained thing you own, and it runs exactly when things go wrong. None of this turns a light red on a contact center voice dashboard.
The other exposure is a number that anybody can dial. OWASP ranks prompt injection first among risks to applications built on language models, and a voice channel is an open microphone into the instruction path itself: a caller talks the model out of what it was built and told to do. Mitigations exist and they are worth naming. Treat caller speech as untrusted input and keep the transcript out of the context that carries instructions, constrain what the model can emit to a defined set of intents and slots rather than free text, and require confirmation for anything that moves money, changes credentials, or reads account data back.
The customer journey as the real test environment
Take a composite example, assembled from patterns that recur across multi country voice estates rather than drawn from one operator. An operator runs support numbers in fourteen countries behind one AI system. On Friday the team delivers an updated model and a new synthetic voice. Both pass in testing, no issues. By Monday, the share of calls handled without an agent is up by six points, complaints are up in three countries where the release went live first, and every dashboard is green. Nobody knows why.
The new voice made the menus two seconds longer, and nobody adjusted the window in which the system listens for a caller to stop talking. Callers spoke too early, the system heard fragments, filled the gaps, and guessed just confidently enough to keep a person out of the call.
The headline number improved because failures had stopped escalating. Every part did its job, so nothing raised an alarm. What broke was the outcome, and no single part owns the outcome. People given those same recordings transcribed them easily.
Those failures are not hypothetical. Test calls run by my own team over the past two years have found a global biopharmaceutical company whose menu prompts ran into each other faster than callers could answer, a financial services provider whose speech recognition intermittently failed on the word “agent”, so the route to a human worked on some calls and failed on others, and a healthcare data provider whose misrouted number reached an AI assistant that was never meant to answer it. In every case the systems carrying the call reported nothing wrong.
From system monitoring to outcome validation
Monitoring looks inward: are my systems up? Validation looks outward. It places a real call in country and checks the result against what should have happened: is a customer in this country, on this network, right now, getting the right answer?
Monitoring only sees what you own, and these failures hide inside the part causing them. So the two work together: validation tells you something is wrong and where, monitoring tells you why. Three changes follow. Report three numbers where you currently report one: calls the AI resolved correctly, calls it escalated correctly, and calls it failed. Report the slower calls alongside the average ones, and report by country and carrier instead of one global figure.
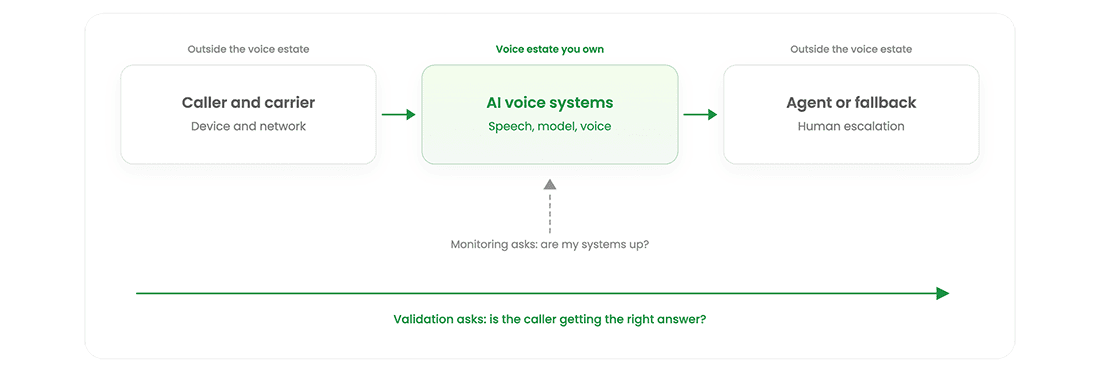
Figure 1. A single call crosses the voice estate an operator owns and systems it does not. Monitoring covers only the shaded stage. Validation traverses the whole path from the caller’s side.
Continuous testing as an assurance layer
The industry already has vocabulary for this. TM Forum’s autonomous network levels give operators a shared scale for how much of the “operate, assure and optimize” loop runs without people, and the same NVIDIA survey places 88% of organizations at Levels 1 to 3 on a scale of 0 to 5. Moving up that scale rests on evidence about delivered outcomes.
If the journey is what breaks, the journey is what you test. That means dialing the real public number, from a real device, on a real carrier in the country the customer is calling from, rather than looping a call back inside your own data center. It means testing from the outside in, and it means doing it on a schedule, across every country and carrier your customers use, fixed and mobile.
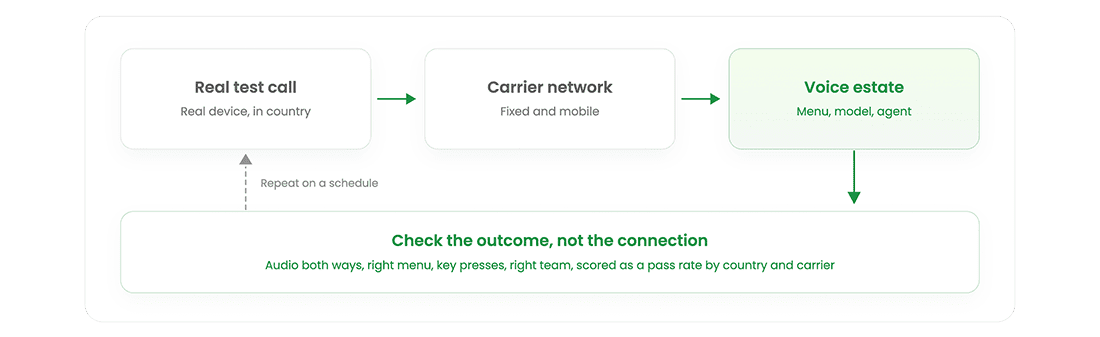
Figure 2. Testing the journey from the outside in. A scheduled call dialed from a real device in the country the customer calls from, scored on the delivered outcome.
Check outcomes, not connections: audio clear both ways, the right menu, key presses registered, the caller reaching the right team with their details intact. Score it across many calls with a library of realistic phrases, accepting a pass rate rather than an exact match, so decline shows as a trend. Treat a model update like a network change: try it on a few numbers first, then pull it back if the pass rate drops.
Several approaches are in this category. Synthetic transaction monitoring from operator owned probes, carrier side test call generation and crowdsourced testing on real handsets all produce outside in evidence, and they trade off differently on country coverage, cost and how closely the test resembles a real customer’s call. The common requirement is that the evidence originates outside the systems being assured, on a call placed in the country where the customer is dialing from.
Practical implications
Keep human escalation as a safety valve, not a number to drive down: cutting it without checking correctness makes the metric look better while the service gets worse. Then give the outcome an owner. Gartner’s June 2025 forecast that over 40% of agentic AI projects will be canceled by the end of 2027 attributes those cancellations to escalating costs, unclear business value and inadequate risk controls. Model capability doesn’t appear anywhere on that list. This is organizational before it’s technical.
These failures are seams between systems that break without producing an error, and monitoring your own equipment cannot see them: the gap sits between what your systems report and what your customer gets. Networks have been tested end to end for decades rather than trusted part by part. Voice estates deserve the same.
References
- NVIDIA (2026) State of AI in Telecommunications: 2026 Trends. Fourth annual survey report, published 19 February 2026, based on responses from 1,038 telecom professionals worldwide. Summary of findings: Survey Reveals AI Advances in Telecom.
- Tay, G., Ma, W., Lee, J., Tang, Y., Lee, D., Yin, W., Shen, D., Meng, S., Zhu, Y., Li, M. and Smola, A. (2026) Back to Basics: Revisiting ASR in the Age of Voice Agents. Boson AI. arXiv preprint arXiv:2603.25727, 26 March 2026. Introduces the WildASR benchmark. Dataset and code: bosonai/WildASR.
- Bogavelli, T., Gauthier Melançon, G., Stankiewicz, K., Bamgbose, O., Riols, F., Nguyen, H.H., Mehndiratta, R., Brin, L.D., Marinier, J., Subramani, H., Madamala, A., Nemala, S.K. and Sunkara, S. (2026) EVA-Bench: A New End-to-end Framework for Evaluating Voice Agents. arXiv preprint arXiv:2605.13841, 13 May 2026, revised 27 May 2026. DOI: 10.48550/arXiv.2605.13841.
- OWASP GenAI Security Project (2025) OWASP Top 10 for LLM Applications 2025. OWASP Foundation. Prompt injection is listed first, as LLM01.
- Gartner (2025) Gartner Predicts Over 40% of Agentic AI Projects Will Be Canceled by End of 2027. Press release, Sydney, 25 June 2025.
- TM Forum (2025) Autonomous Networks Framework v2.0.0 (IG1218F). Introductory Guide, published 20 March 2025, TM Forum Approved 9 May 2025. Levels of autonomy 0 to 5. Evaluation criteria for assigning a level are in Autonomous Network Levels Evaluation Methodology (IG1252).
-
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
………………………………………………………………………………………………………………………………………………………………………..
About the author:
Satish Barot is co-founder and CTO of Klearcom. He has spent around twenty years building telephony products and leads the engineering team behind Klearcom’s voice testing platform.
Verizon offers free online AI training tailored to your interests!
Verizon has launched an online portal that curates AI training content from several tech giants, including IBM, Google, Microsoft, Anthropic, OpenAI, and online course provider Coursera. The U.S.’ largest wireless carrier by subscriber count says that the type of courses on offer normally cost in the region of $700 per year, but it is making them available for free.
“Strengthening the American economy starts with making sure every individual has the opportunity to adapt and succeed in a rapidly changing world. AI isn’t just a technological shift – it will change the face of every workforce around the world,” said Verizon CEO Dan Schulman.
“Companies, working closely together and with the public sector, have a responsibility to invest in people with the same urgency they invest in technology. By giving people and small businesses free access to the best AI training, we are helping workers retain their jobs, navigate transitions, support their families, and help small businesses grow – while building confidence in our American economy. When you empower people to embrace change rather than fear it, you create a ripple effect that builds healthier communities and a stronger and more resilient national economy.”
Linked to this initiative is a separate $1 million grant that Verizon has awarded to the Liberty Science Center (LSC) in Jersey City, New Jersey. The funds will be spend on providing practical AI skills to individuals and small businesses.
“As a company with a strong footprint in New Jersey, Verizon is deeply committed to supporting the communities we call home, and our longstanding partnership with Liberty Science Centre is a cornerstone of that commitment,” said Donna Epps, chief responsible business officer of Verizon. “Verizon and LSC have a shared vision of empowering the learners and leaders of tomorrow, and we’re excited to work together to create programming that evokes curiosity for new technologies for educators, families and students from across the state.”
The non-profit “Centre for Humane Technology (CHT)” – co-founded by ex-Googler Tristan Harris – has published a report (PDF) explaining how AI could damage everything from personal relationships to governments, and -most significantly- the workplace.
References:
https://www.verizon.com/ai-skills/home
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Introduction:
According to the Wall Street Journal, the AI build-out is rapidly becoming the largest concentrated infrastructure investment cycle in modern American economic history. Unlike earlier national build-outs—railroads, interstate highways, electrification, or the commercial internet—this cycle is being driven largely by a small group of cloud platforms deploying highly specialized compute, networking, power, cooling, and semiconductor infrastructure at unprecedented speed. Economist Stijn van Nieuwerburgh estimates that U.S. spending on data centers and related AI infrastructure could reach $10.3 trillion [1.] between 2025 and 2032, equivalent to an average of 3.6% of annual GDP. The estimate encompasses far more than conventional enterprise data centers: it reflects the industrial-scale infrastructure needed to train and serve frontier AI models, including GPU and accelerator clusters, high-bandwidth memory, advanced packaging, optical interconnects, high-capacity Ethernet and InfiniBand fabrics, grid interconnection, substations, backup generation, liquid cooling, and long-haul fiber connectivity.
Note 1. The $10.3 trillion number is a scenario-based estimate of U.S. AI infrastructure investment during 2025–2032—not a forecast of announced corporate spending. The Brookings analysis behind it assumes that about 183 GW of new data-center capacity will be completed through 2032, versus a 509-GW announced/planned pipeline. A representative 200-MW AI campus is estimated to cost about $8.2 billion: $5.6 billion for IT equipment, $2.2 billion for the facility, and $0.4 billion for power infrastructure. Thus, most of the investment is in compute and networking hardware rather than buildings.
The scale creates a major financing challenge: the five largest hyperscalers are projected to spend about $800 billion on capex in 2026, exceeding their combined operating cash flow. Under the Brookings assumptions, the resulting infrastructure would need roughly $3.7 trillion of annual revenue by 2032 to produce a 10% unlevered return. The key economic issue, therefore, is whether future AI revenue and utilization can justify the enormous capital investment.
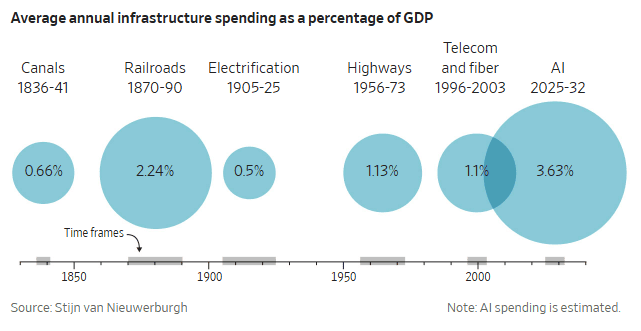
From Cloud Data Centers to AI Factories:
The defining characteristic of this AI buildout investment cycle is its concentration. The five U.S. hyperscalers (Alphabet, Amazon, Meta, Microsoft, and Oracle) are collectively expected to invest roughly $4.2 trillion in capital expenditures during the four years ending in 2029, according to FactSet estimates cited in the source material. Increasingly, this capital is directed toward AI-optimized facilities: campuses designed around megawatt-scale accelerator pods, dense GPU clusters, high-radix network fabrics, and power delivery systems capable of supporting workloads whose energy and cooling profiles differ sharply from those of traditional cloud computing.
Those five major hyperscalers increased combined capital expenditures from approximately $97 billion in 2020 to more than $400 billion in 2025, with the paper projecting approximately $800.5 billion in 2026. That 2026 figure is significant because it exceeds their combined operating cash flow of approximately $707.1 billion. In other words, projected capex is about 113% of operating cash flow. Pacific Software Ventures That creates a MAJOR financing problem: AI infrastructure investment is becoming too large to be financed entirely from hyperscaler internally generated cash.
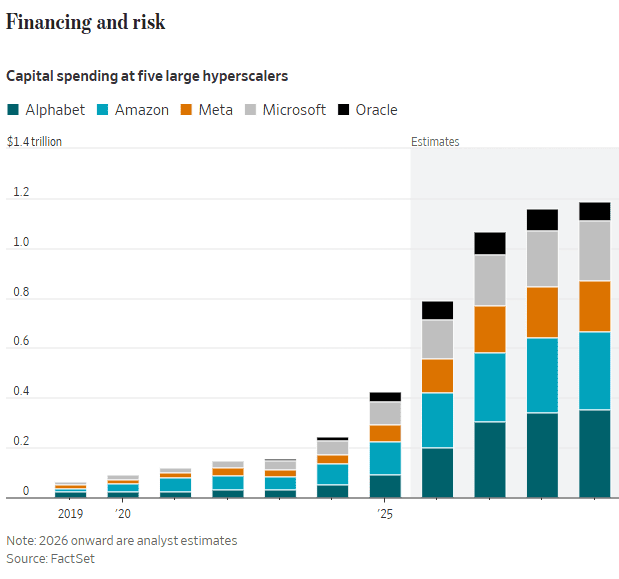
AI infrastructure is not simply an expansion of conventional cloud capacity. Large-model training and inference create a distinct systems-engineering problem. Training AI frontier foundation models requires thousands to hundreds of thousands of tightly coupled accelerators. Those accelerators must exchange model parameters, activation data, and gradients at extremely high rates. Network performance therefore becomes a first-order determinant of usable compute capacity. A GPU cluster can deliver poor economics if its fabric introduces congestion, latency, packet loss, or inadequate bisection bandwidth during distributed training.
That requirement is accelerating deployment of:
-
GPU- and AI-accelerator servers with high-bandwidth memory and advanced semiconductor packaging.
-
High-speed scale-up interconnects within accelerator nodes and scale-out fabrics across clusters.
-
400 GbE, 800 GbE, and emerging 1.6 TbE Ethernet architectures, along with InfiniBand deployments for tightly coupled training environments.
-
Optical transceivers, co-packaged optics research, photonic switching, and expanded fiber density within and between data-center campuses.
-
AI-aware workload scheduling, distributed storage, data pipelines, checkpointing systems, and network telemetry.
-
Direct-to-chip liquid cooling, rear-door heat exchangers, chilled-water systems, and other thermal-management systems required by high-density AI racks.
-
New transmission lines, substations, transformers, gas generation, battery systems, and other power infrastructure needed to support multi-hundred-megawatt and gigawatt-scale campuses.
In effect, hyperscalers are building what are increasingly described as AI factories: integrated physical and digital production systems that convert electricity, capital equipment, data, and semiconductor capacity into trained models, inference tokens, and AI-enabled cloud services.
A Historically Large Capital Concentration:
AI investment is projected to reach 1.9% of U.S. GDP in 2026, according to Goldman Sachs estimates cited in the source material. The late-19th-century railroad boom was the last period in which a single new infrastructure category represented a larger share of the U.S. economy.
The comparison is useful, but incomplete. Railroads connected physical markets over decades. The AI build-out is being deployed on a far more compressed timetable and is dependent on global supply chains for leading-edge accelerators, high-bandwidth memory, advanced substrates, optical components, power equipment, and data-center construction capacity.
This creates a reinforcing investment loop:
-
Foundation-model developers require more compute to train larger or more capable models.
-
Cloud providers build additional accelerator capacity to support training and inference demand.
-
Semiconductor vendors, memory suppliers, networking companies, optical-component manufacturers, and power-equipment suppliers expand production.
-
Data-center developers secure land, power contracts, grid interconnections, fiber routes, water or cooling capacity, and financing.
-
Enterprises adopt AI services, increasing inference demand and reinforcing hyperscaler investment.
The strategic question is whether revenue from AI applications, enterprise subscriptions, API usage, advertising optimization, software agents, automation, and industry-specific deployments will scale fast enough to justify the capital intensity of the underlying infrastructure.
Financial and Infrastructure Risks:
The scale of investment introduces material financial-system risk. A growing portion of AI-related infrastructure is being financed through debt, including special-purpose entities and off-balance-sheet structures that may have limited public disclosure. These structures can allow technology companies and infrastructure developers to finance data-center construction, equipment purchases, and long-term capacity commitments without placing all obligations directly on corporate balance sheets.
That can be economically rational when capacity utilization is high and long-term AI demand is durable. However, it also creates exposure if expected AI revenues, cloud bookings, or accelerator utilization fail to materialize.
The central risk is not merely that an individual model underperforms. It is that a synchronized reduction in AI capital expenditure could affect multiple interconnected sectors at once:
-
Data-center developers and construction firms.
-
Semiconductor, memory, storage, and server suppliers.
-
Optical networking and switching vendors.
-
Utilities, independent power producers, and grid-equipment manufacturers.
-
Banks, private-credit funds, infrastructure lenders, and equipment-finance providers.
-
Commercial real-estate markets in data-center-heavy regions.
A sudden pause in hyperscaler spending would therefore have broader consequences than a typical technology downcycle. It could reduce orders across a deeply interdependent industrial supply chain while exposing leveraged infrastructure vehicles to weaker cash flows.
IT Product Inflation, Power, and Network Capacity:
The AI build-out is also creating supply-side pressure in strategic technology markets. Demand for data-center equipment—especially memory, advanced semiconductors, servers, optics, and power-delivery equipment—has tightened supply and raised costs. The source material notes that prices paid by importers for computers, peripherals, and semiconductors were 20% higher in August than a year earlier.
That inflation can propagate beyond the data center. Higher component prices can increase the cost of consumer electronics, including smartphones, PCs, gaming systems, and storage products. Enterprises may also face higher prices for servers, networking equipment, cloud services, and AI-enabled software.
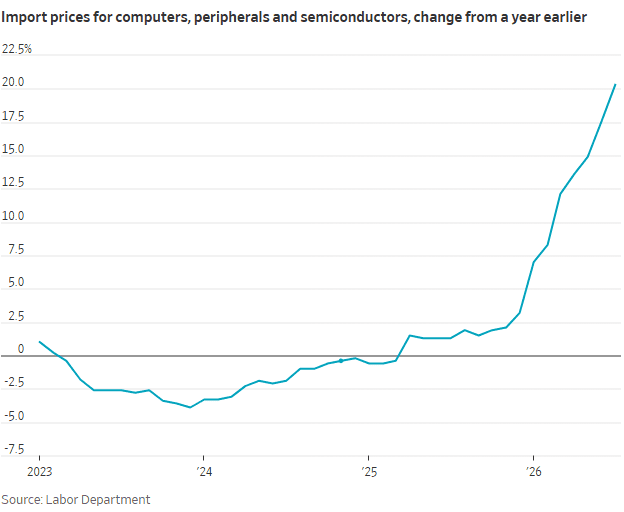
Power is an equally important constraint. AI data centers concentrate demand geographically, often creating large and relatively inflexible new loads on regional grids. A single large campus may require hundreds of megawatts, while the next generation of AI campuses could require gigawatt-scale capacity. This is driving demand for new generation, transmission capacity, substations, transformers, energy storage, and grid-management technologies.
The result is a collision between digital infrastructure planning and energy-system planning. Data-center capacity is no longer determined primarily by real estate, fiber connectivity, or server availability. In many markets, the gating factor is now the ability to obtain firm power, complete interconnection studies, procure transformers and switchgear, and finance new grid infrastructure.
Conclusions:
For IEEE Techblog readers, the central issue is not whether AI demand is real. It is whether the industry can build an economically sustainable, energy-efficient, resilient, and interoperable infrastructure stack at the required scale.
That challenge spans multiple engineering domains:
-
Semiconductor architecture, packaging, memory bandwidth, and energy efficiency.
-
Data-center electrical design, cooling, rack density, and operational resiliency.
-
High-performance networking, congestion control, optical interconnects, and distributed-system design.
-
AI software optimization, including model efficiency, quantization, sparsity, scheduling, and inference optimization.
-
Grid integration, power electronics, demand response, and energy-aware workload placement.
-
Security, supply-chain assurance, and operational management across increasingly autonomous infrastructure.
The AI boom may indeed become the defining infrastructure investment cycle of this era. Its long-term success, however, will depend less on headline capital-expenditure totals than on whether the industry can translate massive spending on accelerators and data centers into durable productivity gains, commercially viable AI services, and infrastructure that does not impose unsustainable costs on power systems, supply chains, consumers, or the financial sector.
………………………………………………………………………………………………………………………………………………
References:
Dell’Oro: Data Center capex grew 92% in 2Q-2026 (caveats galore)
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?