Ethernet
1.6T Ethernet Packet Loss Problem Solved: PHY-Layer Buffer Exhaustion with MAC-Layer Credit-Based Flow Control
Introduction:
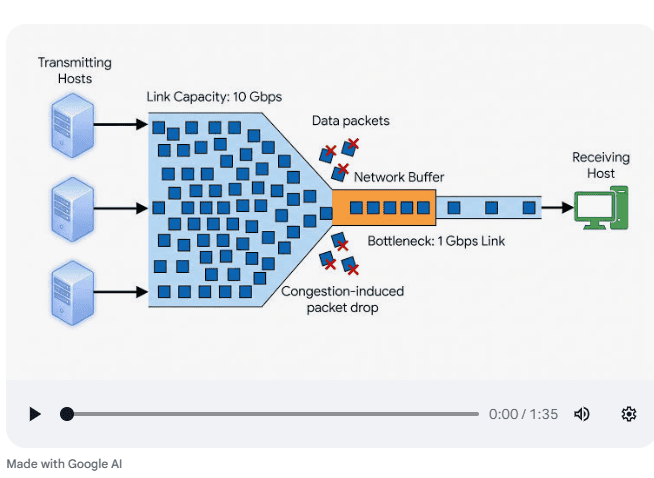
As network fabrics scale to support next-generation AI clusters and workloads, the industry is confronting a harsh physical-layer reality. Recent laboratory benchmarks evaluating 1.6 Terabit Ethernet (1.6T) data streams confirm that under saturated, wire-speed workloads, traditional packet-forwarding logic triggers instantaneous Physical layer (PHY) memory buffer exhaustion.
Recently released laboratory validation data provides the first definitive, real-world proof that the 1.6 Terabit Ethernet (1.6T) PHY layer packet loss problem has been solved in hardware. That’s enabled the networking industry to go from theoretical design to proven physical deployment for next-generation multi-terabit fabrics. While the Open Compute Project (OCP) outlined the architectural blueprint for Ethernet for Scale-Up Networks (ESUN) in February 2026, the live telemetry published from production-ready merchant silicon testbeds establishes a critical milestone: under saturated, wire-speed workloads, hardware-enforced Credit-Based Flow Control (CBFC) at the Media Access Control (MAC) layer successfully prevents physical layer (PHY) memory buffer exhaustion. In synchronized, collective AI training workloads (such as All-Reduce), dropping a single packet introduces a catastrophic tail-latency penalty that leaves expensive GPU clusters sitting idle.
This solution is primarily based on the data link-layer protocol stack defined by the Open Compute Project’s (OCP’s) Ethernet for Scale-Up Networks (ESUN) specification which was successfully tested at the OCP Summit last week by Keysight.
Last week’s hardware test results confirm that by combining the physical signaling foundation of the IEEE P802.3dj Task Force (within the IEEE 802.3 Working Group) with the active pacing blocks of the OCP ESUN specification, silicon architects can guarantee zero-packet-discard performance at full 1.6T line rates without relying on physically impractical silicon buffer footprints.
The Root Cause – Synchronized Bursts vs. PHY Buffers:
Traditional Ethernet was designed for asynchronous, distributed internet traffic where transient congestion could be absorbed by deep-buffer switches or managed gracefully by top-of-stack TCP/IP windows. AI scale-up environments flip this paradigm. Thousands of processing nodes push traffic simultaneously in synchronized, bursty phases. When a 1.6T pipe—operating on 8 channels of 224G SerDes using PAM4 modulation—receives an unpaced burst, the sheer data density overflows the tight SRAM allocation of the physical coding and routing components.
-
- Priority Flow Control (PFC / Pause Frames): Operates too coarsely. Sending a pause frame halts an entire traffic class across the link, creating head-of-line blocking, buffer bloat, and potential deadlock cascades across the data center fabric [Keysight Technologies Protocol Analysis].
- TCP/RoCEv2 Retransmissions: Re-sending a dropped packet introduces millisecond-level delays. In a tightly coupled cluster, the entire training job stalls until that single packet is recovered, destroying overall cluster efficiency.
| Architectural Dimension | IEEE P802.3dj Draft Standard | OCP ESUN Open Specification |
|---|---|---|
| Primary Layer Focus | Physical Layer (PHY) & Electrical Interfaces | Media Access Control (MAC) & Link Sublayer |
| Signaling & Plumbing | 8 lanes of 224G SerDes via PAM4 modulation | Inherits IEEE physicals, modifies packet frame encapsulation |
| Error Handling | Concatenated Forward Error Correction (Inner/Outer RS-FEC) | Link-Level Retry (LLR) for microsecond-range hardware recovery |
| Congestion Control | None (Best-effort link transport) | Credit-Based Flow Control (CBFC) per virtual channel |
| Header Efficiency | Retains standard 28–48 byte IP/UDP network headers | Strips network overhead down to a lightweight 4-byte L2 header |
-
- Short-Range Data Center Clusters (Up to 500 meters):
-
- Standard designation:
1.6TBASE-DR8 - Fiber Type:OS2 Single-Mode Fiber (SMF)
- Cabling Infrastructure: Uses a 16-fiber MPO/MTP connector layout. It utilizes a parallel structure with 8 fibers for transmitting (Tx) and 8 fibers for receiving (Rx) to run eight concurrent 200 Gbps PAM4 pathways.
- Standard designation:
-
- Campus and Intra-Data Center Links (Up to 2 kilometers):
-
- Standard designation:
1.6TBASE-DR8-2 - Fiber Type:OS2 Single-Mode Fiber (SMF)
- Cabling Infrastructure: Also utilizes parallel fibers over a 16-fiber MPO/MTP connector.
- Note: Non-IEEE multi-source agreements (MSAs) have also developed Wavelength Division Multiplexing (WDM) variants like 2×FR4 to hit this 2 km reach. These multiplex eight channels down onto a simpler, standard LC or dual mini-MPO/MTP duplex fiber layout over a standard OS2 cable.
- Standard designation:
-
- Short-Range Data Center Clusters (Up to 500 meters):
-
- Credit Allocation: The downstream receiving node advertises explicit buffer availability to the upstream transmitting node in the form of “credits,” segmented down to granular virtual channels
- Strict Transmission Gate: The upstream MAC transmitter is prohibited from sending a frame unless it possesses a valid credit for that specific virtual channel [Synopsys Architecture Blog].
- Hardware-Enforced Backpressure: As the receiving node’s physical buffers fill, it stops issuing credits. The transmitting node immediately pauses transmission at the silicon boundary, holding packets safely in scale-out network queues before they ever touch the physical wire [Keysight Technologies Protocol Analysis].
-
- Hyperscale Cloud Operators: Meta, Microsoft
- Silicon Architecture & Chip Design: AMD, Broadcom, Cisco, Intel, Marvell, NVIDIA
- Network & Optical Systems: Arista, Hewlett Packard Enterprise (HPE)
- Design & Automation Software: Cadence, Synopsys
+-------------------------------------------------------------------------+

|                  AI WORKLOAD LAYER (All-Reduce / Collective Communications) |
+-------------------------------------------------------------------------+

|                 OCP ESUN LINK LAYER (Base Specification 1.0)             |
|   - 4-Byte Segmented Frame Header (Stripped of traditional IP overhead) |
|   - Credit-Based Flow Control (Proactive virtual-channel buffering)     |
|   - Link-Level Retry (Microsecond-range local hardware error recovery)  |
+-------------------------------------------------------------------------+

|                 IEEE P802.3dj PHYSICAL LAYER (Draft Amendment)          |
|   - Multi-rate MAC Configuration (1.6 Terabits per second throughput)   |
|   - Concatenated Forward Error Correction (Inner & Outer RS-FEC)        |
|   - Physical Media Dependent Signaling (8 Lanes x 224G SerDes via PAM4) |
+-------------------------------------------------------------------------+

|                 PHYSICAL LAYER MEDIA (Data Center Infrastructure)       |
|   - OS2 Single-Mode Fiber (Max 500m via DR8 / Max 2km via 2xFR4 WDM)    |
|   - MPO-16 / MTP-16 High-Density Connectors                             |
+-------------------------------------------------------------------------+
References:
OCP ESUN – Network Operator Requirements – Base Specification 1.0. https://www.opencompute.org/news/the-ocp-esun-10-specification-has-been-released/
2026 OCP Summit: Full-Stack AI Networking Silicon from Nvidia/Cisco and Broadcom; Ethernet vs InfiniBand Interconnects
Executive Summary:
At the 2026 Open Compute Project (OCP) Global Summit in San Jose, CA this week, the multi-vendor push for open, gigawatt-scale AI networks reached a critical tipping point as Cisco and Broadcom deployed massive 102.4 Tbps Ethernet fabrics to challenge Nvidia’s proprietary grip. These and other networking silicon companies are responding to what Cisco executives call a new “Network Supercycle” triggered by agentic AI workloads. The architectural battle lines for gigawatt-scale AI infrastructure were drawn between open ecosystems and proprietary stacks. Broadcom championed the open alternative by introducing its 102.4 Tbps Tomahawk 6 switching platform and third-generation TH6-Davisson Co-Packaged Optics (CPO) to drastically reduce power consumption across clusters exceeding 100,000 accelerators.
- Cisco accelerated this so called “Network Supercycle” by highlighting massive hyperscaler traction for its custom Silicon One P200 routing chips, which Microsoft and Alibaba Cloud have integrated into their custom architectures to handle dense, geographically distributed AI workloads.
- Nvidia defended its market dominance with its Quantum-3 InfiniBand switches and native sub-2µs point-to-point latency; however, despite InfiniBand technically originating as an open industry standard, Nvidia’s sole manufacturing monopoly, closed software integration with CUDA, and proprietary extensions like SHARP have effectively turned it into a vertically locked, high-premium ecosystem. This strict architectural division has forced hyperscalers to choose between the seamless, turnkey acceleration of Nvidia’s proprietary pipeline for tight scale-up GPU environments, or the superior multi-vendor economics, flexibility, and anti-lock-in guardrails offered by Broadcom and Cisco’s open Ethernet frameworks.
- Broadcom launched an open Ethernet fabric architecture designed for gigawatt-scale clusters scaling past 100,000 parallel AI accelerators, showcasing innovations like the 102.4 Tbps Tomahawk 6 and Jericho 4 silicon. The company also introduced TH6-Davisson Co-Packaged Optics, Thor Ultra 800G NICs, and Open Rack Version 3 blueprints to compete with proprietary InfiniBand stacks. You can read more about Broadcom’s announcements at the official corporate site.
I. Cisco has worked with Nvidia on an Ultra-Dense Small Form-Factor Pluggable (USFP), a transceiver that conforms to the Octal Small Form-Factor Pluggable (OSFP) footprint that governs most high-speed datacenter transceivers today. Cisco said USFP enables the industry to accelerate AI by building on the ecosystem models that have powered today’s AI networks. By combining a path to higher-capacity fabrics and improved efficiency with familiar operational practices, USFP helps customers scale AI infrastructure while maintaining the flexibility, interoperability, and consistency required at scale.
Unlike other optical transceivers, the leading versions of which are designed to handle 200-Gb/s today, USFP provides 400-Gb/s full-duplex data rates over 16 lanes with 32 in the future, achieving transmission rates from 6.4 Tb/s up to 12.8 Tb/s. Nvidia said scalability is facilitated by an internal connector technology that reduces wear and improves signal integrity. USFP works with switches and SmartNICs. The new USFP is designed to save power without requiring liquid cooling, something that other solutions feature—most notably Arista Network’s eXtra-dense Pluggable Optics (XPO) solution, which packs its own liquid-cooled cold plate.
Cisco and NVIDIA claim that, compared to an OSFP module supporting 200-Gb/s, the new USFP has approximately 1.3X the power efficiency. At the same time, the USFP matches the footprint of today’s OSFP transceivers, making for an easier transition than the new form-factor XPO, which Arista says improves density by a factor of 4X. The two companies said they’ll work with a “community-led multi-source project” to create an open industry specification for USFP. Members of that “community” were not identified. 
Source: NVIDIA and Cisco
In a blogpost, Cisco executives Bill Gartner, SVP and GM, Optical Systems and Optics, and Will Eatherton, SVP Networking Engineering, stated:
“To help customers scale AI infrastructure efficiently and sustainably, Cisco takes a full-stack, co-designed platform approach that combines silicon, high-density systems, optics, software, and operational expertise. USFP reflects that philosophy. Rather than a standalone innovation, it is part of a broader platform vision that advances scale, efficiency, and performance while preserving the deployment, serviceability, and lifecycle models customers depend on.”
………………………………………………………………………………………………………………………………………………………………………
Cisco also highlighted massive cloud traction for its custom Silicon One P200 routing chip, which provides 51.2 Tb/s of high-buffering switching capacity designed to seamlessly link vast, geographically distributed AI data sites. Microsoft and Alibaba Cloud.
“As our infrastructure demands grow, the P200’s robust architecture provides the speed and enhanced buffering capabilities necessary to address the increasing scale of our cloud and high-performance services,” said Anand Ramakrishna, Corporate Vice President, Engineering, Microsoft, in a statement.
Alibaba has embedded the Silicon One P200 into its Quantum Cat router. “We paired Cisco’s silicon with Alibaba’s custom systems and the SONiC operating system,” stated Dennis Cai, Vice President, Head of Network Infrastructure, Alibaba Cloud Intelligence Group. “This combination … delivers the flexibility and operational power required for some of the world’s most demanding networks.”
Cisco also said that its previously announced 102.4-Tb/s Silicon One G300 is now available for customer sampling, with some G300-powered systems shipping to customers. Another chip, the 51.2-Gb/s G302, is designed to function at top-of-rack (ToR) deployments for scale up or scale across infrastructure.
Cisco’s OCP announcements indicate the networking market leader’s efforts to continue unifying its full-stack strategy around its own silicon, switching, and software, a tack that so far has proved successful.
………………………………………………………………………………………………………………………………………………………………………
-
- Tomahawk 6 & Jericho 4 Silicon: Broadcom demonstrated live partner systems running its 102.4 Tbps Tomahawk 6 switching platform for low-latency frontend fabrics, alongside Jericho 4 silicon for deep-buffered scale-out routing.
- TH6-Davisson Co-Packaged Optics (CPO): This third-generation CPO architecture integrates optics directly onto the switch substrate. By eliminating internal copper traces to traditional transceivers, it drastically reduces power consumption per gigabit.
- Thor Ultra 800G NICs: These high-performance network interface cards support line-rate 800 Gbps RoCE (RDMA over Converged Ethernet) throughput, accelerating memory-to-memory data transfers while bypassing CPU overhead.
- ORV3 Ecosystem Blueprint: Broadcom aligned its PCIe Gen 6 switches, retimers, and optical components with the Open Rack Version 3 (ORV3) and Open Rack Wide standards, supporting dense liquid-cooled rack configurations.
- Open Standard Commitments: Under standardizing frameworks like ESUN (Ethernet for Scale-Up Networking), Broadcom pitched open Ethernet as the primary economic and physical alternative to proprietary InfiniBand fabrics for frontier AI clusters.
- Enterprise LAN and Client-to-Server Interconnects: Connects standard server racks to local networks, user devices, and the broader internet.
- Front-End Data Center Networks: Manages standard cloud computing workloads, database queries, and multi-tenant hosting environments.
- Emerging AI Backends (via RoCEv2): Through frameworks like the Ultra Ethernet Consortium (UEC) and platforms like NVIDIA’s Spectrum-X, modern 800Gbps Ethernet is increasingly deployed by hyperscalers (such as Meta and xAI) for AI clusters due to its superior Total Cost of Ownership (TCO) and rapid innovation cycle.
- Ecosystem and TCO: Leverages a massive global supply chain and existing IT skills, avoiding the proprietary premium and single-vendor lock-in common with InfiniBand.
- RoCE Adaptability: Uses RDMA over Converged Ethernet (RoCEv2) along with Priority Flow Control (PFC) to emulate the low-latency, lossless advantages of InfiniBand over traditional network lines.
-
- Header Optimization: Standard Ethernet headers carry massive protocol overhead that increases latency for small data frames. ESUN implements a streamlined, compact 4-byte ESUN Header (EH) to maximize packet efficiency, strip away unneeded bytes, and drastically lower transport latency.
- Lossless Reliability & Tail Latency Control: AI workloads depend heavily on synchronized “collective” mathematical operations where a single dropped packet can stall the entire training run. ESUN implements advanced Credit-Based Flow-Control (CBFC) to guarantee zero packet loss and tightly manage jitter and tail latency.
- Decoupled Multi-Vendor Interoperability: ESUN focuses strictly on how network switches and network interface cards (NICs) handle frame formatting and packet switching. By keeping the fabric protocol-agnostic, it allows accelerators to define their own host-side transport layers independently, allowing operators to mix-and-match silicon suppliers.
| Networking Initiative | Governing Body | Primary Focus | Role in the AI Ecosystem |
|---|---|---|---|
| ESUN | Open Compute Project (OCP) | Scale-Up Network Fabric (L2/L3 switching and framing) | Optimizes the actual network switches and packet formatting inside the physical rack. |
| SUE-T (Scale-Up Ethernet Transport) | Open Compute Project (OCP) | Scale-Up Endpoint Transport (XPU-to-XPU communication) | A specialized transport protocol layer designed to work natively inside the ESUN switch framework to handle load balancing and transaction scheduling. |
| UEC (Ultra Ethernet Consortium) | Linux Foundation | Data Center-Wide Networks (Initially Scale-Out, expanding to Scale-Up) | A broader, top-to-bottom architecture that ESUN actively pulls specifications and best practices from to align with global standards. |
III. Ethernet vs. InfiniBand for Interconnects:
The structural battle between Broadcom’s open Ethernet platform and Nvidia’s proprietary InfiniBand fabric [1.] are direct competitors for backend compute & storage interconnects in data centers, high-performance computing (HPC), and AI clusters within data centers. The technical architectures, advantages, and philosophies of both approaches contrast sharply.
Note 1. InfiniBand by itself is an open, industry-standard specification managed by the InfiniBand Trade Association (IBTA). Nvidia acquired its primary architect, the Israeli company Mellanox, for $6.9 billion in 2019. However, in the context of modern AI data centers, Nvidia has effectively turned InfiniBand into a de facto proprietary ecosystem through vendor monopoly and closed optimizations. Here’s how that happened:
-
- Vendor Monopoly: Nvidia is the sole manufacturer of AI-class InfiniBand silicon. Competitors like Intel abandoned the technology, while Broadcom and Cisco focus entirely on Ethernet.
- Proprietary Extensions: Nvidia injects closed-source hardware features like SHARP (which offloads AI math directly onto switches) that require a strict end-to-end Nvidia hardware pipeline.
- Software Lock-In: Management and orchestration tools are tightly bound to Nvidia’s proprietary CUDA and Unified Fabric Manager (UFM) stacks.
| Aspect | The Theoretical Standard | The Modern AI Reality |
|---|---|---|
| The Spec | Open, industry-standard managed by the IBTA. | Monopolized by a single vendor (Nvidia). |
| The Silicon | Anyone can build an InfiniBand chip. | Nvidia is the sole manufacturer of AI-class InfiniBand. |
| The Interconnect | Interoperable with various hardware platforms. | Tightly coupled with Nvidia GPUs and CUDA via proprietary extensions like SHARP. |
| Feature / Metric | Broadcom Open Ethernet Platform | Nvidia Proprietary InfiniBand Fabric |
|---|---|---|
| Architectural Philosophy | Open ecosystem. Decouples compute from networking to prevent vendor lock-in. | Vertically integrated. Tightly couples GPUs, switches, and software for a turn-key solution. |
| Top Raw Bandwidth | 102.4 Tbps single-chip switching capacity via Tomahawk 6. Supports native 800G per port. | 51.2 Tbps single-chip switching capacity on the latest Quantum-3 switches (400G per port). |
| Latency Profile | Average < 5µs using RoCE v2. Drops significantly via UEC 1.1 optimizations. | Native sub-2µs point-to-point latency with near-zero jitter. |
| Congestion & Reliability | Uses packet spraying, adaptive routing, and link-level retries via Ultra Ethernet Consortium (UEC). | Native credit-based flow control. Prevents buffer overflows at the hardware level for a completely lossless fabric. |
| Optical Integration | Leading the industry with Co-Packaged Optics (CPO) integrated onto the switch substrate. | Moving toward CPO integration in upcoming H2 2026 platform refreshes. |
| Relative Costs | Standard commoditized pricing. Roughly 1/3 the hardware cost of InfiniBand. | Premium pricing tied directly to Nvidia’s exclusive compute bundle. |
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.futuriom.com/articles/news/cisco-shows-full-stack-networking-strategy-at-ocp/2026/10
https://blogs.cisco.com/news/cisco-and-nvidia-announce-usfp-expanding-the-path-to-ai-connectivity
https://www.broadcom.com/company/news/resources/media-kits/2026-ocp-global-summit
Cisco Execs: New “Network Supercycle” as Agentic AI Workloads Reshape Telecom Infrastructure
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Huawei’s Ascend Silicon Roadmap Extends From AI Chips to Cluster-Scale Infrastructure
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
Meta’s “Iris” AI Chip for MTIA: Implications for Telecom-Grade Optical Networking, DCI and High Capacity Ethernet Fabrics
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Disclaimer: The author used Perplexity.ai for the research in this article.
……………………………………………………………………………………………………………..
Introduction:
Ethernet is now the leader in “scale-out” AI networking. In 2023, InfiniBand held an ~80% share of the data center switch market. A little over two years later, Ethernet has overtaken it in data center switch and server port counts. Indeed, the demand for Ethernet-based interconnect technologies continues to strengthen, reflecting the market’s broader shift toward scalable, open, and cost-efficient data center fabrics. According to Dell’Oro Group research published in July 2025, Ethernet was on track to overtake InfiniBand and establish itself as the primary fabric technology for large-scale data centers. The report projects cumulative data center switch revenue approaching $80 billion over the next five years, driven largely by AI infrastructure investments. Other analysts say Ethernet now represents a majority of AI‑back‑end switch ports, likely well above 50% and trending toward 70–80% as Ultra Ethernet / RoCE‑based fabrics (Remote Direct Memory Access/RDMA over Converged Ethernet) scale.
With Nvidia’s expanding influence across the data center ecosystem (via its Mellanox acquisition), Ethernet-based switching platforms are expected to maintain strong growth momentum through 2026 and the next investment cycle.
The past, present, and future of Ethernet speeds depicted in the Ethernet Alliance’s 2026 Ethernet Roadmap:
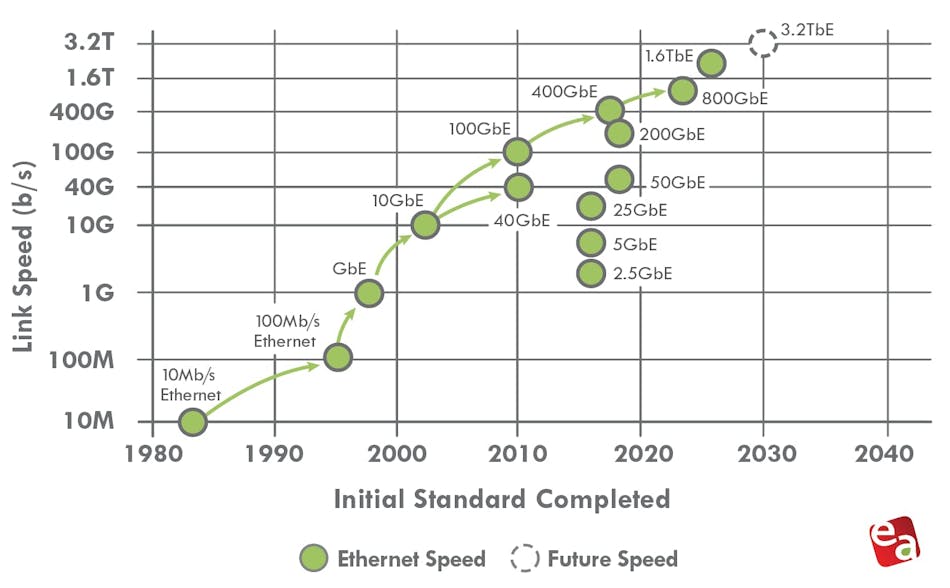
- IEEE 802.3 expects to complete IEEE 802.3dj, which supports 200 Gb/s, 400 Gb/s, 800 Gb/s, and 1.6 Tb/s, by late 2026.
- A 400-Gb/s/lane Signaling Call For Interest (CFI) is already scheduled for March.
- PAM-6 is an emerging, high-order modulation format for short-reach, high-speed optical fiber links (e.g., 100G/400G+ data center interconnects). It encodes 2.585 bits per symbol using 6 distinct amplitude levels, offering a 25% higher bitrate than PAM-4 within the same bandwidth.
………………………………………………………………………………………………………………………………………………………………………………………………………..
Dominant Ethernet speeds and PHY/PMD trends:
In 2026, the Ethernet portfolio spans multiple tiers of performance, with 100G, 200G, 400G, and 800G serving as the dominant server‑ and fabric‑facing speeds, while 1.6T begins to appear in early AI‑scale spine and inter‑cluster links.
-
Server‑to‑leaf topology:
-
100G and 200G remain prevalent for general‑purpose and mid‑tier AI inference workloads, often implemented over 100GBASE‑CR4 / 100GBASE‑FR / 100GBASE‑LR and their 200G counterparts (e.g., 200GBASE‑CR4 / 200GBASE‑FR4 / 200GBASE‑LR4) using 4‑lane PAM4 modulation.
-
Many AI‑optimized racks are migrating to 400G server interfaces, typically using 400GBASE‑CR8 / 400GBASE‑FR8 / 400GBASE‑LR8 with 8‑lane 50 Gb/s PAM4 lanes, often via QSFP‑DD or OSFP form‑factors.
-
-
Leaf‑to‑spine and spine‑to‑spine topology:
-
400G continues as the workhorse for many brownfield and cost‑sensitive fabrics, while 800G is increasingly targeted for new AI and high‑growth pods, typically deployed as 800GBASE‑DR8 / 800GBASE‑FR8 / 800GBASE‑LR8 over 8‑lane 100 Gb/s PAM4 links.
-
IEEE 802.3dj is progressing toward completion in 2026, standardizing 200 Gb/s per lane operation a
-
For cloud‑resident (hyperscale) data centers, the Ethernet‑switch leadership is concentrated among a handful of vendors that supply high‑speed, high‑density leaf‑spine fabrics and AI‑optimized fabrics.
Core Ethernet‑switch leaders:
-
NVIDIA (Spectrum‑X / Spectrum‑4)
NVIDIA has become a dominant force in cloud‑resident Ethernet, largely by bundling its Spectrum‑4 and Spectrum‑X Ethernet switches with H100/H200/Blackwell‑class GPU clusters. Spectrum‑X is specifically tuned for AI workloads, integrating with BlueField DPUs and offering congestion‑aware transport and in‑network collectives, which has helped NVIDIA surpass both Cisco and Arista in data‑center Ethernet revenue in 2025. -
Arista Networks
Arista remains a leading supplier of cloud‑native, high‑speed Ethernet to hyperscalers, with strong positions in 100G–800G leaf‑spine fabrics and its EOS‑based software stack. Arista has overtaken Cisco in high‑speed data‑center‑switch market share and continues to grow via AI‑cluster‑oriented features such as cluster‑load‑balancing and observability suites. -
Cisco Systems
Cisco maintains broad presence in cloud‑scale environments via Nexus 9000 / 7000 platforms and Silicon One‑based designs, particularly where customers want deep integration with routing, security, and multi‑cloud tooling. While its share in pure high‑speed data‑center switching has eroded versus Arista and NVIDIA, Cisco remains a major supplier to many large cloud providers and hybrid‑cloud operators.
Other notable players:
-
HPE (including Aruba and Juniper post‑acquisition)
HPE and its Aruba‑branded switches are widely deployed in cloud‑adjacent and hybrid‑cloud environments, while the HPE‑Juniper combination (via the 2025 acquisition) strengthens its cloud‑native switching and security‑fabric portfolio. -
Huawei
Huawei supplies CloudEngine Ethernet switches into large‑scale cloud and telecom‑owned data centers, especially in regions where its end‑to‑end ecosystem (switching, optics, and management) is preferred. -
White‑box / ODM‑based vendors
Most hyperscalers also source Ethernet switches from ODMs (e.g., Quanta, Celestica, Inspur) running open‑source or custom NOS’ (SONiC, Cumulus‑style stacks), which can collectively represent a large share of cloud‑resident ports even if they are not branded like Cisco or Arista. White‑box / ODM‑based Ethernet switches hold a meaningful and growing share of the data‑center Ethernet market, though they still trail branded vendors in overall revenue. Estimates vary by source and definition. - ODM / white‑box share of the global data‑center Ethernet switch market is commonly estimated in the low‑ to mid‑20% range by revenue in 2024–2025, with some market trackers putting it around 20–25% of the data‑center Ethernet segment. Within hyperscale cloud‑provider data centers specifically, the share of white‑box / ODM‑sourced Ethernet switches is higher, often cited in the 30–40% range by port volume or deployment count, because large cloud operators heavily disaggregate hardware and run open‑source NOSes (e.g., SONiC‑style stacks).
-
ODM‑direct sales into data centers grew over 150% year‑on‑year in 3Q25, according to IDC, signaling that white‑box share is expanding faster than the overall data‑center Ethernet switch market.
-
Separate white‑box‑switch market studies project the global data‑center white‑box Ethernet switch market to reach roughly $3.2–3.5 billion in 2025, growing at a ~12–13% CAGR through 2030, which implies an increasing percentage of the broader Ethernet‑switch pie over time.
Ethernet vendor positioning table:
| Vendor | Key Ethernet positioning in cloud‑resident DCs | Typical speed range (cloud‑scale) |
|---|---|---|
| NVIDIA | AI‑optimized Spectrum‑X fabrics tightly coupled to GPU clusters | 200G/400G/800G, moving toward 1.6T |
| Arista | Cloud‑native, high‑density leaf‑spine with EOS | 100G–800G, strong 400G/800G share |
| Cisco | Broad Nexus/Silicon One portfolio, multi‑cloud integration | 100G–400G, some 800G |
| HPE / Juniper | Cloud‑native switching and security fabrics | 100G–400G, growing 800G |
| Huawei | Cost‑effective high‑throughput CloudEngine switches | 100G–400G, some 800G |
| White‑box ODMs | Disaggregated switches running SONiC‑style NOSes | 100G–400G, increasingly 800G |
Supercomputers and modern HPC clusters increasingly use high‑speed, low‑latency Ethernet as the primary interconnect, often replacing or coexisting with InfiniBand. The “type” of Ethernet used is defined by three layers: speed/lane rate, PHY/PMD/optics, and protocol enhancements tuned for HPC and AI. Slingshot, the proprietary Ethernet-based solution from HPE, commanded 48.1% of performance for the Top500 list in June 2025 and 46.3% in November 2025. On both of the lists, it provided interconnectivity for six of the top 10 – including the top three: El Capitan, Frontier, and Aurora.
HPC Speed and lane‑rate tiers:
-
Mid‑tier HPC / legacy supercomputers:
-
100G Ethernet (e.g., 100GBASE‑CR4/FR4/LR4) remains common for mid‑tier clusters and some scientific workloads, especially where cost and power are constrained.
-
-
AI‑scale and next‑gen HPC:
-
400G and 800G Ethernet (400GBASE‑DR4/FR4/LR4, 800GBASE‑DR8/FR8/LR8) are now the workhorses for GPU‑based supercomputers and large‑scale HPC fabrics.
-
1.6T Ethernet (IEEE 802.3dj, 200 Gb/s per lane) is entering early deployment for spine‑to‑spine and inter‑cluster links in the largest AI‑scale “super‑factories.”
-
In summary, NVIDIA and Arista are the most prominent Ethernet‑switch leaders specifically for AI‑driven, cloud‑resident data centers, with Cisco, HPE/Juniper, Huawei, and white‑box ODMs rounding out the ecosystem depending on region, workload, and procurement model. In hyperscale cloud‑provider data centers, ODMs hold a 30%-to-40% market share.
References:
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
AI Data Center Boom Carries Huge Default and Demand Risks
Markets and Markets: Global AI in Networks market worth $10.9 billion in 2024; projected to reach $46.8 billion by 2029
Using a distributed synchronized fabric for parallel computing workloads- Part I
Using a distributed synchronized fabric for parallel computing workloads- Part II
Dell’Oro: Abysmal revenue results continue: Ethernet Campus Switch and Worldwide Telecom Equipment + Telco Convergence Moves to Counter Cable Broadband
Dell’Oro Group recently reported that:
1. 2Q 2024 worldwide Ethernet Campus Switch revenues contracted year-over-year for the third quarter in a row. Ethernet campus switch sales hit an all-time high in 2Q 2023 and a year later, vendors are suffering in comparison.
“We expect another year-over-year contraction in sales next quarter, in 3Q 2024,” said Siân Morgan, Research Director at Dell’Oro Group. “However, the outlook is improving, and the Ethernet Campus Switch market is expected to return to growth in 4Q 2024.”
“While the economy in China remains soft, Huawei grew year-over-year campus switch revenues across the rest of Asia Pacific and CALA. Over half of Huawei’s campus switch sales were generated outside China,” added Morgan.
Additional highlights from the 2Q 2024 Ethernet Switch–Campus Report:
- The contraction in Ethernet campus switch sales was broad-based across both modular and fixed form factors, all verticals and regions.
- Sales to North America fell the most of any macro-economic region.
- Cisco grew campus switch revenues on a quarter-over-quarter basis, for the first time in a year.
The Dell’Oro Group’s Ethernet Switch–Campus Quarterly Report offers a detailed view of Ethernet switches built and optimized for deployment outside the data center, to connect users and things to the Local Area Networks. The report contains in-depth market and vendor-level information on manufacturers’ revenue, ports shipped, and average selling prices for both Modular and Fixed, and Fixed Managed and Unmanaged Ethernet Switches (100 Mbps, 1/2.5/5/10/25/40/50/100/400 Gbps), Power-over-Ethernet, plus regional breakouts as well as split by customer size (Enterprise vs. SMB) and vertical segments. To purchase these reports, please contact us by email at [email protected].
……………………………………………………………………………………………………….
2. Preliminary findings indicate that worldwide telecom equipment revenues across the six telecom programs tracked at Dell’Oro Group—Broadband Access, Microwave & Optical Transport, Mobile Core Network (MCN), Radio Access Network (RAN), and SP Router & Switch—declined 16% year-over-year (Y/Y) in 2Q24, recording a fourth consecutive quarter of double-digit contractions. Helping to explain the abysmal results are excess inventory, weaker demand in China, challenging 5G comparisons, and elevated uncertainty.
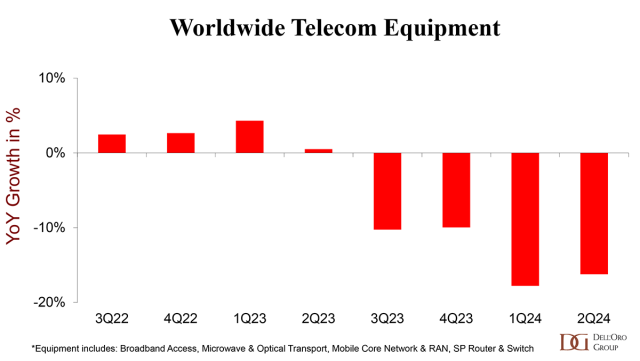
Regional output deceleration was broad-based in the second quarter of 2024, reflecting slower revenue growth on a Y/Y basis in all regions, including North America, EMEA, Asia Pacific, and CALA (Caribbean and Latin America). Varied momentum in activity in the first half was particularly significant in China – the total telecom equipment market in China stumbled in the second quarter, declining 17% Y/Y.
The downward pressure was not confined to a specific technology, and initial readings show that all six telecom programs declined in the second quarter. In addition to the wireless programs (RAN and MCN), which are still impacted by slower 5G deployments, spending on Service Provider Routers fell by a third in 2Q24.
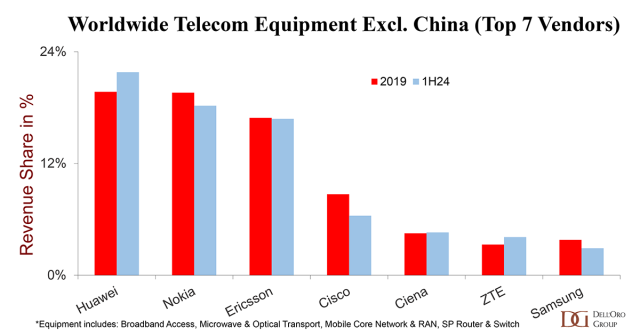
Supplier rankings were mostly unchanged. The top 7 suppliers in 1H24 accounted for 80% of the worldwide telecom equipment market and included Huawei, Nokia, Ericsson, ZTE, Cisco, Ciena, and Samsung. Huawei and ZTE combined gained nearly 3 percentage points of share between 2023 and 1H24.
Supplier positions differ slightly when we exclude the Chinese market. Despite the ongoing efforts by the U.S. government to curb Huawei’s rise, Huawei is still well positioned in the broader telecom equipment market, excluding China, which is up roughly two percentage points relative to 2019 levels.
- Even with the second half of 2024 expected to account for 54% of full-year revenues, market conditions are expected to remain challenging in 2024.
- The Dell’Oro analyst team collectively forecasts global telecom equipment revenues to contract 8 to 10% in 2024, even worse than the 4% decline in 2023.
3. U.S. Telcos Betting on Convergence and Scale To End Cable’s Broadband Reign
U.S. telcos have been very active the past two weeks with deals and partnerships.
- Verizon announced a $20B deal to acquire Frontier Communications and push the combined entity to a fiber footprint of 25 million homes and a fixed wireless footprint of approximately 60 million homes.
- AT&T announced partnerships with four open access network providers to help it expand the reach of its fiber services outside its existing wireline footprint. AT&T will serve as an ISP in these markets, delivering both residential and enterprise services via these partnerships. AT&T is on track to pass a minimum of 30 million homes with fiber by 2025 in its own footprint, as well as an additional 1.5 million homes through its Gigapower joint venture with BlackRock.
- AT&T has also quietly increased the availability of its Internet Air FWA (Fixed Wireless Access) services to over 130 markets, as It potentially positions the service to move beyond just a means of capturing existing DSL subscribers.
These deals follow on the heels of T-Mobile’s proposed acquisition of Lumos Networks, which is slated to pass 3.5 million homes with fiber by the end of 2028. Under the terms of the deal, Lumos will transition to a wholesale model with T-Mobile as the anchor ISP. This is exactly the type of arrangement T-Mobile has established with some of its other infrastructure partners. However, with its partial ownership of Lumos, T-Mobile can presumably generate better returns and healthier margins from its broadband service offerings. The joint venture also is consistent with T-Mobile’s goal of expanding its market presence and footprint without expending a significant amount of capital. In fact, if you take the $1.4B that T-Mobile will ultimately invest in Lumos as it increases its homes passed from 320K to 3.5M by the end of 2028, T-Mobile’s cost per home passed ends up being somewhat less than $500.
That $500 per home passed figure could be even lower should Lumos continue to secure additional American Rescue Plan Act (ARPA) Capital Project Fund grants as well as a portion of the $3.6 B in aggregate BEAD (Broadband Equity, Access, and Development) funding across North Carolina, South Carolina, and Virginia.
The primary reason for T-Mobile’s push into both direct fiber network ownership and partnerships with open access fiber providers is that the operator has over 1 million customers on a waiting list for its fixed wireless service. These customers can’t be served because they are in markets where T-Mobile does not have enough 5G capacity to serve them. As T-Mobile expands the reach of its fiber offering, it can not only provide service to these customers but also existing FWA subscribers. Once an FWA subscriber switches to T-Mobile Fiber, that opens the spectrum for additional FWA subscribers.
US telcos are moving quickly to expand the reach of their fiber, fixed wireless, and ISP services to complement their nationwide mobile networks because they smell blood among the largest cable operators. Telcos are disrupting the broadband market faster and more efficiently right now—a disruption that could very well be amplified by Federal and State subsidies.
With the rollout of 5G networks having had little impact on the profitability of mobile services, fixed wireless has emerged as the most successful use case for mobile network operators (MNOs) can monetize their excess 5G capacity. FWA’s timing couldn’t have been better, with inflation having increased from 2021 on, pushing subscribers to seek out more affordable—but still high quality—broadband service offerings. FWA hit the market providing a powerful combination of affordability, speed, and availability.
The success of FWA combined with overall fiber network expansions has given telcos a potent tool for not only the convergence of mobile and fixed broadband services but also the emergence of these services being offered on an almost nationwide basis. It’s pretty simple math. If you can offer a product or service to a larger number of end customers, the higher the likelihood of continued net subscriber additions, all other things being equal.
Even in markets where there is overlap between fixed wireless and that MNO’s own (or marketed) fiber broadband services, there isn’t really a danger of cannibalization, because the two services will very likely address very different subscribers. As the telcos’ ARPU (average revenue per unit) results have shown, subscribers are willing to pay more for fiber-based connectivity. In 2Q24, for example, AT&T announced that its fiber broadband ARPU is $69 and that the mix shift of its subscribers to fiber has pushed overall broadband ARPU up to $66.17, representing a 6% increase from 2Q23.
Meanwhile, in the second quarter, T-Mobile reported an ARPA figure of $142.54, which was up from $138.94 in 2Q23. Partially fueling that increase was an increase in the number of customers per account, due largely to the adoption of FWA services. Remember, T-Mobile prices and treats its FWA offering as an additional line of service, making it very simple to add to an existing T-Mobile account.
With a starting price point of $50 and typical download speeds ranging from 33-182 Mbps and upload speeds of 6-23 Mbps, T-Mobile is clearly targeting the low-mid cable broadband tiers—and having a great deal of success in converting those subscribers.
Going forward, the 1-2 punch of FWA and fiber will allow the largest telcos to have substantially larger broadband footprints than their cable competitors. Combine that with growing ISP relationships with open access providers and these telcos can expand their footprint and potential customer base further. And by expanding further, we don’t just mean total number of homes passed, but also businesses, enterprises, MDUs (multi-dwelling units), and data centers. Fiber footprint is as much about total route miles as it is about total passings. And those total route miles are, once again, increasing in value, after a prolonged slump.
For cable operators to successfully respond, consolidation likely has to be back on the table. The name of the game in the US right now is how to expand the addressable market of subscribers or risk being limited to existing geographic serving areas. Beyond that, continuing to focus on the aggressive bundling of converged services, which certainly has paid dividends in the form of new mobile subscribers.
Beyond that, being able to get to market quickly in new serving areas will be critical. In this time of frenzied buildouts and expansions, the importance of the first mover advantage can not be overstated.
The push and pull of broadband and wireless subscribers isn’t expected to slow down anytime soon. Certainly, with inflation continuing to put pressure on household budgets, consumers are going to be focused on keeping their communications costs low and looking for value wherever they can find it. That means we are returning to an environment where subscribers take advantage of introductory pricing on services only to switch providers to extend that introductory pricing once the initial offer expires. That shifting and its expected downward pressure on residential ARPU will likely be countered by increasing ARPUs at some providers as they move existing DSL customers to fiber or, in the case of cable operators, move customers to multi-gigabit tiers.
The US broadband market is definitely in for a wild ride over the next few years as the competitive landscape changes across many markets. The net result is certain to be shifts in market share and ebbs and flows in net subscriber additions depending on consumer sentiment. One thing that will remain constant is that value and reliability will remain key components of any subscription decision. The providers that deliver on that consistently will ultimately be the winners.
References:
Ethernet Campus Switch Revenues Plunge by 30 Percent in 2Q 2024, According to Dell’Oro Group
US Telcos Betting on Convergence and Scale To End Cable’s Broadband Reign
Dell’Oro: Private RAN revenue declines slightly, but still doing relatively better than public RAN and WLAN markets
Dell’Oro: Campus Ethernet Switch Revenues dropped 23% YoY in 1Q-2024
Dell’Oro: RAN revenues declined sharply in 2023 and will remain challenging in 2024; top 8 RAN vendors own the market
Dell’Oro: Broadband Equipment Spending to exceed $120B from 2022 to 2027
Dell’Oro: RAN Market to Decline 1% CAGR; Mobile Core Network growth reduced to 1% CAGR
Dell’Oro: Optical Transport market to hit $17B by 2027; Lumen Technologies 400G wavelength market
Nvidia enters Data Center Ethernet market with its Spectrum-X networking platform
Nvidia is planning a big push into the Data Center Ethernet market. CFO Colette Kress said the Spectrum-X Ethernet-based networking solution it launched in May 2023 is “well on track to begin a multi-billion-dollar product line within a year.” The Spectrum-X platform includes: Ethernet switches, optics, cables and network interface cards (NICs). Nvidia already has a multi-billion-dollar play in this space in the form of its Ethernet NIC product. Kress said during Nvidia’s earnings call that “hundreds of customers have already adopted the platform.” And that Nvidia plans to “launch new Spectrum-X products every year to support demand for scaling compute clusters from tens of thousands of GPUs today to millions of DPUs in the near future.”
- With Spectrum-X, Nvidia will be competing with Arista, Cisco, and Juniper at the system level along with “bare metal switches” from Taiwanese ODMs running DriveNets network cloud software.
- With respect to high performance Ethernet switching silicon, Nvidia competitors include Broadcom, Marvell, Microchip, and Cisco (which uses Silicon One internally and also sells it on the merchant semiconductor market).

Image by Midjourney for Fierce Network
…………………………………………………………………………………………………………………………………………………………………………..
In November 2023, Nvidia said it would work with Dell Technologies, Hewlett Packard Enterprise and Lenovo to incorporate Spectrum-X capabilities into their compute servers. Nvidia is now targeting tier-2 cloud service providers and enterprise customers looking for bundled solutions.
Dell’Oro Group VP Sameh Boujelbene told Fierce Network that “Nvidia is positioning Spectrum-X for AI back-end network deployments as an alternative fabric to InfiniBand. While InfiniBand currently dominates AI back-end networks with over 80% market share, Ethernet switches optimized for AI deployments have been gaining ground very quickly.” Boujelbene added Nvidia’s success with Spectrum-X thus far has largely been driven “by one major 100,000-GPU cluster, along with several smaller deployments by Cloud Service Providers.” By 2028, Boujelbene said Dell’Oro expects Ethernet switches to surpass InfiniBand for AI in the back-end network market, with revenues exceeding $10 billion.
………………………………………………………………………………………………………………………………………………………………………………
In a recent IEEE Techblog post we wrote:
While InfiniBand currently has the edge in the data center networking market, but several factors point to increased Ethernet adoption for AI clusters in the future. Recent innovations are addressing Ethernet’s shortcomings compared to InfiniBand:
- Lossless Ethernet technologies
- RDMA over Converged Ethernet (RoCE)
- Ultra Ethernet Consortium’s AI-focused specifications
Some real-world tests have shown Ethernet offering up to 10% improvement in job completion performance across all packet sizes compared to InfiniBand in complex AI training tasks. By 2028, it’s estimated that: 1] 45% of generative AI workloads will run on Ethernet (up from <20% now) and 2] 30% will run on InfiniBand (up from <20% now).
………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.fierce-network.com/cloud/data-center-ethernet-nvidias-next-multi-billion-dollar-business
https://www.nvidia.com/en-us/networking/spectrumx/
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
Data Center Networking Market to grow at a CAGR of 6.22% during 2022-2027 to reach $35.6 billion by 2027
LightCounting: Optical Ethernet Transceiver sales will increase by 40% in 2024
Dell’Oro: Campus Ethernet Switch Revenues dropped 23% YoY in 1Q-2024
Worldwide Campus Ethernet Switch [1.] revenues plummeted by 23% YoY in the 1st quarter of 2024 to a 2-year low, according to the Dell’Oro Group.
- The only two vendors that grew campus switch revenues year over year were Santa Clara, CA based Arista Networks and Ubiquiti [2.].
- Cisco’s campus switch revenues fell more than the worldwide average.
Note 1. With higher demand from new use cases for wired connectivity such as automation, analytics, and network visibility, and the need for new access switches to aggregate Wireless LAN access points, Dell’Oro Group is offering in-depth analysis specifically on Ethernet Switches built and optimized for deployment outside the data center, for the purpose of connecting users and things to the corporate Local Area Network (LAN).
“Basically, campus switches are really the networking gear to connect users and devices and laptops,” said Sameh Boujelbene, VP with Dell’Oro Group. “Access points are probably the number one application.”
………………………………………………………………………………………………………..
Note 2. Although headquartered in New York, NY, Ubiquiti wrote in a 2019 SEC filing:
“We use contract manufacturers, primarily located in China, Vietnam and Taiwan, to manufacture our products. Our relationships with contract manufacturers allow us to conserve working capital, reduce manufacturing costs and minimize delivery lead times while maintaining high product quality and the ability to scale quickly to handle increased order volume. Over the long term, our contract manufacturers are not required to manufacture our products for any specific period or in any specific quantity. If necessary, we expect that it would take approximately 3 to 6 months to transition manufacturing, quality assurance and shipping services to new providers.”
………………………………………………………………………………………………………………………
“Vendor backlogs of campus switch orders have now been completely run down, and the market is in a multi-quarter digestion cycle,” said Siân Morgan, Research Director at Dell’Oro Group. “The shipments of most port speeds declined, and the Average Sales Price (ASP) also dropped on a YoY basis.
“However, in 1Q 2024, Arista had its third sequential quarter of (market) share gain, growing Campus Switch sales to large enterprises.
On the downside, Cisco’s Campus Switch shipments contracted sharply. This reduction contrasts with their shipments in 2023, when Cisco opened the “floodgate” for Catalyst and Meraki port shipments which had been on backorder,” added Morgan.

Additional highlights from the 1Q 2024 Ethernet Switch – Campus Report:
- The contraction in campus switch sales was broad-based across all regions, with the exception of Central America-Latin America (CALA).
- Some vendors bucked the price trend and were able to grow port ASPs thanks to richer product mixes.
- 5/5.0 Gbps switch ports are expected to return to growth as shipments of Wi-Fi 7 Access Points accelerate.
The Dell’Oro Group Ethernet Switch – Campus Quarterly Report offers a detailed view of Ethernet switches built and optimized for deployment outside the data center, to connect users and things to the Local Area Networks. The report contains in-depth market and vendor-level information on manufacturers’ revenue, ports shipped and average selling prices for both Modular and Fixed, and Fixed Managed and Unmanaged Ethernet Switches (100 Mbps, 1/2.5/5/10/25/40/50/100/400 Gbps), Power-over-Ethernet, plus regional breakouts as well as split by customer size (Enterprise vs. SMB) and vertical segments.
To purchase these reports, email [email protected]
References:
Campus Ethernet Switch Revenues Crash to a Two-Year Low in 1Q 2024, According to Dell’Oro Group
Dell’Oro: Optical Transport, Mobile Core Network & Cable CPE shipments all declined in 1Q-2024
Dell’Oro: Broadband network equipment spending to drop again in 2024 to ~$16.5 B
Highlights of IEEE Triple Milestone Event – May 20, 2024 at CHM
Three very significant IEEE Milestones were celebrated May 20th at the Computer History Museum (CHM) in Mt. View, CA. They were as follows:
- Google’s PageRank Algorithm and the Birth of Google. The PageRank Algorithm shaped our access to digital content and put Google on the map as an established web search company.
- The 1974 IEEE Computer Society paper on TCP (“Transmission Control Protocol (TCP) Enables the Internet”) authored by Vint Cerf and Bob Kahn.
- The IEEE 802 LAN/MAN Standards Committee which generated and maintains the standards for IEEE 802.3 (Ethernet), 802.11 (Wi-Fi®), 802.15 (early Bluetooth), among others.
Among newer and important IEEE 802 projects:
- IEEE 802.1 Time Sensitive Networks Task Group provides standards for deterministic connectivity through IEEE 802 networks (i.e., guaranteed packet transport with bounded latency, low packet delay variation, and low packet loss). It’s being used at CERN’s Large Hadron Collider (LHC) – the world’s largest and most powerful particle accelerator.
- IEEE 802.19 Wireless Coexistence Working Group deals with coexistence between unlicensed wireless networks. Many of the IEEE 802 wireless standards use unlicensed spectrum and hence need to address the issue of coexistence when operating in the same unlicensed frequency band in the same location.
In addition, four other ground breaking IEEE milestones were briefly discussed:
- Development of the Commercial Laser Printer, 1971-1977 Ron Rider, VP of Digital Imaging (retired), Xerox PARC
- Xerox Alto Establishes Personal Networked Computing, 1972-1983 John Shoch, Office Systems Division President (retired), Xerox PARC
- Ethernet Local Area Network (LAN), 1973-1985.
- ALOHAnet Packet Radio Data Network, 1971 Bob Metcalfe, Co-Inventor of Ethernet at Xerox PARC and Frank Kuo, University of Hawaii.
Dedication of the above 4 Milestones:
The first three milestones were dedicated at SRI PARC on Friday, May 17th. The fourth milestone ALOHAnet led directly to the development of Ethernet.
………………………………………………………………………………………………………………..
You can watch a replay of this four hour event here.
………………………………………………………………………………………………………………..
Of particular significance to IEEE Techblog readers:
- Vint Cerf, who co-authored the TCP (Transmission Control Protocol) paper with Bob Kahn and is often called a “father of the Internet,” described the history of the Internet. He said that Arpanet and ALOHAnet led the way to the Internet, which is celebrating its 50th anniversary this month with the IEEE Computer Society’s publication of the TCP paper.
- In addition to new enabling technologies (e.g. hollow core fiber and LEO satellite connectivity) Vint said we need new policies for economic, social and legal frameworks to make the Internet safer and more secure. Also, to hold bad actors responsible for malicious behavior. The Internet Society and others need to educate regulators to make these types of changes.
- Past and present executives of the IEEE 802 LAN/MAN Standards Committee discussed the success of Ethernet (802.3), Wi-Fi (IEEE 802.11), Wireless Specialty Networks (IEEE 802.15), MAC Bridging (IEEE 802.1) which were developed by IEEE 802 LMSC. The purpose and role of the Radio Regulatory Technical Advisory Group, which supports the work of various 802 wireless standards, was also explained.
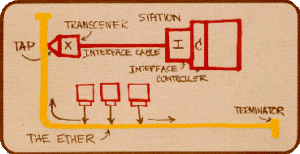
- Ethernet co-inventor Bob Metcalfe provided a genesis of Ethernet which he co-invented with David Boggs while at Xerox in 1973. Working on Project MAC at MIT in 1970, Metcalfe used the Arpanet to connect dumb terminals to time shared computers. After he joined Xerox PARC, Bob read a paper about the ALOHAnet network at the University of Hawaii by Norm Abramson and was so intrigued that he visited there for one month to gain a deeper understanding of that innovative radio packet network. It used randomized retransmissions after a collision. The Ethernet MAC protocol (Carrier Sense Multiple Access with Collision Detection) he developed used similar ALOHAnet concepts. At 2.94 Mb/sec, the first Ethernet was 306.25 times faster than ALOHAnet (9.6 Kb/sec). That’s because it ran on 0.5 inch coaxial cable rather than radio airwaves. The 2.94 Mb/sec rate (vs 3 Mb/sec) was chosen due to the size limitation of the Ethernet circuit card which could not include a 3 Mb/sec crystal oscillator. That first 1973 version of Ethernet was used at Xerox to enable Alto GUI workstations (predecessor to the PC) to share a networked laser printer and for Xerox PARC engineers to communicate via in house email.
Addendum: Metcalfe did not mention that the hardware for the 10M b/sec version of Ethernet, which in 1985 became the IEEE 802.3 10Base5 CSMA/CD standard, was designed at Xerox by Robert Garner and Ron Crane, RIP.
In April 2022, IEEE SV Tech History committee (founded and initially chaired by this author 2013-2015), presented an event on the history of Ethernet at Xerox. The event description is here and the video is here. Unsung Hero of Ethernet Geoff Thompson moderated this superb panel session. It was originated by this author to provide well deserved recognition for another Unsung Hero- the late and great Ron Crane who (with Robert Garner) co-designed Xerox’s 10 Mb/sec Ethernet circuit card for the Xerox Star workstation as well as 3COMs breakout product – Etherlink circuit card (product # 3C100) for the IBM PC, which shipped in September 1982.
References:
https://ieeetv.ieee.org/
https://spectrum.ieee.org/ethernet-ieee-milestone
https://ethernethistory.typepad.com/my_weblog/2017/08/in-memory-of-ron-crane.html
Ethernet Alliance multi-vendor interoperability demo (10GbE to 800GbE) at OFC 2023
The Ethernet Alliance, a global consortium dedicated to progressing Ethernet technologies (albeit, only the MAC frame format is left from the original 10BaseT Ethernet standard), this week exhibited a multivendor interoperability demonstration at the OFC 2023 conference and exhibition in San Diego, CA.
–>Please see References 1. and 2. below for the detailed multi-vendor interoperability demo diagrams.
Featuring 18 different participating member companies, the Ethernet Alliance interoperability demo spans diverse Ethernet technologies ranging from 10 Gigabit Ethernet to 800GbE. The interoperability display features a live network between the booths of Ethernet Alliance and the Optical Internetworking Forum, Exfo, Spirent Communications, and Viavi Solutions.
The network leverages single-mode optical fibers with high-speed traffic originating from an array of switches, routers, interconnects, including copper and optical cables. It also employs various interconnects using multiple pluggable form factors such as OSFP, QSFP-DD, QSFP, and SFP, and multiple interface types including OIF 400ZR, OpenZR+ MSA 400ZR+, and 800G-ETC-CR8.
The Ethernet Alliance also spent time highlighting its roadmap, which sees continued advancement in the speed, reliability, and use cases for the networking protocol across multiple sectors. The goal of the organization is not to invent new standards, but rather to help foster their adoption and deployment in an interoperable approach.

Source: Ethernet Alliance
……………………………………………………………………………………………………………………………….
“We’re now at the half-century mark, and Ethernet’s star continues to rise. As a profoundly resilient technology that’s getting progressively faster, it is an innovation engine that drives market diversification and fuels business growth. If you think about the journey from invention to deployment, what we do is we try to show that the technology does work and it is mature enough that it can be deployed,” said Peter Jones, chairman, Ethernet Alliance.
In the enterprise market, demand for 10 GbE-based Ethernet remains strong and there is also some growth for 25 GbE, which is intended more for servers. Ethernet also has 100 GbE and 400 GbE speeds to support larger enterprise and campus needs.
Network operators are always looking for more network capacity and speed and to that end 800 GbE and soon 1.6 Tb/s Ethernet (TbE) will fit the bill.
Jones said that in the early days, the goal for each new set of specifications was to provide 10-times the speed, at only three-times the price of the existing specification. Over time what has occurred is the standards have not just been racing forward to ever faster speeds, but rather are being tailored to meet the price and performance characteristics that a given use case requires.
For example, work is ongoing to help bring Ethernet into more industrial use cases as a solution for serial connections. Ethernet is also increasingly finding its way into automotive use cases as modern vehicles rely on growing levels of compute capacity to operate and communicate.
The Ethernet Alliance is also working on certification efforts for Power-over-Ethernet (PoE). While there have long been PoE standards, there hasn’t been a full-scale certification effort in the same way that there is for Wi-Fi in the wireless world. Jones said that while PoE mostly works today, there have been some instances of vendor technologies that weren’t interoperable.
“We really want people to be able to buy certified devices because we want to preserve the idea that Ethernet just works and we were starting to see that breaking down with PoE,” Jones said. “Ethernet is the most important technology that no one ever sees. Very few people that use the internet understand that Ethernet is the key part of it,” he added.
“One of OFC’s highlights was live interoperability demonstrations from leading optics companies running over OFCnet,” said OFC chairs Chris Cole, Coherent Corporation; Ramon Casellas, Centre Tecnològic de Telecomunicacions de Catalunya; and Ming-Jun Li, Corning Incorporated.
References:
https://ethernetalliance.org/wp-content/uploads/2022/09/EA_Ecosystem-Demo.pdf
https://optics.org/news/14/3/17
https://www.sdxcentral.com/articles/analysis/why-you-should-never-bet-against-ethernet/2023/03/