Cisco
2026 OCP Summit: Full-Stack AI Networking Silicon from Nvidia/Cisco and Broadcom; Ethernet vs InfiniBand Interconnects
Executive Summary:
At the 2026 Open Compute Project (OCP) Global Summit in San Jose, CA this week, the multi-vendor push for open, gigawatt-scale AI networks reached a critical tipping point as Cisco and Broadcom deployed massive 102.4 Tbps Ethernet fabrics to challenge Nvidia’s proprietary grip. These and other networking silicon companies are responding to what Cisco executives call a new “Network Supercycle” triggered by agentic AI workloads. The architectural battle lines for gigawatt-scale AI infrastructure were drawn between open ecosystems and proprietary stacks. Broadcom championed the open alternative by introducing its 102.4 Tbps Tomahawk 6 switching platform and third-generation TH6-Davisson Co-Packaged Optics (CPO) to drastically reduce power consumption across clusters exceeding 100,000 accelerators.
- Cisco accelerated this so called “Network Supercycle” by highlighting massive hyperscaler traction for its custom Silicon One P200 routing chips, which Microsoft and Alibaba Cloud have integrated into their custom architectures to handle dense, geographically distributed AI workloads.
- Nvidia defended its market dominance with its Quantum-3 InfiniBand switches and native sub-2µs point-to-point latency; however, despite InfiniBand technically originating as an open industry standard, Nvidia’s sole manufacturing monopoly, closed software integration with CUDA, and proprietary extensions like SHARP have effectively turned it into a vertically locked, high-premium ecosystem. This strict architectural division has forced hyperscalers to choose between the seamless, turnkey acceleration of Nvidia’s proprietary pipeline for tight scale-up GPU environments, or the superior multi-vendor economics, flexibility, and anti-lock-in guardrails offered by Broadcom and Cisco’s open Ethernet frameworks.
- Broadcom launched an open Ethernet fabric architecture designed for gigawatt-scale clusters scaling past 100,000 parallel AI accelerators, showcasing innovations like the 102.4 Tbps Tomahawk 6 and Jericho 4 silicon. The company also introduced TH6-Davisson Co-Packaged Optics, Thor Ultra 800G NICs, and Open Rack Version 3 blueprints to compete with proprietary InfiniBand stacks. You can read more about Broadcom’s announcements at the official corporate site.
I. Cisco has worked with Nvidia on an Ultra-Dense Small Form-Factor Pluggable (USFP), a transceiver that conforms to the Octal Small Form-Factor Pluggable (OSFP) footprint that governs most high-speed datacenter transceivers today. Cisco said USFP enables the industry to accelerate AI by building on the ecosystem models that have powered today’s AI networks. By combining a path to higher-capacity fabrics and improved efficiency with familiar operational practices, USFP helps customers scale AI infrastructure while maintaining the flexibility, interoperability, and consistency required at scale.
Unlike other optical transceivers, the leading versions of which are designed to handle 200-Gb/s today, USFP provides 400-Gb/s full-duplex data rates over 16 lanes with 32 in the future, achieving transmission rates from 6.4 Tb/s up to 12.8 Tb/s. Nvidia said scalability is facilitated by an internal connector technology that reduces wear and improves signal integrity. USFP works with switches and SmartNICs. The new USFP is designed to save power without requiring liquid cooling, something that other solutions feature—most notably Arista Network’s eXtra-dense Pluggable Optics (XPO) solution, which packs its own liquid-cooled cold plate.
Cisco and NVIDIA claim that, compared to an OSFP module supporting 200-Gb/s, the new USFP has approximately 1.3X the power efficiency. At the same time, the USFP matches the footprint of today’s OSFP transceivers, making for an easier transition than the new form-factor XPO, which Arista says improves density by a factor of 4X. The two companies said they’ll work with a “community-led multi-source project” to create an open industry specification for USFP. Members of that “community” were not identified. 
Source: NVIDIA and Cisco
In a blogpost, Cisco executives Bill Gartner, SVP and GM, Optical Systems and Optics, and Will Eatherton, SVP Networking Engineering, stated:
“To help customers scale AI infrastructure efficiently and sustainably, Cisco takes a full-stack, co-designed platform approach that combines silicon, high-density systems, optics, software, and operational expertise. USFP reflects that philosophy. Rather than a standalone innovation, it is part of a broader platform vision that advances scale, efficiency, and performance while preserving the deployment, serviceability, and lifecycle models customers depend on.”
………………………………………………………………………………………………………………………………………………………………………
Cisco also highlighted massive cloud traction for its custom Silicon One P200 routing chip, which provides 51.2 Tb/s of high-buffering switching capacity designed to seamlessly link vast, geographically distributed AI data sites. Microsoft and Alibaba Cloud.
“As our infrastructure demands grow, the P200’s robust architecture provides the speed and enhanced buffering capabilities necessary to address the increasing scale of our cloud and high-performance services,” said Anand Ramakrishna, Corporate Vice President, Engineering, Microsoft, in a statement.
Alibaba has embedded the Silicon One P200 into its Quantum Cat router. “We paired Cisco’s silicon with Alibaba’s custom systems and the SONiC operating system,” stated Dennis Cai, Vice President, Head of Network Infrastructure, Alibaba Cloud Intelligence Group. “This combination … delivers the flexibility and operational power required for some of the world’s most demanding networks.”
Cisco also said that its previously announced 102.4-Tb/s Silicon One G300 is now available for customer sampling, with some G300-powered systems shipping to customers. Another chip, the 51.2-Gb/s G302, is designed to function at top-of-rack (ToR) deployments for scale up or scale across infrastructure.
Cisco’s OCP announcements indicate the networking market leader’s efforts to continue unifying its full-stack strategy around its own silicon, switching, and software, a tack that so far has proved successful.
………………………………………………………………………………………………………………………………………………………………………
-
- Tomahawk 6 & Jericho 4 Silicon: Broadcom demonstrated live partner systems running its 102.4 Tbps Tomahawk 6 switching platform for low-latency frontend fabrics, alongside Jericho 4 silicon for deep-buffered scale-out routing.
- TH6-Davisson Co-Packaged Optics (CPO): This third-generation CPO architecture integrates optics directly onto the switch substrate. By eliminating internal copper traces to traditional transceivers, it drastically reduces power consumption per gigabit.
- Thor Ultra 800G NICs: These high-performance network interface cards support line-rate 800 Gbps RoCE (RDMA over Converged Ethernet) throughput, accelerating memory-to-memory data transfers while bypassing CPU overhead.
- ORV3 Ecosystem Blueprint: Broadcom aligned its PCIe Gen 6 switches, retimers, and optical components with the Open Rack Version 3 (ORV3) and Open Rack Wide standards, supporting dense liquid-cooled rack configurations.
- Open Standard Commitments: Under standardizing frameworks like ESUN (Ethernet for Scale-Up Networking), Broadcom pitched open Ethernet as the primary economic and physical alternative to proprietary InfiniBand fabrics for frontier AI clusters.
- Enterprise LAN and Client-to-Server Interconnects: Connects standard server racks to local networks, user devices, and the broader internet.
- Front-End Data Center Networks: Manages standard cloud computing workloads, database queries, and multi-tenant hosting environments.
- Emerging AI Backends (via RoCEv2): Through frameworks like the Ultra Ethernet Consortium (UEC) and platforms like NVIDIA’s Spectrum-X, modern 800Gbps Ethernet is increasingly deployed by hyperscalers (such as Meta and xAI) for AI clusters due to its superior Total Cost of Ownership (TCO) and rapid innovation cycle.
- Ecosystem and TCO: Leverages a massive global supply chain and existing IT skills, avoiding the proprietary premium and single-vendor lock-in common with InfiniBand.
- RoCE Adaptability: Uses RDMA over Converged Ethernet (RoCEv2) along with Priority Flow Control (PFC) to emulate the low-latency, lossless advantages of InfiniBand over traditional network lines.
-
- Header Optimization: Standard Ethernet headers carry massive protocol overhead that increases latency for small data frames. ESUN implements a streamlined, compact 4-byte ESUN Header (EH) to maximize packet efficiency, strip away unneeded bytes, and drastically lower transport latency.
- Lossless Reliability & Tail Latency Control: AI workloads depend heavily on synchronized “collective” mathematical operations where a single dropped packet can stall the entire training run. ESUN implements advanced Credit-Based Flow-Control (CBFC) to guarantee zero packet loss and tightly manage jitter and tail latency.
- Decoupled Multi-Vendor Interoperability: ESUN focuses strictly on how network switches and network interface cards (NICs) handle frame formatting and packet switching. By keeping the fabric protocol-agnostic, it allows accelerators to define their own host-side transport layers independently, allowing operators to mix-and-match silicon suppliers.
| Networking Initiative | Governing Body | Primary Focus | Role in the AI Ecosystem |
|---|---|---|---|
| ESUN | Open Compute Project (OCP) | Scale-Up Network Fabric (L2/L3 switching and framing) | Optimizes the actual network switches and packet formatting inside the physical rack. |
| SUE-T (Scale-Up Ethernet Transport) | Open Compute Project (OCP) | Scale-Up Endpoint Transport (XPU-to-XPU communication) | A specialized transport protocol layer designed to work natively inside the ESUN switch framework to handle load balancing and transaction scheduling. |
| UEC (Ultra Ethernet Consortium) | Linux Foundation | Data Center-Wide Networks (Initially Scale-Out, expanding to Scale-Up) | A broader, top-to-bottom architecture that ESUN actively pulls specifications and best practices from to align with global standards. |
III. Ethernet vs. InfiniBand for Interconnects:
The structural battle between Broadcom’s open Ethernet platform and Nvidia’s proprietary InfiniBand fabric [1.] are direct competitors for backend compute & storage interconnects in data centers, high-performance computing (HPC), and AI clusters within data centers. The technical architectures, advantages, and philosophies of both approaches contrast sharply.
Note 1. InfiniBand by itself is an open, industry-standard specification managed by the InfiniBand Trade Association (IBTA). Nvidia acquired its primary architect, the Israeli company Mellanox, for $6.9 billion in 2019. However, in the context of modern AI data centers, Nvidia has effectively turned InfiniBand into a de facto proprietary ecosystem through vendor monopoly and closed optimizations. Here’s how that happened:
-
- Vendor Monopoly: Nvidia is the sole manufacturer of AI-class InfiniBand silicon. Competitors like Intel abandoned the technology, while Broadcom and Cisco focus entirely on Ethernet.
- Proprietary Extensions: Nvidia injects closed-source hardware features like SHARP (which offloads AI math directly onto switches) that require a strict end-to-end Nvidia hardware pipeline.
- Software Lock-In: Management and orchestration tools are tightly bound to Nvidia’s proprietary CUDA and Unified Fabric Manager (UFM) stacks.
| Aspect | The Theoretical Standard | The Modern AI Reality |
|---|---|---|
| The Spec | Open, industry-standard managed by the IBTA. | Monopolized by a single vendor (Nvidia). |
| The Silicon | Anyone can build an InfiniBand chip. | Nvidia is the sole manufacturer of AI-class InfiniBand. |
| The Interconnect | Interoperable with various hardware platforms. | Tightly coupled with Nvidia GPUs and CUDA via proprietary extensions like SHARP. |
| Feature / Metric | Broadcom Open Ethernet Platform | Nvidia Proprietary InfiniBand Fabric |
|---|---|---|
| Architectural Philosophy | Open ecosystem. Decouples compute from networking to prevent vendor lock-in. | Vertically integrated. Tightly couples GPUs, switches, and software for a turn-key solution. |
| Top Raw Bandwidth | 102.4 Tbps single-chip switching capacity via Tomahawk 6. Supports native 800G per port. | 51.2 Tbps single-chip switching capacity on the latest Quantum-3 switches (400G per port). |
| Latency Profile | Average < 5µs using RoCE v2. Drops significantly via UEC 1.1 optimizations. | Native sub-2µs point-to-point latency with near-zero jitter. |
| Congestion & Reliability | Uses packet spraying, adaptive routing, and link-level retries via Ultra Ethernet Consortium (UEC). | Native credit-based flow control. Prevents buffer overflows at the hardware level for a completely lossless fabric. |
| Optical Integration | Leading the industry with Co-Packaged Optics (CPO) integrated onto the switch substrate. | Moving toward CPO integration in upcoming H2 2026 platform refreshes. |
| Relative Costs | Standard commoditized pricing. Roughly 1/3 the hardware cost of InfiniBand. | Premium pricing tied directly to Nvidia’s exclusive compute bundle. |
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.futuriom.com/articles/news/cisco-shows-full-stack-networking-strategy-at-ocp/2026/10
https://blogs.cisco.com/news/cisco-and-nvidia-announce-usfp-expanding-the-path-to-ai-connectivity
https://www.broadcom.com/company/news/resources/media-kits/2026-ocp-global-summit
Cisco Execs: New “Network Supercycle” as Agentic AI Workloads Reshape Telecom Infrastructure
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Huawei’s Ascend Silicon Roadmap Extends From AI Chips to Cluster-Scale Infrastructure
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
Meta’s “Iris” AI Chip for MTIA: Implications for Telecom-Grade Optical Networking, DCI and High Capacity Ethernet Fabrics
Dell’Oro: High End Routing Revenue Increased 25% YoY in 2Q-2026; Cisco’s Resurgence due to Silicon One ASIC
According to a recently published report by Dell’Oro Group, High End Routing and Aggregation equipment revenue grew 25% year-over-year in the second quarter of 2026, fueled by stronger demand across all regions and customer segments. Notably, vendor direct sales revenue to cloud providers surged 94 percent year-over-year during the same quarter, driven by hyperscalers’ AI infrastructure push.
“Demand for High End Routers is growing at a very fast pace,” said Jimmy Yu, Vice President at Dell’Oro Group. “One reason for this accelerated growth is that hyperscalers are building more data centers and adding capacity to existing ones. This not only drives direct sales to cloud providers for data center interconnect and cloud access, but also indirect sales to communication service providers that build the wide area network and connections to enterprises,” added Yu.

Additional highlights from the 2Q 2026 High End Routing and Aggregation Report:
- For a fifth consecutive quarter, Core Router revenue grew at a high double-digit rate, reaching a new record revenue level in 2Q 2026. Edge Router and Enterprise High End Router also posted strong results this quarter, with revenue growing 20 percent and 31 percent, respectively.
- All three customer verticals—communication service provider, cloud provider, and enterprise/public—grew at a double-digit rate in the quarter. Communication service providers accounted for the majority of router revenue, followed by cloud providers.
- All of the major regions—North America, EMEA, Asia Pacific, and Latin America—grew at a double-digit rate in the quarter. The highest growth rates occurred in North America and Latin America.
………………………………………………………………………………………………………………………………………………………………………………………………………….
Analysis of Cisco’s Resurgence:
Silicon One has been a major enabler of Cisco’s improved position in high-end routing, particularly in hyperscale and AI-oriented backbone/interconnect deployments. But it is not the sole explanation, and “market-share gain” needs to be segmented carefully by routing category, geography, and customer type.
Cisco’s Silicon One strategy gave the company a competitive, internally controlled routing-silicon platform—initially embodied in the Cisco 8000 family—that combines high forwarding capacity, deep buffering, large-scale routing tables, programmable packet processing, and a common architecture spanning router and switch roles. Those capabilities matter directly in the high-end provider/core-routing market, where Cisco competes principally with Juniper, Nokia, and Huawei, as well as with white-box/merchant-silicon architectures in webscale environments. Cisco itself said Silicon One-based 8000 systems contributed to growth in its core-routing portfolio and webscale-provider business in fiscal 2024.
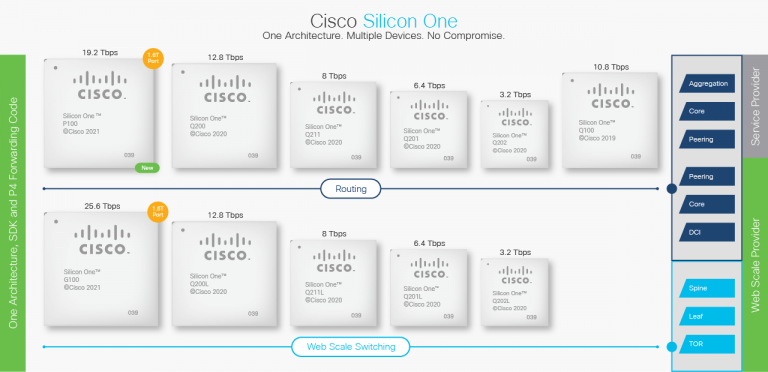
Image Credit: Cisco
……………………………………………………………………………………………………………………………………………………….
Silicon One changed Cisco’s proposition in several ways:
The original Q100 Silicon One device was introduced with roughly 10 Tb/s-class routing capacity and was designed for high-scale routing, programmable forwarding, deep buffering, and large distributed-router configurations. Cisco positioned it as a common platform capable of replacing different specialized roles—line-card processing, route processing, and fabric functions—with a unified architecture.
Subsequent devices increased the technical competitiveness of the platform. Cisco’s P100, for example, was positioned as a 19.2-Tb/s full-duplex routing ASIC with 112G SerDes, deep buffers, large tables, and a 28.8-Tb/s, 36-port 800GbE line-card design.
Silicon One is likely the technical foundation of Cisco’s recovery or expansion in high-end routing, while AI demand and optical/system integration are the near-term accelerants.
The AI impact is newer—and real:
The recent acceleration in Cisco’s high-performance networking business is increasingly tied to AI infrastructure, but this should not be confused with conventional service-provider routing share.
Cisco’s more recent Silicon One products span distinct roles:
-
G-series, such as G200, are particularly associated with high-radix Ethernet switching for AI back-end networks.
-
P-series, including P200, are deep-buffer routing silicon targeted at scaling AI infrastructure across data centers, not merely inside a single cluster.
-
Q-series devices have been central to Cisco 8000 routing platforms for service-provider and webscale use.
Cisco reported that approximately 60% of its fiscal-2026 AI-infrastructure orders were Silicon One-based systems, with the other 40% optics. It also attributed hyperscaler success to the scalability and programmability of Silicon One and said it expected further design wins around G300, G200, and P200 devices. This supports the conclusion that Silicon One is now central to Cisco’s high-performance networking momentum.
However, the G200-driven surge is more directly a data-center AI Ethernet switching story than proof of a broad-based win in the traditional carrier high-end-routing market. Industry reporting described G200 as the core of Cisco’s AI systems orders in 2025, aimed at Ethernet AI-cluster fabrics.
Attributing market-share progress wholly to the ASIC would overstate the case. Silicon One is necessary competitive infrastructure, but routing wins still depend on a larger system proposition:
-
IOS XR and operational maturity. Large carriers buy a software, automation, telemetry, reliability, and lifecycle platform—not merely a forwarding chip.
-
Optics integration. Cisco’s Acacia coherent-optics assets and pluggable optics portfolio strengthen the routed-optical/network-interconnect proposition. Cisco reported service-provider-routing and Acacia-optics growth together in fiscal 2026.
-
400G/800G upgrade cycles. Capacity migration creates opportunities for vendors with credible density, power, and system-roadmap advantages.
-
AI data-center interconnection. Distributed AI introduces demand for high-capacity routed interconnects between clusters, campuses, and data centers—an adjacent growth vector that favors high-scale routing platforms.
-
Supply-chain and product control. Owning silicon lets Cisco coordinate ASICs, systems, software, and optics rather than aligning its roadmap entirely to merchant-chip availability.
-
Commercial execution. Hyperscaler design wins, account relationships, pricing, support, and ability to meet qualification requirements remain decisive.
Cisco’s stated plan to extend Silicon One throughout its high-performance networking systems by fiscal 2029 makes clear that it regards vertical integration as a strategic differentiator rather than merely a component substitution.
In conclusion, Cisco’s gain in high-end routing is substantially enabled by Silicon One because the ASIC family restored Cisco’s competitiveness in bandwidth density, routing scale, buffering, programmability, and power efficiency—especially in webscale, cloud, and emerging AI interconnect opportunities. But the resulting commercial gains reflect the combined offer of Silicon One, Cisco 8000 platforms, IOS XR, coherent optics, customer relationships, and favorable upgrade cycles—not the ASIC in isolation.
………………………………………………………………………………………………………………………………………………………………………………………
References:
High End Routing and Aggregation Market Grew 25 Percent in 2Q 2026, According to Dell’Oro Group
https://blogs.cisco.com/sp/ciscosilicononep100announcement
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
Cisco Execs: New “Network Supercycle” as Agentic AI Workloads Reshape Telecom Infrastructure
Cisco report: Agentic AI to reshape WAN traffic, AI inference will be ~25% of total traffic by 2035
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Impact of optical component shortages & bottlenecks explained + Hyperscaler’s CAPEX
Cisco CEO sees great potential in AI data center connectivity, silicon, optics, and optical systems
Cisco 800G line card for Cisco 8000 Series Routers powered by Silicon One ASIC
Cisco’s ‘Internet of the Future’ Strategy with Silicon One Architect
Cisco restructuring plan will result in ~4100 layoffs; focus on security and cloud based products
Cisco report: Agentic AI to reshape WAN traffic, AI inference will be ~25% of total traffic by 2035
Executive Summary:
Consumer-driven AI traffic [1.] currently represents a marginal share of aggregate Internet traffic. However, accelerating adoption of agentic AI is expected to materially reshape traffic composition over the next decade. In its “AI Impact on Wide Area Networks” report, Cisco projects that AI will emerge as the dominant driver of network traffic growth. As consumer AI adoption approaches “near-universal usage,” AI and agentic AI are forecast to increase consumer-driven network traffic by approximately 6.6× by the mid-2030s (see chart below).
Cisco estimates that this AI expansion will account for roughly 63% of incremental traffic growth relative to non-AI scenarios. The study focuses specifically on WAN implications, rather than data center or GPU infrastructure, and provides guidance on network design and capacity planning. Methodologically, the report integrates real-world traffic observations (via Cisco Crosswork Assurance User Experience), third-party industry datasets, and controlled laboratory evaluations of AI agents to characterize how AI-generated traffic diverges from conventional web traffic patterns.
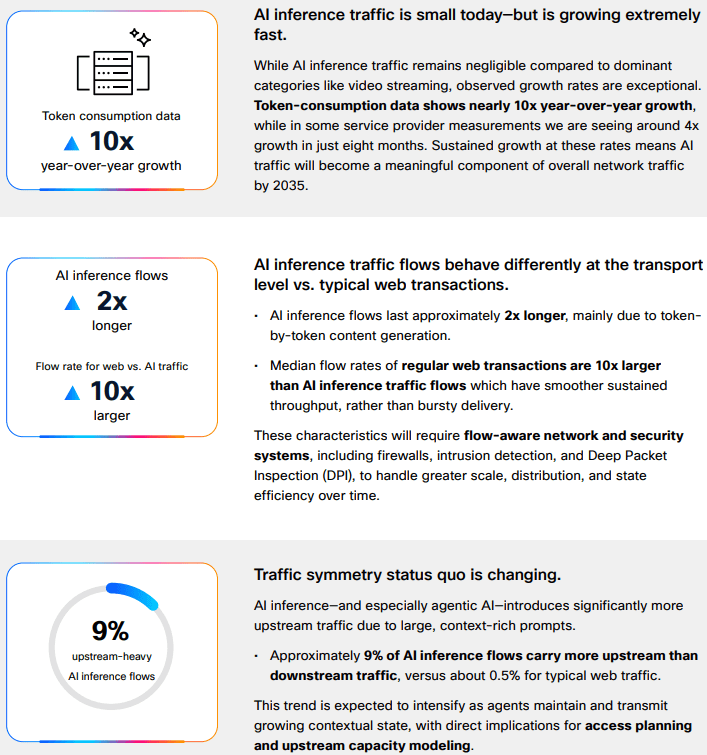
Token-consumption data shows nearly 10x year-over-year growth, while in some service provider measurements Cisco is seeing ~4x growth in just eight months. Sustained growth at these rates means AI traffic will become a meaningful component of overall network traffic by 2035.
Note 1. Consumer AI traffic has a few defining technical traits: it is still dominated by short text-based exchanges, but it is becoming more stateful, more upstream-heavy, and more latency-sensitive as users move from simple prompts to agentic workflows and multimodal interactions. Today’s consumer AI traffic is still overwhelmingly text-oriented, which is one reason the aggregate bandwidth impact remains modest despite rapid adoption. Comcast’s network observation is a useful real-world proxy: 97.1% of AI traffic was text-based, while images accounted for 2.6% and video only 0.3%. The key technical implication is that current traffic volumes are often limited more by conversation frequency and session behavior than by very large payloads, though that changes quickly as users adopt image, audio, and video generation.
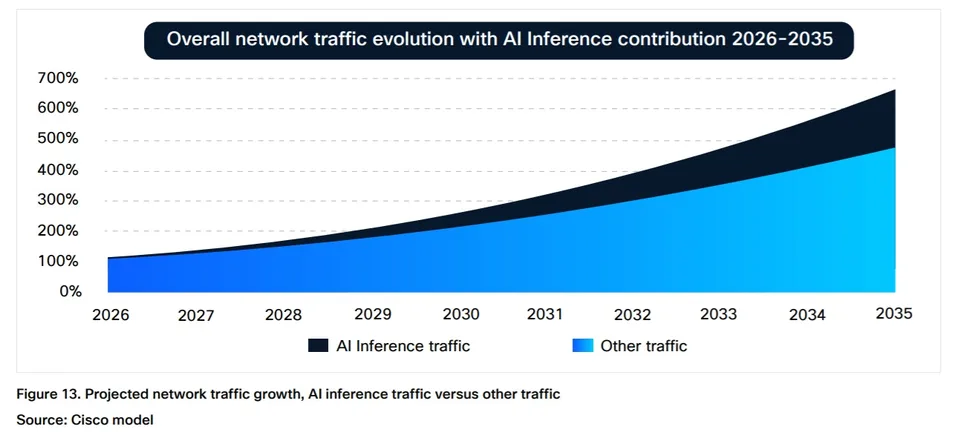
Although AI inference traffic is currently “negligible” relative to dominant categories such as video streaming, Cisco projects it will comprise approximately 25% of total network traffic by 2035 (see chart below). At that point, AI traffic is expected to represent a “meaningful component” of overall network load. Importantly, AI-generated traffic exhibits distinct characteristics: inference flows are approximately twice the duration of typical web transactions, demonstrate higher upstream bandwidth demand, and operate at “software speed” rather than human interaction rates.
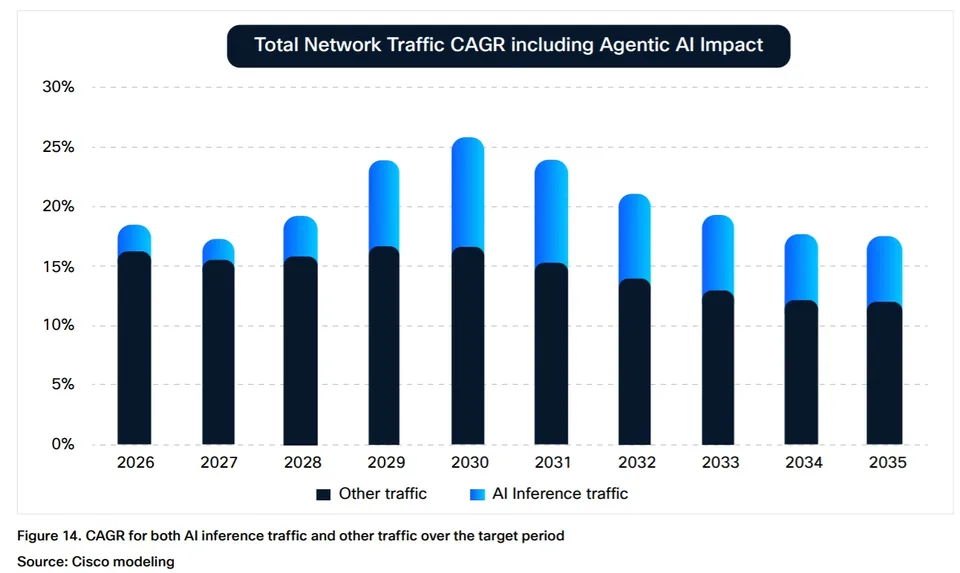
The emergence of AI agents as “power users” further amplifies these dynamics. Cisco notes that agent-executed tasks can generate up to 450% more traffic per task compared to human-driven interactions. This shift is expected to drive operator adoption of “flow-aware network and security systems” as traffic patterns become increasingly machine-driven and less predictable.
Cisco’s broader framing is that AI traffic “isn’t just adding traffic,” but is changing the shape of traffic, with inference flows running about twice as long as typical web transactions and, in some cases, generating up to 450% more traffic per task when an agent executes the workload. AI inference sessions tend to hold resources longer, create more sustained flows, and push operators to think in terms of flow-aware behavior rather than only peak-throughput sizing. Cisco also notes that about 9% of AI inference flows carry more upstream than downstream traffic, versus about 0.5% for typical web traffic, which is a meaningful shift for access and broadband networks. Cisco reports that approximately 9% of AI inference flows are upstream-dominant, compared to roughly 0.5% for traditional web traffic, with this divergence expected to widen alongside increased agentic AI utilization. In parallel, latency sensitivity is anticipated to become a more critical performance parameter for AI-driven applications.
Latency and symmetry:
AI traffic is also more sensitive to latency than many ordinary consumer web transactions because the user experience is often conversational and interactive, with the expectation of near-immediate turn-taking. Cisco describes AI inference as operating at “software speed” rather than human speed, which means small delays can be more noticeable and operationally important. At the same time, upstream demand becomes more significant because prompts, context, attachments, and agent-generated actions can increase return-path traffic, especially as multimodal inputs and agentic tool use expand.
Multimodal growth:
The biggest step-up in technical impact comes when consumer AI shifts from text-only prompting to multimodal generation and agent-driven workflows. In those cases, each task can involve multiple model calls, retrieval steps, tool invocations, and richer media payloads, which expands both flow count and bytes per session. Cisco’s study suggests that this is why AI traffic will increasingly require “flow-aware network and security systems,” because the traffic profile is not just larger, but structurally different from conventional browsing.
Infrastructure Implications:
Telecom infrastructure is becoming “increasingly intertwined with hyperscale infrastructure, not because operators are leading AI investment, but because they are becoming part of the ecosystem that supports it,” analyst firm MTN Consulting said in an April 27th research note. “Demand for optical transport, data-center interconnect, and edge infrastructure is rising as telecom networks carry growing volumes of cloud and AI-driven traffic,” the firm said.
“AI network traffic is already reshaping infrastructure needs. What we are seeing is clear: AI isn’t just adding traffic. It’s changing the shape of traffic,” Javier Antich, principal product management engineer in the CTO office of Cisco’s provider connectivity group, and Gurudatt Shenoy, SVP, product management, provider connectivity, explained in this blog post.
These shifts are beginning to influence access network evolution. Fiber networks already provide relatively symmetric throughput and low latency, while cable operators are advancing similar capabilities through DOCSIS upgrades. Mid-split and high-split architectures increase upstream spectrum allocation, enabling more balanced capacity profiles. Concurrently, Tier 1 operators such as Comcast and Charter Communications are introducing low-latency enhancements within DOCSIS networks.
Operational data reflects early-stage impacts. Comcast Chief Network Officer Elad Nafshi noted at the Cable Next-Gen event in March that approximately 97.1% of AI traffic on Comcast’s network remains text-based, with images accounting for 2.6% and video just 0.3%, indicating that bandwidth-intensive multimodal AI traffic has yet to scale materially.
Network design impact:
For broadband and access networks, the immediate engineering issues are upstream traffic capacity, queue behavior, and latency consistency rather than raw total throughput alone. Symmetry upgrades (such as DOCSIS mid-split and high-split for MSOs), along with low-latency capabilities, are relevant because consumer AI creates more return-path pressure and more time-sensitive sessions. In other words, the challenge is not simply to carry more bytes; it is to carry more interactive sessions with predictable performance, especially as multimodal and agentic usage scales.
………………………………………………………………………………………………………………………………………………………………………………………………………….
References:
Will the wave of AI generated user-to/from-network traffic increase spectacularly as Cisco and Nokia predict?
Telecom operators investing in Agentic AI while Self Organizing Network AI market set for rapid growth
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Cisco CEO sees great potential in AI data center connectivity, silicon, optics, and optical systems
The Financial Trap of Autonomous Networks: Scaling Agentic AI in the Telecom Core
Ericsson integrates Agentic AI into its NetCloud platform for self healing and autonomous 5G private networks
STL Partners webinar: Agentic AI needed for RAN autonomy & efficiency
Nokia to showcase agentic AI network slicing; Ericsson partners with Ookla to measure 5G network slicing performance
Agentic AI and the Future of Communications for Autonomous Vehicles (V2X)
Telecom data centers must be redesigned for the AI era with rack scale architectures, enhanced power & cooling requirements
Is the “far edge” a bridge to far to cross for AI inferencing? What about “Distributed AI Grids”?
T-Mobile US announces new broadband wireless and fiber targets, 5G-A with agentic AI and live voice call translation
Intel and AI chip startup SambaNova partner; SN50 AI inferencing chip max speed said to be 5X faster than competitive AI chips
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
On February 10, 2026, Cisco announced the Silicon One G300 102.4 Tbps Ethernet switch silicon, claiming it can power gigawatt-scale AI clusters for training, inference, and real-time agentic workloads, while maximizing GPU utilization with a 28% improvement in job completion time. The G300 was said to offer Intelligent Collective Networking, which combines an industry-leading fully shared packet buffer, path-based load balancing, and proactive network telemetry to offer better performance and profitability for large-scale data centers. It efficiently absorbs bursty AI traffic, responds faster to link failures, and prevents packet drops that can stall jobs, ensuring reliable data delivery even over long distances. With Intelligent Collective Networking, Cisco can deliver 33% increased network utilization, and a 28% reduction in job completion time versus simulated non-optimized path selection, making AI data centers more profitable with more tokens generated per GPU-hour. Also, the Cisco Silicon One G300 is highly programmable, enabling equipment to be upgraded for new network functionality even after it has been deployed. This enables Silicon One-based products to support emerging use cases and play multiple network roles, protecting long-term infrastructure investments. And with security fused into the hardware, customers can embrace holistic, at-speed security to keep clusters up and running.
The Cisco Silicon One G300 will power new Cisco N9000 and Cisco 8000 systems that push the frontier of AI networking in the data center. The systems feature innovative liquid cooling and support high-density optics to achieve new efficiency benchmarks and ensure customers get the most out of their GPU investments. In addition, the company enhanced Nexus One to make it easier for enterprises to operate their AI networks — on-premises or in the cloud — removing the complexity that can hold organizations back from scaling AI data centers.
“We are spearheading performance, manageability, and security in AI networking by innovating across the full stack – from silicon to systems and software,” said Jeetu Patel, President and Chief Product Officer, Cisco. “We’re building the foundation for the future of infrastructure, supporting every type of customer—from hyperscalers to enterprises—as they shift to AI-powered workloads.”
“As AI training and inference continues to scale, data movement is the key to efficient AI compute; the network becomes part of the compute itself. It’s not just about faster GPUs – the network must deliver scalable bandwidth and reliable, congestion-free data movement,” said Martin Lund, Executive Vice President of Cisco’s Common Hardware Group. “Cisco Silicon One G300, powering our new Cisco N9000 and Cisco 8000 systems, delivers high-performance, programmable, and deterministic networking – enabling every customer to fully utilize their compute and scale AI securely and reliably in production.”
The networking industry reaction to Cisco’s newest ASIC has been largely positive, with industry analysts and partners highlighting its role in reclaiming Cisco’s dominance in the AI infrastructure market. For example, Brendan Burke of Futurium thinks Cisco’s Silicon One G300 could be the backbone of Agentic AI Inference. His take: “Cisco’s latest announcements represent a calculated move to assert dominance in the AI networking fabric by attacking the specific bottlenecks of GPU cluster efficiency. As AI workloads shift toward agentic inference, where autonomous agents continuously interact across distributed environments, the network must handle unpredictable traffic patterns, unlike the structured flows of traditional training. Cisco is leveraging its vertical integration strategy to address the reliability and power constraints that plague these massive clusters. By emphasizing programmable silicon and rigorous optic qualification, Cisco aims to decouple network lifespan from rapid GPU innovation cycles, ensuring infrastructure can adapt to new traffic steering algorithms without hardware replacements. The G300 is a bid to make Ethernet the undisputed standard for AI back-end networks.”
- Industry-Leading Specs: Market analysts have noted that the G300’s 102.4 Tbps switching capacity sets a new benchmark for AI scale-out and scale-across networking.
- Efficiency Gains: Initial simulations showing a 28% reduction in job completion time (JCT) and a 33% increase in network utilization have been cited as major differentiators for large-scale AI clusters.
- Sustainability Focus: The shift toward liquid-cooled systems for the G300, which offers 70% greater energy efficiency per bit, is being viewed as a critical move for sustainable AI growth.
- Competitive Positioning: Experts from HyperFRAME Research suggest that the new silicon signals a “new confidence” from Cisco, positioning them as the “Apple of infrastructure” by tightly integrating hardware and software.
- AI Infrastructure Pivot: Financial analysts at Seeking Alpha have upgraded Cisco’s outlook, viewing the company no longer as just a legacy hardware firm but as a central player in the AI revolution.
- Partner Confidence: Major partners, such as Shanghai Lichan Technology, have expressed excitement about the Nexus 9100 Series powered by this silicon, specifically for its ability to simplify and scale AI deployments.
- Nvidia & Broadcom Competition: While the G300 is seen as a strong challenger to Nvidia’s Spectrum-X and Broadcom’s Tomahawk/Jericho lines, some observers note that Cisco still faces a steep climb to regain market share lost to these competitors in recent years.
- Complexity Concerns: Some industry veterans have pointed out that while the silicon is “hyperscale ready,” the success of these ASICs in the enterprise will depend on Cisco’s ability to maintain operational simplicity through tools like the Nexus Dashboard.
……………………………………………………………………………………………………………………………………………………………………………………………
|
Cisco Silicon One G300
|
Broadcom Tomahawk 6 (BCM78910 Series)
|
|---|---|
|
Bandwidth
102.4 Tbps  |
Bandwidth
102.4 Tbps  |
|
Manufacturing Process
TSMC 3nm  |
Manufacturing Process
3nm technology |
|
SerDes Lanes & Speed
512 lanes at 200 Gbps per link  |
SerDes Lanes & Speed
512 lanes at 200 Gbps per link, or 1024 lanes at 100G |
|
Port Configuration
Up to 64 x 1.6TbE ports or 512 x 200GbE ports |
Port Configuration
Up to 64 x 1.6TbE ports or 512 x 200GbE ports |
|
Target AI Cluster Size
Supports deployments of up to 128,000 GPUs |
Target AI Cluster Size
Supports over 100,000 XPUs (accelerators) Broadcom |
- Congestion Management: Cisco differentiates its G300 with an “Intelligent Collective Networking” approach featuring a fully shared packet buffer and a load-balancing agent that communicates across all G300s in the network to build a global map of congestion. Broadcom’s Tomahawk series also includes smart congestion control and global load balancing, though Cisco claims its implementation achieves higher network utilization (33% better).
- Programmability: Cisco emphasizes P4 programmability, allowing customers to update network functionality even after deployment.
- Ecosystem & Integration: Broadcom operates primarily in the merchant silicon market, with their chips used by various partners like HPE Juniper Networking. Cisco uses its own silicon to power its
Nexus 9000 and 8000 Series switches, tightly integrating hardware with software management platforms like Nexus One for a unified solution.
- Cooling Solutions: The Cisco G300 is designed to support high-density optics and is offered in new systems that include liquid-cooled options, providing 70% greater energy efficiency per bit compared to previous generations.
………………………………………………………………………………………………………………………………………………………………………………
References:
https://newsroom.cisco.com/c/r/newsroom/en/us/a/y2026/m02/cisco-announces-new-silicon-one-g300.html
https://blogs.cisco.com/sp/cisco-silicon-one-g300-the-next-wave-of-ai-innovation
Will Cisco’s Silicon One G300 Be the Backbone of Agentic Inference?
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Cisco CEO sees great potential in AI data center connectivity, silicon, optics, and optical systems
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Nvidia enters Data Center Ethernet market with its Spectrum-X networking platform
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Disclaimer: The author used Perplexity.ai for the research in this article.
……………………………………………………………………………………………………………..
Introduction:
Ethernet is now the leader in “scale-out” AI networking. In 2023, InfiniBand held an ~80% share of the data center switch market. A little over two years later, Ethernet has overtaken it in data center switch and server port counts. Indeed, the demand for Ethernet-based interconnect technologies continues to strengthen, reflecting the market’s broader shift toward scalable, open, and cost-efficient data center fabrics. According to Dell’Oro Group research published in July 2025, Ethernet was on track to overtake InfiniBand and establish itself as the primary fabric technology for large-scale data centers. The report projects cumulative data center switch revenue approaching $80 billion over the next five years, driven largely by AI infrastructure investments. Other analysts say Ethernet now represents a majority of AI‑back‑end switch ports, likely well above 50% and trending toward 70–80% as Ultra Ethernet / RoCE‑based fabrics (Remote Direct Memory Access/RDMA over Converged Ethernet) scale.
With Nvidia’s expanding influence across the data center ecosystem (via its Mellanox acquisition), Ethernet-based switching platforms are expected to maintain strong growth momentum through 2026 and the next investment cycle.
The past, present, and future of Ethernet speeds depicted in the Ethernet Alliance’s 2026 Ethernet Roadmap:
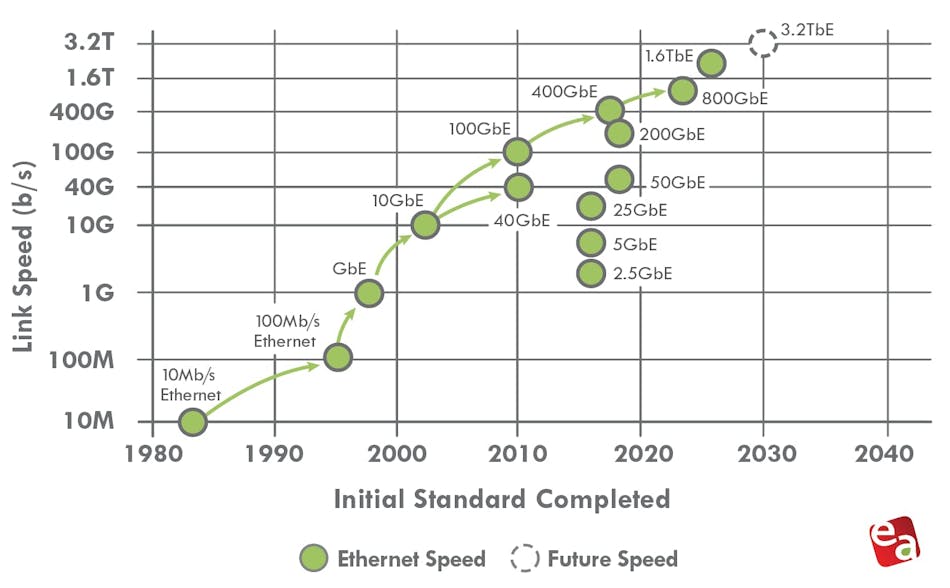
- IEEE 802.3 expects to complete IEEE 802.3dj, which supports 200 Gb/s, 400 Gb/s, 800 Gb/s, and 1.6 Tb/s, by late 2026.
- A 400-Gb/s/lane Signaling Call For Interest (CFI) is already scheduled for March.
- PAM-6 is an emerging, high-order modulation format for short-reach, high-speed optical fiber links (e.g., 100G/400G+ data center interconnects). It encodes 2.585 bits per symbol using 6 distinct amplitude levels, offering a 25% higher bitrate than PAM-4 within the same bandwidth.
………………………………………………………………………………………………………………………………………………………………………………………………………..
Dominant Ethernet speeds and PHY/PMD trends:
In 2026, the Ethernet portfolio spans multiple tiers of performance, with 100G, 200G, 400G, and 800G serving as the dominant server‑ and fabric‑facing speeds, while 1.6T begins to appear in early AI‑scale spine and inter‑cluster links.
-
Server‑to‑leaf topology:
-
100G and 200G remain prevalent for general‑purpose and mid‑tier AI inference workloads, often implemented over 100GBASE‑CR4 / 100GBASE‑FR / 100GBASE‑LR and their 200G counterparts (e.g., 200GBASE‑CR4 / 200GBASE‑FR4 / 200GBASE‑LR4) using 4‑lane PAM4 modulation.
-
Many AI‑optimized racks are migrating to 400G server interfaces, typically using 400GBASE‑CR8 / 400GBASE‑FR8 / 400GBASE‑LR8 with 8‑lane 50 Gb/s PAM4 lanes, often via QSFP‑DD or OSFP form‑factors.
-
-
Leaf‑to‑spine and spine‑to‑spine topology:
-
400G continues as the workhorse for many brownfield and cost‑sensitive fabrics, while 800G is increasingly targeted for new AI and high‑growth pods, typically deployed as 800GBASE‑DR8 / 800GBASE‑FR8 / 800GBASE‑LR8 over 8‑lane 100 Gb/s PAM4 links.
-
IEEE 802.3dj is progressing toward completion in 2026, standardizing 200 Gb/s per lane operation a
-
For cloud‑resident (hyperscale) data centers, the Ethernet‑switch leadership is concentrated among a handful of vendors that supply high‑speed, high‑density leaf‑spine fabrics and AI‑optimized fabrics.
Core Ethernet‑switch leaders:
-
NVIDIA (Spectrum‑X / Spectrum‑4)
NVIDIA has become a dominant force in cloud‑resident Ethernet, largely by bundling its Spectrum‑4 and Spectrum‑X Ethernet switches with H100/H200/Blackwell‑class GPU clusters. Spectrum‑X is specifically tuned for AI workloads, integrating with BlueField DPUs and offering congestion‑aware transport and in‑network collectives, which has helped NVIDIA surpass both Cisco and Arista in data‑center Ethernet revenue in 2025. -
Arista Networks
Arista remains a leading supplier of cloud‑native, high‑speed Ethernet to hyperscalers, with strong positions in 100G–800G leaf‑spine fabrics and its EOS‑based software stack. Arista has overtaken Cisco in high‑speed data‑center‑switch market share and continues to grow via AI‑cluster‑oriented features such as cluster‑load‑balancing and observability suites. -
Cisco Systems
Cisco maintains broad presence in cloud‑scale environments via Nexus 9000 / 7000 platforms and Silicon One‑based designs, particularly where customers want deep integration with routing, security, and multi‑cloud tooling. While its share in pure high‑speed data‑center switching has eroded versus Arista and NVIDIA, Cisco remains a major supplier to many large cloud providers and hybrid‑cloud operators.
Other notable players:
-
HPE (including Aruba and Juniper post‑acquisition)
HPE and its Aruba‑branded switches are widely deployed in cloud‑adjacent and hybrid‑cloud environments, while the HPE‑Juniper combination (via the 2025 acquisition) strengthens its cloud‑native switching and security‑fabric portfolio. -
Huawei
Huawei supplies CloudEngine Ethernet switches into large‑scale cloud and telecom‑owned data centers, especially in regions where its end‑to‑end ecosystem (switching, optics, and management) is preferred. -
White‑box / ODM‑based vendors
Most hyperscalers also source Ethernet switches from ODMs (e.g., Quanta, Celestica, Inspur) running open‑source or custom NOS’ (SONiC, Cumulus‑style stacks), which can collectively represent a large share of cloud‑resident ports even if they are not branded like Cisco or Arista. White‑box / ODM‑based Ethernet switches hold a meaningful and growing share of the data‑center Ethernet market, though they still trail branded vendors in overall revenue. Estimates vary by source and definition. - ODM / white‑box share of the global data‑center Ethernet switch market is commonly estimated in the low‑ to mid‑20% range by revenue in 2024–2025, with some market trackers putting it around 20–25% of the data‑center Ethernet segment. Within hyperscale cloud‑provider data centers specifically, the share of white‑box / ODM‑sourced Ethernet switches is higher, often cited in the 30–40% range by port volume or deployment count, because large cloud operators heavily disaggregate hardware and run open‑source NOSes (e.g., SONiC‑style stacks).
-
ODM‑direct sales into data centers grew over 150% year‑on‑year in 3Q25, according to IDC, signaling that white‑box share is expanding faster than the overall data‑center Ethernet switch market.
-
Separate white‑box‑switch market studies project the global data‑center white‑box Ethernet switch market to reach roughly $3.2–3.5 billion in 2025, growing at a ~12–13% CAGR through 2030, which implies an increasing percentage of the broader Ethernet‑switch pie over time.
Ethernet vendor positioning table:
| Vendor | Key Ethernet positioning in cloud‑resident DCs | Typical speed range (cloud‑scale) |
|---|---|---|
| NVIDIA | AI‑optimized Spectrum‑X fabrics tightly coupled to GPU clusters | 200G/400G/800G, moving toward 1.6T |
| Arista | Cloud‑native, high‑density leaf‑spine with EOS | 100G–800G, strong 400G/800G share |
| Cisco | Broad Nexus/Silicon One portfolio, multi‑cloud integration | 100G–400G, some 800G |
| HPE / Juniper | Cloud‑native switching and security fabrics | 100G–400G, growing 800G |
| Huawei | Cost‑effective high‑throughput CloudEngine switches | 100G–400G, some 800G |
| White‑box ODMs | Disaggregated switches running SONiC‑style NOSes | 100G–400G, increasingly 800G |
Supercomputers and modern HPC clusters increasingly use high‑speed, low‑latency Ethernet as the primary interconnect, often replacing or coexisting with InfiniBand. The “type” of Ethernet used is defined by three layers: speed/lane rate, PHY/PMD/optics, and protocol enhancements tuned for HPC and AI. Slingshot, the proprietary Ethernet-based solution from HPE, commanded 48.1% of performance for the Top500 list in June 2025 and 46.3% in November 2025. On both of the lists, it provided interconnectivity for six of the top 10 – including the top three: El Capitan, Frontier, and Aurora.
HPC Speed and lane‑rate tiers:
-
Mid‑tier HPC / legacy supercomputers:
-
100G Ethernet (e.g., 100GBASE‑CR4/FR4/LR4) remains common for mid‑tier clusters and some scientific workloads, especially where cost and power are constrained.
-
-
AI‑scale and next‑gen HPC:
-
400G and 800G Ethernet (400GBASE‑DR4/FR4/LR4, 800GBASE‑DR8/FR8/LR8) are now the workhorses for GPU‑based supercomputers and large‑scale HPC fabrics.
-
1.6T Ethernet (IEEE 802.3dj, 200 Gb/s per lane) is entering early deployment for spine‑to‑spine and inter‑cluster links in the largest AI‑scale “super‑factories.”
-
In summary, NVIDIA and Arista are the most prominent Ethernet‑switch leaders specifically for AI‑driven, cloud‑resident data centers, with Cisco, HPE/Juniper, Huawei, and white‑box ODMs rounding out the ecosystem depending on region, workload, and procurement model. In hyperscale cloud‑provider data centers, ODMs hold a 30%-to-40% market share.
References:
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
AI Data Center Boom Carries Huge Default and Demand Risks
Markets and Markets: Global AI in Networks market worth $10.9 billion in 2024; projected to reach $46.8 billion by 2029
Using a distributed synchronized fabric for parallel computing workloads- Part I
Using a distributed synchronized fabric for parallel computing workloads- Part II
Will the wave of AI generated user-to/from-network traffic increase spectacularly as Cisco and Nokia predict?
Network operators are bracing themselves for a wave of AI traffic, partially based on a RtBrick survey, as well as forecasts by Cisco and Nokia, but that hasn’t happened yet. The heavy AI traffic today is East to West (or vice-versa) within cloud resident AI data centers and for AI data center interconnects.
1. Cisco believes that AI Inference agents will soon engage “continuously” with end-users, keeping traffic levels consistently high. has stated that AI will greatly increase network traffic, citing a shift toward new, more demanding traffic patterns driven by “agentic AI” and other applications. This perspective is a core part of Cisco’s business strategy, which is focused on selling the modernized infrastructure needed to handle the coming surge. Cisco identified three stages of AI-driven traffic growth, each with different network demands:
- Today’s generative AI models produce “spikey” traffic which spikes up when a user submits a query, but then returns to a low baseline. Current networks are largely handling this traffic without issues.
- Persistent “agentic” AI traffic: The next phase will involve AI agents that constantly interact with end-users and other agents. Cisco CEO Chuck Robbins has stated that this will drive traffic “beyond the peaks of current chatbot interaction” and keep network levels “consistently high”.
- Edge-based AI: A third wave of “physical AI” will require more computing and networking at the edge of the network to accommodate specialized use cases like industrial IoT.
“As we move towards agentic AI and the demand for inferencing expands to the enterprise and end user networking environments, traffic on the network will reach unprecedented levels,” Cisco CEO Chuck Robbins said on the company’s recent earnings call. “Network traffic will not only increase beyond the peaks of current chatbot interaction, but will remain consistently high with agents in constant interaction.”

2. Nokia recently predicted that both direct and indirect AI traffic on mobile networks will grow at a faster pace than regular, non-AI traffic.
- Direct AI traffic: This is generated by users or systems directly interacting with AI services and applications. Consumer examples: Using generative AI tools, interacting with AI-powered gaming, or experiencing extended reality (XR) environments. Enterprise examples: Employing predictive maintenance, autonomous operations, video and image analytics, or enhanced customer interactions.
- Indirect AI traffic: This occurs when AI algorithms are used to influence user engagement with existing services, thereby increasing overall traffic. Examples: AI-driven personalized recommendations for video content on social media, streaming platforms, and online marketplaces, which can lead to longer user sessions and higher bandwidth consumption.
The Finland based network equipment vendor warned that the AI wave could bring “a potential surge in uplink data traffic that could overwhelm our current network infrastructure if we’re not prepared,” noting that the rise of hybrid on-device and cloud tools will require much more than the 5-15 Mbps uplink available on today’s networks. Nokia’s Global Network Traffic 2030 report forecasts that overall traffic could grow by 5 to 9 times current levels by 2033. All told, Nokia said AI traffic is expected to hit 1088 exabytes (EB) per month by 2033. That means overall traffic will grow 5x in a best case scenario and 9x in a worse case.
To manage this anticipated traffic surge, Nokia advocates for radical changes to existing network infrastructure.
- Cognitive networks: The company states that networks must become “cognitive,” leveraging AI and machine learning (ML) to handle the growing data demand.
- Network-as-Code: As part of its Technology Strategy 2030, Nokia promotes a framework for more flexible and scalable networks that leverage AI and APIs.
- 6G preparation: Nokia Bell Labs is already conducting research and field tests to prepare for 6G networks around 2030, with a focus on delivering the capacity needed for AI and other emerging technologies.
- Optimizing the broadband edge: The company also highlights the need to empower the broadband network edge to handle the demands of AI applications, which require low latency and high reliability.
Nokia’s Global Network Traffic 2030 report didn’t mention agentic AI, which are artificial intelligence systems designed to autonomously perceive, reason, and act in their environment to achieve complex goals with less human oversight. Unlike generative AI, which focuses on creating content, agentic AI specializes in workflow automation and independent problem-solving by making decisions, adapting plans, and executing tasks over extended periods to meet long-term objectives.
3. Ericsson did point to traffic increases stemming from the use of AI-based assistants in its 2024 Mobility Report. In particular, it predicted the majority of traffic would be related to the use of consumer video AI assistants, rather than text-based applications and – outside the consumer realm – forecast increased traffic from “AI agents interacting with drones and droids. Accelerated consumer uptake of GenAI will cause a steady increase of traffic in addition to the baseline increase,” Ericsson said of its traffic growth scenario.
…………………………………………………………………………………………………………………………………………………………………………………..
Dissenting Views:
1. UK Disruptive Analysis Founder Dean Bubley isn’t a proponent of huge AI traffic growth. “Many in the telecom industry and vendor community are trying to talk up AI as driving future access network traffic and therefore demand for investment, spectrum etc., but there is no evidence of this at present,” he told Fierce Network.
Bubley argues that AI agents won’t really create much traffic on access networks to homes or businesses. Instead, he said, they will drive traffic “inside corporate networks, and inside and between data centers on backbone networks and inside the cloud. “There might be a bit more uplink traffic if video/images are sent to the cloud for AI purposes, but again that’s hypothetical,” he said.
2. In a LinkedIn post, Ookla analyst Mike Dano said he was a bit suspicious about “Cisco predicting a big jump in network traffic due to AI agents constantly wandering around the Internet and doing things.” While almost all of the comments agreed with Dano, it still is an open question whether the AI traffic Armageddon will actually materialize.
……………………………………………………………………………………………………………………………………………………………………………………….
References:
RtBrick survey: Telco leaders warn AI and streaming traffic to “crack networks” by 2030
https://www.fierce-network.com/cloud/will-ai-agents-really-raise-network-traffic-baseline
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Both telecom and enterprise networks are being reshaped by AI bandwidth and latency demands of AI. Network operators that fail to modernize architectures risk falling behind. Why? AI workloads are network killers — they demand massive east-west traffic, ultra-low latency, and predictable throughput.
- Real-time observability is becoming non-negotiable, as enterprises need to detect and fix issues before they impact AI model training or inference.
- Self-driving networks are moving from concept to reality, with AI not just monitoring but actively remediating problems.
- The competitive race is now about who can integrate AI into networking most seamlessly — and HPE/Juniper’s Mist AI, Cisco’s assurance stack, and Nvidia’s AI fabrics are three different but converging approaches.
Cisco, HPE/Juniper, and Nvidia are designing AI-optimized networking equipment, with a focus on real-time observability, lower latency and increased data center performance for AI workloads. Here’s a capsule summary:
Cisco: AI-Ready Infrastructure:
- Cisco is embedding AI telemetry and analytics into its Silicon One chips, Nexus 9000 switches, and Catalyst campus gear.
- The focus is on real-time observability via its ThousandEyes platform and AI-driven assurance in DNA Center, aiming to optimize both enterprise and AI/ML workloads.
- Cisco is also pushing AI-native data center fabrics to handle GPU-heavy clusters for training and inference.
- Cisco claims “exceptional momentum” and leadership in AI: >$800M in AI infrastructure orders taken from web-scale customers in Q4, bringing the FY25 total to over $2B.
- Cisco Nexus switches now fully and seamlessly integrated with NVIDIA’s Spectrum-X architecture to deliver high speed networking for AI clusters
HPE + Juniper: AI-Native Networking Push:
- Following its $13.4B acquisition of Juniper Networks, HPE has merged Juniper’s Mist AI platform with its own Aruba portfolio to create AI-native, “self-driving” networks.
- Key upgrades include:
-Agentic AI troubleshooting that uses generative AI workflows to pinpoint and fix issues across wired, wireless, WAN, and data center domains.
-Marvis AI Assistant with enhanced conversational capabilities — IT teams can now ask open-ended questions like “Why is the Orlando site slow?” and get contextual, actionable answers.
-Large Experience Model (LEM) with Marvis Minis — digital twins that simulate user experiences to predict and prevent performance issues before they occur.
-Apstra integration for data center automation, enabling autonomous service provisioning and cross-domain observability
Nvidia: AI Networking at Compute Scale
- Nvidia’s Spectrum-X Ethernet platform and Quantum-2 InfiniBand (both from Mellanox acquisition) are designed for AI supercomputing fabrics, delivering ultra-low latency and congestion control for GPU clusters.
- In partnership with HPE, Nvidia is integrating NVIDIA AI Enterprise and Blackwell architecture GPUs into HPE Private Cloud AI, enabling enterprises to deploy AI workloads with optimized networking and compute together.
- Nvidia’s BlueField DPUs offload networking, storage, and security tasks from CPUs, freeing resources for AI processing.
………………………………………………………………………………………………………………………………………………………..
Here’s a side-by-side comparison of how Cisco, HPE/Juniper, and Nvidia are approaching AI‑optimized enterprise networking — so you can see where they align and where they differentiate:
| Feature / Focus Area | Cisco | HPE / Juniper | Nvidia |
|---|---|---|---|
| Core AI Networking Vision | AI‑ready infrastructure with embedded analytics and assurance for enterprise + AI workloads | AI‑native, “self‑driving” networks across campus, WAN, and data center | High‑performance fabrics purpose‑built for AI supercomputing |
| Key Platforms | Silicon One chips, Nexus 9000 switches, Catalyst campus gear, ThousandEyes, DNA Center | Mist AI platform, Marvis AI Assistant, Marvis Minis, Apstra automation | Spectrum‑X Ethernet, Quantum‑2 InfiniBand, BlueField DPUs |
| AI Integration | AI‑driven assurance, predictive analytics, real‑time telemetry | Generative AI for troubleshooting, conversational AI for IT ops, digital twin simulations | AI‑optimized networking stack tightly coupled with GPU compute |
| Observability | End‑to‑end visibility via ThousandEyes + DNA Center | Cross‑domain observability (wired, wireless, WAN, DC) with proactive issue detection | Telemetry and congestion control for GPU clusters |
| Automation | Policy‑driven automation in campus and data center fabrics | Autonomous provisioning, AI‑driven remediation, intent‑based networking | Offloading networking/storage/security tasks to DPUs for automation |
| Target Workloads | Enterprise IT, hybrid cloud, AI/ML inference & training | Enterprise IT, edge, hybrid cloud, AI/ML workloads | AI training & inference at hyperscale, HPC, large‑scale data centers |
| Differentiator | Strong enterprise install base + integrated assurance stack | Deep AI‑native operations with user experience simulation | Ultra‑low latency, high‑throughput fabrics for GPU‑dense environments |
Key Takeaways:
- Cisco is strongest in enterprise observability and broad infrastructure integration.
- HPE/Juniper is leaning into AI‑native operations with a heavy focus on automation and user experience simulation.
- Nvidia is laser‑focused on AI supercomputing performance, building the networking layer to match its GPU dominance.
- Cisco leverages its market leadership, customer base and strategic partnerships to integrate AI with existing enterprise networks.
- HPE/Juniper challenges rivals with an AI-native, experience-first network management platform.
- Nvidia aims to dominate the full-stack AI infrastructure, including networking.
OpenAI partners with G42 to build giant data center for Stargate UAE project
OpenAI, the maker of ChatGPT, said it was partnering with United Arab Emirates firm G42 and others to build a huge artificial-intelligence data center in Abu Dhabi, UAE. It will be the company’s first large-scale project outside the U.S. OpenAI and G42 said Thursday the data center would have a capacity of 1 gigawatt (1 GW) [1], putting it among the most powerful in the world. OpenAI and G42 didn’t disclose a cost for the huge data center, although similar projects planned in the U.S. run well over $10 billion.
………………………………………………………………………………………………………………………………………………………………………..
Note 1. 1 GW of continuous power is enough to run roughly one million top‑end Nvidia GPUs once cooling and power‑conversion overheads are included. That’s roughly the annual electricity used by a city the size of San Francisco or Washington.
“Think of 1MW as the backbone for a mid‑sized national‑language model serving an entire country,” Mohammed Soliman, director of the strategic technologies and cybersecurity programme at the Washington-based Middle East Institute think tank, told The National.
………………………………………………………………………………………………………………………………………………………………………..
The project, called Stargate UAE, is part of a broader push by the U.A.E. to become one of the world’s biggest funders of AI companies and infrastructure—and a hub for AI jobs. The Stargate project is led by G42, an AI firm controlled by Sheikh Tahnoon bin Zayed al Nahyan, the U.A.E. national-security adviser and brother of the president. As part of the deal, an enhanced version of ChatGPT would be available for free nationwide, OpenAI said.
The first 200-megawatt chunk of the data center is due to be completed by the end of 2026, while the remainder of the project hasn’t been finalized. The buildings’ construction will be funded by G42, and the data center will be operated by OpenAI and tech company Oracle, G42 said. Other partners include global tech investor, AI/GPU chip maker Nvidia and network-equipment company Cisco.
Data centers are grouped into three sizes: small, measuring up to about 1,000 square feet (93 square metres), medium, around 10,000 sqft to 50,000 sqft, and large, which are more than 50,000 sqft, according to Data Centre World. On a monthly basis, they are estimated to consume as much as 36,000kWh, 2,000MW and 10MW, respectively.

UAE has at least 17 data centers, according to data compiled by industry tracker DataCentres.com. AFP
The data-center project is the fruit of months of negotiations between the Gulf petrostate and the Trump administration that culminated in a deal last week to allow the U.A.E. to import up to 500,000 AI chips a year, people familiar with the deal have said.
That accord overturned Biden administration restrictions that limited access to cutting-edge AI chips to only the closest of U.S. allies, given concerns that the technology could fall into the hands of adversaries, particularly China.
To convince the Trump administration it was a reliable partner, the U.A.E. embarked on a multipronged charm offensive. Officials from the country publicly committed to investing more than $1.4 trillion in the U.S., used $2 billion of cryptocurrency from Trump’s World Liberty Financial to invest in a crypto company, and hosted the CEOs of the top U.S. tech companies for chats in a royal palace in Abu Dhabi.
As part of the U.S.-U.A.E agreement, the Gulf state “will fund the build-out of AI infrastructure in the U.S. at least as large and powerful as that in the UAE,” David Sacks, the Trump administration’s AI czar, said earlier this week on social media.
U.A.E. fund MGX is already an investor in Stargate, the planned $100 billion network of U.S. data centers being pushed by OpenAI and SoftBank.
Similar accords with other U.S. tech companies are expected in the future, as U.A.E. leaders seek to find other tenants for their planned 5-gigawatt data-center cluster. The project was revealed last week during Trump’s visit to the region, where local leaders showed the U.S. president a large model of the project.
The U.A.E. is betting U.S. tech giants will want servers running near users in Africa and India, slightly shaving off the time it takes to transmit data there.
Stargate U.A.E. comes amid a busy week for OpenAI. On Wednesday, a developer said it secured $11.6 billion in funding to push ahead with an expansion of a data center planned for OpenAI in Texas. OpenAI also announced it was purchasing former Apple designer Jony Ive’s startup for $6.5 billion.
References:
https://www.wsj.com/tech/open-ai-abu-dhabi-data-center-1c3e384d?mod=ai_lead_pos6
https://www.thenationalnews.com/future/technology/2025/05/24/stargate-uae-ai-g42/
Wedbush: Middle East (Saudi Arabia and UAE) to be next center of AI infrastructure boom
Cisco to join Stargate UAE consortium as a preferred tech partner
Cisco to join Stargate UAE consortium as a preferred tech partner
Cisco Systems Inc. today announced the signing of a Memorandum of Understanding (MoU) to join the Stargate UAE consortium as a preferred technology partner. The strategic MoU, signed by Cisco’s Chair and Chief Executive Officer Chuck Robbins together with other consortium partners, G42, OpenAI, Oracle, NVIDIA and SoftBank Group, envisions the construction of an AI data center in Abu Dhabi with a target capacity of 1 GW, with an initial 200 MW capacity to be delivered in 2026.

Photo Credit: Cisco
As a partner in this initiative, Cisco will provide advanced networking, security and observability solutions to accelerate the deployment of next-generation AI compute clusters.
“With the right infrastructure in place, AI can transform data into insights that empower every organization to innovate faster, tackle complex challenges, and deliver tangible outcomes,” said Chuck Robbins, Cisco Chair and CEO. “Cisco is proud to join this consortium to harness the power of AI and deliver the infrastructure that will enable tomorrow’s breakthroughs.”
Today’s announcement follows Robbins’ recent visit to Bahrain, Saudi Arabia, Qatar, and the UAE where Cisco announced a series of strategic initiatives across all phases of the AI transformation in the region. These new initiatives employ Cisco’s trusted technology across the region’s AI infrastructure buildouts, leveraging the company’s deep expertise in networking and security together with longstanding regional partnerships. By fostering the development of secure, AI-powered digital infrastructure and collaborating with key Cisco partners, the company is delivering world-class, trusted technology to the region.
More information on Cisco’s recent announcements in the Middle East is here.
“AI is the most transformative force of our time,” said Nvidia CEO Jensen Huang in a press release Thursday. “With Stargate UAE, we are building the AI infrastructure to power the country’s bold vision – to empower its people, grow its economy, and shape its future.”
The Stargate project, in collaboration with Emirati firm G42, will span 10 square miles and include a 5-gigawatt capacity. As part of the deal, OpenAI and Oracle are slated to manage a 1-gigawatt compute cluster built by G42. The project will include chips from Nvidia, while Cisco Systems will provide connectivity infrastructure.
The companies said an initial 200-megawatt AI cluster should launch next year.
References:
https://www.prnewswire.com/news-releases/cisco-joins-stargate-uae-initiative-302463388.html
https://www.cnbc.com/2025/05/22/stargate-uae-openai-nvidia-oracle.html
More information on Cisco’s recent announcements in the Middle East is here.
Wedbush: Middle East (Saudi Arabia and UAE) to be next center of AI infrastructure boom
Cisco CEO sees great potential in AI data center connectivity, silicon, optics, and optical systems
It’s no surprise to IEEE Techblog readers that Cisco’s networking business – still its biggest unit, generating nearly half its total sales – reported <$6.9 billion in revenue for the three-month period ending in January (Cisco’s second fiscal quarter). That was down 3% compared with the same quarter the year before. For its first half year, networking sales dropped 14% year-over-year, to about $13.6 billion.
However, total second-quarter revenues grew 9% year-over-year, to just less than $14 billion, boosted by the Splunk (security company) acquisition in March 2024. Thanks to that deal, Cisco’s security revenues more than doubled for the first half, to about $4.1 billion. But net income fell 8%, to roughly $2.4 billion, due partly to higher costs for research and development, as well as sales and marketing expenses.
Cisco groused about an “inventory correction” as networking customers digested stock they had already bought, but that surely is not the case now as that inventory has been worked off by its customers (ISPs, telcos, enterprise & government end users). Cisco CFO Richard Scott Herren now says “The demand that we’re seeing today a function of extended lead times like we saw a couple of years ago. That’s not the case. Our lead times are not extending.”
Currently, Cisco firmly believes that Ethernet connectivity sales to owners of AI data centers is an “emerging opportunity.” That refers to Cisco’s data center switching solutions for “web-scale” and enterprise customer intra-data center communications. The company’s AI strategy is described here.

Image Courtesy of Cisco Systems
………………………………………………………………………………………………………………………………………
AI investments “will lead to our networking equipment being combined with Nvidia GPUs, and that’s how we’ll accomplish that in the future,” CEO Chuck Robbins told industry analysts on a call to discuss second-quarter results, according to a Motley Fool transcript. “There’s so much change going on right now from a technology perspective that there’s both excitement about the opportunity, and candidly, there’s a little bit of fear of slowing down too much and letting your competition get too much ahead of you. So, we saw solid demand,” he said.
However, Cisco will face mighty competition in that space.
- Nokia is targeting the same opportunity and last month said it would spend an additional €100 million (US$104 million) on its Internet Protocol unit annually with the goal of generating another €1 billion ($1.04 billion) in data center revenues by 2028.
- Arista Networks is another rival in this market, selling high performance Ethernet switches to cloud service providers like Microsoft.
- Nvidia, whose $7 billion acquisition of Mellanox in 2019 gave it effective control of InfiniBand, an alternative to Ethernet that had represented the main option for connecting GPU clusters when analysts published research on the topic in August 2023. Just as important, the Mellanox division of Nvidia also is a leader in Ethernet connectivity within data centers as described in this IEEE Techblog post.
- Juniper Networks (being acquired by HPC) is also focusing on networking the AI data center as per a white paper you can download after filling out this form.
During the Q & A, Robbins elaborated: “On the $700 million in AI orders, it’s a combination of systems, silicon, optics, and optical systems. And I think if you break it down, it’s about half is in silicon and systems. And it continues to accelerate. And I’d say the teams have done a great job on the silicon front. We’ve invested heavily in more resources there. The team is running parallel development efforts for multiple chips that are staggered in their time frames. They’ve worked hard. They were increasing the yield, which is a positive thing. And so, we feel good about it, but it’s a combination of all those things that we’re selling to the customers.”
…………………………………………………………………………………………………………………………………………………………………………………………
Enterprise AI:
“What we’re seeing on the enterprise side relative to AI is it’s still — customers are still in the very early days, and they all realize they need to figure out exactly what their use cases are. We’re starting to see some spending though on specific AI-driven infrastructure. And we think as we get AI pods out there — we got Hyperfabric coming. We got AI defense coming.
We have Hypershield in the market. And we got this new DPU switch, they are all going to be a part of the infrastructure to support these AI applications. So, we’re beginning to see it happen, but I think it’s also really important to understand that as the enterprises leverage their private data, their proprietary data, and they’ll do some training on that and then they’ll run inference obviously against that. We believe that opportunity is an order of magnitude higher than what we’ve seen in training today. We’re going to continue to innovate and build capabilities to put ourselves in a better position to be a real beneficiary as this continues to accelerate. But as of today, we feel like we’re in pretty good shape.”
“If you look at AI defense with the AI Summit that we did recently, there’s — I think there’s about 20-some-odd customers who are interested in going to proof of concept with us right now on it. We had almost half the Fortune 100 there for that event. So, I feel good about where we are. It will turn into greater demand as we just continue to scale these products.”
Telco use of AI Edge Applications:
“We see some of the European network operators are looking at delivering AI as a service,” said Robbins. “We see a lot of them planning for AI edge applications that are sitting at the edge of their networks that they’re managing for customers.”
,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,………………………………………………
Cisco raised its guidance and now expects revenues for the full year of between $56 billion and $56.5 billion, up from its earlier range of $55.3 billion to $56.3 billion.
,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,,………………………………………………
References:
https://www.cisco.com/site/uk/en/solutions/artificial-intelligence/index.html
https://www.juniper.net/content/dam/www/assets/white-papers/us/en/networking-the-ai-data-center.pdf
Nokia selects Intel’s Justin Hotard as new CEO to increase growth in IP networking and data center connections
Initiatives and Analysis: Nokia focuses on data centers as its top growth market
Nvidia enters Data Center Ethernet market with its Spectrum-X networking platform