Tomahawk
Broadcom’s Open Ethernet Fabric: Architectural Evolution, AI Tail Latency, Proprietary Interconnects, Cisco Silicon One
Introduction:
On November 15, 2026, Broadcom showcased its open Ethernet fabric portfolio for artificial intelligence (AI) and high-performance computing at the Super Computing 2026 (SC26) event in Chicago, IL. The silicon included the 102.4-terabit Tomahawk 6 switch, Tomahawk Ultra, Jericho 4, and the 800G Thor Ultra network interface card with enhanced RoCE. Those components are designed to rival proprietary systems like Nvidia’s InfiniBand and NVLink in AI and HPC clusters. With bandwidth reaching parity across ASICs, competition now centers on tail-latency determinism in collective operations.
Here’s a comparison chart that provides a quick comparison of the individual Broadcom component attributes:
| Component | Silicon Class | Throughput | Key Architectural Features | Target Topology Role |
|---|---|---|---|---|
| Tomahawk 6 (BCM78910) | Ethernet Switch ASIC | 102.4 Tbps | 3nm process, 512 × 200G SerDes, dynamic load balancing, UEC telemetry | Scale-out spine/leaf fabrics for massive GPU clusters |
| Tomahawk Ultra | Low-Latency Switch ASIC | 51.2 Tbps | ~250ns latency, Credit-Based Flow Control (CBFC), Link Layer Retry (LLR) | Intra-rack scale-up accelerator memory fabrics |
| Thor Ultra | AI Network Interface Card (NIC) | 800 Gbps (2 × 400G / 1 × 800G) | PCIe Gen6 x16, eRoCE, direct GPU memory placement, packet trimming | Host accelerator endpoints (GPUs, TPUs, XPUs) |
| Jericho 4 | Fabric / Core Router ASIC | Multi-Tbps Modular | Deep HBM packet buffers, virtual output queuing (VOQ) | Inter-pod aggregation and multi-datacenter AI federations |
Broadcom also co-presented technical sessions at the SC26 Workshop on High-Performance Fabrics for AI and HPC, organized in collaboration with researchers from The Ohio State University. The technical presentations highlighted how emerging specifications—including Scale-Up Ethernet Transport (SUE-T) under the Open Compute Project and transport standards from the Ultra Ethernet Consortium (UEC)—provide deterministic, lossless transmission for collective communication routines across distributed foundation models.
Architectural Evolution: Toward Open Ethernet Fabrics:
Broadcom’s Tomahawk 6 switches and Thor Ultra Ethernet NICs illustrate the growing role of Ethernet in high-performance AI and HPC networking. Rather than relying solely on conventional RoCEv2 behavior, this architecture combines higher switching capacity with packet-level multipath out-of-order data placement, selective retransmission, and programmable congestion control. These capabilities address key transport and congestion-management challenges in large accelerator clusters.
Thor Ultra’s enhanced RDMA over Converged Ethernet, or eRoCE [1.], allows supported RDMA traffic to reach accelerator memory even when packets arrive out of order. This capability enables packet spraying across multiple network paths, improving load distribution without requiring every packet in a transfer to follow the same route. Ordering requirements still apply to some operations, including sends and atomics; out-of-order placement is not universal across all RDMA traffic.
Note 1. eRoCE is a network protocol that allows servers to use Remote Direct Memory Access (RDMA) directly over standard Ethernet networks. It lets applications read and write data in the memory of a remote computer with ultra-low latency and minimal CPU involvement.
The architecture also supports selective retransmission and packet trimming. Selective retransmission improves recovery efficiency by resending missing packets rather than unnecessarily retransmitting data already received. Packet trimming provides a congestion signal by removing a packet’s payload while preserving header information, helping endpoints detect loss and initiate recovery. These mechanisms support more responsive congestion handling, but should not be characterized as providing instantaneous recovery or eliminating every source of network congestion.
This direction is consistent with the Ultra Ethernet Consortium’s goal of developing an open, interoperable communications architecture for AI and HPC. The consortium emphasizes multipathing, congestion management, scalability, and compatibility with widely deployed APIs. Support for individual UEC features, however, should be distinguished from demonstrated interoperability across a complete multivendor deployment.
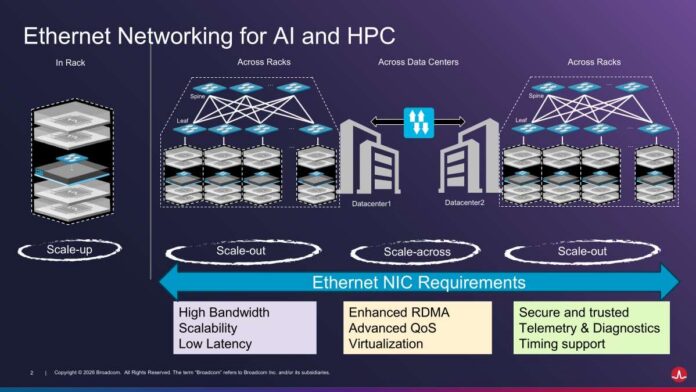
Hot Chips 2026 Broadcom Thor Ultra Ethernet NIC -Ethernet Networking for AI and HPC
Solving AI Tail Latency: Broadcom vs. Proprietary Fabrics:
To overcome the congestion and recovery bottlenecks of legacy RoCEv2 (such as ECMP hash collisions and PFC pause storms), Broadcom’s SC26 announced architecture splits intelligence between the Thor Ultra NIC and Tomahawk switches. This integrates per-packet spraying, hardware-level out-of-order GPU reassembly, packet trimming with hardware SACK, and Link-Layer Retry (LLR) with credit-based flow control (CBFC) to achieve ~250ns scale-up latency [2.].
Note 2. Scale-up latency: For an Ethernet switch, scale-up latency refers to the time required for a small control, memory, or synchronization packet to traverse a single-hop network domain (such as a rack or pod) and reach a target accelerator (XPU/GPU). However, Ethernet switch latency is not equivalent to end-to-end network latency, and neither necessarily represents collective-operation completion time across a GPU cluster. Therefore, Tomahawk Ultra’s approximately 250 ns switch latency should not, by itself, be interpreted as evidence of performance comparable to proprietary accelerator interconnects for AI collective operations.
Whereas proprietary fabrics like Nvidia InfiniBand and NVLink rely on single-vendor, closed-loop credit control and specialized memory semantics to prevent packet drops, Broadcom achieves equivalent tail-latency determinism over standard IEEE 802.3 Ethernet frames. By spraying packets across all available links and allowing the Thor Ultra NIC to reassemble out-of-order payloads directly into GPU memory via dma-buffer, the fabric eliminates ECMP elephant-flow collisions [3.] without incurring CPU reordering overhead. Simultaneously, switch-level packet trimming and link-local LLR/CBFC recover transient 200G SerDes bit errors and queue spikes in nanoseconds, matching proprietary collective completion times while avoiding vendor lock-in.
Note 3. ECMP elephant-flow collisions occur when Equal-Cost Multi-Path (ECMP) routing hash algorithms accidentally assign two or more massive, high-bandwidth data transfers—known as elephant flows—to the same physical network path.
Implications for Research and Cloud Infrastructure:
Tomahawk 6 provides 102.4 Tbps of switching capacity on a single ASIC. Broadcom has described architectures using this capacity to connect approximately 128,000 accelerators through two switching tiers. Depending on port speeds, topology, and oversubscription requirements, higher switch radix can reduce switching stages and the associated optics, cabling, latency, and power overhead.
For university computing centers, national laboratories, and cloud operators, the broader opportunity is an Ethernet-based infrastructure strategy supported by a wider supplier ecosystem. The UEC explicitly identifies manufacturer choice and interoperability as intended benefits, alongside performance, scalability, and total cost of ownership. These goals make open Ethernet relevant to organizations evaluating both technical requirements and long-term procurement flexibility.
For application and systems teams, the objective is to expose advanced network capabilities through compatible software interfaces—not to imply that high-performance RDMA traffic must traverse the conventional Linux networking data path. The UEC’s stated emphasis on compatibility with widely deployed APIs provides a more precise basis for discussing software portability and ecosystem continuity.
The strongest architectural conclusion is that Ethernet is evolving beyond higher link speeds alone: endpoint transport capabilities and fabric-level congestion management are becoming central to its suitability for large-scale AI and HPC workloads. Broadcom’s published features support that conclusion, while workload-performance and energy-efficiency comparisons still require clearly defined test conditions.
Broadcom Tomahawk vs. Cisco Silicon One:
Broadcom’s disaggregated strategy—utilizing specialized ASICs like Tomahawk Ultra, Tomahawk 6, and Jericho 4 paired with Thor Ultra NICs—contrasts with Cisco’s unified, P4-programmable Silicon One architecture (such as the G300 and G302 series). While Broadcom offloads congestion management and reassembly to the endpoint NIC and keeps switch pipelines lean, Cisco relies on large on-die shared buffers and switch-driven Intelligent Packet Flow to minimize collective completion times without specialized endpoint dependencies.
In practice, this creates a clear architectural trade-off for tail-latency control across heterogeneous clusters. Broadcom’s endpoint-offload design requires pairing Tomahawk switches with UEC-compliant NICs like Thor Ultra to execute hardware out-of-order reassembly and packet trimming, delivering maximum scale-up determinism when both ends of the wire are aligned.
Conversely, Cisco’s Intelligent Packet Flow absorbs bursty all-reduce micro-bursts directly within Silicon One’s deep, fully shared on-die packet buffers while dynamically steering flows via real-time fabric telemetry, enabling predictable tail latency even when connected to standard, off-the-shelf third-party RoCEv2 NICs.
References:
https://casrai.org/news/broadcom-sc26-tomahawk-6-thor-ultra-open-ethernet-ai-2026
https://www.servethehome.com/broadcom-tomahawk-ultra-launch-for-scale-up-ethernet/
https://www.broadcom.com/company/news/product-releases/63361
https://www.servethehome.com/broadcom-thor-ultra-ethernet-nic-at-hot-chips-2026/
https://www.cisco.com/c/en/us/solutions/collateral/silicon-one/silicon-one-g300-ds.html
https://blogs.cisco.com/datacenter/ai-network-performance-with-cisco-intelligent-packet-flow
Ethernet Advances Towards 400 Gb/s-per-Lane Signaling for AI Networks: IEEE P802.3dv, Copper and Optical Interconnects
1.6T Ethernet Packet Loss Problem Solved: PHY-Layer Buffer Exhaustion with MAC-Layer Credit-Based Flow Control
2026 OCP Summit: Full-Stack AI Networking Silicon from Nvidia/Cisco and Broadcom; Ethernet vs InfiniBand Interconnects
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks