AI/ML
AI-RAN Push: NVIDIA, Nokia, and Operators Drive Towards Distributed Compute Platforms
Introduction:
A massive industry consortium spearheaded by NVIDIA, Nokia, and leading global telecom operators has announced an expanded ecosystem initiative aimed at transforming traditional radio access network (RAN) sites into converged, distributed intelligence platforms. While vendor marketing frequently leans on the ambiguous hype of “AI-RAN,” this specific alignment underscores a tangible structural shift: the push to monetize edge network infrastructure by hosting centralized AI inference and processing workloads directly within the carrier’s decentralized footprint.
The coalition, which includes T-Mobile US, Deutsche Telekom, Orange, and SoftBank, is actively deploying multi-vendor frameworks to validate whether cell sites can simultaneously manage real-time layer-1/layer-2 radio scheduling and high-throughput external AI workloads on a single, unified hardware fabric.
Multi-Vendor Validation and Live Network Milestones:
Rather than remaining confined to isolated laboratory benchmarks, the initiative highlighted several live-network implementation milestones:
-
- T-Mobile US Commercial Network Execution: T-Mobile completed a live AI-RAN call within a commercial production environment, leveraging Nokia’s cloud-native RAN software integrated with NVIDIA’s accelerated computing architecture. The trial successfully demonstrated dynamic, real-time compute resource allocation between standard cellular traffic and concurrent AI applications.
- European Operator Deployment Frameworks: Deutsche Telekom and Orange are initiating deep architectural trials across their European footprints. These validation tests focus explicitly on multi-tenant control planes and the orchestration of heterogeneous GPU resources across legacy and greenfield environments.
- SoftBank Industrial Clusters: Moving past speculative trials, SoftBank is designing localized edge computing clusters that treat cell towers as distributed mini-data centers, targeted directly at hosting low-latency, localized autonomous vehicle and industrial robotics workloads.
Globally, nearly 20 telecom operators have publicly announced AI-RAN collaborations using Nokia anyRAN software and NVIDIA ARC.
- T-Mobile recently marked the world’s first AI-RAN call on its commercial network in Bellevue, Washington, running on commercial ARC servers, Nokia’s NVIDIA CUDA-accelerated RAN software and massive multiple-input multiple-output radios, and connected to an existing 5G Standalone core and a commercial smartphone.
- BT is planning live AI-RAN trials in Birmingham, England, with Nokia and NVIDIA in 2027.
- Deutsche Telekom has validated Nokia and NVIDIA’s commercial AI-RAN platform in Bonn and Oulu labs, including AI-enhanced uplink channel estimation to improve uplink user throughput, with plans to move to field trials in 2027.
- Elisa simultaneously ran voice, mobile data and video analytics on the NVIDIA ARC platform, marking a European first in Elisa’s over-the-air field environment using 5G spectrum. The trial clears the way for distributed deployment and commercial AI-RAN services in 2027.
- Orange is testing Nokia 5G software on NVIDIA ARC, focusing on AI-RAN spectral efficiency improvements and support for edge services in live networks.
NVIDIA is introducing two ARC configurations — MGX 2U and MGX 4U — designed for dense, high-capacity intelligence and radio workloads, typically deployed at centralized RAN sites. Powered by NVIDIA RTX PRO™ 6000 Blackwell Server Edition GPUs, the configurations will offer x86 and NVIDIA Vera CPU options. Dell Technologies, Quanta Cloud Technology and Supermicro will offer ARC-ready servers.
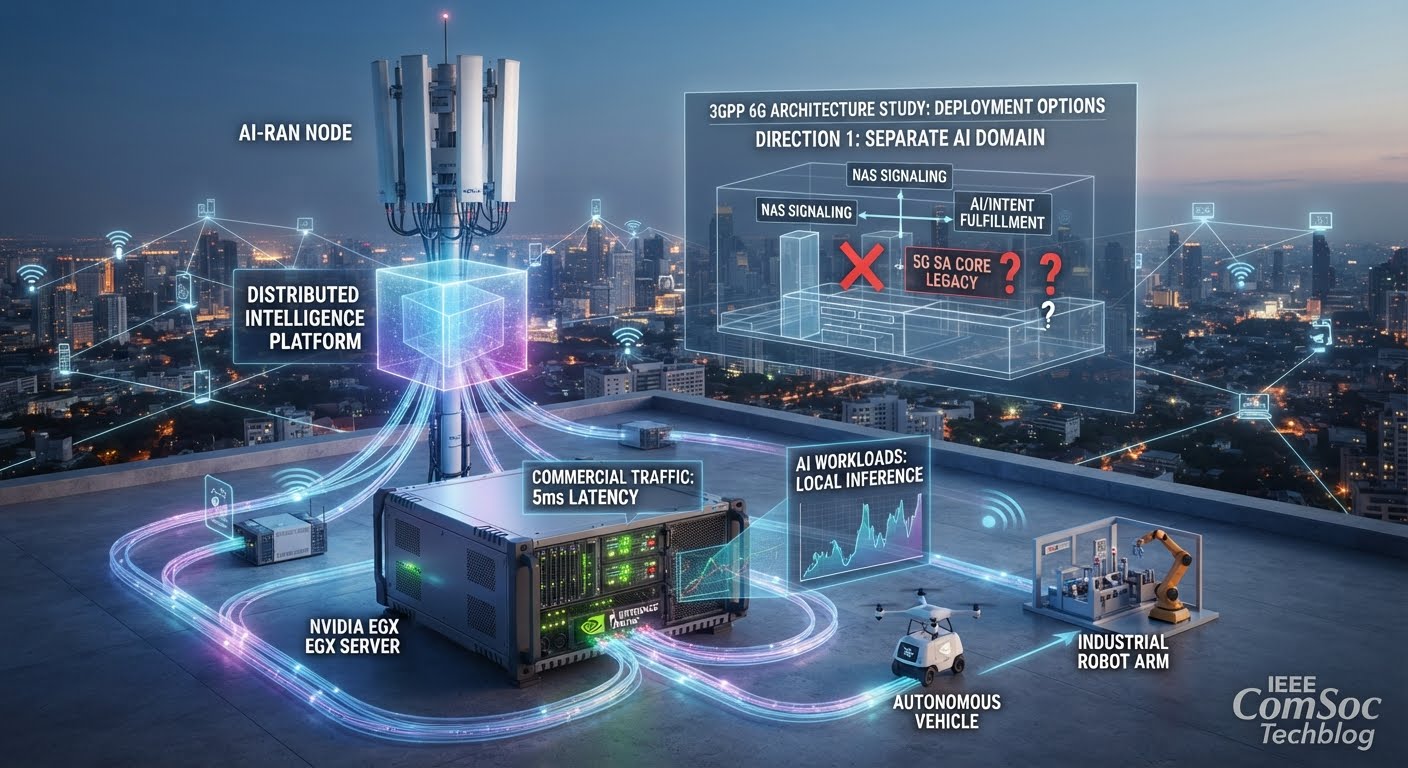
Image generated by Google Gemini
………………………………………………………………………………………………………………………………………………………………………………………
6G Splinter Risk – Will AI-RAN Interoperability Outpace the 6G SA Core?
This real-world push for decentralized AI-RAN execution exposes a critical timing and protocol gap within the broader standardization landscape. As vendors accelerate hardware deployments, the 3GPP SA2 Working Group remains technically fractured over how to formalize the underlying 6G core architecture. Rather than standardizing deterministic state behaviors, the current 6G study phase risks repeating the exact implementation voids that crippled 5G Standalone (SA) interoperability. Today’s commercial push for AI integration highlights the three architectural paths currently splintering 3GPP SA2:
-
- Direction 1 (Separate AI Domain): Anchors the core to the existing 5G Service-Based Architecture (SBA). It utilizes a dedicated AI domain for intent handling via the Service-Based Interface (SBI) while routing Non-Access Stratum (NAS) signaling through the AMF. Backed strongly by Western operators and vendors (including T-Mobile, Deutsche Telekom, Nokia, and NVIDIA), this path preserves 5G infrastructure investments but shifts the burden of multi-vendor integration directly to the device client.
- Direction 2 (AI Functionality in 6G NFs): Integrates machine learning natively within dedicated, standardized 6G network functions following legacy pipeline procedures.
- Direction 3 (Agent-Handled Connectivity): Eliminates traditional structural silos by deeply embedding autonomous AI agents directly into control and user plane procedures, bypassing the AMF entirely via a new Signaling Routing Function (SRF). This introduces massive procedural disruption to baseband silicon and core security frameworks.
………………………………………………………………………………………………………………………………………………………….
Conclusions – Bridging the Hype Gap:
The core engineering risk is that AI and machine learning models are fundamentally non-deterministic. If 3GPP restricts its focus to defining logical API endpoints rather than mandating strict behavioral state-machine realization, open agent-to-agent telemetry, and standardized model interchange formats, 6G will degenerate into a hyper-complex web of proprietary black boxes.
•Telcos have historically struggled to compete with hyperscalers (AWS, Azure, Google Cloud) on raw cloud storage and compute. AI-RAN could possibly the game because of physical close proximity and deterministic latency. By hosting AI workloads at the edge of the connectivity path, network operators might offer “Sovereign AI” and ultra-low-latency processing which centralized hyperscaler data centers physically cannot match.
As detailed in several previous IEEE Techblog posts (see References below), the telecom industry cannot afford another capital expenditure cycle driven by speculative lab benchmarks. By transforming cell towers into high-margin compute platforms, this distributed intelligence alliance offers carriers a concrete pathway to monetize low-latency edge workloads. However, for AI-RAN to achieve true multi-vendor utility, the engineering community must force 3GPP to bridge the gap between paper standards and deterministic software reality. We cannot afford to build another ghost in the machine.
………………………………………………………………………………………………………………………………………………………….
References:
6G Architecture and Economics: Core Network Evolution, AI Integration and Business Case
Warning: 6G core network must not repeat the 5G SA 3GPP architecture specs vs lack of interoperable standards
Sept 2026 3GPP meeting updates for 5G Advanced and 6G planning (with timeline for submisson to ITU-R WP 5D via ATIS)
Roles of 3GPP and ITU-R WP 5D in the IMT 2030/6G standards process
3GPP approves timelines for Release 21 which will specify 6G RAN, Core and 5G Advanced
Dell’Oro: RAN Market Stabilized in 2025 with 1% CAG forecast over next 5 years; Opinion on AI RAN, 5G Advanced, 6G RAN/Core risks
Ericsson leads SK Telecom AI RAN vs. NVIDIA’s GPU centric AI RAN Alliance
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Dell’Oro: AI RAN revenue forecast: $35B from 2026-to-2030; 3 types of AI RAN explained
Broadcom lending Anthropic up to $42 billion in yet another AI circular financing deal
Backgrounder:
According to Reuters, which obtained Anthropic’s IPO prospectus, the Big Tech giants are depicted in multiple ways in the IPO filing- as distribution partners, financial backers, computer suppliers, and competitors, all at once. They uncovered the clearest view yet of how circular the AI world really is, and how much an AI lab’s success depends on the giants it’s also competing against.
Reuters was able to calculate that Anthropic pays roughly 16% of every dollar it earns from its cloud partners (Amazon, Google, Microsoft) back to those same big tech partners. It counts the full value of contracts sold through a cloud marketplace as revenue, then treats the cloud platform’s cut of revenue as a marketing cost.
OpenAI does the opposite by only counting what it keeps after the cloud partner takes its share. That difference matters for understanding the big numbers floating around, and how to actually compare the two rivals’ toplines as they both eye the public market.
Broadcom’s relationship with Anthropic spans compute supply, equipment leasing and financing — giving the semiconductor company a central role in Anthropic’s infrastructure buildout. That differentiates it from other major partners and investors such as Amazon which primarily provide cloud infrastructure and distribution for Anthropic’s AI model Claude.
As part of that complex relationship, revealed in the IPO filing, Broadcom has agreed to lend Anthropic up to $42 billion to finance infrastructure spending. In turn, Anthropic stands to become the largest customer in Broadcom’s entire chip design business next year, making their relationship a prime example of the reciprocal spending that has animated AI skeptics on Wall Street, even as the AI lab readies a public offering that could see it valued at $2 trillion.
“It feels that there’s quite a concentrated bet right now on two companies being able to generate enough revenues to support all the financing that’s happened,” said Robert Leitao, managing partner of Rothschild & Co.
Anthropic disclosed that Broadcom’s role in supplying hardware and acting as a financing partner creates “potential conflicts of interest” that might affect Anthropic’s ability to access the computing power needed for its work, according to the prospectus.
The AI lab also warned that Broadcom’s decisions around pricing and hardware could affect its ability to procure enough computing infrastructure. Broadcom did not comment. Anthropic declined to comment to Reuters.
In April, Anthropic announced it was teaming up with Broadcom and Google for a deal that would see Google provide its Tensor Processing Unit (TPU) chip capacity to Anthropic, with the supply coming online in 2027. Broadcom designs Google’s TPUs that are manufactured by TSMC in Taiwan.

A Broadcom circuit board for chip testing is pictured during a lab tour as Broadcom prepares to launch new optical chip tech to fend off Nvidia in San Jose, California, U.S., September 5, 2025. Brittany Hosea-Small · REUTERS via Yahoo Finance.
Anthropic is also relying on Broadcom for equipment leasing and financing. Broadcom could designate a financing partner, and the debt instruments could be converted into Anthropic shares. Anthropic said in its filing it doesn’t expect any notes to be sold before it completes its IPO. The convertible note Anthropic would issue could finance about a third of the $125.2 billion commitment the AI lab has made for a five-year lease of tensor processing unit (TPU) computing capacity.
Other Players:
Broadcom rivals Nvidia and AMD have also provided funding to their own customers, including OpenAI and Anthropic, which the labs then used to pay for access to the companies’ high-powered chips. The concern about such circular financial schemes is that if one domino in the row falls, it will cause a chain reaction that will decimate the AI trade and, as a result, the global equities markets that have benefited from and come to rely on AI firms and hyperscalers.
As to the circularity of all of this financing, the BIS notes (via FT Alphaville):
“… circular relationships make reported demand partly endogenous to firms’ own financing decisions. For example, when a supplier finances a customer, part of the supplier’s revenue growth reflects its own capital investment, rather than organic final demand. This makes it harder for investors, lenders and supervisors to gauge what part of the current AI boom is based on organic demand.”
“The parallel with the telecom boom of the late 1990s is instructive: upstream equipment vendors financed network operators so they could buy the vendors’ equipment. This meant that part of the equipment vendors’ reported sales was being funded by the vendors themselves. For a time, as operators expanded their networks, equipment orders also expanded and vendors booked both the sales and loans as assets. However, when operators’ own revenues failed to materialize or slowed, they could neither repay the loans nor sustain the equipment purchases. Equipment vendors then sustained both financial losses and a loss of sales. Such dynamics may also play out in AI if revenue growth and end user demand fall short of firms’ expectations.”
……………………………………………………………………………………………………………………………………………………………………………………………..
- 2026 Debt Issuance: Projected between $220 billion and $250+ billion for major US hyperscalers (Alphabet / Google, Amazon, Meta, Microsoft, and Oracle), with broader AI-related market debt reaching up to $570 billion.
- 2027 Forecast: Goldman Sachs projects direct hyperscaler debt issuance to nearly double to around $400 billion (Jeff Pu estimates $419 billion) as companies finance over a third of their infrastructure needs.
- Aggregate Capex: Combined capital expenditures are expected to hit roughly $940 billion in 2026 and scale past $1.3 trillion in 2027.
- Market Share: Hyperscaler investment-grade bond sales have jumped from roughly 2% of total US supply (2022–2024) to roughly 9% in 2026.
- Credit Impact: Credit spreads on a 10-year hyperscaler credit basket have widened from historical 40–75bp ranges toward 90bp+, driven by leverage concerns.
- Cash Flow Outlook: S&P Global Ratings expects all major hyperscalers to run negative free operating cash flow through 2026 and 2027, with a cash-flow inflection point not projected until 2028–2029.
Source: Google Gemini
…………………………………………………………………………………………………………………………………………………………
References:
https://www.ft.com/content/87875b20-4081-4511-9afe-4ee389409742
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs (07/23)
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Telcos don’t have an AI problem; they have a voice estate visibility problem
By Satish Barot, Co-founder and CTO, Klearcom with Shazia Hasnie
AI is increasing telecom interdependence
This author has spent around twenty years building telephony products, and the last few watching what happens when AI gets added to them. The models are usually fine, but the voice estates around them are not.
Explanation: The voice estate is everything a voice call touches: the number dialed, the carriers delivering it, the menu that answers, the systems behind it, and in every country/location served.
NVIDIA’s February 2026 survey of roughly one thousand telecom respondents found that sixty percent of organizations are using or evaluating generative AI, up from forty nine percent in its 2024 edition. The voice call that once met a gateway and a queue now meets speech recognition, a language model, a synthetic voice, and also identity checks.
Every one of those can be healthy while the call goes wrong. So the useful test is whether you can prove, from outside your own network, that a real customer’s call still ends the way it should.
Why AI amplifies operational complexity
Old fashioned faults announce themselves: a line drops and something logs it. AI is quieter, and it fails in ways worth naming. It gets worse quietly: a model loses accuracy on one kind of request and nothing reports an error. It’s also confidently wrong. WildASR tested seven speech recognition systems on recordings degraded the way phone audio is. When a caller is cut off mid word, by a network delay or by the system deciding they had finished, the models fill in words nobody said. Further down the line that looks like a clean answer. The same benchmark makes a broader point: robustness measured in one language can substantially mispredict behavior in another, so a release validated in one market tells you little about the next.
Speed fails at the edges, not the average. A system that usually answers in under a second, but takes two and a half seconds on one call in ten, feels broken to those callers and healthy on every voice testing team chart. Nor is the result repeatable: EVA-Bench tested twelve systems and found a wide gap between passing once and passing every time, which undoes testing against a single expected answer.
Then the ones nobody looks at: the fallback menu that takes over when the AI gives up is usually the least maintained thing you own, and it runs exactly when things go wrong. None of this turns a light red on a contact center voice dashboard.
The other exposure is a number that anybody can dial. OWASP ranks prompt injection first among risks to applications built on language models, and a voice channel is an open microphone into the instruction path itself: a caller talks the model out of what it was built and told to do. Mitigations exist and they are worth naming. Treat caller speech as untrusted input and keep the transcript out of the context that carries instructions, constrain what the model can emit to a defined set of intents and slots rather than free text, and require confirmation for anything that moves money, changes credentials, or reads account data back.
The customer journey as the real test environment
Take a composite example, assembled from patterns that recur across multi country voice estates rather than drawn from one operator. An operator runs support numbers in fourteen countries behind one AI system. On Friday the team delivers an updated model and a new synthetic voice. Both pass in testing, no issues. By Monday, the share of calls handled without an agent is up by six points, complaints are up in three countries where the release went live first, and every dashboard is green. Nobody knows why.
The new voice made the menus two seconds longer, and nobody adjusted the window in which the system listens for a caller to stop talking. Callers spoke too early, the system heard fragments, filled the gaps, and guessed just confidently enough to keep a person out of the call.
The headline number improved because failures had stopped escalating. Every part did its job, so nothing raised an alarm. What broke was the outcome, and no single part owns the outcome. People given those same recordings transcribed them easily.
Those failures are not hypothetical. Test calls run by my own team over the past two years have found a global biopharmaceutical company whose menu prompts ran into each other faster than callers could answer, a financial services provider whose speech recognition intermittently failed on the word “agent”, so the route to a human worked on some calls and failed on others, and a healthcare data provider whose misrouted number reached an AI assistant that was never meant to answer it. In every case the systems carrying the call reported nothing wrong.
From system monitoring to outcome validation
Monitoring looks inward: are my systems up? Validation looks outward. It places a real call in country and checks the result against what should have happened: is a customer in this country, on this network, right now, getting the right answer?
Monitoring only sees what you own, and these failures hide inside the part causing them. So the two work together: validation tells you something is wrong and where, monitoring tells you why. Three changes follow. Report three numbers where you currently report one: calls the AI resolved correctly, calls it escalated correctly, and calls it failed. Report the slower calls alongside the average ones, and report by country and carrier instead of one global figure.
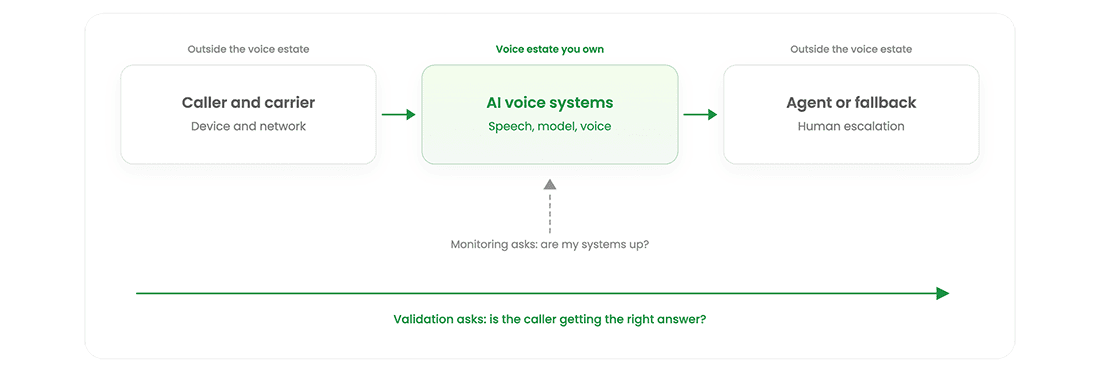
Figure 1. A single call crosses the voice estate an operator owns and systems it does not. Monitoring covers only the shaded stage. Validation traverses the whole path from the caller’s side.
Continuous testing as an assurance layer
The industry already has vocabulary for this. TM Forum’s autonomous network levels give operators a shared scale for how much of the “operate, assure and optimize” loop runs without people, and the same NVIDIA survey places 88% of organizations at Levels 1 to 3 on a scale of 0 to 5. Moving up that scale rests on evidence about delivered outcomes.
If the journey is what breaks, the journey is what you test. That means dialing the real public number, from a real device, on a real carrier in the country the customer is calling from, rather than looping a call back inside your own data center. It means testing from the outside in, and it means doing it on a schedule, across every country and carrier your customers use, fixed and mobile.
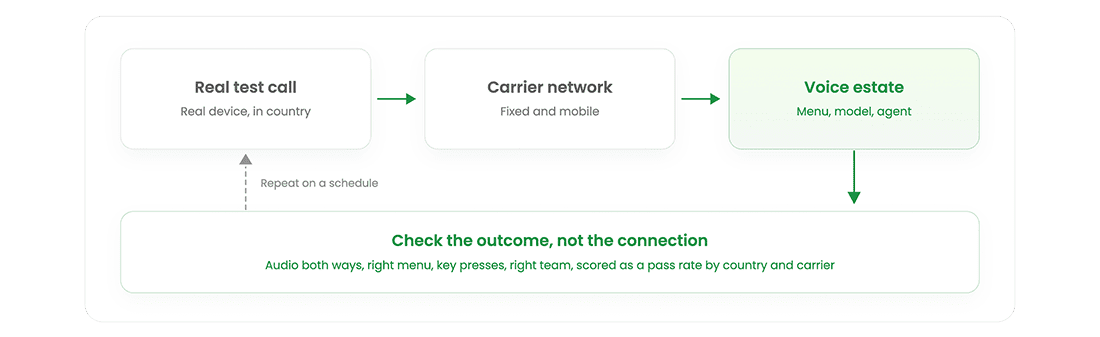
Figure 2. Testing the journey from the outside in. A scheduled call dialed from a real device in the country the customer calls from, scored on the delivered outcome.
Check outcomes, not connections: audio clear both ways, the right menu, key presses registered, the caller reaching the right team with their details intact. Score it across many calls with a library of realistic phrases, accepting a pass rate rather than an exact match, so decline shows as a trend. Treat a model update like a network change: try it on a few numbers first, then pull it back if the pass rate drops.
Several approaches are in this category. Synthetic transaction monitoring from operator owned probes, carrier side test call generation and crowdsourced testing on real handsets all produce outside in evidence, and they trade off differently on country coverage, cost and how closely the test resembles a real customer’s call. The common requirement is that the evidence originates outside the systems being assured, on a call placed in the country where the customer is dialing from.
Practical implications
Keep human escalation as a safety valve, not a number to drive down: cutting it without checking correctness makes the metric look better while the service gets worse. Then give the outcome an owner. Gartner’s June 2025 forecast that over 40% of agentic AI projects will be canceled by the end of 2027 attributes those cancellations to escalating costs, unclear business value and inadequate risk controls. Model capability doesn’t appear anywhere on that list. This is organizational before it’s technical.
These failures are seams between systems that break without producing an error, and monitoring your own equipment cannot see them: the gap sits between what your systems report and what your customer gets. Networks have been tested end to end for decades rather than trusted part by part. Voice estates deserve the same.
References
- NVIDIA (2026) State of AI in Telecommunications: 2026 Trends. Fourth annual survey report, published 19 February 2026, based on responses from 1,038 telecom professionals worldwide. Summary of findings: Survey Reveals AI Advances in Telecom.
- Tay, G., Ma, W., Lee, J., Tang, Y., Lee, D., Yin, W., Shen, D., Meng, S., Zhu, Y., Li, M. and Smola, A. (2026) Back to Basics: Revisiting ASR in the Age of Voice Agents. Boson AI. arXiv preprint arXiv:2603.25727, 26 March 2026. Introduces the WildASR benchmark. Dataset and code: bosonai/WildASR.
- Bogavelli, T., Gauthier Melançon, G., Stankiewicz, K., Bamgbose, O., Riols, F., Nguyen, H.H., Mehndiratta, R., Brin, L.D., Marinier, J., Subramani, H., Madamala, A., Nemala, S.K. and Sunkara, S. (2026) EVA-Bench: A New End-to-end Framework for Evaluating Voice Agents. arXiv preprint arXiv:2605.13841, 13 May 2026, revised 27 May 2026. DOI: 10.48550/arXiv.2605.13841.
- OWASP GenAI Security Project (2025) OWASP Top 10 for LLM Applications 2025. OWASP Foundation. Prompt injection is listed first, as LLM01.
- Gartner (2025) Gartner Predicts Over 40% of Agentic AI Projects Will Be Canceled by End of 2027. Press release, Sydney, 25 June 2025.
- TM Forum (2025) Autonomous Networks Framework v2.0.0 (IG1218F). Introductory Guide, published 20 March 2025, TM Forum Approved 9 May 2025. Levels of autonomy 0 to 5. Evaluation criteria for assigning a level are in Autonomous Network Levels Evaluation Methodology (IG1252).
-
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
………………………………………………………………………………………………………………………………………………………………………..
About the author:
Satish Barot is co-founder and CTO of Klearcom. He has spent around twenty years building telephony products and leads the engineering team behind Klearcom’s voice testing platform.
Bain & Co: AI Infrastructure Buildout Will Require $6 Trillion Revenue by 2031 to Support Massive CAPEX
Introduction:
Bain & Company estimates that the AI industry will need to generate approximately $6 trillion in annual revenue by 2031 to support the capital intensity (CAPEX) of the global AI infrastructure buildout, including investment in data centers, accelerated computing, memory, networking and power systems. In its latest technology report, released September 29th, Bain projects that new AI-enabled products could account for roughly $4.2 trillion of that revenue requirement. The firm identifies AI-driven innovation across search, advertising, autonomous systems and physical AI as major prospective sources of value creation.
Enterprise adoption could contribute a further $1 trillion to $1.4 trillion annually through productivity gains in software engineering, sales, marketing, customer service and IT operations. Bain characterizes “absorption speed”—the rate at which enterprises operationalize AI—as the emerging competitive variable, with leading AI labs investing more than $9.75 billion in engineering models intended to accelerate enterprise deployment and integration.
“The debate today is fixated on employee productivity. The economics of AI infrastructure demand trillions in new revenue beyond productivity gains. What the industry needs is a wave of innovation that will dwarf what mobile and cloud unlocked,” said David Crawford, chairman of Bain’s global technology practice and lead author of the report.
At a Glance:
- AI infrastructure investment is racing ahead, but generating enough economic value to justify it will require trillions of dollars in new AI-driven revenue.
- Productivity gains from existing enterprise and consumer applications won’t be enough; entirely new markets must emerge to close the funding gap.
- The winners will be those that create breakthrough AI applications that transform industries and expand the global economy.
Consumer AI services, including subscription and advertising-supported offerings, are projected to contribute between $200 billion and $400 billion in annual revenue. This segment is central to the commercial scaling of AI because it extends AI-enabled services to billions of users through consumer platforms, devices and digital-service ecosystems.
“New products and uses that don’t exist today will enable new markets and opportunities from abundant intelligence – these may include drug discovery, mental health and energy generation,” Bain said.
Bain forecasts annual AI infrastructure spending of up to $1.5 trillion by 2031. The figure encompasses greenfield data-center construction, expansion of existing facilities, and continuing investment in GPUs, memory, network fabrics and related infrastructure. Bain assumes that capital expenditure could represent approximately one-quarter of total AI-industry revenue—“an ambitious but reasonable percentage based on trends among cloud providers.” On that basis, the firm calculates that the AI market would need to approach $6 trillion in annual revenue to sustain the projected infrastructure investment cycle.
“The unprecedented speed and scale of the AI buildout, with billions flowing into chips, data centers, networks and power systems, have focused attention on the challenge of building capacity. But the more important question may be whether enough economic value can be created to justify it.”
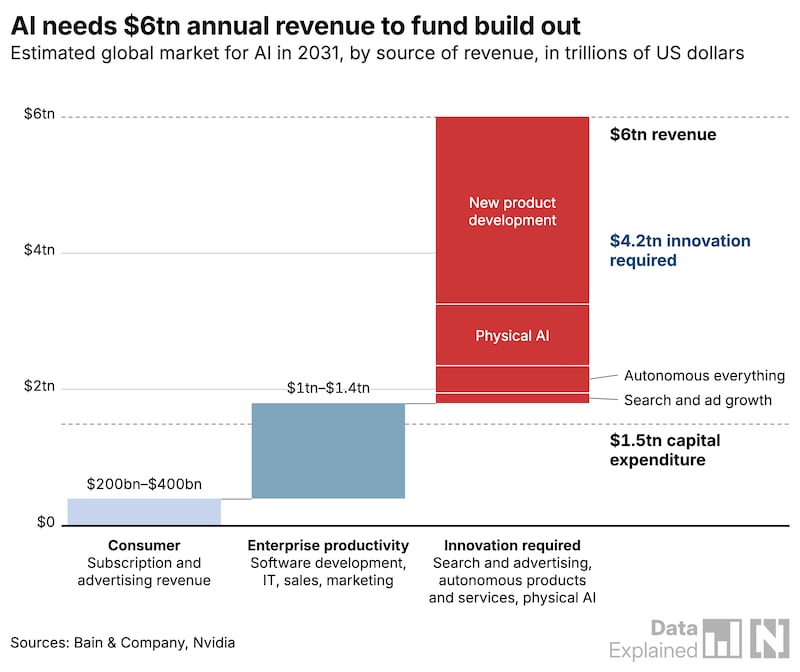
Consider the scale of investment and the gap between that and the revenue model necessary to fund it.
- The arms race among hyperscalers (Microsoft, Google, Amazon, Meta, and Oracle) is accelerating: Their capital expenditures could reach $780 billion in 2026, nearly five times the level of just three years earlier.
- Leading-edge AI data centers today are approaching 1 gigawatt (GW) of power capacity. By 2027, many are expected to approach 2 GW facilities, with 9 GW campuses emerging by the end of the decade.
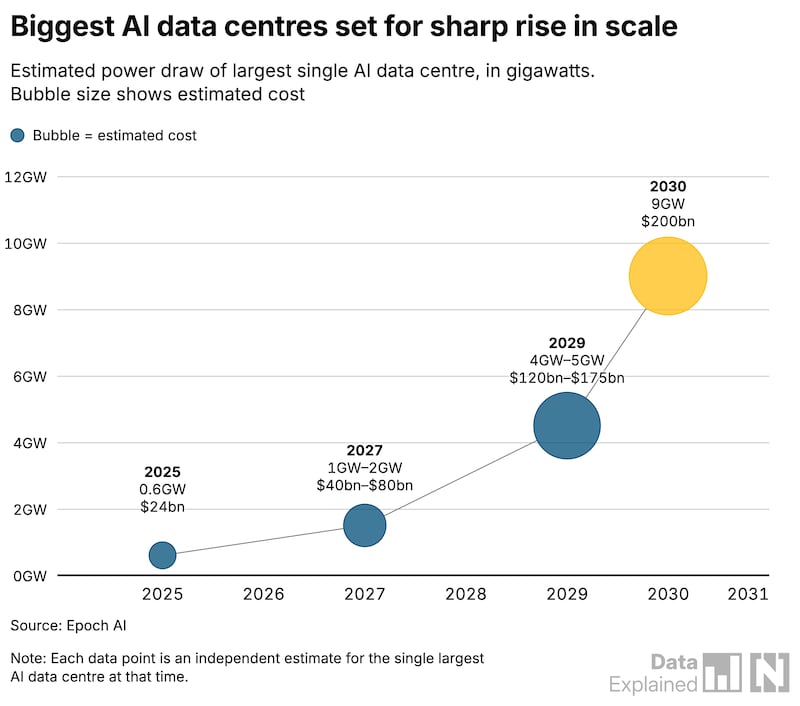
The scale of individual AI data-center projects illustrates the infrastructure requirements underlying those projections. Bain said AI data-center size and cost are increasing rapidly, with leading facilities approximately doubling in scale every 12 to 16 months. Meta Platforms’ Prometheus data center in Ohio, for example, had approximately 600 MW of capacity and an estimated cost of $24 billion in 2025, according to Epoch AI. The facility is projected to reach as much as 2 GW of capacity and cost approximately $80 billion by 2027. Epoch AI projects that Prometheus could reach 5 GW by 2029, with costs of up to $175 billion, and 9 GW by 2030, at an estimated cost of $200 billion.
Such growth places data-center infrastructure squarely within the telecommunications and network-infrastructure domain. Multi-gigawatt AI campuses require high-density optical interconnects, large-scale Ethernet or InfiniBand fabrics, low-latency east-west traffic engineering, high-capacity metro and long-haul connectivity, and resilient access to electric generation and transmission capacity. The infrastructure challenge consequently extends beyond data-center construction to the coordinated scaling of semiconductor supply chains, transport networks, power systems, cooling infrastructure and specialized technical labor.
Bain identified electric-grid capacity, access to GPUs and other critical infrastructure components, talent availability, workforce retention, public acceptance and regulatory requirements as important factors shaping the pace and geography of AI data-center deployment. Resource consumption, noise and community impacts are also becoming material considerations in project planning and approval processes.
Governments in the UAE, Saudi Arabia, the European Union, South Korea and the United States are supporting the expansion of AI and data-centre infrastructure, Bain said. The firm described data centres as increasingly important to technology innovation, economic development and national sovereignty.
The Bain report stated: “Capital needs for data infrastructure will remain high … bottlenecks in power, semiconductors, and other inputs carry large capital needs of their own, opening additional entry points for investors. And as sovereign infrastructure becomes a bigger part of national strategies, partnerships offer both a way in and geographic diversification.”
…………………………………………………………………………………………………………………………………………………………………………………………………………………….
Greg Ip of the WSJ: Believers in the artificial-intelligence boom need to take a very close look at this number: 9% of GDP. That is how much American businesses and consumers eventually have to spend per year on the services of companies like Anthropic and OpenAI to justify the staggering sums being committed to the technology right now.
Is it plausible that Americans will spend as much of their income on this one technology as they do on food? Roughly twice what the nation pays for all forms of energy or all computers and software? Seven times what consumers spend on phone, streaming, and internet services combined?
You should be skeptical. Even the most transformative inventions eventually run into the law of diminishing returns: each additional dollar a user spends yields less additional productivity (or enjoyment) than the last. That imposes a natural ceiling. The question, of course, is where that ceiling is. Whether or not you think 9% of GDP is right, you have to care, because this figure isn’t some fever dream: it is implicit in the dollars that investors and companies are committing right now.
The figure is courtesy of Columbia University finance professor Stijn Van Nieuwerburgh. His paper, first presented at the Brookings Institution, showed that the AI build-out is now bigger than any investment boom in American history. His more intriguing, and sobering, statistic is how much revenue AI would have to garner to justify that boom.
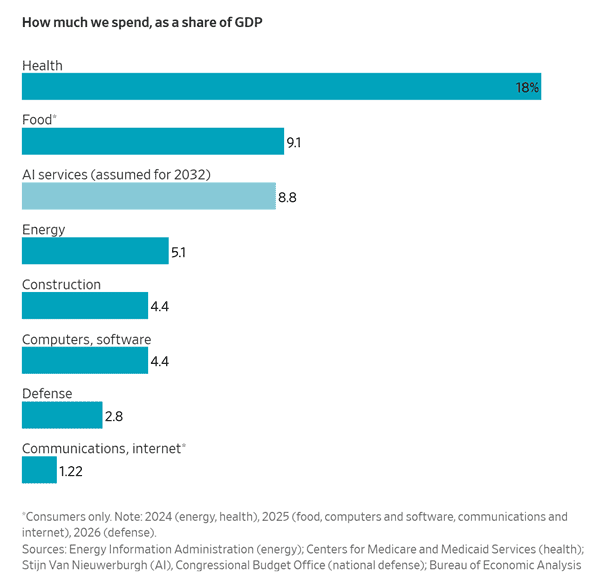
Conclusions:
- Dramatic innovation will be required to deliver the revenue necessary to fund the gap.
- The economics required to generate ROI from AI infrastructure are demanding trillions in new revenue, not just cost savings.
- The industry needs a wave of application innovation comparable with what mobile and cloud unlocked, not just productivity gains on existing workflows.
- The infrastructure is being built ahead of the demand curve, and funding it sustainably will require adding approximately 1% to the annual global GDP growth rate.
- The question is whether the applications arrive in time to pay for it.
……………………………………………………………………………………………………………………………………………………………………………………………………………….
References:
https://www.bain.com/insights/topics/technology-report/
https://www.wsj.com/tech/ai/will-america-spend-9-of-its-gdp-on-ai-the-industry-is-counting-on-it-3501bb4f?st=HkbAZs&reflink=desktopwebshare_permalink&mc_cid=65590ec418&mc_eid=5917efd771
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Dell’Oro: Data Center capex grew 92% in 2Q-2026 (caveats galore)
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
The AI Infrastructure Build-Out: A $10 Trillion Bet on Compute, Power, and Networks
Introduction:
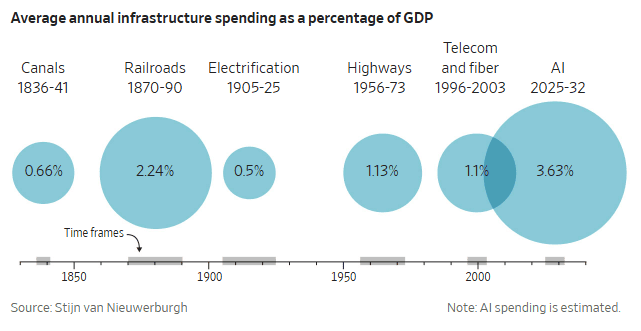
According to the Wall Street Journal, the AI build-out is rapidly becoming the largest concentrated infrastructure investment cycle in modern American economic history. Unlike earlier national build-outs—railroads, interstate highways, electrification, or the commercial internet—this cycle is being driven largely by a small group of cloud platforms deploying highly specialized compute, networking, power, cooling, and semiconductor infrastructure at unprecedented speed. Economist Stijn van Nieuwerburgh estimates that U.S. spending on data centers and related AI infrastructure could reach $10.3 trillion [1.] between 2025 and 2032, equivalent to an average of 3.6% of annual GDP. The estimate encompasses far more than conventional enterprise data centers: it reflects the industrial-scale infrastructure needed to train and serve frontier AI models, including GPU and accelerator clusters, high-bandwidth memory, advanced packaging, optical interconnects, high-capacity Ethernet and InfiniBand fabrics, grid interconnection, substations, backup generation, liquid cooling, and long-haul fiber connectivity.
Note 1. The $10.3 trillion number is a scenario-based estimate of U.S. AI infrastructure investment during 2025–2032—not a forecast of announced corporate spending. The Brookings analysis behind it assumes that about 183 GW of new data-center capacity will be completed through 2032, versus a 509-GW announced/planned pipeline. A representative 200-MW AI campus is estimated to cost about $8.2 billion: $5.6 billion for IT equipment, $2.2 billion for the facility, and $0.4 billion for power infrastructure. Thus, most of the investment is in compute and networking hardware rather than buildings.
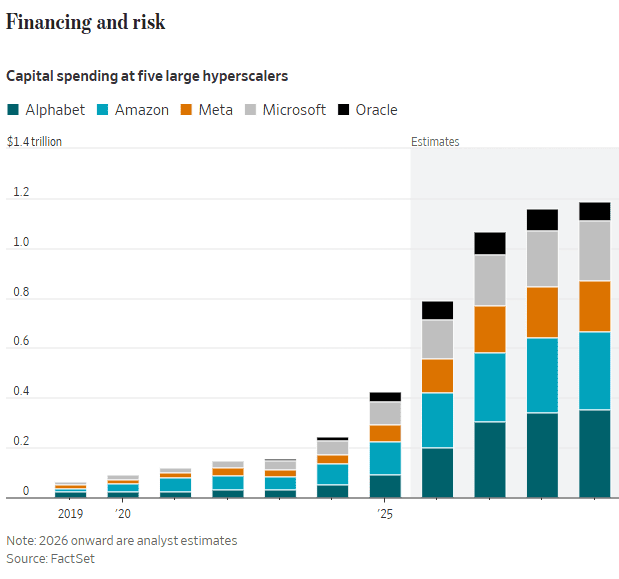
The scale creates a major financing challenge: the five largest hyperscalers are projected to spend about $800 billion on capex in 2026, exceeding their combined operating cash flow. Under the Brookings assumptions, the resulting infrastructure would need roughly $3.7 trillion of annual revenue by 2032 to produce a 10% unlevered return. The key economic issue, therefore, is whether future AI revenue and utilization can justify the enormous capital investment.
From Cloud Data Centers to AI Factories:
The defining characteristic of this AI buildout investment cycle is its concentration. The five U.S. hyperscalers (Alphabet, Amazon, Meta, Microsoft, and Oracle) are collectively expected to invest roughly $4.2 trillion in capital expenditures during the four years ending in 2029, according to FactSet estimates cited in the source material. Increasingly, this capital is directed toward AI-optimized facilities: campuses designed around megawatt-scale accelerator pods, dense GPU clusters, high-radix network fabrics, and power delivery systems capable of supporting workloads whose energy and cooling profiles differ sharply from those of traditional cloud computing.
Those five major hyperscalers increased combined capital expenditures from approximately $97 billion in 2020 to more than $400 billion in 2025, with the paper projecting approximately $800.5 billion in 2026. That 2026 figure is significant because it exceeds their combined operating cash flow of approximately $707.1 billion. In other words, projected capex is about 113% of operating cash flow. Pacific Software Ventures That creates a MAJOR financing problem: AI infrastructure investment is becoming too large to be financed entirely from hyperscaler internally generated cash.
AI infrastructure is not simply an expansion of conventional cloud capacity. Large-model training and inference create a distinct systems-engineering problem. Training AI frontier foundation models requires thousands to hundreds of thousands of tightly coupled accelerators. Those accelerators must exchange model parameters, activation data, and gradients at extremely high rates. Network performance therefore becomes a first-order determinant of usable compute capacity. A GPU cluster can deliver poor economics if its fabric introduces congestion, latency, packet loss, or inadequate bisection bandwidth during distributed training.
That requirement is accelerating deployment of:
-
GPU- and AI-accelerator servers with high-bandwidth memory and advanced semiconductor packaging.
-
High-speed scale-up interconnects within accelerator nodes and scale-out fabrics across clusters.
-
400 GbE, 800 GbE, and emerging 1.6 TbE Ethernet architectures, along with InfiniBand deployments for tightly coupled training environments.
-
Optical transceivers, co-packaged optics research, photonic switching, and expanded fiber density within and between data-center campuses.
-
AI-aware workload scheduling, distributed storage, data pipelines, checkpointing systems, and network telemetry.
-
Direct-to-chip liquid cooling, rear-door heat exchangers, chilled-water systems, and other thermal-management systems required by high-density AI racks.
-
New transmission lines, substations, transformers, gas generation, battery systems, and other power infrastructure needed to support multi-hundred-megawatt and gigawatt-scale campuses.
In effect, hyperscalers are building what are increasingly described as AI factories: integrated physical and digital production systems that convert electricity, capital equipment, data, and semiconductor capacity into trained models, inference tokens, and AI-enabled cloud services.
A Historically Large Capital Concentration:
AI investment is projected to reach 1.9% of U.S. GDP in 2026, according to Goldman Sachs estimates cited in the source material. The late-19th-century railroad boom was the last period in which a single new infrastructure category represented a larger share of the U.S. economy.
The comparison is useful, but incomplete. Railroads connected physical markets over decades. The AI build-out is being deployed on a far more compressed timetable and is dependent on global supply chains for leading-edge accelerators, high-bandwidth memory, advanced substrates, optical components, power equipment, and data-center construction capacity.
This creates a reinforcing investment loop:
-
Foundation-model developers require more compute to train larger or more capable models.
-
Cloud providers build additional accelerator capacity to support training and inference demand.
-
Semiconductor vendors, memory suppliers, networking companies, optical-component manufacturers, and power-equipment suppliers expand production.
-
Data-center developers secure land, power contracts, grid interconnections, fiber routes, water or cooling capacity, and financing.
-
Enterprises adopt AI services, increasing inference demand and reinforcing hyperscaler investment.
The strategic question is whether revenue from AI applications, enterprise subscriptions, API usage, advertising optimization, software agents, automation, and industry-specific deployments will scale fast enough to justify the capital intensity of the underlying infrastructure.
Financial and Infrastructure Risks:
The scale of investment introduces material financial-system risk. A growing portion of AI-related infrastructure is being financed through debt, including special-purpose entities and off-balance-sheet structures that may have limited public disclosure. These structures can allow technology companies and infrastructure developers to finance data-center construction, equipment purchases, and long-term capacity commitments without placing all obligations directly on corporate balance sheets.
That can be economically rational when capacity utilization is high and long-term AI demand is durable. However, it also creates exposure if expected AI revenues, cloud bookings, or accelerator utilization fail to materialize.
The central risk is not merely that an individual model underperforms. It is that a synchronized reduction in AI capital expenditure could affect multiple interconnected sectors at once:
-
Data-center developers and construction firms.
-
Semiconductor, memory, storage, and server suppliers.
-
Optical networking and switching vendors.
-
Utilities, independent power producers, and grid-equipment manufacturers.
-
Banks, private-credit funds, infrastructure lenders, and equipment-finance providers.
-
Commercial real-estate markets in data-center-heavy regions.
A sudden pause in hyperscaler spending would therefore have broader consequences than a typical technology downcycle. It could reduce orders across a deeply interdependent industrial supply chain while exposing leveraged infrastructure vehicles to weaker cash flows.
IT Product Inflation, Power, and Network Capacity:
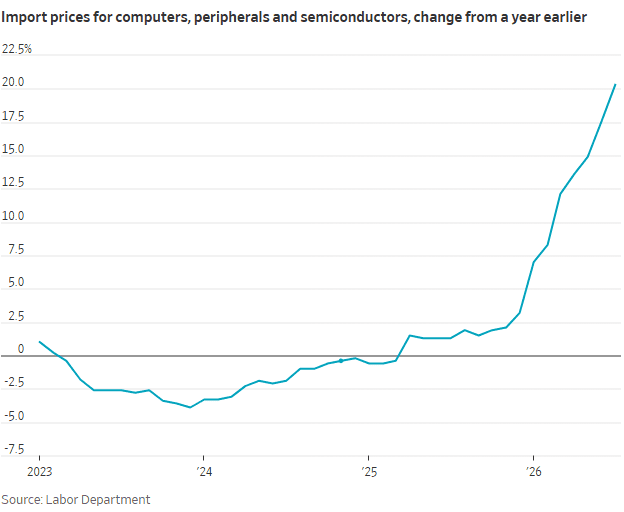
The AI build-out is also creating supply-side pressure in strategic technology markets. Demand for data-center equipment—especially memory, advanced semiconductors, servers, optics, and power-delivery equipment—has tightened supply and raised costs. The source material notes that prices paid by importers for computers, peripherals, and semiconductors were 20% higher in August than a year earlier.
That inflation can propagate beyond the data center. Higher component prices can increase the cost of consumer electronics, including smartphones, PCs, gaming systems, and storage products. Enterprises may also face higher prices for servers, networking equipment, cloud services, and AI-enabled software.
Power is an equally important constraint. AI data centers concentrate demand geographically, often creating large and relatively inflexible new loads on regional grids. A single large campus may require hundreds of megawatts, while the next generation of AI campuses could require gigawatt-scale capacity. This is driving demand for new generation, transmission capacity, substations, transformers, energy storage, and grid-management technologies.
The result is a collision between digital infrastructure planning and energy-system planning. Data-center capacity is no longer determined primarily by real estate, fiber connectivity, or server availability. In many markets, the gating factor is now the ability to obtain firm power, complete interconnection studies, procure transformers and switchgear, and finance new grid infrastructure.
Conclusions:
For IEEE Techblog readers, the central issue is not whether AI demand is real. It is whether the industry can build an economically sustainable, energy-efficient, resilient, and interoperable infrastructure stack at the required scale.
That challenge spans multiple engineering domains:
-
Semiconductor architecture, packaging, memory bandwidth, and energy efficiency.
-
Data-center electrical design, cooling, rack density, and operational resiliency.
-
High-performance networking, congestion control, optical interconnects, and distributed-system design.
-
AI software optimization, including model efficiency, quantization, sparsity, scheduling, and inference optimization.
-
Grid integration, power electronics, demand response, and energy-aware workload placement.
-
Security, supply-chain assurance, and operational management across increasingly autonomous infrastructure.
The AI boom may indeed become the defining infrastructure investment cycle of this era. Its long-term success, however, will depend less on headline capital-expenditure totals than on whether the industry can translate massive spending on accelerators and data centers into durable productivity gains, commercially viable AI services, and infrastructure that does not impose unsustainable costs on power systems, supply chains, consumers, or the financial sector.
………………………………………………………………………………………………………………………………………………
References:
Dell’Oro: Data Center capex grew 92% in 2Q-2026 (caveats galore)
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Bain: AI to greatly increase network operator expenses; network re-engineering needed!
Introduction by Bain:
“Over the next three to five years, the operating cost structure used by telecom operators is likely to undergo one of the most significant shifts in decades. As AI agents become embedded across customer care, network operations, software engineering, and enterprise functions, tokens will account for a growing share of operating expenditures.”
Key Points:
- Unless telcos proactively manage their costs, scaling up AI will simply add expenses to an already-heavy legacy base.
- An agentic operating model is emerging: a 70-to-30 ratio of legacy to AI costs, with AI automating or augmenting work across processes.
- Cost traps lurk: cheaper AI models, bigger bills; bolting AI onto legacy processes; and demos mistaken for transformation.
- Telco leaders can take five key actions today to avoid the traps.
Executive Summary:
Telecom operators are extending AI agents across network operations as they pursue higher levels of autonomy, but the shift could introduce a significant new operating-cost burden unless legacy processes, tooling and organizational structures are retired alongside the automation, according to Bain & Company.
Bain’s warning comes as operators accelerate plans for autonomous networks. TM Forum reported in June that 81% of 80 surveyed operators are targeting Level 4 autonomous networks or higher by 2030, and 20% expect to reach that threshold by 2027.
Under TM Forum’s Autonomous Networks framework, Level 4 moves beyond rule-based or preconfigured automation toward closed-loop, intent-driven decision-making within defined network domains. Current Level 4 work includes deployment of closed-loop operations in production networks, agent-based operating architectures, and metrics intended to quantify the operational and business value of autonomous-network use cases.
-
- Lagging Returns: According to Bain’s Automation and AI Pathfinder Survey, nearly 40% of companies saw AI cost savings land below 10%.
- Growing Budgets: Despite missing initial savings targets, 90% of these companies are still increasing their AI budgets.
- Autonomous Agents: Only 7% of companies currently run fully autonomous AI agents in production. Data access remains the top barrier to progress.
- AI Summaries: Bain’s research on Zero-Click Search shows that 80% of consumers rely on AI-written results for at least 40% of their searches.
- Fewer Clicks: About 60% of searches now end without the user clicking through to another website. This shift reduces organic web traffic by 15% to 25%.
Bain estimates that AI agents and associated token consumption could represent 20% to 30% of a telecom operator’s operating-cost base within the next three to five years, leaving conventional operating costs at 70% to 80%.
As AI spending rises, telcos risk increasing total costs without generating proportional gains in productivity or growth.
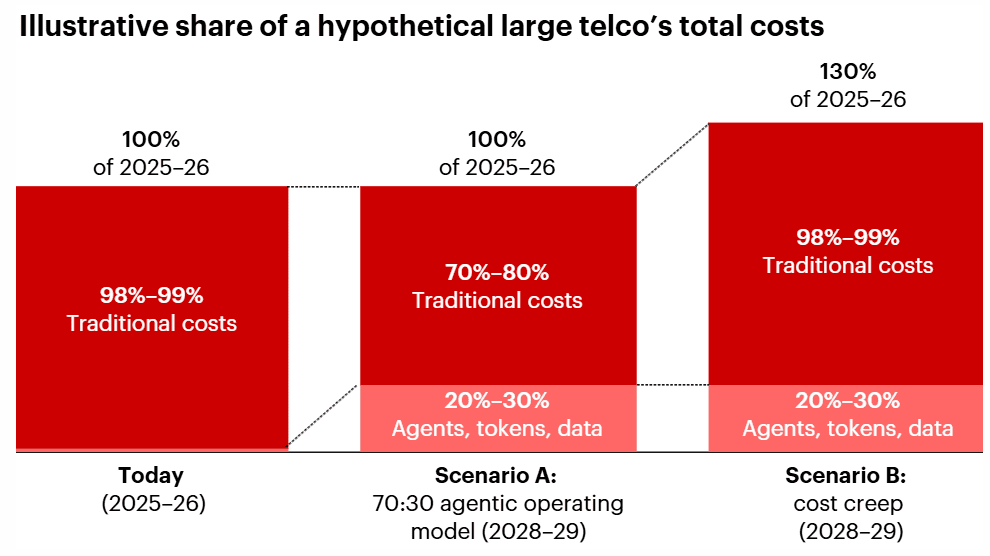
Notes: Illustration doesn’t incorporate absolute value changes; traditional costs are fully loaded, including costs from traditional software-as-a-service and cloud infrastructure, agency/outsourcing, depreciation, and more. Source: Bain estimates
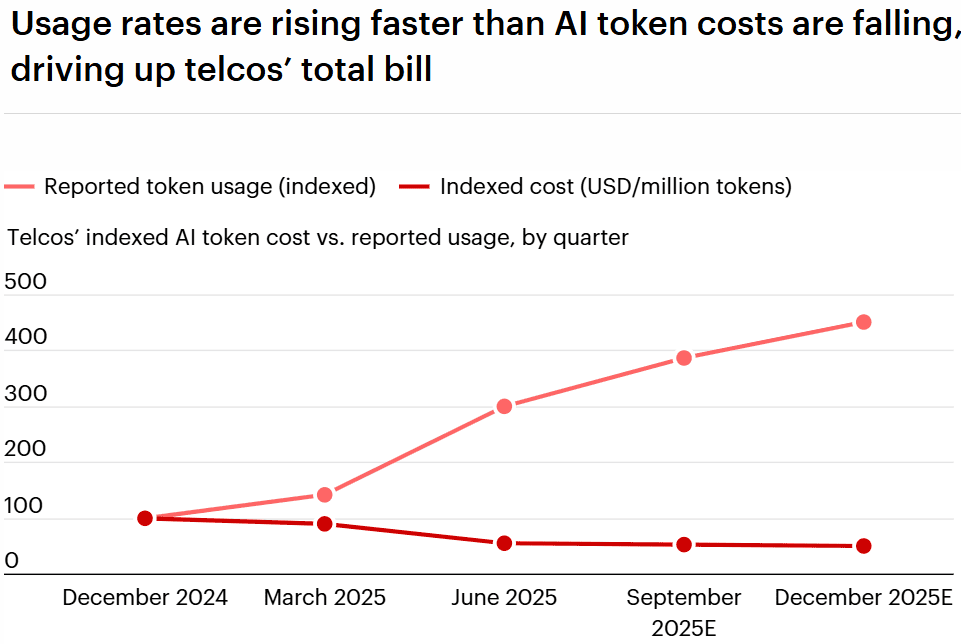
Sources: Wells Fargo (October 2025); Barclays (November 2025); company websites; news and industry reports; Bain analysis.
…………………………………………………………………………………………………………………………………………………………………………………..
However, cost is not the main issue. The principal risk is that network operators can create a parallel operating model when they layer agentic AI onto established network-operations processes without eliminating the people, software, outsourced functions and infrastructure those processes were designed to support.
In that scenario, AI compute, model inference and agent orchestration become incremental expenses, while legacy network operations centers, monitoring platforms, user-facing software licenses, managed-service arrangements and manual operational handoffs remain largely intact.
Network Re-engineering Required:
Avoiding this outcome requires process re-engineering rather than task-level automation. Bain recommends that operators redesign end-to-end workflows around the work agents assume, including:
-
Reducing manual monitoring, ticket triage and operational handoffs.
-
Reassessing workforce requirements as agents absorb repeatable diagnostic and remediation tasks.
-
Reviewing software, tooling and managed-service contracts when agents begin performing functions previously executed through conventional applications or outsourced processes.
-
Removing redundant operational steps rather than simply automating them.
-
Measuring the cost of an operational outcome, rather than the unit cost of model inference or token consumption.
This distinction is especially important in network operations, where an agent may continuously ingest alarms, correlate events, retrieve telemetry, diagnose faults, select a remediation action, trigger network tools, validate results and escalate exceptions to human operators. Each stage can add cost.
Inference is therefore only one component of the AI operating model. A production-grade agentic workflow may also require orchestration, tool and API calls, runtime evaluation, observability, data storage, policy enforcement, security controls, human-in-the-loop escalation and supporting compute infrastructure.
Bain argues that operators should evaluate the complete cost of the resolved operational event. For a service-affecting incident, that includes the total cost of detection, triage, diagnosis, remediation, validation and any remaining human intervention—not simply the marginal cost of the model invocation.
Closed-Loop Operations and Opex Reduction:
Bain cited Vivo in Brazil as an example of an operator redesigning a complete network workflow around AI-enabled automation rather than applying automation to discrete tasks. As part of Telefónica’s Autonomous Network Journey program, Vivo implemented a self-healing mechanism for its virtualized standalone 5G core.
The implementation monitors network-function performance, detects anomalies, identifies root causes and applies corrective actions automatically. It then validates whether the action restored normal operation and can progress to an additional remediation level when required.
Telefónica said the system correlates events across logical and physical infrastructure and completes the detect-to-resolve sequence without human intervention. For the targeted incidents, the company reported a 30-minute reduction in mean time to resolution.
The deployment also reduces repetitive work and manual intervention, while improving the use of computational resources. Telefónica has not disclosed a monetary estimate of the operating-cost savings associated with the implementation, however.
The significance of the Vivo deployment is architectural as much as operational. It integrates detection, correlation, diagnosis, remediation and verification into a closed-loop workflow. That is materially different from deploying an AI assistant within an otherwise unchanged operating model.
Other operator deployments illustrate the potential conventional opex benefits associated with higher autonomy. In a TM Forum case study, China Mobile reported that intelligent agents helped its network operations center achieve Level 4 autonomy under its self-assessment using TM Forum’s Autonomous Networks Levels framework.
China Mobile reported:
-
More than 30% reduction in backend operations-and-maintenance manpower.
-
More than 5% savings in frontline installation-and-maintenance manpower.
-
An average 30% reduction in mean time to repair for network faults and customer complaints.
An earlier TM Forum autonomous-network case study involving China Mobile reported O&M efficiency improvements of 10% to 20%, service-provisioning time reductions of 30% to 50%, and energy-consumption reductions of 3% to 5% across participating internet data centers and base stations.
The reported figures are operator-reported results published through TM Forum case studies. They demonstrate the possible efficiency gains from closed-loop automation, but they do not eliminate the need to account for AI-specific costs such as inference, orchestration, tool execution, supporting infrastructure and operational governance.
Measure Autonomous Networks by Outcomes:
TM Forum is also developing mechanisms to measure the value generated by autonomous-network deployments. In July, it approved version 2.0 of its Autonomous Networks High-Value Scenarios Effectiveness Indicators guide, intended to help operators quantify the impact of Level 4 autonomous-network scenarios.
This outcome-based approach aligns with Bain’s recommendation. For network operations, operators should move beyond narrow AI measures such as token counts, model cost per query or inference latency. Those measures remain operationally useful, but they do not establish whether an AI deployment improves the economics of network operation.
The most relevant measures include:
An operator may accept higher AI spending per workflow if it meaningfully reduces outage duration, truck rolls, customer-impacting incidents, workforce requirements or service-activation delays. Conversely, a deployment that lowers model-inference costs but leaves manual handoffs, duplicate monitoring tools and legacy support structures unchanged may offer limited net operating benefit.
AI Consumption at Telecom Scale:
AT&T has illustrated the potential scale of enterprise AI consumption, although its reported figures span AI workloads across the business and are not limited to autonomous network operations. The operator said in July that it processes an average of 45 billion tokens per day.
AT&T uses an AI gateway to route tasks among models based on cost, latency and expected output quality. The company said the platform can switch models during multi-turn interactions and has reduced costs for certain AI workloads by as much as 90%, producing multimillion-dollar savings.
The operating principle is relevant to telecom network automation: only a minority of tasks require the most capable—and most expensive—models. Routine classification, alarm enrichment, knowledge retrieval, configuration validation and other bounded operational tasks may be suitable for smaller models, purpose-built models or conventional deterministic automation. More capable reasoning models can be reserved for ambiguous, multi-domain or exception-heavy cases.
Bain similarly recommends matching model capability to task complexity rather than applying a single model class across every AI workload. Operators should establish dedicated compute budgets, instrument workflow-level economics and treat inference capacity as an operational resource that requires active governance.
Governing Agentic Network Operations:
Agent behavior itself can become a material source of cost and operational risk. Poorly designed agents may repeatedly transmit large context windows, loop without completing a task, invoke overlapping diagnostic tools or conduct duplicative checks that add token and infrastructure consumption without improving the result.
Bain recommends guardrails that limit both expenditure and runtime. In a telecom network-operations environment, those controls could include:
-
Maximum token, compute and tool-call budgets per incident or workflow.
-
Time limits before an agent must escalate an unresolved task to a human operator.
-
Context-management rules that prevent unnecessary repetition of telemetry, alarms and historical ticket data.
-
Controls to consolidate overlapping diagnostic checks and duplicate agent activity.
-
Policy constraints governing which network changes an agent may propose, execute or validate autonomously.
-
Continuous monitoring for model drift, abnormal agent behavior, spending anomalies and degraded operational outcomes.
-
Explicit business and financial ownership for each production agent and workflow.
The central issue is that autonomous networks will not necessarily lower opex simply because they reduce manual work. Operators must also remove the legacy cost structures that agentic systems replace. Otherwise, AI agents risk becoming an additional layer of expense on top of existing network operations rather than the foundation for a more efficient operating model.
……………………………………………………………………………………………………………………………………….
References:
Bain & Co, McKinsey & Co, AWS suggest how telcos can use and adapt Generative AI
McKinsey: AI infrastructure opportunity for telcos? AI developments in the telecom sector
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
5G infrastructure moves from coverage and speeds to cloud-native, orchestration, automation and AI-assisted networks
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
Executive Summary:
Google parent Alphabet’s emerging business of selling artificial intelligence (AI) accelerator chips is twice as large as a cloud computing rival, Google executive Thomas Kurian claimed Tuesday at a Goldman Sachs investors conference.
On July 22, Google reported second-quarter cloud-computing revenue of $24.77 billion, up 82% year over year, driven by artificial intelligence workloads, handily beating estimates of $22.46 billion. For the first time, Google included third-party sales of AI accelerator chips, called tensor-processing units, in cloud revenue.
Kurian, head of Google’s cloud business, made these remarks at Goldman Sachs’ Communacopia conference:
“We offer the best computational infrastructure for AI, and we offer 3 types of silicon. NVIDIA GPUs, our own Tensor Processing Units (TPUs), custom ARM silicon. [As AI models generate code awe also offer our own Arm processors to run that code.] We offer 2.7x better price performance for training, 80% better price performance for inference, 30% better price performance for CPUs. All of that allows us to differentiate our portfolio from other providers. It allows us to offer solutions to financial markets and capital markets.”
“The size of our accelerator business, our TPU business, is more than twice that of the next-largest hyperscaler.”
“Our platform is called Gemini Enterprise. It is used by over 90% of the Fortune 100 and thousands of small businesses. It’s used in a very specific way. People want to use it as a reasoning agent. So break the plan, understand the steps that are needed, reason on it and execute the steps. So it uses a reasoning agent to understand all the information in the company to then automate that workflow process. And when it does it, you want strong controls. What kinds of controls? Companies are worried about security. They’re worried about auditing, what these agents are doing. They want to manage costs and set budget caps. We have all those controls. And we allow people to use the right model for the right task. So you don’t have to always use the most expensive model, saving people a lot of money in doing so. We have a range of companies from insurance.”
–>You can read the entire transcript here. For more on Google’s TPUs please see:
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Google’s TPU photo
……………………………………………………………………………………………………………………………………………………
Kurian added that Google monetizes TPU systems through three business models. One is letting companies rent TPU processing at its own cloud business. Also, Google sells TPU systems directly for deployment in customers’ data centers. One such customer is Anthropic. Third, Google also sells TPUs through a Blackstone cloud computing joint venture.
Google’s AI Chip Business:
In May, Google introduced Ironwood, its eighth-generation of TPUs. The Ironwood TPUs target both training of AI models and “inferencing” — processing AI workloads.
In a report published Aug. 24, Morgan Stanley analyst Brian Nowak estimated that Google cloud could garner $84 billion in “first party” — meaning non-cloud rental — TPU sales in 2027.
“We are raising our TPU sale estimates to $27 billion selling at a 30% gross margin,” Nowak said. “In all, we now expect Google to sell 0.3 gigawatts of TPU systems in the second half of 2026, 3.2 gigawatts in 2027 and 4.2 gigawatts in 2028. This translates into $84 billion/$108 billion of TPU-related Google cloud revenue in 2027 and 2028.”
In Q2-2026, Google said its cloud computing order backlog jumped to $514 billion, up from $460 billion in Q1. The backlog is converted into realized revenue as new data centers come online and crunch artificial intelligence-related workloads — training AI models and processing AI apps.
Google has increased its 2026 capital spending guidance to a range of $195 billion to $205 billion. Most of the spendings is going toward AI data centers and AI model development. In Q2, capital spending jumped 100% from a year earlier to $44.9 billion.
Kurian, a former top executive at Oracle, took over as the cloud-computing unit’s CEO in November 2018. When Kurian arrived, Google’s cloud customers were mostly other tech companies. Under Kurian, Google has targeted enterprise customers with cloud-based data-analytics and artificial intelligence tools.
Hyperscaler Custom Silicon: Meta, Microsoft, Oracle, and the Shift to In-House AI Accelerators:
While Google’s TPU business has reached a scale that Kurian says is more than twice that of the next-largest hyperscaler, other cloud and platform operators are rapidly expanding their own custom AI silicon programs to reduce dependence on Nvidia GPUs and optimize cost, power, and workload-specific performance.
Amazon.com has developed in-house Trainium AI accelerators while Microsoft has developed Maia AI chips. Amazon is further ahead than Microsoft in selling AI chips to outside customers, analysts say.
Meta – MTIA Family Targets Inference at Scale:
Meta has moved aggressively into custom silicon with its Meta Training and Inference Accelerator (MTIA) family, announcing four new chips — MTIA 300, 400, 450, and 500 — in March 2026 as part of a strategy to diversify hardware sources and lower AI infrastructure costs. The MTIA 300 entered production in mid-2026, with subsequent generations rolling out on an approximately six-month cadence through 2027.
Meta’s MTIA chips are manufactured by TSMC and co-developed with Broadcom under a multi-year partnership extending through 2029. The roadmap spans ranking and recommendation training (MTIA 300), combined generative AI and ranking workloads (MTIA 400), and decode-optimized generative AI inference (MTIA 450 and 500), with mass deployment of the flagship MTIA 500 planned for late 2027. Meta plans to put its own AI chip into production in September and is aiming to roughly double the computing capacity across its data centres.
By mid-2026, Meta, Amazon, Microsoft, and OpenAI have each closed the gap on the three key AI inputs — custom chips, power, and models — that only Google held in 2021.
Microsoft: Maia 200 and the Push to External Customers:
Microsoft unveiled its first custom AI accelerator, Maia 100, at Hot Chips 2024, followed by the inference-optimized Maia 200 in January 2026. Maia 200, built on TSMC’s 3 nm process with more than 140 billion transistors, 216 GB of HBM3e, and over 10 PFLOPS of FP4 compute within a 750 W SoC TDP, is designed to deliver 30% better performance per dollar for AI token generation.blogs.
Maia 200 will serve multiple models, including OpenAI’s GPT-5.2, and support Microsoft Foundry, Microsoft 365 Copilot, and reinforcement learning workflows. Microsoft plans to unveil next-gen Maia 300 AI chip in September, aiming to lower costs for in-house and OpenAI models while actively courting major enterprise customers. Anthropic is reportedly in talks with Microsoft to rent the company’s custom AI server chips as it looks to expand computing capacity.blogs.
Oracle: Partner-Led AI Clusters Rather Than Custom Silicon:
Oracle has taken a different path, opting not to develop its own AI accelerator but instead building large-scale AI clusters using third-party chips from Nvidia and AMD. Oracle plans to install the first MI450-equipped Helios racks in its OCI data centers during the third quarter of 2026, with an initial deployment targeting 50,000 MI450 processors.
Oracle’s AI strategy emphasizes rapid deployment of massive GPU-based clusters to serve anchor tenants like OpenAI under a reported $300 billion, five-year cloud computing contract beginning in 2027. In parallel, OpenAI is diversifying its supply of compute by designing its own chips with partners like Broadcom, with the first custom AI inference chips expected to deploy in the second half of 2026.
Market Implications:
By 2026, five of six major AI players — Google, Meta, Amazon, Microsoft, and OpenAI — now control at least two of the three critical AI inputs (chips, power, models), down from only Google in 2021. This vertical integration trend is reshaping the AI infrastructure market, with hyperscalers increasingly using custom silicon to optimize cost and performance for specific workloads while maintaining strategic flexibility through multi-vendor GPU procurement.
Google’s TPU v7, Amazon’s Trainium 3, Microsoft’s Maia 2, and Meta’s MTIA 2 all ramped into volume production in 2025–2026, signaling a maturation of the hyperscaler custom silicon ecosystem. Meta is also the first commercial gigawatt AMD MI450 deployment in H2 2026, illustrating a hybrid approach that combines in-house accelerators with third-party GPUs.
…………………………………………………………………………………………………………………………………………………..
References:
https://www.investors.com/news/technology/google-stock-cloud-kurian-ai-chip-business/
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Google announces Gemini: it’s most powerful AI model, powered by TPU chips
Google Cloud and Verizon Expand Strategic Partnership to Scale Enterprise AI and Autonomous Network Operations
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
Meta’s “Iris” AI Chip for MTIA: Implications for Telecom-Grade Optical Networking, DCI and High Capacity Ethernet Fabrics
Custom AI Chips: Powering the next wave of Intelligent Computing
AI Compute Has a Switchboard Problem: Orchestration & Data Center Fabric Explained
South Korean startup Rebellions to use open source software for carriers to quickly build AI stacks with its AI inferencing chips
Autonomous customer experience required for AI-Native 6G and distributed intelligence at the network edge
Executive Sumary:
Communications service providers (CSPs) have historically competed on network-centric KPIs—coverage, capacity, reliability, and price—anchored in 3GPP performance and management frameworks (e.g., TS 28-series, TS 23.501 QoS models). However, these metrics alone are no longer sufficient to sustain differentiation in increasingly saturated and capital-intensive markets, according to Chantel Cary, Product Marketing Senior Manager at Oracle Communications [1],
“The battleground has shifted,” Cary told Capacity Global. “Today, customer experience is becoming the clearest point of differentiation, and in many cases, the most important driver of growth.”
This shift is unfolding alongside structural constraints: flat ARPU, rising capex associated with 5G standalone, fiber access (FTTx), and edge cloud expansion, and increasing customer acquisition and retention costs. At the same time, customer expectations—benchmarked against hyperscaler-grade digital platforms—are becoming uniformly high across mobile and fixed broadband services.
“They do not compare a telecom provider only to other providers,” she said. “They compare every experience to the best experience they have anywhere.”
…………………………………………………………………………………………………………………………………………………………………………………………………………………..
Note 1. Oracle Communications is a dedicated global business unit and product portfolio fully owned and operated by Oracle. It provides enterprise software and infrastructure designed specifically for telecommunications service providers (like AT&T or Verizon) and large enterprises. Their solutions manage everything from network routing, security, and signaling (including 5G) to back-office billing, revenue management, and customer experience operations,
…………………………………………………………………………………………………………………………………………………………………………………………………………………..
Analysys Mason reports that 97% of operators view AI-powered automation as essential for survival and growth, reinforcing alignment with TM Forum’s Autonomous Networks framework and the broader industry transition toward AI-native system design.
AI-Native Customer Experience Architecture:
Cary’s concept of “autonomous customer experience” maps directly to the emerging paradigm of AI-native networks, where intelligence is embedded across both network and service layers rather than applied as an overlay. “It is not about removing the human element from engagement,” she explained. “It is about using AI to continuously orchestrate the customer lifecycle in ways that humans alone cannot manage at scale.”
In wireless networks, this evolution is reflected in 3GPP-defined enablers such as the Network Data Analytics Function (NWDAF, TS 23.288), which provides real-time analytics to optimize policy control, mobility, and QoS. In parallel, O-RAN Alliance architectures introduce the near-real-time and non-real-time RAN Intelligent Controllers (near-RT RIC, non-RT RIC), enabling AI-driven control loops for radio resource management and service optimization.
Image Credit: Aisera
In wireline and converged networks, similar principles are emerging through SDN-based control planes, broadband network gateways (BNG) with telemetry streaming, and ITU-T frameworks (e.g., Y.3172 for machine learning in future networks), enabling closed-loop optimization across access, aggregation, and core domains.
However, Cary notes that most OSS/BSS environments remain fragmented, limiting the ability to operationalize these capabilities at the customer experience layer. Data silos, batch-oriented processing, and loosely coupled workflows constrain real-time, cross-domain orchestration.
AI Across Commercial and Network Domains:
Cary identifies three primary domains of impact, increasingly converging with network intelligence:
-
Marketing: AI-driven personalization is evolving toward real-time, context-aware engagement informed by both customer behavior and network conditions (e.g., location, QoS state, congestion). This aligns with event-driven architectures and customer data platforms integrated with network analytics (e.g., NWDAF exposure via APIs). “Personalisation shifts from broad audiences to the individual,” she said, adding that relevance is now “a prerequisite for attention.”
-
Sales: AI enables next-best-action and dynamic offer generation, incorporating network-aware insights such as service availability, slice characteristics (in 5G SA), and fiber capacity constraints. Integration with policy control (3GPP TS 23.203) and service orchestration frameworks supports closed-loop order capture and fulfillment. “That combination of higher conversion and lower friction is valuable,” she said.
-
Service: AI-driven assurance is transitioning from reactive fault management to predictive and intent-based service assurance across both wireless and wireline domains. Telemetry from RAN, transport, and fixed access networks feeds AI models that anticipate degradation and trigger remediation before customer impact. “Human agents still play a central role,” Cary said, “but they can be augmented with real-time recommendations, contextual history and autonomous processes that improve both speed and consistency.”
Scaling Challenges in AI-Native Transformation:
Despite progress in AI models and domain-specific analytics, Cary highlights a systemic gap in operationalization.
“What it lacks, in many cases, is the ability to turn fragmented customer data into real-time decisions that can actually be executed across marketing, sales and service,” she said.
Analysys Mason data indicates that only 6% of operators achieve ROI above 25% from AI initiatives, while 60% advance just 20% of proofs of concept into production. This reflects challenges in integrating heterogeneous data sources across OSS, BSS, and network domains, as well as limitations in MLOps and real-time orchestration frameworks.
Fragmentation is compounded in converged networks, where wireless (3GPP-based) and wireline (e.g., Broadband Forum TR-369/USP, TR-383 for disaggregated BNG) ecosystems often evolve independently. Additionally, 93% of operators cite multi-vendor complexity as increasing total cost of ownership, underscoring the need for interoperable, standards-based integration across AI, network, and IT domains.
“That creates an unfortunate pattern across the industry,” she said, “promising AI initiatives that demonstrate value in isolation but fail to scale because they are not connected to the data, systems and processes where real work happens.”
Toward Fully AI-Native Operations:
Cary emphasizes that the target state is not incremental automation but fully AI-native operations, where intelligence is embedded into both network control loops and customer engagement workflows.
“This is why the future of customer experience in communications is not about layering AI onto the edge of the enterprise,” Cary said. “It is about making AI operational at the core of engagement.”
This vision aligns with emerging 6G research directions, where AI is treated as a native design primitive across RAN, core, and service layers, as well as with TM Forum’s Open Digital Architecture (ODA), which promotes composable, API-driven integration between OSS, BSS, and AI components.
Oracle’s approach reflects this convergence by unifying customer data, embedding AI into engagement and orchestration layers, and integrating these capabilities with telecom operational systems across both wireless and wireline domains.
Implementation Suggestions:
Cary said that network providers do not need to transform everything at once. She recommends starting by unifying customer data across touchpoints to establish a trusted, real-time view, before activating high-value AI use cases across marketing, sales and service. From there, providers can embed AI into workflows so insight translates into action rather than sitting in dashboards, eventually connecting those capabilities into end-to-end orchestration.
Indeed, Cary advocates a phased approach consistent with AI-native transformation:
-
Establish a unified, real-time data fabric spanning customer, service, and network domains.
-
Deploy high-value AI use cases (e.g., next-best-action, churn prediction, predictive assurance) leveraging both IT and network telemetry.
-
Embed AI into execution workflows to enable closed-loop, intent-driven orchestration across the customer lifecycle.
This progression reflects the broader industry trajectory toward converged, AI-native networks, where customer experience is no longer an overlay on connectivity, but a direct outcome of tightly coupled intelligence across wireless and wireline infrastructures.
“The communications providers that lead in the years ahead will not be the ones that simply adopt more AI tools. They will be the ones that use AI to rethink how customer engagement works across the enterprise. AI is not just enhancing customer experience,” she added. “It is redefining how customer experience is delivered, and in communications, that shift is likely to separate the providers that keep pace from the ones that set the pace.”
………………………………………………………………………………………………………………………………
Editorial Analysis:
Cary’s vision aligns with IMT 2030/6G’s shift from AI as an overlay to AI as an architectural primitive, spanning the air interface, semantic service handling, and distributed edge intelligence across wireless and wireline domains. The cleanest way to map her suggestions into 6G is to treat “autonomous customer experience” as the service-layer expression of an AI-native network stack: AI decisions would no longer sit only in OSS/BSS, but would be distributed across RAN, transport, core, and edge applications, with closed-loop control spanning wireless and wireline domains. That maps well to current AI-native 6G proposals that emphasize model interdependencies, distributed intelligence, and AI embedded directly in the architecture rather than layered on top.
For the AI native air interface, the link is to AI-assisted radio control, where the network uses learned models to optimize scheduling, mobility, beam management, and QoS-aware policy decisions in real time. In a 6G framing, that extends beyond today’s AI for RAN optimization and toward an AI-native air interface in which the radio stack itself is designed for machine-driven adaptation, including distributed control loops between UE, RAN, and core. For your article, this supports language that customer experience is increasingly shaped by network intelligence at the point of access, not just by back-office engagement systems.ieeexplore.ieee+2
Semantic communications maps to the idea that the network should optimize for meaning or task relevance, not simply bit delivery. In practice, that means a 6G service layer could prioritize the semantic value of an interaction—such as whether a customer is trying to resolve an outage, confirm a move order, or change a plan—and allocate resources accordingly across wireless and wireline paths. The relevance to Cary’s argument is that customer experience becomes more contextual and intent-aware when the network itself can distinguish between low-value traffic and high-importance service interactions.
Distributed intelligence at the network edge is the most direct bridge between CSP operations and 6G design. In a converged wireless-wireline environment, edge AI can fuse RAN telemetry, fixed access metrics, subscriber context, and service history to trigger local decisions such as proactive care, dynamic QoS adjustment, or preemptive fault mitigation. That makes the experience layer more autonomous because the decision point moves closer to where the event occurs, reducing dependence on centralized, slower, batch-oriented processing.
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.nokia.com/6g/unlocking-the-full-potential-of-ai-native-6g-through-standards/
Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020)
SHIELD-6G with AI-native cyber threat intelligence platform to enhance cybersecurity for Europe’s future 6G networks
AT&T and Ericsson boost Cloud RAN performance with AI-native software running on Intel Xeon 6 SoC
Ericsson and Intel collaborate to accelerate AI-Native 6G; other AI-Native 6G advancements at MWC 2026
NVIDIA and global telecom leaders to build 6G on open and secure AI-native platforms + Linux Foundation launches OCUDU
AT&T and Ericsson boost Cloud RAN performance with AI-native software running on Intel Xeon 6 SoC
Huawei’s AI-Centric Network Vision: Six Imperatives for the Next Decade; Critical Questions for IEEE Techblog Community
The Case for AI-Native Networks:
At MWC Shanghai 2026 [1.], David Wang, Deputy Chairman of the Board and Rotating Chairman of Huawei, outlined a strategic roadmap for AI-native mobile networks, positioning artificial intelligence as the cornerstone of industry growth over the next decade.
Note 1. MWC Shanghai 2026 was held June 24–26, 2026 at the Shanghai New International Expo Center (SNIEC), with Huawei showcasing products and solutions in Hall N1.
Over the past 40 years, innovation in mobile technology from each generation to the next has been key to the industry’s success. “With each generation, we have pushed the limits of spectral efficiency and performance,” said Wang. “Network architecture has gradually flattened, with new application scenarios and services emerging left and right. This has consistently expanded the boundaries of communications, helping carriers translate network capabilities into commercial value,” he added.
Huawei argues that traditional telecom infrastructure built around data traffic is no longer sufficient. As the global digital ecosystem transitions toward real-time interactions with AI applications and intelligent agents, mobile and transport networks must be completely redesigned to support both communication and computing. According to Huawei, an AI-native architecture transforms networks from simple communication utilities into revenue-generating engines while helping operators transition to Level-4 and Level-5 network autonomy
Huawei’s Six Strategic Imperatives:
Wang identified six imperatives to guide the industry through the age of intelligence:
-
Developing new services and capabilities for future mobile communications systems
-
Integrating AI with mobile communications to build three distinct layers of intelligence
-
Building network architecture for integrated satellite-ground communications
-
Advocating for sustainable and future-oriented spectrum planning and allocation
-
Clearly defining the specifications of AI-native core networks
-
Exploring new business models and application scenarios for mobile services

Photo Credit: Huawei
Innovations Unveiled: Byte and Token Monetization:
Huawei released a portfolio of innovations targeting both services and infrastructure. On the services side, in collaboration with China’s three major carriers, the company announced advances in 5G-Advanced (5G-A) high-uplink and experience monetization, AI-powered business upgrades, and token monetization.
For infrastructure, Huawei launched the AI-centric target network, designed to enhance carrier competitiveness in byte and token monetization. This architecture comprises three layers:
-
Basic Communications Network: A shift from traffic-centric to real-time interaction networking, offering guaranteed connectivity with high uplink and downlink capabilities alongside advanced QoS mechanisms.
-
Computing Network: A transition from traffic transport to network-wide compute scheduling and supply, where “connecting to the network is equivalent to accessing compute.”
-
AI Computing Infrastructure: High-performance, efficient compute with support for open-source and open ecosystems.
5G-Advanced: 100 Million Users and Beyond:
The global 5G-A (based on 3GPP Release 18) user base has surpassed 100 million. Huawei is now working with network operators worldwide to advance 5G-A experience monetization and integrate it into installed base operations, targeting mid-range and high-end user retention, ARPU growth, and sustainable revenue expansion.
High Uplink Speed: The New Frontier for AI Applications:
High uplink capacity is critical for token monetization. Emerging AI applications—such as multimodal AI glasses for real-time translation and augmented exhibitions—demand uplink speeds of 20 Mbps or higher. In 2026, leading carriers globally are piloting commercial high-uplink services with guaranteed peak speeds, latency, and universal uplink performance.
Upper-6 GHz: The Next Golden Band:
The proliferation of AI agents is expected to drive rapid growth in token services, requiring ultra-broadband networks with high uplink, high reliability, and low latency. Upper-6 GHz (U6 GHz) is positioned as the next-generation golden frequency band for this purpose.
-
More than 20 countries and regions have designated U6 GHz for IMT, covering nearly 80% of the global population.
-
2026 marks the commercial debut of U6 GHz, with the Middle East expected to deploy the world’s first commercial 5G-A network on U6 GHz.
-
Select carriers in Hong Kong and Macao will also initiate commercial U6 GHz deployment.
AI-Native B2C and B2B Services:
Huawei plans to collaborate with carriers in Guangdong, Shanghai, Hebei, and other regions in 2026 to reengineer B2C and B2H services with AI, targeting consumer applications such as smart home assistants, personal communication assistants, and integrated consumer-home services. In the B2B segment, the focus is on AI computing services centered on compute-network integration, unlocking new business growth avenues.
Path to Level-4 Autonomous Networks:
Huawei is advancing AI-native technologies toward Level-4 autonomous networks by developing domain-specific intelligence. In 2026, the company will work with carriers to deploy domain-specific intelligence across wireless and transmission network domains in key regions. This will enable cross-domain synergy in maintenance, optimization, energy efficiency, and user experience, enhancing network quality and enabling differentiated products for high-speed rail, event venues, and campuses.
Critical Questions:
Huawei’s AI-centric network vision positions AI not as an incremental improvement to mobile networks but as a foundational network architecture. That vision raises several critical questions for the IEEE community and IEEE Techblog readers:
-
Interoperability: How does Huawei’s AI-centric target network align—or conflict—with AI-RAN Alliance initiatives and O-RAN specifications?
-
Vendor Comparison: How does Huawei’s AI-centric target network compare with Ericsson’s cloud RAN strategy and Nokia’s Altiplano/Corteca agentic AI platforms in terms of technical architecture and commercial viability?
- Specifications and Standards: What role will 3GPP and ITU-R play in standardizing AI-native core network specifications, particularly for token monetization and compute-network integration?
- Autonomous Networks: How do Huawei’s domain-specific intelligence approaches compare with vendor-neutral SMO/rApp ecosystems, and what are the implications for multi-vendor interoperability?
-
Are carriers adequately prepared for the operational and cultural shifts required to transition from traffic monetization to token monetization?
-
How will U.S./European regulatory frameworks (e.g. spectrum policy, AI governance, data sovereignty) shape the deployment of AI-native networks compared to China’s more centralized approach?
- Spectrum Policy: With Upper 6 GHz emerging as a key enabler for AI-driven token services, what are the regulatory and coexistence challenges, particularly in regions yet to designate Upper 6 GHz for IMT 2030? What will WRC 2027 decide?
Conclusions:
Huawei’s roadmap underscores the ICT industry’s rapid shift towards AI token monetization, positioning 5G-Advanced high-uplink, AI-native networks, and Upper 6 GHz spectrum as the foundational pillars for the next decade of growth. The success of this vision depends not only on technological feasibility but also on standards alignment, regulatory support, and carrier willingness to reinvent business models—a complex challenge that warrants close scrutiny from the IEEE technical community.
……………………………………………………………………………………………………………………………………………………………………………………
References:
https://www.huawei.com/en/news/2026/6/mwcs-ai-byte-token
https://carrier.huawei.com/minisite/mwcs2026/en/
https://www.huawei.com/en/news/2026/6/mwcs-gsma-asac-5g-advanced
Huawei unveils AI Centric Network roadmap, U6 GHz products, 5G Advanced strategy and SuperPoD cluster computing platforms
Huawei FY2025: 2.2% YoY revenue increase; strategic pivot to AI and intelligent automotive solutions
Huawei, Qualcomm, Samsung, and Ericsson Leading Patent Race in $15 Billion 5G Licensing Market
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
Huawei launches CloudMatrix 384 AI System to rival Nvidia’s most advanced AI system
U.S. export controls on Nvidia H20 AI chips enables Huawei’s 910C GPU to be favored by AI tech giants in China
Huawei Cloud Review and Global Sales Partner Policies for 2026
Huawei’s “FOUR NEW strategy” for carriers to be successful in AI era
Huawei to revolutionize network operations and maintenance
Huawei’s Electric Vehicle Charging Technology & Top 10 Charging Trends
Bloomberg: Meta to sell AI compute in a new cloud services offering
Disclaimer: Perplexity.ai was used for research resulting in this article.
Executive Summary:
According to Bloomberg, Meta Platforms is advancing plans to commercialize its internal AI infrastructure through a new cloud services offering, signaling a strategic expansion beyond its traditional hyperscale consumer platforms into the competitive AI infrastructure market. This initiative would position Meta alongside established cloud providers such as Amazon Web Services (AWS), Microsoft Azure, and Google Cloud, while also overlapping with emerging GPU-centric “neocloud” providers. Meta’s move represents a significant evolution in the AI infrastructure landscape, with potential ripple effects across data center architecture, optical transport networks, and the broader telecom ecosystem.
At the core of this strategy is the monetization of Meta’s rapidly expanding AI compute footprint. The company has aggressively invested in large-scale data center infrastructure—reportedly including multi-hundred-billion-dollar campus developments—to support training and inference for its proprietary large language models (LLMs) and recommendation systems. As these deployments scale, Meta appears to be seeking to externalize surplus capacity, transforming a cost center into a revenue-generating platform.
The proposed service portfolio is expected to span two primary layers. First, Meta may expose access to hosted AI models via APIs, analogous to AWS Bedrock or Azure AI Services, enabling enterprises to integrate generative AI and foundation model capabilities without managing underlying infrastructure. Second, Meta is exploring the provision of raw compute capacity—primarily GPU-accelerated workloads—mirroring the infrastructure-as-a-service (IaaS) model offered by neocloud providers such as CoreWeave. This dual-layer approach would allow Meta to compete both in higher-margin AI platform services and in lower-level compute provisioning.
Telecom & Networking Implications:
From a telecom and network infrastructure perspective, this development has several implications. Hyperscale AI workloads are increasingly bandwidth-intensive, requiring high-capacity, low-latency interconnects within and between data centers. Meta’s investments are therefore likely to drive demand for advanced optical networking technologies, including coherent pluggable optics (e.g., 400ZR/800ZR), data center interconnect (DCI) architectures, and AI-optimized fabric designs leveraging Ethernet-based scale-out topologies. In addition, the geographic placement of these data centers—often in power-abundant, rural locations—introduces new requirements for long-haul fiber connectivity and edge aggregation.
The initiative, internally referred to as “Meta Compute,” reflects a broader industry shift toward vertically integrated AI infrastructure stacks, where hyperscalers tightly couple compute, networking, and software frameworks. For telecom operators and infrastructure vendors, this trend underscores the growing convergence between cloud, AI, and network domains, particularly as AI-driven workloads begin to influence traffic patterns, peering strategies, and edge deployment models.
Strategically, Meta’s entry into the AI cloud market raises competitive pressure across multiple fronts. Unlike traditional cloud providers, Meta brings extensive experience in hyperscale distributed systems and open-source AI frameworks (e.g., PyTorch), but lacks a mature enterprise cloud ecosystem. Its success will likely depend on its ability to translate internal infrastructure efficiencies into externally consumable services, while addressing enterprise requirements for reliability, security, and service-level agreements.
Meta’s cloud push is best viewed as a network-and-infrastructure strategy as much as a software business, because monetizing AI capacity depends on how well it can expose compute, move data, and preserve performance at hyperscale. The telecom significance is that Meta is turning internal AI infrastructure into a market-facing platform, which increases the importance of optical transport, data-center interconnect, and low-latency backbone engineering.
From a telecom perspective, the key issue is not simply that Meta may sell AI models or GPU capacity; it is that the company is building a service layer on top of a very large, power- and bandwidth-intensive distributed system. Reuters reported that Meta is considering both hosted model access and raw compute sales, with the former resembling an AI platform service and the latter looking more like neocloud infrastructure.That means the network becomes part of Meta’s product offering. Large AI inference and training environments require high-bisection fabrics inside the data center, plus dense east-west traffic handling, which pushes demand for faster Ethernet switching, advanced optical modules, and carefully engineered rack-to-rack and site-to-site interconnects. Meta’s AI cloud ambitions reinforce a broader shift: hyperscalers are no longer treating networking as a background utility, but as a primary constraint on scale.
Network World’s coverage of Meta Compute notes that Meta has unified data center and network oversight and is planning multi-gigawatt AI buildouts, underscoring how tightly power, fiber, switching, and facility design are now linked.
For network operators and vendors, that translates into stronger demand for long-haul fiber, DCI platforms, low-latency transport, and high-radix switching. It also raises the strategic value of metro and regional interconnect corridors that can support AI clusters, especially when capacity must be spread across multiple sites for power, land, or resiliency reasons.
Meta’s potential move into raw compute sales is especially relevant to telecom because it resembles the economics of infrastructure-heavy cloud and colocation models. In practice, the service quality will depend on how efficiently Meta can provision GPU clusters, maintain deterministic performance, and avoid congestion across the transport layer connecting those clusters. That implies growing importance for:
-
Coherent optical transport and scalable DCI.
-
High-capacity Ethernet fabrics for AI clusters.
-
Open-rack and disaggregated infrastructure designs.
-
Network automation that can track workload placement and traffic hotspots.
These are not just cloud concerns; they are telecom-grade capacity-planning problems. As AI clusters become larger and more distributed, network planning starts to look more like core network engineering than conventional enterprise hosting.

Image Credits: Gabby Jones/Bloomberg / Getty Images
……………………………………………………………………………………………………………………………………………………………………..
Conclusions:
Meta’s entry would not only compete with AWS, Azure, and Google Cloud, but could also pressure specialized neocloud providers more directly. Reuters noted that Meta’s spare capacity could matter more to neo-cloud vendors than to the largest hyperscalers, because those providers rely on access to external GPU supply and managed infrastructure growth. For telecom analysts, that suggests the competitive battleground is shifting from “who has the best model” to “who can deliver the most resilient compute-network-power stack.” The winners will likely be those that can couple AI accelerators with fiber-rich sites, robust interconnect, and energy-secure data center footprints.
Meta’s move reflects the convergence of cloud, AI, and transport networks. The story is less about Meta becoming a generic cloud vendor and more about hyperscale AI infrastructure evolving into a new class of network-dependent utility. Indeed, Meta’s cloud initiative highlights a broader industry reality — in the AI era, compute is valuable, but connectivity, optical scale, and power-aware architecture increasingly determine whether compute can be monetized at all.
……………………………………………………………………………………………………………………………………….
References:
Meta, like SpaceX, looks to turn excess AI compute into cash
https://www.cnbc.com/2026/05/27/mark-zuckerberg-says-meta-starting-cloud-business-on-the-table.html
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
OCP 2025 Meta keynote: Scaling the AI Infrastructure to Data Center Regions
TechCrunch: Meta to build $10 billion Subsea Cable to manage its global data traffic
AI Frenzy Backgrounder; Review of AI Products and Services from Nvidia, Microsoft, Amazon, Google and Meta; Conclusions
Bharti Airtel and Meta extend 2Africa Pearls subsea cable system to India
Is AI the driving force behind the metaverse?