Edge AI
Infineon PSoC MCUs Expand TinyML into a Broader Range of Edge AI Applications
Disclaimer: ChatGPT helped research and write this article, but the author checkpointed the AI repeatedly and had the final say on what to include/exclude in this blog post.
…………………………………………………………………………………………………………………….
Introduction:
Artificial intelligence (AI) running on embedded devices is evolving beyond the relatively narrow range of machine-learning applications traditionally associated with TinyML [1.], rather than Large Language Models (LLMs). Newer microcontrollers (MCUs) are beginning to support a broader class of Edge AI workloads, including speech recognition, natural-language processing, computer vision, optical character recognition (OCR), selected translation applications and increasingly sophisticated voice interfaces. Many selected AI workloads can now be executed locally on embedded MCUs, reducing or eliminating the need for cloud processing for those particular functions.
Note 1. Traditional TinyML (Tiny Machine Learning) focuses on relatively small, task-specific machine-learning models running on resource-constrained embedded devices. The newer development is the ability to supplement those workloads with compact language models and more sophisticated speech and vision inference.
…………………………………………………………………………………………………………………………………………………………………………………
Infineon’s PSoC™ Edge family of microcontrollers illustrates this transition. By combining heterogeneous Arm processors, dedicated neural-network accelerators, substantial memory resources, graphics capabilities and embedded AI software, these MCUs provide a platform for intelligent devices capable of performing more complex AI processing locally.
Infineon states: “The relevant question is not whether an MCU can replicate an 8B LLM, but whether it can deliver useful AI experiences within the power, cost, and latency constraints of edge products. For many real-world edge applications, PSOC™ Edge is not merely capable, it is often a more appropriate solution than a higher-(processing) power MPU-based architecture.”
Let’s examine that assertion and consider Edge AI applications that can be supported by the Infineon PSoC MCUs.
Edge AI Applications supported by Infineon PSoC MCUs:
Infineon’s PSoC Edge MCUs support TinyML, which consists of low-latency, deterministic AI models that process sensor, audio, and vision data locally. The hardware is designed for applications requiring battery-powered execution, sub-1 milliwatt wake states, and zero cloud dependency.
From Infineon: PSoC Edge AI Applications include:
Audio & Voice Processing:
- Speech-to-Intent: Converting spoken commands directly into system actions (e.g., “Turn on the fan”) without needing to transcribe speech into text first.
- Acoustic Event Detection: Identifying specific environmental sounds such as glass breaking, baby crying, gunshots, or alarms.
- Beamforming & Noise Reduction: Using neural networks to filter out background noise in communication devices and smart wearables.
Low-Power Vision (TinyVision):
- Presence & Gesture Detection: Recognizing if a human is in front of a device or interpreting basic hand movements for touchless control.
- Object & Face Counting: Tracking things like people entering a room or basic inventory sorting on a conveyor belt.
- Defect Classification: Performing basic visual quality inspections in automated manufacturing lines.
Smart Sensing & Predictive Maintenance:
- Vibration and Anomaly Detection: Monitoring industrial motors, pumps, or consumer appliances to predict mechanical failure before it happens.
- Sensor Fusion: Combining data from multiple sensors (e.g., temperature, pressure, humidity, and gas sensors) to evaluate environmental conditions or air quality index (AQI) changes in real time.
- Biometric Tracking: Processing health metrics locally in fitness trackers, such as advanced heart-rate variability and sleep stage classification.
The table below illustrates how the PSoC Edge E84 matches these workloads by splitting tasks between its distinct processing domains:
| Workload Type | Active Hardware Component | Typical Power/Performance State |
| Always-On Passive Listening | Cortex-M33 + NNLite microNPU | Ultra-low power, sub-1 mW state waiting for wake words or threshold anomalies. |
| Active Machine Learning Inference | Cortex-M55 + Arm Ethos-U55 NPU | High performance, using 128 MACs/cycle execution to compute vision or audio matrices instantly. |
Source (for the information in this section and the table): Infineon
………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………
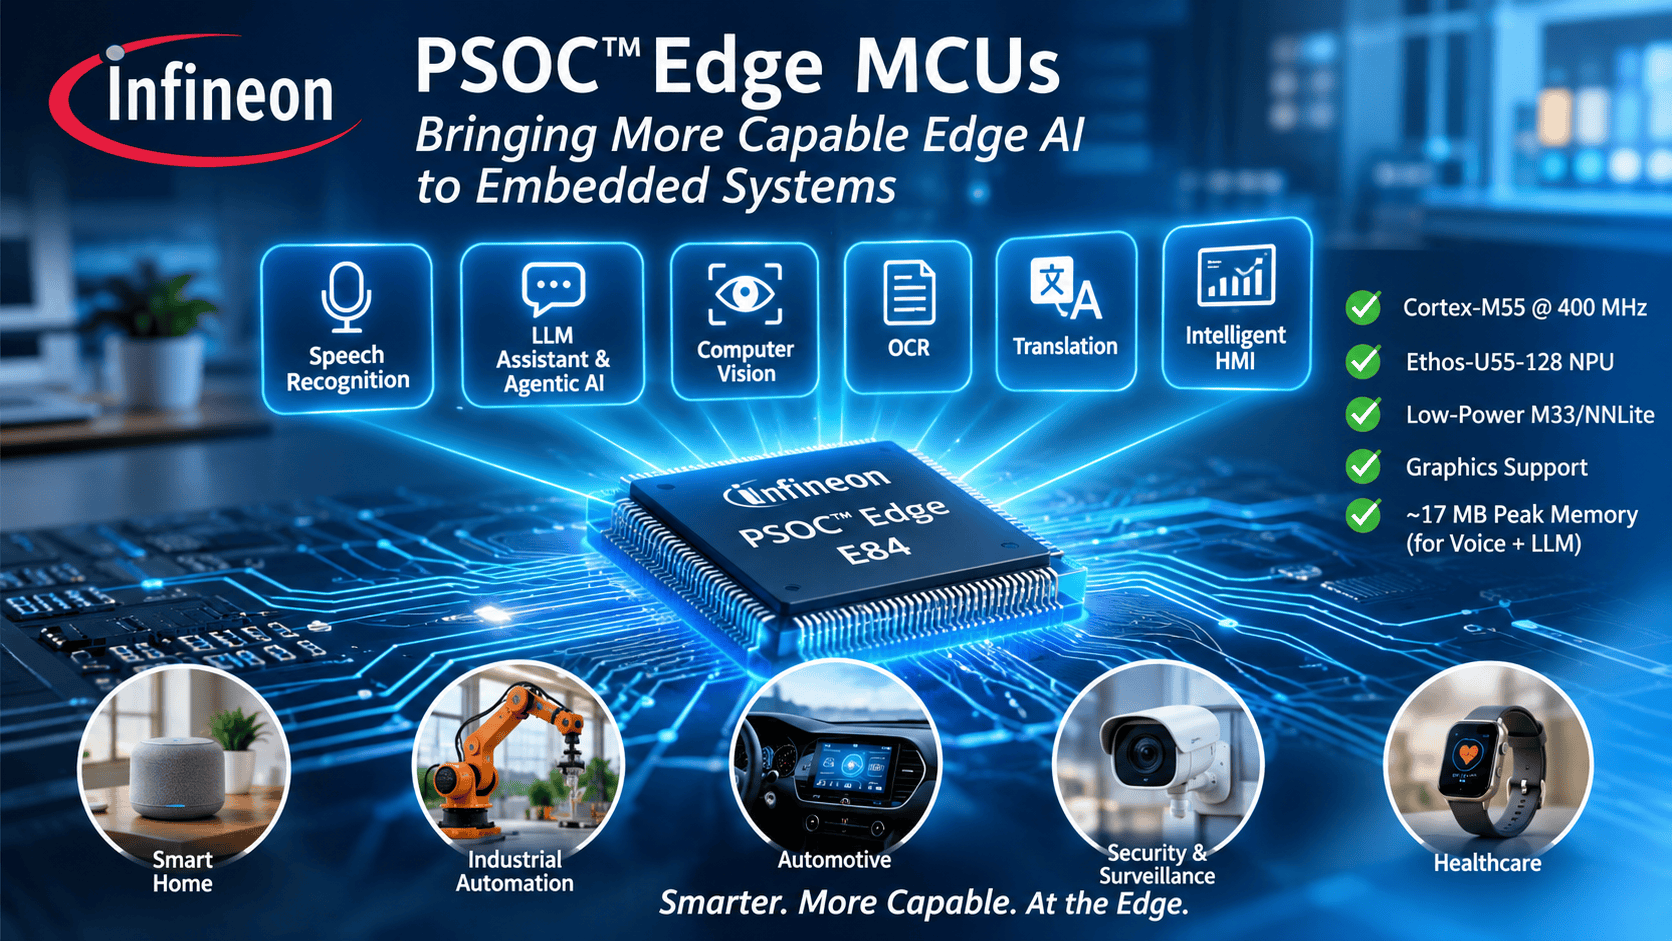
Infineon PSOC Edge MCUs bring more capable AI processing to embedded devices, supporting applications ranging from speech recognition and compact language models to computer vision and intelligent human-machine interfaces. Image generated by ChatGPT.
……………………………………………………………………………………………………………………………………………………………………………….
PSoC Edge: A Heterogeneous Architecture for Embedded AI:
The PSoC Edge family is designed to combine high-performance AI inference with low-power, always-on processing. Its multi-domain architecture enables different processors and neural accelerators to handle workloads according to their performance and power requirements.
The PSOC Edge E84, used in the EWNA demonstration, incorporates:
- Arm Cortex-M55: A 400 MHz processor with Helium DSP extensions for signal processing and machine-learning workloads.
- Arm Ethos-U55-128 NPU: A dedicated neural processing unit for accelerating neural-network inference.
- Arm Cortex-M33: A separate, lower-power processor operating at up to 200 MHz.
- Infineon NNLite: A dedicated neural-network accelerator associated with the Cortex-M33 domain for low-power, always-on AI applications.
The E84 also provides up to 6 MB of system SRAM, 512 KB of resistive RAM (RRAM), external-memory interfaces and a low-power 2.5D graphics processor. Its display controller supports MIPI-DSI/DBI interfaces and resolutions up to 1024 × 768. Multiple digital audio interfaces support multi-microphone applications, including far-field voice interaction. Connectivity includes USB, 10/100 Ethernet, CAN-FD, SPI, UART, I2C, I3C and I2S.
This heterogeneous architecture provides two important processing domains:
- High-performance domain: The Cortex-M55 and Ethos-U55 combination handles more computationally demanding AI workloads, including full voice inference and more complex neural-network applications.
- Low-power domain: The Cortex-M33 and NNLite combination supports continuous, energy-efficient processing, including wake-word detection and other always-on machine-learning functions.
This arrangement is particularly useful for intelligent voice interfaces. The lower-power domain can monitor for an activation phrase without requiring the higher-performance processing resources to remain continuously active. Once activated, more demanding speech-recognition and language-model workloads can use the higher-performance domain.
The result is a flexible MCU architecture that combines conventional embedded processing with multiple levels of AI acceleration.
PSOC Edge family: Different configurations for different AI workloads:
Not all PSOC Edge devices offer identical AI and HMI capabilities. Infineon’s product comparison identifies the following differences:
| MCU | AI acceleration | Voice AI | Vision AI | Graphics |
|---|---|---|---|---|
| E84 | NNLite + Ethos-U55-128 | Full voice inference | Presence, gesture, motion | Yes |
| E83 | NNLite + Ethos-U55-128 | Full voice inference | Presence, gesture, motion | No |
| E82 | NNLite | Wake-word detection | Not listed | Yes |
| E81 | NNLite | Wake-word detection | Not listed | No |
Source: Infineon data sheets
The E84 offers the broadest combination of the capabilities listed above, including full voice inference, vision functions and graphics. This differentiation is important when evaluating the family for embedded AI designs. The appropriate MCU depends on the workload, processing requirements, Human Machine Interface (HMI) complexity, memory resources and power budget.
………………………………………………………………………………………………………………………………………………………………
Infineon Demo At Embedded World North America (EWNA) 2026:
At EWNA 2026 [September 22–24, 2026 in Anaheim CA], Infineon demonstrated an on-device Edge AI application using the PSOC™ Edge E84. The demonstration integrated a 6.5-million-parameter Nexus Ember task-oriented language model, with a 512-token context window, and a 16-million-parameter FastConformer streaming speech-to-text engine, together with graphics support. The application demonstrated local speech recognition and language-model inference without requiring cloud processing for those functions.
Of particular interest, Infineon supplied detailed measurements of the implementation, including model size, memory utilization, language-model generation speed, speech-recognition latency and power consumption. These provide useful engineering data for evaluating the feasibility of executing compact language models and multiple AI workloads on MCU-class hardware.
Its reported measurements—18 generated tokens per second, a 0.36-second language-model time to first token, approximately 17 MB peak memory usage for the 16M voice-control pipeline excluding graphics buffers, and 92.6 mW active SoC power—provide useful evidence of what is achievable with a compact MCU-based AI implementation.
The broader application opportunities include advanced speech recognition, interactive voice interfaces, task-oriented language models, selected translation workloads, computer vision, gesture recognition, OCR and industrial monitoring.
These MCUs will not replace application processors (see Addendum below), embedded Linux systems or cloud-based AI infrastructure for large language models and computationally intensive multimodal applications. Their significance is different: an expanding range of useful AI functions can now be performed locally on increasingly capable microcontroller platforms. For embedded-system designers, that can mean reduced dependence on cloud services, improved data privacy, lower communication requirements, faster interaction and potentially lower system cost and power consumption.
Paradigm Shift: Why Localized AI Execution Matters (Source: Google Gemini):
- Deterministic Latency & Reliability: By removing reliance on cellular, Wi-Fi, or cloud backends, critical applications suffer zero network dropouts (1:14). Latency drops to a deterministic sub-second window, which is vital for industrial machinery interfaces or responsive consumer electronics (0:11).
- Ironclad Data Privacy: Because processing happens entirely on the local silicon chip, sensitive voice data, visual captures, and text streams never leave the device boundary (0:25). This inherently complies with privacy frameworks and eliminates consumer data exposure risks.
- Drastic Power Savings: Transitioning an RF radio into high-throughput transmit mode to stream audio or video payload data to the cloud consumes significant energy. Offloading neural processing locally to a highly optimized NPU cuts total system energy consumption drastically, extending battery life and making “always-on” edge devices sustainable
Conclusions:
The important development is that Edge AI is no longer limited to narrowly defined TinyML inference. Infineon’s PSOC Edge family demonstrates how microcontrollers can increasingly support intelligent, voice-enabled, vision-aware and language-model-driven embedded applications.
The combination of heterogeneous processing, neural-network acceleration, graphics and memory resources enables a broader range of applications, including conversational interfaces, speech recognition, computer vision, OCR, selected translation workloads and industrial monitoring. The E84 demonstration provides concrete evidence that compact language models and streaming speech recognition can operate together locally, with relatively low power consumption.
Although MCU-based Edge AI will not replace more powerful application processors or cloud-based AI for demanding workloads, it can reduce cloud dependence, improve privacy and responsiveness, and lower system costs for many embedded applications. The opportunity is to bring useful AI capabilities directly into devices that traditionally relied on much simpler embedded processing.
……………………………………………………………………………………………………………………………………………………………………..
Addendum:
Google Gemini suggests using dedicated Application Processors (MPUs) or Edge Accelerators for open ended AI at the edge.
To support more demanding, general-purpose generative AI at the edge applications than the Infineon PSoC Edge MCUs, designers will typically need to move beyond MCU architectures to application processors (MPUs) or dedicated AI accelerators with substantially greater memory capacity and bandwidth. Microcontrollers lack the extreme memory bandwidth and capacity (such as High Bandwidth Memory or large external LPDDR buses) required to execute unconstrained, open-ended generative text and vision models.
| Processor Category | Example Hardware | Generative AI Capabilities |
|---|---|---|
| High-End Edge NPU Modules | NVIDIA Jetson Orin Nano / NX | Runs 1B to 3B parameter models locally with fast token generation. Uses shared unified LPDDR5 VRAM to fit small LLMs (e.g., Llama 3.2 3B or Qwen 2.5 3B) entirely on the device. |
| Application Processors | NXP i.MX 95 / STMicroelectronics STM32MP2 | Can handle highly optimized, tiny text models or text-to-speech tasks, but constrained by memory bandwidth. Ideal for structured, deterministic multi-modal smart interfaces rather than open-ended text gen. |
| Dedicated AI Accelerators | Hailo-8 / Raspberry Pi AI Kit | Excellent for offloading complex vision and neural network computations if paired with a capable host CPU. Designed for highly power-efficient mathematical processing (up to 26 TOPS) but lacks on-chip external DRAM for massive LLM weight pools. |
| Product | Official vendor hyperlink |
|---|---|
| NVIDIA Jetson Orin Nano / NX | NVIDIA Jetson Modules |
| NXP i.MX 95 | NXP i.MX 95 Applications Processor |
| STMicroelectronics STM32MP2 | STMicroelectronics STM32MP2 Series |
| Hailo-8 | Hailo AI Products |
| Raspberry Pi AI Kit | Raspberry Pi AI Kit |
Note: The original Raspberry Pi AI Kit uses the Hailo-8L (13 TOPS), not the Hailo-8 (26 TOPS) in the first “Overview of Edge AI Hardware Tiers.. Raspberry Pi’s official documentation confirms this distinction.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………………..
Architectural Deep Dive: Why These Distinctions Matter:
The Memory Wall Constraint: Single-stream token generation for language models is heavily throttled by memory bandwidth rather than raw TOPS compute. This is why High-End NPU Modules with high-throughput unified memory architectures excel at localized LLM tasks over general-purpose application processors.
Coprocessor Offloading: Dedicated accelerators like the Hailo-8 require a powerful host CPU (like an ARM Cortex-A) because the accelerator manages the parallelized weight matrices for neural layers while the host handles system OS routines, memory routing, and basic context token tracking.
……………………………………………………………………………………………………………………………………………………………………………………………………………………..
References:
https://www.infineon.com/products/microcontroller/32-bit-psoc-arm-cortex/32-bit-psoc-edge-arm
Blaize and Winmate Forge Strategic Partnership to Accelerate Edge AI Integration in Ruggedized Systems
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Is the “far edge” a bridge to far to cross for AI inferencing? What about “Distributed AI Grids”?
T-Mobile’s Strategy of Deploying Multi-Vendor AI-RAN on “Kinetic Edge” using AWS Pillars
Will “AI at the Edge” transform telecom or be yet another telco monetization failure?
Custom AI Silicon: OpenAI, Anthropic, Hyperscalers, Huawei and the Battle with Nvidia, AMD and Broadcom
Google’s TPU Business Outpaces Rivals as Hyperscalers Accelerate Custom AI Silicon Strategies
AWS to deploy AI inference chips from Cerebras in its data centers; Anapurna Labs/Amazon in-house AI silicon products
Blaize and Winmate Forge Strategic Partnership to Accelerate Edge AI Integration in Ruggedized Systems
Bridging the Edge Connectivity Gap:
While modern AI architecture has historically favored centralized data centers, mission-critical applications require real-time inference at the edge. For defense personnel in remote locations, maritime operations, or emergency medical responders, reliance on cloud-based processing is often non-viable due to bandwidth constraints and latency requirements.
Eldorado Hills, CA based Blaize Holdings, Inc. and Winmate Inc. (TAIWAN) have announced a Strategic Partnership Agreement aimed at generating approximately $15 million in business during its inaugural year. This collaboration integrates Blaize’s high-performance AI accelerators into Winmate’s industrial-grade ruggedized hardware ecosystem—including UAVs, handhelds, vehicle-mounted computers, and embedded systems—designed for mission-critical reliability in high-stress environments. Both organizations anticipate this agreement to be the foundation of a long-term, multi-year technological synergy.
The partnership addresses the “cloud dependency” bottleneck by leveraging Blaize’s GSP® (Graph Streaming Processor) architecture. These chips are engineered to industrial specifications, enabling sophisticated AI workloads to run locally on the device. When paired with Winmate’s ruggedized chassis—built to withstand extreme thermal fluctuations, high-velocity vibration, and dust ingress—the resulting systems provide high-compute AI capabilities in environments where traditional hardware fails.
- Border security and surveillance: Real-time threat detection and perimeter monitoring
- Mobile command and control: On-site intelligence and situational awareness for field teams
- Drones and unmanned systems: Autonomous navigation and mission execution for UAVs and ground vehicles
- Critical infrastructure: Continuous monitoring and predictive analytics for power, ports, and transportation
- Maritime domain awareness: Vessel tracking and anomaly detection at sea
- Field healthcare: Portable diagnostics and decision support in remote and disaster environments
Deal at a glance:
- First-year revenue: the parties intend to work in good faith to close approximately $15 million in business, expected to scale meaningfully in subsequent years
- Term: Three-year initial term, with automatic renewal
- Next steps: Joint engineering, sales, and marketing execution to bring integrated systems to market, with additional opportunities to be added through follow-on programs
-
- Task-Level Parallelism: The architecture leverages an on-chip hardware scheduler to analyze data dependencies in real-time. It executes deeper layers of a neural network as soon as previous layers produce sufficient intermediate results, minimizing the “idle time” typical of sequential processing.
- Performance-to-Power Ratio: The flagship Blaize 1600 SoC features 16 GSP cores delivering 16 TOPS (Tera Operations Per Second) of AI inference within a conservative 7W power envelope.
- Memory Efficiency: By streaming data through the processor and holding intermediate results in cache, the GSP reduces external DRAM access by up to 50x, which significantly lowers latency and overall system thermal output.
- Unified Development Platform: All hardware is supported by the Blaize Picasso SDK, which allows developers to port models from standard frameworks (like PyTorch or TensorFlow) into a streaming execution format without requiring low-level hardware manual coding.
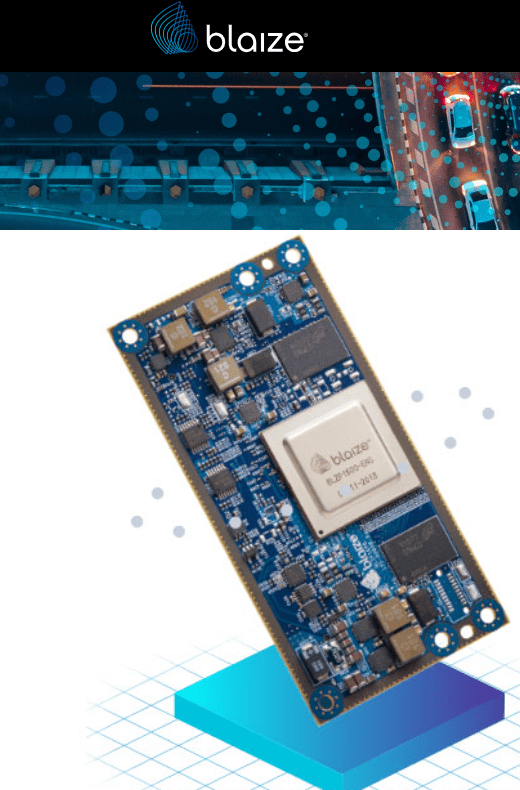
Image Credit: Blaize Holdings
………………………………………………………………………………………………………………………
- Pathfinder P1600 SOM: This System-on-Module is the primary vehicle for integration into Winmate’s handhelds and drones. It operates as a standalone unit with dual ARM Cortex-A53 processors and integrated MIPI CSI camera interfaces for real-time sensor fusion.
- Mission-Ready Durability: These systems are engineered to meet MIL-STD-810H and IP65+ standards, ensuring that Blaize’s AI silicon remains stable under extreme vibration, thermal shock (operating in sub-zero or high-heat field conditions), and high-velocity impacts.
- Sovereign Edge Computing: By processing sensitive data locally on ruggedized handhelds or vehicle-mounted units, the partnership ensures data sovereignty, preventing critical telemetry or biometric data from ever leaving the device during field operations
“Our customers can’t wait, and they often can’t rely on the cloud. They need AI that runs where the work happens. Winmate makes some of the most capable rugged systems in the industry, and our chips are designed to run AI inside exactly those kinds of devices. This partnership turns a years-long vision into a practical, deployable answer for defense and critical infrastructure operators,” said Dinakar Munagala, CEO of Blaize, Inc.
“Our platforms are deployed on naval vessels, in border outposts, on industrial sites, and in disaster zones – environments where most hardware fails. With Blaize, we can now deliver those same systems with on-device AI built in, giving customers real-time intelligence wherever they operate,” said Ken Lu, Chairman and CEO of Winmate Inc.
-
- Latency: The necessity for near-zero response times in autonomous and diagnostic systems.
- Security: The requirement to process sensitive data locally to mitigate the risks associated with transmitting information over public or compromised networks.
About Blaize, Inc.
Blaize delivers a programmable AI platform, purpose-built for AI inference workloads in real-world environments. Its Hybrid AI architecture combines the Blaize GSP (Graph Streaming Processor) with GPU-based infrastructure, enabling AI inference workloads to run across edge, cloud, and data center. Blaize solutions support computer vision, multimodal AI, and sensor-driven applications across smart cities, industrial automation, telecommunications, retail, logistics, and defense. Blaize is headquartered in El Dorado Hills, California, with a global presence across North America, Europe, the Middle East, and Asia. Visit www.blaize.com or follow us on LinkedIn @blaizeinc.
About Winmate Inc.
Winmate Inc. is a publicly traded global leader in rugged computing systems, delivering industrial-grade platforms – including handhelds, tablets, vehicle-mounted units, panel PCs, and embedded modules – for demanding environments across defense, transportation, energy, healthcare, and industrial markets.
………………………………………………………………………………………………………………………………………………………………………………………………………………………..References:
Is the “far edge” a bridge to far to cross for AI inferencing? What about “Distributed AI Grids”?
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Will “AI at the Edge” transform telecom or be yet another telco monetization failure?
Private 5G networks move to include automation, autonomous systems, edge computing & AI operations
Is the “far edge” a bridge to far to cross for AI inferencing? What about “Distributed AI Grids”?
How Far is the Far Edge?
As major telcos size up distributed edge sites for a possible AI inferencing model, they’re trying to determine how far out the right place is in their networks to invest in AI computing capacity. According to Light Reading, the “far edge” is a divisive option for inferencing. According to Omdia, owned by Informa, the Far edge includes: radio access network (RAN) cell sites, aggregation hubs, exchange offices, optical line terminal (OLT) nodes, and Tier 2 metro hubs.
Many telcos are struggling to define how far is the edge from customer premises and how to serve various use cases with compute and intelligence? It seems that 5G SA core with network slicing would be mandatory to support multiple unique use cases, each with different QoS requirements.
According to Omdia’s Telco Edge Computing Survey last year, just 15% of telcos ranked network far edge as the top location for where most AI inferencing will take place, while even less (11%) said the network near edge would be the main spot (which includes central offices, headend sites and large telco data centers). The results showed AI inferencing is expected to be handled mostly on the end devices themselves and at the enterprise edge (e.g., offices, campus or manufacturing sites).
Kerem Arsal, Omdia senior principal analyst for telco enterprise and whoIe sale, predicted in a research note that this year will see telcos split into camps of “believers” and “doubters” of the far edge.

Image Credit: Sphere
…………………………………………………………………………………………………………………………………………………………………………………………………………………..
AT&T VP Yigal Elbaz, speaking at the recent New Street Research and BCG Global Connectivity Leaders Conference, expressed a cautious view on AI compute at the “far edge,” questioning how far the edge truly needs to extend to serve specific use cases effectively. He said the following (Source: Light Reading)
“The proliferation of compute and high-performing compute across the nation, in all metros is just happening, with a software layer on top of this [and] with the tools that developers need. So, I am not sure that there’s much value in extending that compute all the way to the far edge just to save another millisecond or two milliseconds of latency.”
“AT&T’s fiber and wireless networks can provide the “deterministic experience” needed between any new use cases and help them to “intelligently connect to the right model that they use, the context or the infrastructure that they need because that’s going to be heavily distributed across the US.”
“There’s no doubt that that AI is going to be embedded into wireless networks, and we’re going to call it AI-native and combine the physical space with the intelligence of the network. This is all true,” said Elbaz.
………………………………………………………………………………………………………………………………………………………………………………………………………………………..
Distributed AI Grids:
- Ethernet with RDMA (RoCE): The foundation is built on Nvidia Spectrum-X Ethernet, which utilizes RDMA over Converged Ethernet (RoCE). This allows for direct memory access between edge GPUs (e.g., Nvidia RTX PRO 6000 Blackwell Server Edition) and the network core, bypassing CPU overhead to achieve near-line-rate performance.
- Scale-Across Networking: Using Nvidia Spectrum-XGS, the architecture extends standard RoCE to scale across geographically distributed sites. This creates a unified “AI Factory Grid” where remote edge nodes function as a single, programmable compute substrate.
- Silicon One Routing: Cisco’s Silicon One-based routing is utilized for AI-optimized traffic management, providing the high-speed, high-density throughput required for token-intensive inference workloads.
- Zero Trust & Secure Pathways: The interconnect includes a Zero Trust security layer embedded directly into the fabric. It utilizes localized traffic breakout and policy-enforced pathways to ensure that sensitive IoT and video data (such as public safety feeds) remain within the customer’s secure domain at the network edge.
- Orchestration Control Plane: A workload-aware control plane manages these protocols to intelligently route tasks based on real-time KPIs (latency, cost-per-token, and data sovereignty), ensuring that “mission-critical” inference happens at the optimal node.
- Proprietary Software Lock-in: Integrating network functions into a proprietary ecosystem (like Nvidia’s CUDA or AI Aerial) can create a “subscription trap,” where software is inseparable from specific hardware, making it nearly impossible to swap vendors without a total architectural overhaul.
- Data Fragmentation: Deploying AI across a distributed grid often leads to fragmented data sets across legacy and new multi-vendor platforms, which can result in inaccurate AI models and increased operational complexity.
- Standardization Lag: While industry bodies like the GSMA are pushing for Open Telco AI standards, the rapid deployment of proprietary AI systems often outpaces these frameworks, leading to entrenched, incompatible systems that require significantly more resources to reconcile later.
- Integration with Legacy Systems: Modern “agentic AI” and AI-native stacks often struggle to orchestrate processes across siloed legacy infrastructure, creating rigid operational environments that prevent the seamless flow of data needed for automated network troubleshooting.
Bottom Line: While the AI Grid may offer a more viable roadmap than AI-RAN, there is insufficient industry discourse regarding the strategic risks of a global, geographically distributed computing platform—as Nvidia defines it—reliant on a single-vendor hardware stack. Although Nvidia currently maintains undisputed market dominance, historical precedents such as Intel serve as a cautionary tale; long-term dominance is never guaranteed, and even market leaders face potential obsolescence. Furthermore, Nvidia’s practice of providing capital injections to entities that subsequently re-invest those funds back into Nvidia’s own ecosystem raises significant concerns regarding market sustainability and long-term financial health.
References:
https://www.lightreading.com/ai-machine-learning/at-t-cto-casts-doubt-on-ai-compute-at-the-far-edge
https://www.lightreading.com/5g/nvidia-lines-up-ai-grid-as-orange-cto-echoes-the-ai-ran-doubts
Edge AI Computing Explained: Key Concepts and Industry Use Cases
Will “AI at the Edge” transform telecom or be yet another telco monetization failure?
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Private 5G networks move to include automation, autonomous systems, edge computing & AI operations
Nvidia AI-RAN survey results; AI inferencing as a reinvention of edge computing?
Nvidia’s networking solutions give it an edge over competitive AI chip makers
Will “AI at the Edge” transform telecom or be yet another telco monetization failure?
New Telco Opportunity – AI at the Edge:
At MWC 2026 last week, there were a flurry of claims that “AI at the Edge” would transform the telecom industry. One of many examples is an article titled, “The AI edge boom is giving telecom a new strategic role.” In that piece, Jeff Aaron, vice president of product and solutions marketing at Hewlett Packard Enterprise (HPE) spoke with theCUBE’s John Furrier at MWC Barcelona, during an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming studio. They discussed telecom edge AI and why networking is becoming a strategic foundation for data-centric services. Aaron said:
“A big reason for [reignited interest in routing] is AI workloads. They’re moving everywhere now. They have to move to the edge. For them to move to the edge, you’ve got to get them outside of the factory and to all the locations. We’re right in the core of that, and it’s super exciting.”
As AI expands to the edge, data will need to move not only to local compute, but also between many distributed edge sites, making routing paramount. There are four ways AI infrastructure is scaling — inside data centers and across distributed edge locations, according to Aaron.
“There’s scale-out, scale-across, scale-up, and on-ramp. Two are within the data center — scale-out and scale-up — but scale-across and edge on-ramp basically mean you got to figure out how to connect to those areas, and those are just networking,” he added.
Scale-across refers to connecting distributed data centers and edge locations, while edge on-ramp brings remote sites such as factories or branch locations into the network to access AI services. Supporting those distributed environments creates an opportunity for HPE to bring networking and compute together into a more integrated infrastructure stack. At MWC 2026 Barcelona, those trends are clearly coming into focus, according to Aaron.
“Data is moving everywhere right now, and the network is back. The network isn’t just plumbing. The network is how you build a value-added service using an AI workload as a telco infrastructure,” he added.
Telecom carriers are now urgently trying to move from being “dumb data pipes” to becoming “AI performance platforms” by leveraging their geographically distributed infrastructure to host AI closer to the end user. They urgently want to pivot from selling just bandwidth and connectivity to selling outcomes and intelligence with a heavy focus on industrial and enterprise-specific edge deployments. They are considering the following services and business models:
- Infrastructure as a Service (IaaS) & GPUaaS: Offering raw computing power, specifically GPUs, from edge data centers to enterprises that need low-latency processing without building their own facilities.
- Sovereign AI Clouds: Providing AI services that guarantee data remains within national borders, appealing to government and highly regulated sectors like finance and healthcare.
- API Monetization: Exposing real-time network data (e.g., location intelligence, predictive network quality, fraud risk scoring) via APIs that enterprises pay to integrate into their own applications.
- Outcome-Based Pricing: Charging for specific business results, such as a “guaranteed video call quality” or “fraud loss reduction share,” rather than just data usage.
- AI-as-a-Service (AIaaS): Bundling pre-trained models or specialized AI agents (e.g., for customer service or industrial monitoring) with connectivity
Major Carrier AI Edge Deployment Plans:
- AT&T:
- Launched Connected AI for Manufacturing in March 2026, which unifies 5G, IoT, and generative AI to provide real-time fault detection (claiming a 70% reduction in waste).
- Deploying “Edge Zones” in major U.S. cities (Detroit, LA, Dallas) to allow developers to run low-latency, cloud-based software locally.
- Partnering with AWS to link fiber and 5G directly into AWS environments for distributed AI workloads.
- Verizon:
- Unveiled Verizon AI Connect, a suite of products designed to manage resource-intensive AI workloads for hyperscalers like Google Cloud and Meta.
- Trialing V2X (Vehicle-to-Everything) platforms to provide carmakers with standardized APIs for low-latency edge processing in autonomous driving.
- Collaborating with NVIDIA to integrate GPUs into private 5G networks for on-premise AI inferencing in robotics and AR.
- SK Telecom (SKT):
- Announced an “AI Native” strategy at MWC 2026, including a roadmap for AI-RAN (Radio Access Network) that uses GPUs to optimize network performance and host user AI apps simultaneously.
- Building a Manufacturing AI Cloud powered by over 2,000 NVIDIA RTX GPUs to support digital twin simulations and robotics.
- Expanding AI Data Centers (AIDC) across South Korea and Southeast Asia (Vietnam, Malaysia) using energy-optimized LNG-powered facilities.
- Orange & Deutsche Telekom:
- Deploying AI-powered planning tools to cut fiber rollout costs and optimize site power consumption by up to 33% using AI “Deep Sleep” modes.
- Focusing on Sovereign AI strategies to ensure data governance for European enterprise customers.
- Vodafone:
- Utilizing AI/ML applications for daily power reduction at 5G sites and testing autonomous network healing via AI agents
- BT:
- Offers 5G-connected VR for manufacturing design teams (e.g., Hyperbat) to collaborate on 3D models in real-time.
| Product Category | Primary Target | Key Value Proposition |
|---|---|---|
| AI-RAN | Industry 4.0 | Seamless, ultra-low latency for robotics and sensing. |
| Connected AI Platforms | Manufacturing | Real-time predictive maintenance and waste reduction. |
| AI-as-a-Service (AIaaS) | Developers/SMBs | Access to GPU power and pre-trained models via telco edge nodes. |
| Network Slicing APIs | App Developers | Programmatic control over bandwidth for AR/VR and gaming. |
…………………………………………………………………………………………………………………………………………………………………………………………..
A Dissenting View of “AI at the Edge”:
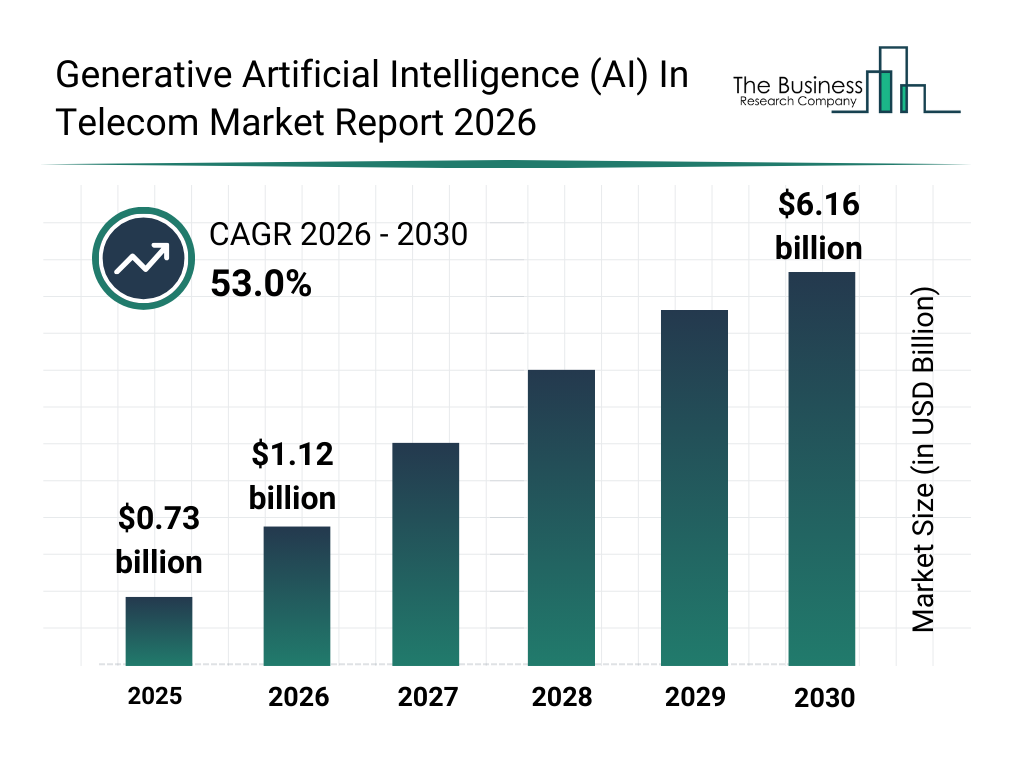
The global market for AI within the global telecommunications sector is valued at $6.69 billion in 2026, growing at a compound annual rate (CAGR) of 41.9% from 2025. The broader edge AI market—including hardware, software, and services—is forecast to reach $29.98 billion in 2026, according to The Business Research Company. We think those estimates are way too high.
The market research firm states:
………………………………………………………………………………………………………
Author’s Opinion:
Unless telcos change their corporate culture along with slowing the footprint growth of cloud service providers/hyperscalers, we think that AI at the Edge will be yet another telco monetization failure. Just like their failure to monetize: 4G LTE apps, the telco cloud, 5G, multi-access edge computing (MEC), OpenRAN, LPWANs and other telecom technologies that never lived up to their promise and potential.
That’s largely because telcos are very weak: developing IT platforms, compute services, killer applications, and rapid execution of new services (e.g. 5G services require a 5G SA core network which telcos were very slow to deploy). Telecom execs themselves cite cultural and speed‑of‑change issues: the industry is not organized like a software company, so it struggles to iterate products at AI/cloud pace. Also, telcos historically struggle with software. Managing distributed GPU clusters is vastly different from managing cell towers.
After spending billions on 5G with very little or no ROI, investors are skeptical of the increased capex required for AI-grade edge servers which must be maintained by telcos. Those servers will be expensive (especially if they contain clusters of Nvidia GPUs) and consume a lot of power, which is a critical issue at the edge of the carrier’s network.
Many network operators frame AI/edge as “network optimization” or “utilizing underused sites,” not as building monetizable AI platforms with APIs, SDKs, and ecosystems. This mirrors 5G, where huge RAN/core builds were not matched by a clear product and platform strategy, leaving value to OTTs and hyperscalers which are extending their control planes and protocol stacks to the network edge (local zones, operator co‑lo, on‑premises stacks).
Telcos risk becoming “dumb pipes” for AI traffic if they can’t provide a superior developer ecosystem. If they only sell space/power/connectivity, the cloud service providers will continue to own the developer and AI value chain. Analysts warn that edge is a “right to participate, not a right to win.” As such, value accrues to whoever owns the AI platform, tools, marketplace, and pricing power, not the entity that provides connectivity, PoP or cell towers.
Data fragmentation and weak “intelligence” layer:
-
AI monetization depends on high‑quality, cross‑domain data, but telco data is fragmented across OSS, BSS, probes, and partner systems; without unification, it is hard to expose compelling network/edge intelligence services.
-
Analysts emphasize that failure here reduces telcos to generic GPU landlords, while higher‑margin offers (real‑time quality, fraud, identity, mobility/context APIs) remain unrealized.
Narrow internal focus on cost savings:
-
Many operators’ early AI focus is inward (Opex reduction in assurance, planning, customer care) rather than building external, revenue‑generating products, echoing how early 5G was justified mainly on cost/efficiency.
-
Commentators warn that if AI/edge remains a “network efficiency” play, the commercial upside will go to cloud/AI natives that turn similar capabilities into products sold to enterprises.
What analysts say telcos must do differently:
-
Build “Sovereign AI factories” and edge AI clouds: GPU‑enabled sites with cloud‑like developer experience (APIs, self‑service portals, metering, SLAs) and clear sovereign/regional guarantees.
-
Combine differentiated connectivity with AI services (latency‑backed SLAs, AI‑on‑RAN, domain‑specific models for verticals) and use modern, flexible commercial models instead of just selling bandwidth or colocation.
Conclusions:
In summary, the main risk for telcos is to successfully transition from owning and maintaining network infrastructure to owning and operating AI platforms and products at software industry speed. AI at the edge is less of a new service or product and more an architectural upgrade. The two ways telcos can benefit are from:
- Internal cost reduction: If telcos use it to lower their own costs (fraud prevention, risk management, predictive maintenance, fault isolation, self-healing networks, etc.), it’s an automatic win but won’t increase the top line.
- Revenue from new AI -Edge services, e.g. Verizon uses edge-based video analytics in warehouses to improve inventory turnover by up to 40%. If they expect to charge a massive premium for “AI-enabled 5G,” they face the same monetization wall that has doomed them for the past 20 years!
References:
https://siliconangle.com/2026/03/04/telecom-edge-ai-makes-networking-strategic-mwc26/
https://www.nvidia.com/en-us/lp/ai/the-blueprint-for-ai-success-ebook/
AT&T and AWS to deliver last mile connectivity for AI workloads; AT&T Geo Modeler™ AI simulation tool
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Private 5G networks move to include automation, autonomous systems, edge computing & AI operations
Dell’Oro: RAN Market Stabilized in 2025 with 1% CAG forecast over next 5 years; Opinion on AI RAN, 5G Advanced, 6G RAN/Core risks
Dell’Oro: Analysis of the Nokia-NVIDIA-partnership on AI RAN
Dell’Oro: AI RAN to account for 1/3 of RAN market by 2029; AI RAN Alliance membership increases but few telcos have joined
Dell’Oro: RAN revenue growth in 1Q2025; AI RAN is a conundrum
Nvidia AI-RAN survey results; AI inferencing as a reinvention of edge computing?
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Qualcomm is a strong believer in Edge AI as an enabler of faster, more secure, and energy-efficient processing directly on devices—rather than the cloud—unlocking real-time intelligence for industries like robotics and smart cities.
In support of that vision, the fabless SoC company announced the official launch of its Qualcomm AI Program for Innovators (QAIPI) 2026 – APAC, a regional startup incubation initiative that supports startups across Japan, Singapore, and South Korea in advancing the development and commercialization of innovative edge AI solutions.
Building on Qualcomm’s commitment to edge AI innovation, the second edition of QAIPI-APAC invites startups to develop intelligent solutions across a broad range of edge-AI applications using Qualcomm Dragonwing™ and Snapdragon® platforms, together with the new Arduino® UNO Q development board, strengthening their pathway toward global commercialization.
Startups gain comprehensive support and resources, including access to Qualcomm Dragonwing™ and Snapdragon® platforms, the Arduino® UNO Q development board, technical guidance and mentorship, a grant of up to US$10,000, and eligibility for up to US$5,000 in patent filing incentives, accelerating AI product development and deployment.
Applications are open now through April 30, 2026 and will be evaluated based on innovation, technical feasibility, potential societal impact, and commercial relevance. The program will be implemented in two phases. The application phase is open to eligible startups incorporated and registered in Japan, Singapore, or South Korea. Shortlisted startups will enter the mentorship phase, receiving one-on-one guidance, online training, technical support, and access to Qualcomm-powered hardware platforms and development kits for product development. They will also receive a shortlist grant of up to US$10,000 and may be eligible for a patent filing incentive of up to US$5,000. At the conclusion of the program, shortlisted startups may be invited to showcase their innovations at a signature Demo Day in late 2026, engaging with industry leaders, investors, and potential collaborators across the APAC innovation ecosystem.
Comment and Analysis:
Qualcomm is a strong believer in Edge AI—the practice of running AI models directly on devices (smartphones, cars, IoT, PCs) rather than in the cloud—because they view it as the next major technological paradigm shift, overcoming limitations inherent in cloud computing. Despite the challenges of power consumption and processing limitations, Qualcomm’s strategy hinges on specialized, heterogenous computing rather than relying solely on RISC-based CPU cores.
Key Issues for Qualcomm’s Edge AI solutions:
- Qualcomm® AI Engine: This combines specialized hardware, including the Hexagon NPU (Neural Processing Unit), Adreno GPU, and CPU. The NPU is specifically designed to handle high-performance, complex AI workloads (like Generative AI) far more efficiently than a generic CPU.
- Custom Oryon CPU: The latest Snapdragon X Elite platform features customized cores that provide high performance while outperforming traditional x86 solutions in power efficiency for everyday tasks.
- Specialization Saves Power: By using specialized AI engines (NPUs) rather than general-purpose CPU/GPU cores, Qualcomm can run inference tasks at a fraction of the power cost.
- Lower Overall Energy: Doing AI at the edge can save total energy by avoiding the need to send data to a power-hungry data center, which requires network infrastructure, and then sending it back.
- Intelligent Efficiency: The Snapdragon 8 Elite, for example, saw a 27% reduction in power consumption while increasing AI performance significantly.
- Instant Responsiveness (Low Latency): For autonomous vehicles or industrial robotics, a few milliseconds of latency to the cloud can be catastrophic. Edge AI provides real-time, instantaneous analysis.
- Privacy and Security: Data never leaves the device. This is crucial for privacy-conscious users (biometrics) and compliance (GDPR), which is a major advantage over cloud-based AI.
- Offline Capability: Edge devices, such as agricultural sensors or smart home devices in remote areas, continue to function without internet connectivity.
- Diversification: With the smartphone market maturing, Qualcomm sees the “Connected Intelligent Edge” as a huge growth opportunity, extending their reach into automotive, IoT, and PCs.
- “Ecosystem of You”: Qualcomm aims to connect billions of devices, making AI personal and context-aware, rather than generic.
- Qualcomm AI Hub: This makes it easier for developers to deploy optimized models on Snapdragon devices.
- Model Optimization: They specialize in making AI models smaller and more efficient (using quantization and specialized AI inference) to run on devices without requiring massive, cloud-sized computing power.
References:
Qualcomm CEO: AI will become pervasive, at the edge, and run on Snapdragon SoC devices
Huawei, Qualcomm, Samsung, and Ericsson Leading Patent Race in $15 Billion 5G Licensing Market
Private 5G networks move to include automation, autonomous systems, edge computing & AI operations
Nvidia’s networking solutions give it an edge over competitive AI chip makers
Nvidia AI-RAN survey results; AI inferencing as a reinvention of edge computing?
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Qualcomm CEO: expect “pre-commercial” 6G devices by 2028
Omdia: How telcos will evolve in the AI era
Dario Talmesio, research director, service provider, strategy and regulation at market research firm Omdia (owned by Informa) sees positive signs for network operators.
“After many years of plumbing, now telecom operators are starting to see some of the benefits of their network and beyond network strategies. Furthermore, the investor community is now appreciating telecom investments, after many years of poor valuation, he said during his analyst keynote presentation at Network X, a conference organized by Light Reading and Informa in Paris, France last week.
“What has changed in the telecoms industry over the past few years is the fact that we are no longer in a market that is in contraction,” he said. Although telcos are generally not seeing double-digit percentage increases in revenue or profit, “it’s a reliable business … a business that is able to provide cash to investors.”
Omdia forecasts that global telecoms revenue will have a CAGR of 2.8% in the 2025-2030 timeframe. In addition, the industry has delivered two consecutive years of record free cash flow, above 17% of sales.
However, Omdia found that telcos have reduced capex, which is trending towards 15% of revenues. Opex fell by -0.2% in 2024 and is broadly flatlining. There was a 2.2% decline in global labor opex following the challenging trend in 2023, when labor opex increased by 4% despite notable layoffs.
“Overall, the positive momentum is continuing, but of course there is more work to be done on the efficiency side,” Talmesio said. He added that it is also still too early to say what impact AI investments will have over the longer term. “All the work that has been done so far is still largely preparatory, with visible results expected to materialize in the near(ish) future,” he added. His Network X keynote presentation addressed the following questions:
- How will telcos evolve their operating structures and shift their business focuses in the next 5 years?
- AI, cloud and more to supercharge efficiencies and operating models?
- How will big tech co-opetition evolve and impact traditional telcos?
Customer care was seen as the area first impacted by AI, building on existing GenAI implementations. In contrast, network operations are expected to ultimately see the most significant impact of agentic AI.
Talmesio said many of the building blocks are in place for telecoms services and future revenue generation, with several markets reaching 60% to 70% fiber coverage, and some even approaching 100%.
Network operators are now moving beyond monetizing pure data access and are able to charge more for different gigabit speeds, home gaming, more intelligent home routers and additional WiFi access points, smart home services such as energy, security and multi-room video, and more.
While noting that connectivity remains the most important revenue driver, when contributions from various telecoms-adjacent services are added up “it becomes a significant number,” Talmesio said.
Mobile networks are another important building block. While acknowledging that 5G has been something of a disappointment in the first five years of the deployment cycle, “this is really changing” as more operators deploy 5G standalone (5G SA core) networks, Omdia observed.
Talmesio said: “At the end of June, there were only 66 telecom operators launching or commercially using 5G SA. But those 66 operators are those operators that carry the majority of the world’s 5G subscribers. And with 5G SA, we have improved latency and more devices among other factors. Monetization is still in its infancy, perhaps, but then you can see some really positive progress in 5G Advanced, where as of June, we had 13 commercial networks available with some good monetization examples, including uplink.”
“Telecom is moving beyond telecoms,” with a number of new AI strategies in place. For example, telcos are increasingly providing AI infrastructure in their data centers, offering GPU as-a-service, AI-related colocation, AI-RAN and edge AI functionality.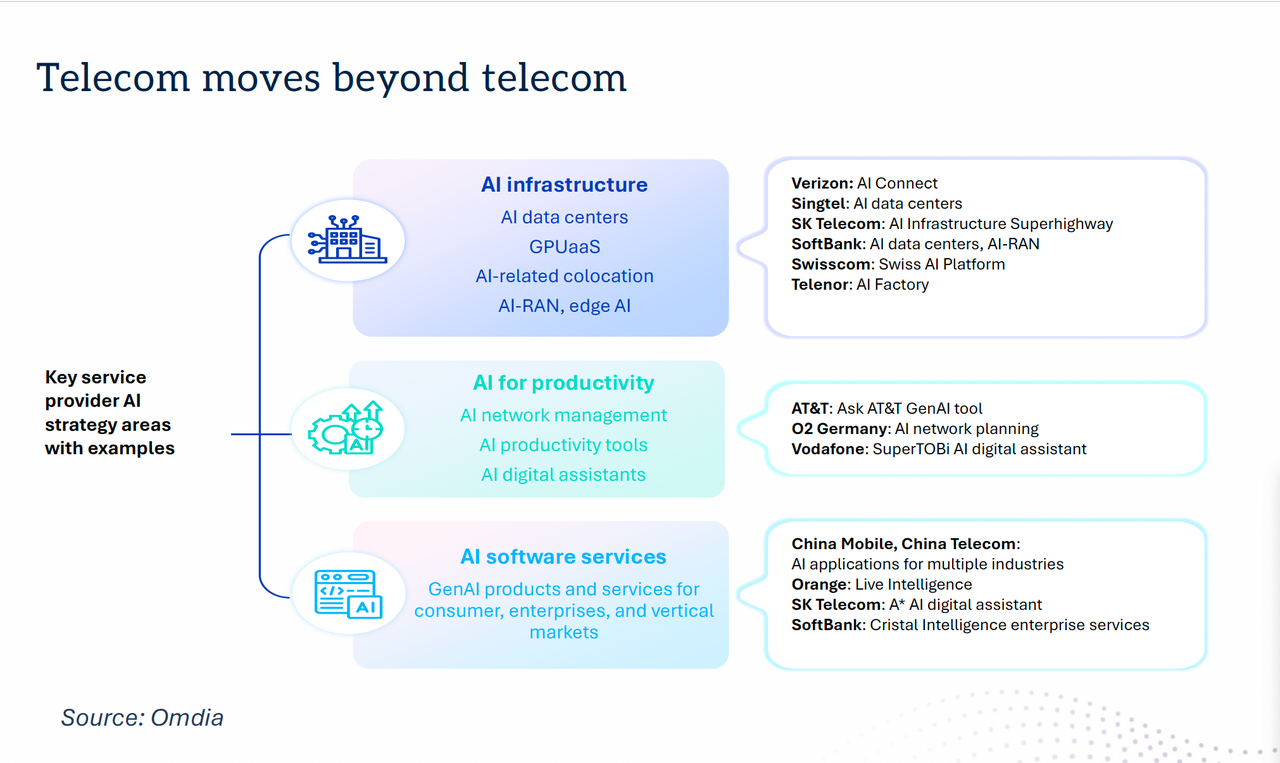

Dario Talmesio, Omdia
……………………………………………………………………………………………………………………………………………………
AI is also being used for network management, with AI productivity tools and AI digital assistants, as well as AI software services including GenAI products and services for consumer, enterprises and vertical markets.
“There is an additional boost for telecom operators to move beyond connectivity, which is the sovereignty agenda,” Talmesio noted. While sovereignty in the past was largely applied to data residency, “in reality, there are more and more aspects of sovereignty that are in many ways facilitating telecom operators in retaining or entering business areas that probably ten years ago were unthinkable for them.” These include cloud and data center infrastructure, sovereign AI, cyberdefense and quantum safety, satellite communication, data protection and critical communications.
“The telecom business is definitely improving,” Talmesio concluded, noting that the market is now also being viewed more favorably by investors. “In many ways, the glass is maybe still half full, but there’s more water being poured into the telecom industry.”
References:
https://networkxevent.com/speakers/dario-talmesio/
https://www.mckinsey.com/industries/technology-media-and-telecommunications/our-insights/pushing-telcos-ai-envelope-on-capital-decisions
Omdia on resurgence of Huawei: #1 RAN vendor in 3 out of 5 regions; RAN market has bottomed
Omdia: Huawei increases global RAN market share due to China hegemony
Dell’Oro & Omdia: Global RAN market declined in 2023 and again in 2024
Omdia: Cable network operators deploy PONs