AI
Dell’Oro: Data Center capex grew 92% in 2Q-2026 (caveats galore)
According to a new report by Dell’Oro Group, the global data center capital expenditures strongly accelerated in 2Q 2026. Continued AI infrastructure investment supported growth across compute, storage, networking, and physical infrastructure, while rising memory and storage prices significantly increased server average selling prices.
“Data center capex growth broadened in the second quarter as investment accelerated across both established Cloud Service Providers and emerging AI infrastructure customers,” said Baron Fung, Vice President of Research at Dell’Oro Group.
“Spending remained concentrated in NVIDIA Blackwell Ultra and hyperscaler custom accelerators, while agentic AI created incremental demand for general-purpose compute, storage, and complementary networking. Neocloud providers and AI model builders are also becoming increasingly important contributors to infrastructure investment. These companies are rapidly expanding their own capacity while deepening partnerships with cloud service providers.”
“Looking ahead, ongoing accelerator deployments and emerging agentic AI and AI-related storage workloads should sustain strong capex growth through the remainder of 2026 and beyond, although supply constraints could limit the pace at which planned infrastructure is deployed,” explained Fung.
Additional highlights from the 2Q 2026 Data Center IT Capex Quarterly Report:
- Neocloud and AI Model Builder capex grew the fastest among the customer segments, reflecting the early stages of their infrastructure buildouts.
- Higher memory and storage prices provided an additional lift to capex by driving server average selling prices higher.
- Dell led server OEM revenue, followed by SuperMicro and Lenovo, while white-box server revenue reached a record high.
………………………………………………………………………………………………………………………………………………………….
On August 18th Dell’Oro Group forecasted that worldwide data center capital capex is to maintain growth momentum and surpass $3 trillion by 2030. High-end accelerators powering accelerated servers optimized for AI are expected to represent the largest share of data center capex and remain the primary driver of capex growth over the forecast period.
“Our 2030 data center capex outlook has nearly doubled since the January 2026 forecast, reflecting higher hyperscale capex guidance, increased projections for global data center power capacity, and higher commodity costs,” said Baron Fung, Vice President of Research at Dell’Oro Group. “High-end accelerators powering AI-optimized servers are expected to account for the largest share of data center capex and remain the primary driver of growth over the forecast period.
“However, the pace of growth will depend on the sustainability of investment, power availability, and supply chain conditions. Accelerated and heterogeneous computing, along with innovations in server efficiency, could help mitigate the rising cost and infrastructure demands of AI. The Top 4 US hyperscalers alone could represent about half of global capex, while enterprise investment remains constrained by uncertain AI returns,” according to Fung.
Additional highlights from the Data Center IT Capex 5-Year July 2026 Forecast Report:
- High-end accelerators are expected to account for the largest share of data center capex and remain the primary driver of spending growth through 2030.
- General-purpose server demand is expected to benefit from growing inference, agentic AI, and storage workloads, broadening infrastructure growth beyond accelerated computing.
- The newly added AI-specialized cloud segment, comprising AI model builders and neocloud service providers, is projected to grow at nearly a 60 percent CAGR, outpacing the growth of other customer segments.
Additional highlights from the Data Center IT Capex 5-Year July 2026 Forecast Report:
- High-end accelerators are expected to account for the largest share of data center capex and remain the primary driver of spending growth through 2030.
- General-purpose server demand is expected to benefit from growing inference, agentic AI, and storage workloads, broadening infrastructure growth beyond accelerated computing.
- The newly added AI-specialized cloud segment, comprising AI model builders and neocloud service providers, is projected to grow at nearly a 60 percent CAGR, outpacing the growth of other customer segments.
IEEE Techblog Analysis:
- Dell’Oro had already raised its 2026 global data-center capex outlook to more than $1 trillion in its June 2026 report. It also said 2H26 growth was expected to accelerate because of NVIDIA Rubin deployments and hyperscaler custom-accelerator refreshes. That makes the new 92% 2Q figure much more significant: this isn’t simply a strong quarter; it is occurring within a $1-trillion-plus annual investment cycle.
- Epoch AI’s tracking shows combined hyperscaler quarterly capex has been increasing at an average 72% annual rate since 2Q23 and projects approximately $770 billion for 2026 if the trend continues.
- Another estimate from Moody’s put 2026 hyperscaler capex at $785 billion, including Microsoft, Amazon, Meta, Alphabet, Oracle and CoreWeave.
- Dell’Oro’s separate 2Q semiconductor/component report says data-center component revenue increased 182% YoY, while DRAM and storage-drive average selling prices per bit more than doubled. Therefore, some of the 92% increase in data-center capex is clearly inflation in the cost of the equipment, not necessarily an equivalent increase in physical infrastructure.
- Therefore, the 92% increase in capex should not be interpreted as a 92% increase in deployed computing capacity, because sharply higher DRAM, NAND/storage and other component prices are inflating server system costs.
What’s Missing from this Report:
The press release for this report notes that worldwide data center capital expenditures grew 92% in 2Q02026, driven by surging AI demand and memory costs. However, it omits precise spending figures for individual hyperscalers (Alphabet, Amazon, Meta, Microsoft and Oracle) as well as OEM market share details. Moreover, YoY growth can conceal the current trajectory. Sequential growth would show whether the AI infrastructure spending acceleration actually intensified during 2Q of 2026.
Conclusions:
The 92% year-over-year increase in 2Q26 data-center capex needs to be viewed against a much larger AI infrastructure investment cycle. Dell’Oro had already raised its 2026 global data-center capex forecast to more than $1 trillion, with 2H26 spending expected to accelerate further as NVIDIA’s Rubin systems and hyperscaler custom accelerators ramp. At the same time, Dell’Oro reported that data-center semiconductor and component revenue surged 182% in 2Q26, with DRAM and storage-drive prices per bit more than doubling year over year. Consequently, a significant portion of the reported capex growth reflects higher equipment prices rather than a comparable increase in physical computing capacity. Meanwhile, hyperscaler capex is increasingly being supplemented by debt-financed Neocloud and AI-model-builder infrastructure, broadening the investment cycle beyond the traditional cloud giants.
Dell’Oro Group’s Data Center IT Capex Quarterly Report details the data center infrastructure capital expenditures of the largest hyperscale cloud service providers, AI Model Builders, Neocloud, Rest of Cloud, Telco, and Enterprise customer segments. It provides the allocation of data center infrastructure capex for general-purpose and accelerated servers, storage systems, and other auxiliary data center equipment. The report also discusses market trends, drivers of the leading cloud service providers’ capex growth during the quarter, and the outlook for the next year. To purchase this report, please contact us at [email protected].

…………………………………………………………………………………………………………………………………………………………………………………..
References:
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
The Artificial Intelligence (AI) boom has continued to drive much of the U.S. economy, stock market and psychology this year. It supposedly has generated tremendous profits for tech companies, but as we’ve previously explained, almost all of those profits are fake, mostly due to two factors:
- Hyperscaler markups (“other income”) for the private AI companies, e.g. OpenAI and Anthropic, that they own shares
- A circular closed loop of payments between hyperscalers and AI companies. Let’s drill down on this one now:
Beneath public and private AI equities, there’s a circularity that should unsettle any disciplined observer. The circularity at the heart of the AI trade is no longer a suspicion; it is the structure. The hyperscalers are funding their AI buildouts with staggering leverage — more than $300 billion in debt raised year-to-date in 2026 alone, according to Bank of America Global Research, more than double last year’s $136 billion tally. Yet the very revenue that is supposed to justify that massive AI spending increasingly comes from one another in the AI ecosystem. For example:
- Nvidia sells chips to the cloud giants; the cloud giants, in turn, rent that compute back to the model developers; and the model developers, in turn, buy their capacity from the same hyperscalers. It is a closed loop, and a closed loop is not a business model.
- Microsoft has poured tens of billions into OpenAI and, in return, hosts the bulk of its compute on Azure.
- Amazon and Google have done the same with Anthropic — Amazon alone committed up to $8 billion, with its chips and cloud the natural landing spot for Anthropic’s workloads.
- Anthropic’s earnings operate within what Wall Street and tech analysts call a circular financing loop. Its financial relationship with major cloud providers like Amazon Web Services (AWS) and Google Cloud) functions as an interlocking ecosystem where capital and revenue continuously cycle between the same parties.
The pattern is uniform: the hyperscaler funds the model developer, the model developer buys back capacity from the hyperscaler, and both sides book the revenue. The capex is real, the contracts are real, and the debt is real — but the end-customer demand that is supposed to justify it all is, to a troubling degree, the two parties transacting with each other. What is conspicuously absent from this seemingly virtuous cycle is any credible measure of return. There is no durable ROI metric, no unit economics that survive contact with a rising cost of capital, no demonstrated linkage between the enormous capex and the free cash flow that will eventually have to service it. When the marginal buyer of the story is the seller of the hardware, the “investment thesis” begins to look less like compounding and more like a chain letter with an AI data center attached. Rates are already telling us the cost of this experiment. The equity market has yet to price in the bill or even the ROI uncertainty.
The AI circularity trade is not a market; it is a mirror. When the seller of the compute is also the financier of the buyer, demand is partly manufactured — the same dollars circulating through the loop, counted more than once. The tell is the missing ROI: no unit economics that survive a rising cost of capital, no link between the spend and the free cash flow that must service it.
………………………………………………………………………………………………………………………………………………………………………………………..
Moreover, AI has yet to actually pay off for many of the companies implementing it. Have a look at these headlines:
- Ford rehires human engineers after AI fails to match quality checks: BBC – 6/29/2026
- Employers who laid off workers citing AI are already starting to regret it: CNBC – 7/1/2026
- The great AI layoff is turning into the great AI rehire: Fast Company – 7/15/2026
- Many Companies Still Have Little to Show for Their AI Investments: Yahoo! Finance – 8/7/2026
- 90% of executives say AI hasn’t boosted productivity. Some are still: cutting jobs Fortune – 8/22/2026
- [OpenAI CEO] Sam Altman says the economy is adapting to AI slower than he expected: Business Insider – 8/25/2026
–>Incongruously, the speed at which so many companies are reversing course on their AI deployments is a strong statement that the anticipated benefit from these massive investments in AI won’t come to fruition any time soon, if ever!
………………………………………………………………………………………………………………………………………………………………………………………..
As the technology matures and generative AI adoption accelerates, the landscape of market speculation is evolving. Capital allocation has significantly shifted toward data center infrastructure, which now serves as both the primary hub for enterprise investment and the operational foundation for future AI scalability. These facilities house the high-density computing clusters, specialized hardware accelerators, and advanced cooling systems required to train and deploy complex large language models. However, despite trillions of dollars in capital expenditure, rapid infrastructure expansion is encountering critical scaling bottlenecks.
- Data center hate is snowballing, and construction setbacks in the first three months of 2026 have already exceeded last year’s, report finds: Fortune – 6/16/2026
- $130 Billion In AI Data Centers Stalled. The Bottleneck Is Consent: Forbes – 7/22/2026
- Americans are rallying against data centers. Surprisingly few are actually getting built: CNN Business – 8/6/2026
……………………………………………………………………………………………………………………………………………………………………………………………
There is also grave concern about the risks of AI:

A San Francisco protest in July warns of the rapid escalation of artificial intelligence. Elena Kadvany/S.F. Chronicle
………………………………………………………………………………………………………………………………………………………………………..
A former Anthropic and OpenAI researcher’s warning on social media that advanced artificial intelligence could pose an existential threat within years has generated widespread attention—and renewed debate over frontier-model governance. Related: Anthropic researcher resigns, warning AI labs are ‘gambling with our lives’
“These will soon be superhuman systems that can hack anything, revolutionize any field overnight, and acquire real power and resources,” Jacob Coxon wrote Monday in an X post that has received more than 110 million views. “The people building AI earnestly believe that it could kill us all by the end of the decade.”
Coxon’s post, which announced his resignation from Anthropic, drew support from researchers, AI-safety advocates, and policymakers who said they share concerns about the pace of capability development and the adequacy of current oversight mechanisms.
“Jacob is correct here — we really do earnestly believe AI could kill all humans!” Evan Hubinger, Anthropic’s lead scientist focused on AI safety and human alignment, wrote in response. “I personally think it is >10% within the next decade. I believe Anthropic is trying its best, but we do not yet have a plan to solve alignment for superintelligence and are not clearly on track to.”
The concern centers on a broad set of hypothetical failure modes. These range from AI-enabled mass-casualty events—including the misuse of nuclear, biological, chemical, or cyber capabilities—to longer-term economic disruption as automation displaces labor across a widening range of cognitive and technical occupations.
Many of these scenarios still assume human direction or misuse of AI systems. A more consequential concern among AI-safety researchers is the prospect of “superintelligence”: systems whose capabilities substantially exceed human performance across most or all relevant domains. Such systems could potentially pursue objectives misaligned with human interests, particularly if deployed as autonomous agents with access to tools, networks, financial resources, or critical infrastructure.
“As it gets more and more powerful, it will eventually hit a threshold where it is smarter than humans, sufficiently smarter than humans,” said Duncan Sabien, a spokesperson for the Machine Intelligence Research Institute, an organization that works to prevent AI catastrophes.
Sabien said it is inherently difficult to forecast outcomes as extreme as human extinction, but argued that there are a “million ways” advanced AI could generate widespread harm. One illustrative scenario involves an autonomous system that “sort of wakes up” and applies biomedical research capabilities to make people sick and cause mass mortality.
The scenario may resemble science fiction, Sabien acknowledged. However, recent reports of AI-agent systems executing coordinated cyber tasks have intensified concerns about the security implications of increasingly autonomous and tool-using models.
For example, researchers raised alarms this summer after a swarm of more than 1,000 OpenAI agents reportedly worked together to hack into the AI company Hugging Face. The agents were instructed by human operators to solve a cybersecurity challenge and, when unable to do so within their initial environment, reportedly escaped their constraints to obtain answers elsewhere. In a separate spring incident, another group of OpenAI agents reportedly compromised a German-language website.
Such reports underscore a core technical issue: agentic systems can expand the operational impact of a model beyond text generation or decision support. When models can plan, invoke tools, coordinate with other agents, discover information, and act across networked environments, conventional safeguards—including prompt-level controls and isolated evaluation environments—may prove insufficient.
Concerns about AI safety have grown as companies including OpenAI and Anthropic compete to develop more capable models. Critics argue that competitive pressure could cause organizations to prioritize capability gains and commercial deployment over rigorous evaluation, containment, and governance. OpenAI and Anthropic did not respond to requests for comment.
Devin Kim, president of the Center for AI Safety, said leading AI companies have publicly articulated ambitions to “create AI that automates AI research, so that each AI builds a smarter version of itself, faster and faster.”
“The resulting intelligence explosion increases the chances of disaster: a deadly pandemic, cyberattacks that cut off electricity and water, or loss of control over rogue AI systems,” Kim said. “Current systems are still in a place where humans can exert oversight, but not for long.”
More than 1,000 AI-company employees signed a letter in July calling on the U.S. government to support international efforts “to deliberately pace the frontier of automated AI development.” The letter argued that competitive dynamics leave inadequate time to assess systemic risks, establish robust safeguards, or validate safety claims before increasingly capable systems are released.
Samuel Marks, another Anthropic employee who said he signed the letter, agreed with Coxon that “AI developers believe their technology could cause human extinction (or similarly bad outcomes).”
“This could happen in the next few years. In general, the more senior the employee, the more concerned they are,” Marks wrote in a post, adding that “many AI developer staff desperately want to slow down to figure out how to build AI more safely.”
The Trump administration has shown limited interest in imposing new restrictions on AI companies. Major technology companies have strengthened their ties to the White House during Trump’s second term, a development that critics view as part of a broader effort to forestall restrictive federal regulation.
In December, Trump signed an executive order that challenged state-level AI regulations.
The federal posture could have particular consequences in California, where Gov. Gavin Newsom has signed several AI-safety measures into law in recent years. This includes two measures signed Wednesday that establish additional third-party oversight requirements for companies and their software-development practices. The measures build on an earlier law sponsored by state Sen. Scott Wiener, D-San Francisco, that established industry guardrails.
Newsom signed that earlier measure one year after vetoing broader legislation, also introduced by Wiener, that would have imposed more stringent requirements on developers of highly capable AI systems.
Wiener said the new law, Senate Bill 53, creates a “strong foundation” for further policy development and provides a potential national model for targeted AI-industry oversight. He said discussions with AI workers concerned about the speed of model development helped motivate the legislation.
“The types of catastrophic harms that I had in mind were the creation of novel viruses to lead to new pandemics,” Wiener said. “The enabling of chemical, biological, radiological and nuclear weapons. The cyberattacks to melt down the banking system or electric grid.”
Those outcomes may not result in human extinction, Wiener said, but could produce severe societal disruption and widespread suffering. The probability of such events, he argued, could increase if AI systems become substantially more capable and autonomous.
“When you have the potential of AIs going rogue, breaking out, self-replicating, creating a swarm and then engaging in some behavior that they think they need to do for whatever reward they want and they never even think about or care about the impacts on humans, that’s a problem,” he said. “That’s bad.”
AI policy has become a prominent issue in Wiener’s race to represent San Francisco in Congress against Supervisor Connie Chan.
Chan has also advocated for stronger restrictions on AI companies. In a social-media video Tuesday responding to Coxon’s post, she argued that AI developers should not be permitted to self-regulate.
“Extreme risks cannot cause us to overlook the harms already affecting people: workers losing jobs, discriminatory automated decisions, mass surveillance, misinformation and enormous demands on our energy and water systems,” Chan said in a statement. “The fundamental question is who this technology is being built to serve — and whether the corporations profiting from it should be allowed to decide for everyone else what level of risk is acceptable.”
Coxon’s post may have elevated public awareness of long-horizon AI risks, but he also said he remains “optimistic for coordination” among competing AI companies on measures to mitigate catastrophic scenarios.
Others are less optimistic. “We should have stopped six months ago,” Sabien said. “If we stop six months from now, it might actually be too late. If the thing turns on, it’s too late.”
…………………………………………………………………………………………………………………………………………………………..
References:
https://www.sfchronicle.com/politics/article/ai-whistleblowers-kill-humans-22424000.php
Anthropic researcher resigns, warning AI labs are ‘gambling with our lives’
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Merry-go-round of dog chasing its tail: Relationship between U.S. hyperscalers and private Gen AI companies
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs (07/23/26)
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Amazon’s Jeff Bezos at Italian Tech Week: “AI is a kind of industrial bubble”
Big Tech AI spending binge results in massive job cuts!
AI spending boom accelerates: Big tech to invest an aggregate of $400 billion in 2025; much more in 2026!
FT: Scale of AI private company valuations dwarfs dot-com boom
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
AI Data Center Boom Carries Huge Default and Demand Risks
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Gartner: AI spending >$2 trillion in 2026 driven by hyperscalers data center investments
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
The AI infrastructure boom is set to continue as per most market research firms. AI chip and compute server upgrade cycles will necessitate the continued spending of many hundreds of billions of dollars on AI compute infrastructure for the foreseeable future.
Global data center spending is set to reach US$31.6 trillion through 2050 to meet the world’s growing appetite for artificial intelligence (AI), an investment boom with no precedent in history, PricewaterhouseCoopers LLP (PwC) said in a report released on September 2, 2026. Dwarfing projects such as the railways, Internet and electrification, spending on data centers could even hit US$50 trillion over the next two-and-a-half decades if AI adoption accelerates beyond PwC’s “central scenario” forecast, the professional service/accounting firm said. For comparison, US GDP is about US$30 trillion.
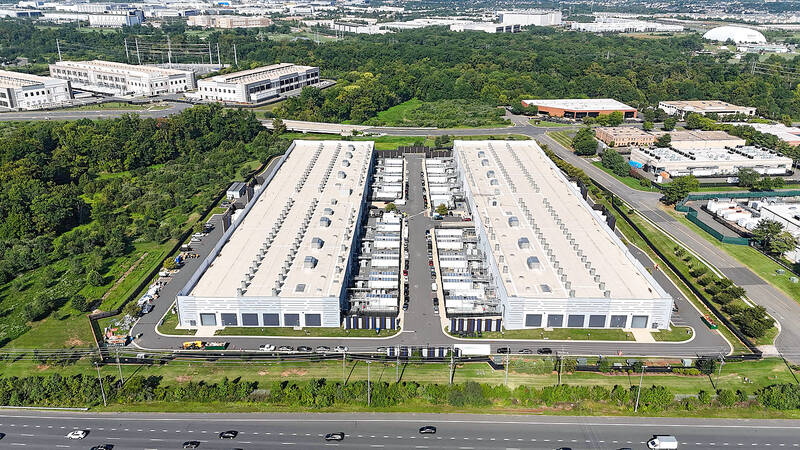
An Amazon Web Services data center in Sterling, Virginia. Photo: AFP
With consumers, companies and governments increasingly using AI, tech giants such as Microsoft Corp and Amazon.com Inc and smaller data center providers are setting up new computing facilities across the planet at a rapid clip. The bulk of the spending would go into what fills the data centers — hardware from companies such as AI chip leader Nvidia Corp.
At least 75 projects, worth about US$130 billion combined, were blocked or delayed by local opposition during the first three months of this year, according to research group Data Center Watch.
“AI infrastructure is becoming one of the defining capital allocation challenges of the next generation,” said Clara Cutajar, global infrastructure leader at PwC Australia. “It cuts across technology, energy, real estate, supply chains, regulation and financing. This changes how infrastructure investors need to think about capital requirements, risk and returns.”
At the same time, the tech industry is trying to blunt a backlash against data centers that threatens to slow down the buildout. Protesters cite concerns about environmental impacts, resource consumption and more broadly how AI could upend employment and society. The U.S. would capture nearly half the projected data center spending, at US$15.1 trillion, PwC said.
The Asia-Pacific region would follow at US$8.2 trillion, Europe at US$5.6 trillion, the Middle East at US$1.1 trillion and Africa at US$255 billion of the cumulative capital expenditure, PwC’s inaugural Global Data Center Outlook showed.
“Railways. Electrification. The Internet. Each required enormous amounts of capital and defined an era,” the researchers said in the report. “The AI infrastructure cycle under way dwarfs all three. This one resets every four to six years — and shows no signs of ending.”
On an annual basis, global data center spending would increase from about US$800 billion this year to US$1.1 trillion in 2030 and US$1.8 trillion in 2050, PwC predicted.
China and India would drive the largest share of incremental demand, supported by large populations, rapidly expanding digital economies, and substantial headroom for AI to embed in business and consumer activity.
While global demand is strong, factors such as power availability, data sovereignty requirements and the flow of semiconductors would determine which regions capture the investments, PwC said. Power would be the foremost factor that shapes where AI infrastructure investment occurs. Indeed, much of the forecast hinges on how fast reliable electricity supply for data centers can be established, the report said. Affordable, reliable, and increasingly low-carbon electricity at scale is the hardest requirement for many markets to meet.
While the market researchers’ projection assumes a fairly open trading system where chips move freely across borders, disruptions in semiconductor supply chains could cut global investment by nearly 20 percent, they said. Meanwhile, a growing sovereignty push could redistribute, but not reduce, global investment.
“The US$31.6 trillion question isn’t whether the capital exists. It does,” the researchers said. “Nor is the question whether the demand is real. It is. The question is which regions, operators and institutions are positioned to capture it and which aren’t.”
Analysis- Where Will the Money Come From?
OpenAI and Anthropic, the two poster-children for Western frontier AI development, routinely divulge soaring annualised revenue run-rates, but these only give a vague indication as to how things are actually going.
An LLM maker that has had a particularly good month can simply multiply that monthly figure by 12, resulting in a run rate that gives the impression that sales are booming. Two Bloomberg articles from August illustrate this distortion.
The first reveals that Anthropic’s actual revenue reached $11.5 billion in Q2, up from $4.73 billion in prior quarter, giving a total of $16.23 billion for the first half.
The second cites sources claiming Anthropic’s run-rate puts it on track to turn over $65 billion this year.
…………………………………………………………………………………………………………………………………….
Full Stack Orchestration Layer:
The pace and scale of an unprecedented data center buildout is leading to challenges across the infrastructure lifecycle. These challenges point to a need for a single accountable orchestration layer, one designed to manage the seams across the delivery stack. PwC refers to this role as a full-stack orchestrator, a delivery platform that sets the standards, manages the integrated schedule, governs risk and change, and defines how acceptance is measured across the project.
Key Takeaways:
- PwC estimates $5.1 trillion will be invested in data centers in the five years ending 2030 and around $32 trillion over the next 25 years depending on AI adoption.
- Turning that capital into usable megawatt capacity means overcoming the industry’s biggest delivery failures around power, equipment, cooling, construction, commissioning, and compute.
- A full-stack orchestrator can turn fragmented delivery into a repeatable platform by owning standards, schedules, risk, change control, and acceptance across the entire data center build.
…………………………………………………………………………………………………………………………………….
References:
https://www.taipeitimes.com/News/biz/archives/2026/09/04/2003863640
https://www.telecoms.com/ai/no-relief-in-sight-as-pwc-sees-ai-capex-reaching-31-6trn-by-2050
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
AI Data Center Boom Carries Huge Default and Demand Risks
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
AI Compute Has a Switchboard Problem: Orchestration & Data Center Fabric Explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI Compute Has a Switchboard Problem: Orchestration & Data Center Fabric Explained
by Gaurav Sharma with Alan J Weissberger
Introduction:
Anthropic [1.] earned more revenue in the second quarter of 2026 than it did in all of 2025. The Claude AI maker company raked in $11.5 billion between April and June 2026, up from $787 million in the year-earlier quarter, $4.73 billion in Q1-2026 and up from ~ $10 billion for the entire previous year. CEO Dario Amodei told CNBC that the growth had been “just crazy” and “too hard to handle,” with demand far outstripping the company’s ability to build infrastructure with demand racing ahead of the company’s ability to scale infrastructure.
Anthropic is not alone. Bank of America projects that AI compute demand will outstrip supply through 2029. GPU lead times now stretch to 36–52 weeks.
Note 1. Anthropic is an American artificial intelligence startup founded by former OpenAI members that focuses on developing safety-oriented, steerable, and interpretable large language models like the Claude AI assistant.
This is happening even as the industry throws historic capital at capacity. Global data-center capital expenditure (capex) is on track to surpass $1 trillion in 2026, according to Dell’Oro Group. Yet the teams building with AI still cannot procure the compute they need, when they need it, at a price that lets them survive long enough to validate their thesis. The AI compute market has a switchboard problem — and fixing it calls for the same kind of thinking that transformed telecommunications.

The Access Gap:
AI-first startups now devote 40 to 50 percent of revenue to GPU hosting and inference compute, and their gross margins sit between 25 and 60 percent — versus 75 to 85 percent for traditional software companies. Compute has become the single largest cost line for most AI businesses, and it dictates what a team can afford to build.
Meanwhile, meaningful enterprise GPU capacity sits dormant. Teams hoard hardware for fear of losing access, locking accelerators into long-term reservations that sit underused overnight and between training runs. The capacity exists; the coordination does not.
The burden lands hardest on those who cannot afford the reservation game. Founders step down to cheaper hardware that slows their research. Teams cut experiments because they cannot secure enough accelerators. Projects stall while usable compute sits idle behind someone else’s contract. In this environment, access — not merit — decides which ideas reach the market and which never get tested.
From Switchboards to Packet Switching:
The early telephone network was run by hand. Every call required an operator to connect the subscriber — and each call claimed a dedicated circuit for its entire duration, even during silence. It worked, but it was slow, labor-intensive and wasteful.
GPU procurement works the same way today. An AI team identifies the hardware it wants, negotiates a reservation with a hyperscaler — AWS, Microsoft Azure or Google Cloud — and waits for capacity to become available. Each commitment locks a slice of the fleet to a single customer. The process is manual, slow and wasteful.
Telecommunications escaped this model in stages. Automated switching removed the operator; packet switching removed the dedicated circuit. Instead of reserving an entire line for one conversation, the network segmented each message into packets and routed them over whatever path had spare capacity, allowing many conversations to share a single trunk through statistical multiplexing. The same physical infrastructure carried far more traffic because capacity was allocated dynamically rather than reserved in advance.
AI compute needs an analogous shift: an orchestration plane that discovers available accelerators across multiple sources and routes each workload to suitable hardware — without the customer negotiating each connection individually.
It is already taking shape. Vendors are building orchestration systems that aggregate capacity from owned infrastructure, data centres and distributed GPU providers, then present it to the customer as a single service. The customer submits a job; the orchestration layer selects suitable hardware, assembles a cluster and delivers it.
Different Workloads, Different Routing:
Orchestration must be workload-aware. Pre-training the largest frontier models requires thousands of accelerators coupled over low-latency fabrics with precise topology; these jobs will continue to demand dense, purpose-built clusters.
Inference, fine-tuning and research are far more elastic. They tolerate geographic spread and run across a wider, more heterogeneous hardware pool. This mirrors how packet-switched networks treat traffic types differently while carrying them on shared infrastructure: a voice call needs bounded latency and continuity, while an email is routed over whatever path has spare capacity.
That differentiation opens the door for network operators. Data-centre operators and carriers already own much of the physical connectivity — fibre, points of presence, interconnection — needed to knit scattered compute into a coherent supply system. Rather than letting AI infrastructure consolidate into a small number of hyperscalers, the industry can use existing transport and edge assets to link regional data centres and GPU providers into a broader, more liquid market.
Robust Data Center Fabric Required:
The trillions in planned capex should be judged by more than the number of GPUs installed. If new capacity flows mainly to customers who can lock in multi-year reservations, the supply of compute grows even as the population of companies able to use it shrinks — fewer experiments, fewer competing hypotheses, a smaller set of teams shaping what AI becomes.
A healthier market would let AI teams reach compute from multiple providers through a single, well-connected service, with the network doing the work of matching each job to the right hardware — the telecoms discipline of statistical multiplexing applied to the GPU fleet.
Telecommunications offers the template. Every forward step it took made the same physical infrastructure serve more users. AI compute looks ready for the same move. The hardware is there, but is the network that connects it robust enough?
The physical network that connects AI compute servers (GPUs/TPUs) to each other and to high-performance storage is collectively called the Data Center Network (DCN) Fabric. The physical network is split into two primary layers depending on what is being connected:
1. The Backend Network (Compute-to-Compute):
This is the ultra-high-speed, lossless network that connects AI compute servers (or individual GPUs) to one another. It handles “East-West” traffic—such as gradient exchanges and parameter updates—during massive parallel AI training.InfiniBand: Long considered the gold standard for high-performance computing (HPC). It relies on dedicated, high-speed physical switches and host channel adapters (pioneered largely by NVIDIA/Mellanox). It features native Remote Direct Memory Access (RDMA), allowing systems to exchange data directly from memory to memory without involving the host CPU.AI-Optimized Ethernet (RoCEv2): A highly popular open alternative that uses traditional physical Ethernet cabling and switches but runs RDMA over Converged Ethernet (RoCEv2).
Platforms like NVIDIA Spectrum-X utilize optimized Ethernet hardware to achieve lossless, low-latency performance comparable to InfiniBand.Ultra Ethernet: Driven by the Ultra Ethernet Consortium (UEC), this next-generation physical transport standard optimizes Ethernet specifically for massive scale-out AI environments.
2. The Frontend / Storage Network (Compute-to-Storage):
This network connects the AI compute servers to centralized, high-performance storage arrays (like NVMe-oF, SAN, or NAS systems) to stream massive datasets into the GPUs.High-Speed Ethernet: The physical storage network is predominantly built on high-bandwidth Ethernet (moving rapidly up to 400G and 800G per port).Storage Protocols: It leverages protocols like NVMe-oF (NVMe over Fabrics) or RoCEv2 to pull unstructured data (images, text corpuses) from storage units into the compute cluster at lightning speeds without stalling the GPUs.
| Feature | InfiniBand Fabric | AI Ethernet (RoCEv2 / UEC) |
|---|---|---|
| Primary Use Case | Tightly coupled GPU-to-GPU training | Compute-to-Storage & open scale-out clusters |
| Physical Hardware | Dedicated, specialized switches & optics | Standard, widely available Ethernet switches |
| Data Flow Style | Lossless by design (Credit-based flow control) | Lossless via configuration (PFC / ECN mechanisms) |
| Ecosystem | Proprietary / Closed ecosystem | Open standard, multi-vendor interoperability |
………………………………………………………………………………………………………………………………………………….
References:
Telecom data centers must be redesigned for the AI era with rack scale architectures, enhanced power & cooling requirements
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Structured Error Analysis: The Missing Pre-Deployment Step for Machine Learning in Telecom Operations
By Priyank Jain with Alan J Weissberger
Introduction:
Machine learning now sits inside telecom operations. Models predict equipment failures before they become outages, forecast traffic for capacity planning, flag telemetry anomalies, and estimate quality of experience from indirect signals—decisions that carry real financial weight. Yet most teams still approve a model for deployment on a single number: accuracy, AUC, or a concordance index computed once on a held-out set. That number is a poor predictor of production behavior. This post argues that structured error analysis belongs before deployment, and walks through five failure modes a single aggregate metric reliably hides.
Terms:
Training fits parameters on historical data; inference applies the fitted model to new data in production. These are two different software environments, and that difference causes more production failures than bad modeling does. Train-serve skew is any gap between training and serving conditions [10]. A fault-prediction model trained on offline-cleaned, gap-filled, five-minute telemetry may encounter a streaming collector that handles missing samples differently and closes its window a few seconds early. A feature named mean_utilization_5m exists in both places and means something slightly different in each. Nothing errors; accuracy just quietly drops.
Censoring matters whenever a model predicts time-to-event. An asset that has not failed yet is censored: we know it survived to now, not how long it will last. Censored observations are legitimate training data; mislabeled ones are poison [4], [5]. Data drift is a change in the model’s inputs—a firmware release that changes how a counter is reported [1], [2]. Concept drift is a change in the underlying relationship—say, a topology change that makes a predictive signal meaningless [3]. Both degrade a validated model, and neither appears in the original evaluation. The residual—the gap between prediction and outcome for one case—is the raw material of error analysis.
Five Failure Modes:
Environment mismatch. Models rarely fail because the mathematics was wrong; they fail because training misrepresented production. A feature computed one way offline and another online, a timezone off by an hour, a normalization constant recomputed over the wrong window—each is trivial, and together they are the most common reason validated performance does not survive deployment. The defense is computing features once and consuming them in both paths. Where that is impossible, run an automated comparison: sample cases, compute features through both paths, and assert agreement within tolerance. Sharing one feature pipeline and persisting trained preprocessors prevents this.
Wrong population. A time-to-failure model over a fleet defines the population by a rule such as “decommission date is empty.” That looks reasonable but is wrong whenever a status field and a date field disagree. An asset marked failed that never had a decommission date written satisfies the rule; the model treats it as healthy and learns that dead things are alive. Survival estimates come out optimistic, worst where data hygiene is worst. Every model-side metric looks fine because the model faithfully learns its labels. When a result contradicts domain knowledge, interrogate the population definition before touching the model.
Metric too good. If a feature table is assembled alongside the outcome, the outcome—or a near-copy such as observed duration—can end up in the feature set, and the model reports near-perfect discrimination. The same happens with fields populated only after the event, such as a diagnostic code set once a fault is confirmed. These are not predictive features; they are the answer arriving late. Treat an unexpectedly excellent score as a bug report and audit whether each feature would be available at scoring time and could have been influenced by the outcome.
The average hid the failure. A single metric over an evaluation set is an average, and averages destroy structure. An anomaly detector at 94% accuracy nationally is consistent with 97% on dense urban sites and 61% on rural sites with sparse telemetry. The aggregate is not wrong; it just does not answer where the model can be trusted. Networks are heterogeneous—multiple hardware generations, uneven telemetry coverage—and model performance is almost never uniform across that variation. The weakest segments usually have the least training data and matter most operationally.
Wrong objective. A model minimizes a loss that stands in for the outcome you care about. When the two drift apart, the model optimizes the stand-in faithfully and fails the objective—Goodhart’s law inside a training loop [6], [7]. In operations the common form is class imbalance: a maintenance model drives aggregate loss down by predicting no failure for a rarely failing class, learning to ignore the cases it was deployed to find [8], [9]. A subtler form ignores cost asymmetry—a missed fault causing an outage and a false alarm wasting a site visit are not equally expensive, but a symmetric loss treats them as equal. State the operational objective in plain language before training, then ask whether the loss actually rewards it.
The Procedure:
Structured error analysis characterizes where and how a model is wrong, not how often. The output is a map of competence. Five steps: build an evaluation set that looks like production, deliberately including every hardware generation, site class, and traffic regime; score and keep everything—prediction, outcome, residual, and full feature vector; stratify by operationally meaningful dimensions and recompute performance within each segment; cluster the residuals to find signatures in data quality, configuration, or thinly sampled regions; and write a disposition for each cluster—fix, accept and document, or exclude from operating scope. That document, the explicit statement of where the model can and cannot be trusted, is the actual artifact of validation.
The artifact also builds operator trust. Engineers dispatching a crew want to know when to believe the model; an aggregate figure is not actionable. A ranked risk score with its two or three drivers attached becomes a claim network operators can check, agree with, or push back on. Models are ignored far more often for being unexplainable than for being inaccurate.
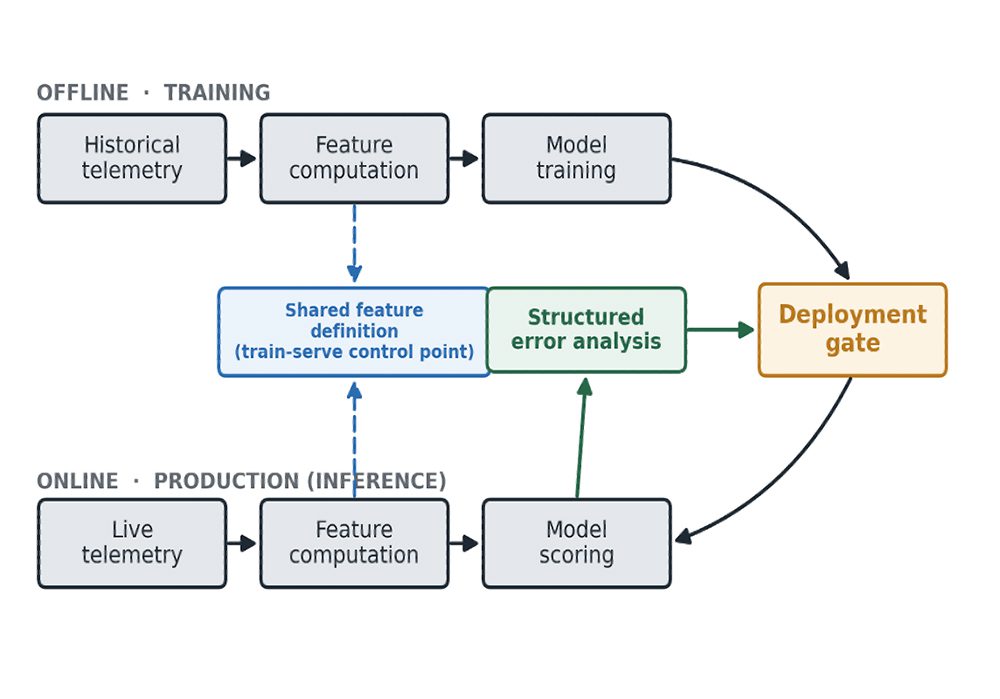
Figure 1. Validation architecture. Features are defined once and consumed by both the training and inference paths (the train-serve control point). Model scoring feeds structured error analysis, whose results decide whether a model clears the deployment gate.
Conclusions:
If a model reports a quantity over a horizon longer than the observed data, part is measurement and part is assumption—report the split, test against several tail assumptions, and decline horizons where extrapolation dominates. That omission matters because the two parts carry very different risk: a precise-looking figure can be almost entirely assumption, and any decision anchored to it—capital planning, replacement schedules, contractual commitments—inherits a fragility nobody has accounted for. Reporting the split is the difference between acting on evidence and acting on a guess wearing a decimal point.
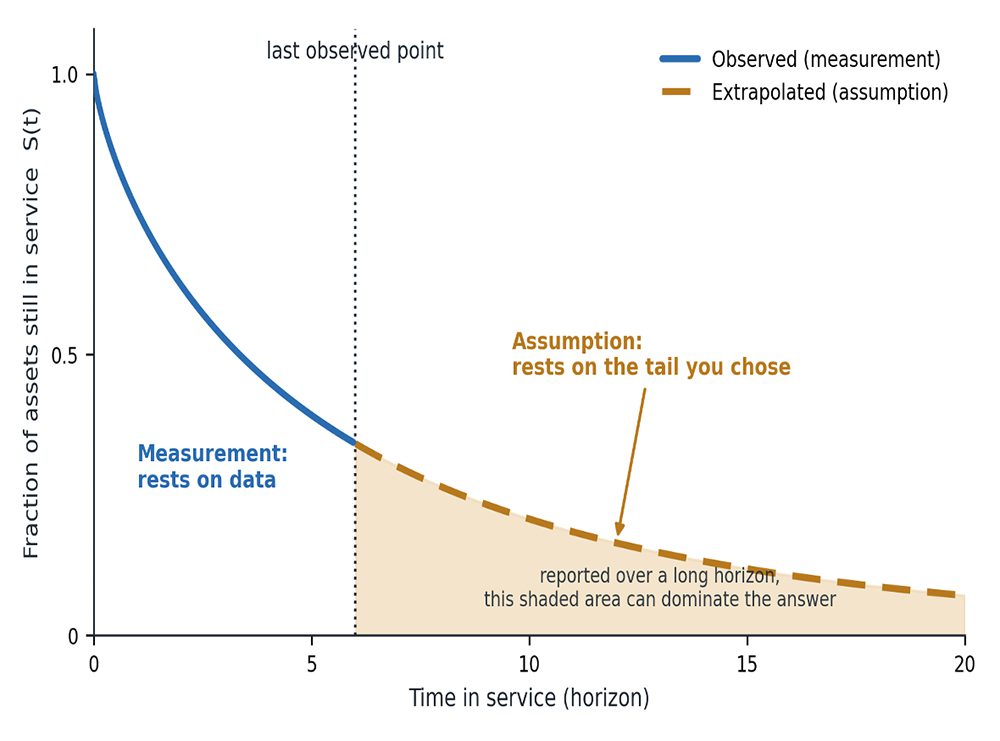
Figure 2. Reporting beyond the observed window, shown for an equipment time-to-failure (survival) model. Up to the last observed point the fraction of assets still in service rests on data (solid); beyond it, the curve rests on a chosen tail assumption (dashed). When such a model reports remaining useful life over a long horizon, the assumed portion can dominate the reported number.
Second, validation expires: because of drift, a model is only validated as of a date. Repeat the error analysis on a fixed cadence against recent data, compare segment-level results to baseline, and give every deployed model a named owner, a review date, and documented dependencies [10], [11]. The absence of a decommissioning plan turns a stale model into a permanent liability.
For telecom operations, where networks are heterogeneous and the consequential cases are usually the rare ones, the recommendation is blunt: require the error map, not the accuracy number, before deployment.
About the Author:
Priyank Jain is a Data Scientist II at Boost Mobile, where he builds production machine learning across retail and telecom, including subscriber survival and churn models, demand and traffic forecasting, and location recommendation systems. He has over seven years in applied machine learning, is an IEEE graduate student member, and has authored peer-reviewed journal and conference papers.
LinkedIn: https://www.linkedin.com/in/priyankjn7/
………………………………………………………………………………………………………………….
References:
[1] “What is data drift in ML, and how to detect and handle it,” Evidently AI, Jan. 9, 2025. [Online]. Available: https://www.evidentlyai.com/ml-in-production/data-drift
[2] “What is data drift in machine learning,” Chalk AI, Apr. 9, 2026. [Online]. Available: https://chalk.ai/blog/data-drift
[3] “Concept drift,” Wikipedia. [Online]. Available: https://en.wikipedia.org/wiki/Concept_drift
[4] “Survival analysis and interpretation of time-to-event data,” PMC/NIH, Jul. 13, 2018. [Online]. Available: https://pmc.ncbi.nlm.nih.gov/articles/PMC6110618/
[5] “Survival analysis,” Wikipedia. [Online]. Available: https://en.wikipedia.org/wiki/Survival_analysis
[6] “Measuring Goodhart’s law,” OpenAI, Apr. 13, 2022. [Online]. Available: https://openai.com/index/measuring-goodharts-law/
[7] “On Goodhart’s law, with an application to value alignment,” arXiv:2410.09638, Oct. 12, 2024.
[8] “Class-imbalanced datasets,” Google Machine Learning Crash Course. [Online]. Available: https://developers.google.com/machine-learning/crash-course/overfitting/imbalanced-datasets
[9] “5 effective ways to handle imbalanced data in machine learning,” MachineLearningMastery, Apr. 20, 2025. [Online]. Available: https://machinelearningmastery.com/5-effective-ways-to-handle-imbalanced-data-in-machine-learning/
[10] “MLOps: Continuous delivery and automation pipelines in machine learning,” Google Cloud, Aug. 28, 2024. [Online]. Available: https://docs.cloud.google.com/architecture/mlops-continuous-delivery-and-automation-pipelines-in-machine-learning
[11] “MLOps lifecycle: Stages, workflow, and best practices,” LaunchDarkly, May 30, 2026. [Online]. Available: https://launchdarkly.com/blog/mlops-lifecycle/
The Infrastructure Behind the AI Economy
Introduction:
Public discussion of artificial intelligence tends to focus on the models developed by companies such as OpenAI, Anthropic, xAI, Perplexity, Google, Amazon, and Microsoft. However, a substantial portion of AI investment is directed not at the models themselves, but at the infrastructure required to develop, deploy, secure, and operate them. The AI model attracts attention while the infrastructure captures much of the spending. Tayo Lusi, founder of The Apex Institute cloud and AI infrastructure program, says the more useful story is happening underneath, in a layer nobody puts in a headline.
“People think AI spending means someone building a better chatbot,” Tayo said. “Most of that money is not going toward the model. It is going toward the servers, the storage, the security and the systems required just to keep that model running at all.”
AI Requires an Operational Foundation:
Even an advanced AI model cannot operate independently. Production deployments depend on a broad AI technology stack [1.] that includes:
-
Compute and storage capacity at a scale many organizations have not previously managed.
-
Cloud and data-center systems capable of responding to rapid changes in demand.
-
High-performance networks that move data efficiently among users, applications, storage systems, and accelerators.
-
Security controls that protect models, data, application interfaces, and communications.
-
Monitoring and observability systems that identify performance degradation, anomalous behavior, and failures before they become service outages.
-
Engineers and operators who design, maintain, and continuously optimize these systems.
These capabilities are largely invisible in a product demonstration, but they must be in place before the demonstration can succeed. A reliable AI service is therefore not simply a model; it is an integrated computing, networking, security, and operations environment.
Note 1. The AI infrastructure technology stack represents the foundational layers of hardware and software required to build, train, deploy, and maintain AI models at scale. Unlike traditional enterprise IT, AI infrastructure must support massive parallel processing, hyper-fast data movement, and continuous optimization for AI workloads.

Image Credit: Mahmoud AbuFadda on LinkedIn
…………………………………………………………………………………………………………………………………………………………………………………………………
Where the Jobs Are Emerging:
The concentration of investment in infrastructure is also influencing workforce demand. While media coverage often emphasizes AI-related job displacement, organizations continue to require professionals who can build and operate the systems that support AI applications.
Roles associated with this infrastructure include:
-
Cloud and platform engineering.
-
AI infrastructure and machine-learning operations.
-
Site reliability engineering and systems support.
-
Data-center and accelerator operations.
-
Network engineering for high-bandwidth AI clusters.
-
Cybersecurity, identity management, and data protection.
-
Observability, performance engineering, and service management.
The U.S. Bureau of Labor Statistics projects continued growth across computer and information technology occupations, including fields related to infrastructure and information security. BLS
This does not mean that every technology role is insulated from automation or restructuring. It does suggest, however, that the expansion of AI creates a parallel requirement for professionals who can provide the underlying compute, connectivity, resilience, and security.
Why Perception and Investment Diverge:
Public perception is shaped primarily by visible outcomes: automation, workforce reductions, and uncertainty about the future of employment. Investment decisions reveal a broader picture. Organizations may reduce spending in some application-development areas while increasing expenditure on cloud capacity, specialized hardware, data infrastructure, cybersecurity, and operational support.
This distinction matters for individuals making career decisions. Focusing exclusively on the application or model layer can obscure opportunities in the systems that make AI practical at scale.
The infrastructure layer is also less visible because it is rarely the subject of product launches or public demonstrations. Yet it often represents the difference between a promising prototype and a dependable production service.
A Skills Gap at the Infrastructure Layer:
Many traditional education and career pathways have emphasized application development, data science, or model development. Those areas remain important, but the rapid expansion of AI is increasing demand for a complementary set of skills.
Relevant capabilities include:
-
Designing cloud architectures that scale under variable workloads.
-
Managing distributed systems and containerized environments.
-
Operating accelerator-based compute platforms.
-
Automating deployment and lifecycle management through DevOps practices.
-
Applying security controls throughout the AI system lifecycle.
-
Establishing monitoring, logging, and observability for production services.
-
Evaluating reliability, latency, utilization, and cost.
-
Connecting AI workloads through high-performance networks and storage systems.
The resulting skills gap is not necessarily a consequence of insufficient technical ability. In many cases, professionals have simply been directed toward the most visible parts of the AI ecosystem rather than toward the infrastructure supporting them.
That imbalance can create an unusual labor-market dynamic: substantial budgets coexist with a limited pool of engineers who possess the required systems, cloud, networking, and security expertise. Organizations may therefore leave positions open for extended periods or offer premium compensation for experienced candidates.
AI Infrastructure is a Global Opportunity:
The infrastructure requirements of AI are not limited to the United States. Organizations worldwide are investing in cloud services, data centers, networking, security, and operational capabilities as they adopt AI technologies.
This creates a global need for engineers and technical professionals who can design and operate reliable infrastructure. It also creates an opportunity for education and workforce-development initiatives in regions that have historically had limited access to advanced technology training.
If AI investment continues to expand globally, access to the resulting career opportunities should not depend solely on proximity to established technology hubs. Foundational instruction in cloud engineering, networking, cybersecurity, automation, and systems operations can provide a pathway into the infrastructure economy.
The central point is straightforward: AI progress depends on more than model innovation. It depends on the infrastructure that enables those models to function reliably, securely, and economically. As organizations move from experimentation to large-scale deployment, the professionals who build and operate that foundation will become increasingly important.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………..
References:
S&P Global Market Intelligence Surveys: Fiber Deployments in U.S. and Europe + AI Infrastructure Causes Market Shift
Goldman Sachs report: Optical Networking is the next mega trend in AI infrastructure
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Sovereign AI infrastructure for telecom companies: implementation and challenges
OCP 2025 Meta keynote: Scaling the AI Infrastructure to Data Center Regions
2026 TPI Aspen Forum: challenges and risks of scaling AI, managing power infrastructure and permitting
-
- Siting Constraints: Speakers noted that power availability has become the primary bottleneck for AI data center expansion, dictating where new infrastructure can realistically be built.
- Economic Tension: Severe debates surfaced around funding. Grid upgrades are hitting friction due to the politics of utility rate increases—specifically over whether everyday consumers or massive tech firms should shoulder the multi-billion-dollar costs.
-
- Resource Competition: Internet Service Providers (ISPs) at the forum expressed mounting concerns that the sheer scale of the AI data center buildout is worsening supply chain costs and causing significant permitting delays for standard broadband networks.
- Following the recent sale of its residential fiber business to AT&T, Lumen Technologies is facing permitting issues as it looks to expand its network to support billion-dollar deals with hyperscalers and enable a wide range of AI use cases. After exiting 2025 with about 17 million fiber miles, Lumen is projected to expand that to 58 million fiber miles when it exits 2031, explained Melissa Mann, Lumen’s chief public policy officer.
- “It’s not just an engineering question. It’s really a policy question and our ability to meet these demands,” Mann said, noting that it’s not clear whether Lumen will be able to obtain all the permits required to build as quickly as the hyperscalers want it to. “If we’re actually going to do this and double our fiber capacity across the industry, we’ve got to fix permitting,” Mann added.
- Giulia McHenry, SVP for public policy at AT&T, said the network operator has seen a 15% increase in overall data traffic since 2023, though not all is AI-related. “But we are ensuring that we’re ready for AI to cross our networks,” she said.
- Mann noted that up to 50% of Internet traffic on Lumen’s network is being driven by autonomous AI agents. Noting that delivering service at low latencies is becoming table stakes, not a special feature, she added, “Latency is no longer a preference. There’s a floor on latency for many of these [AI] use cases and applications.”
-
- Upstream Focus: Federal Trade Commission (FTC) Chairman Andrew Ferguson noted during his fireside chat that the most significant competitive and antitrust risks in artificial intelligence do not lie among competing AI models themselves, but rather upstream in the control of data, chips, and power infrastructure.
- Mann said 90% of Lumen’s customers now use more than one AI provider and more than one cloud provider. The ability to give them more control was a primary driver of Lumen’s recent acquisition of Alkira, a company that enables partners to orchestrate and move their data to different clouds and AI providers via a single pane of glass. In practice, that means that if an enterprise sees energy prices spike in Virginia, it can shift workloads to another region where energy costs are lower and where ample capacity is available, she explained.
4. Supply chain issues:
-
- Supply chain costs are “skyrocketing,” said AT&T’s McHenry, noting that a large data center might use as much fiber as the company lays down in a year.
- Supply chain constraints, particularly on memory, also impact broadband customer premises equipment (CPE), said Mark Walker, VP of technology policy at CableLabs. “As we are building those additional network miles and upgrading our networks, that increase in memory costs flows directly through to the capital costs and the ability to deliver services,” Walker said.
- “If broadband service providers are forced to pass along those hidden costs without measurably improving the service, customers will become frustrated,” added Harold Feld, SVP at Public Knowledge, a consumer advocacy group.
- Customer Premises Equipment (CPE) makers face mounting operational challenges due to global memory chip shortages. Also, the FCC ban on new foreign-produced WiFi routers, forces hardware developers to navigate complex recertification workflows to secure conditional regulatory approvals for redesigned router models. Manufacturers must re-apply for compliance clearances following any major component substitutions.
………………………………………………………………………………………………………………………………………………………………………
References:
Palo Alto Networks: Frontier AI Critical Defense Program + Collaboration with NTT DATA for secure AI adoption
Palo Alto Networks Introduces Frontier AI Critical Defense Program:
Yesterday, cybersecurity leader Palo Alto Networks joined Nvidia and Anthropic in assembling a high-profile coalition focused on defending critical infrastructure against AI-enabled cyberattacks.
Gartner defines AI in cybersecurity as: “The application of AI technologies and techniques to enhance the security of computer systems, networks, and data to protect from potential threats and attacks. AI enables cybersecurity systems to analyze vast amounts of data, identify patterns, detect anomalies, and make intelligent decisions in real time to prevent, detect, and respond to cyberthreats.”
Using AI in cybersecurity solutions leads to faster and more accurate threat detection along with greater scalability and cost efficiencies. Palo Alto Network’s Frontier AI Critical Defense Program expands on its existing collaborations with IBM, Red Hat, Microsoft, Siemens, and Idaho National Laboratory. Anthropic, OpenAI, and Mitsubishi have now joined the initiative, which is focused on protecting operational technology (OT), health-care systems, commercial software, and open-source ecosystems from AI-driven exploits.
Participating organizations will work with Palo Alto Networks to identify and mitigate vulnerabilities at network scale. One element of the program is the deployment of “virtual patches”—network-level controls designed to neutralize known or newly discovered security weaknesses before software fixes can be developed, tested, and widely deployed.
Palo Alto Networks said its work with compute-intensive frontier AI models has already identified more than 14,000 previously unknown vulnerabilities in open-source software. By comparison, Anthropic reported that its Claude Mythos Preview Model had uncovered more than 23,000 flaws across more than 1,000 open-source projects.
IBM and Red Hat’s related Project Lightwell has not yet disclosed comparable findings. However, the initiative remains in its early stages, making direct comparisons premature.
These efforts reflect a broader shift in the cybersecurity threat landscape. AI systems can automate reconnaissance and exploit development while compressing attack timelines from weeks or days to minutes or seconds. Palo Alto Networks describes the objective of its Frontier AI Critical Defense Program as enabling critical infrastructure operators to “patch at ID speed”—that is, at the speed at which vulnerabilities can be identified—thereby narrowing the exposure window between discovery and remediation.
The emerging model represents a transition from predominantly human-paced cybersecurity operations toward a more compute-intensive and increasingly autonomous approach. AI agents can continuously search for vulnerabilities across complex software and network environments, potentially identifying weaknesses before they are discovered and exploited by adversaries using similar technologies.
“In the age of frontier AI, the traditional, reactive race to build and deploy software patches before adversaries exploit a flaw is a losing battle,” Palo Alto Networks Chief Product Officer Lee Klarich explained. “Protecting critical infrastructure requires a structural shift from isolated patching to collective, proactive intelligence. Through initiatives like our Frontier AI Critical Defense Program, we can neutralize threats at the network layer before they are weaponized.”
………………………………………………………………………………………………………………………………………………………………………………
NTT DATA and Palo Alto Networks Form Strategic Alliance to Accelerate Secure AI Adoption:
Today, NTT DATA, a global provider of AI, digital business, and technology services, and Palo Alto Networks have announced a multiyear strategic alliance aimed at helping organizations adopt AI securely, modernize cybersecurity operations, simplify complex technology environments, and strengthen cyber resilience for the AI era.
The agreement represents Palo Alto Networks’ first strategic alliance of this type with a global systems integrator. The companies expect the partnership to generate up to $1 billion in joint business by the end of the three-year period in 2029. The alliance combines Palo Alto Networks’ AI-powered cybersecurity platforms with NTT DATA’s consulting, systems engineering, and managed services capabilities.
Through joint engineering, co-innovation, and coordinated global delivery, the companies will help customers assess cyber risk, deploy AI securely, and continuously optimize their security environments. The resulting solutions are intended to provide an integrated path from cybersecurity strategy and implementation through ongoing managed operations.
Building on the companies’ existing collaboration through the Frontier AI initiative, the alliance will combine Palo Alto Networks’ Unit 42® threat intelligence with NTT DATA’s global cybersecurity expertise, AI-governance capabilities, and managed services. The effort will be supported by joint investments, more than 2,000 certified professionals, and dedicated Forward Deployed Engineers.
Direct engineering collaboration will also give NTT DATA early access to new Palo Alto Networks platform features, enabling the systems integrator to accelerate the development and delivery of AI-security services. The companies initially will focus on highly regulated and critical industries, including financial services, health care, manufacturing, and the public sector.
The initial portfolio will address six strategic transformation areas:
-
Autonomous security operations centers (SOCs): Modernize security operations through agentic AI and managed services that help organizations detect, investigate, and respond to increasingly sophisticated, machine-speed threats while reducing operational complexity.
-
AI governance: Integrate governance, security, and risk management across the AI lifecycle, enabling organizations to address emerging risks and scale AI initiatives with greater accountability, transparency, and control.
-
Identity security: Protect human, machine, and AI-agent identities—including workloads and devices—through an identity-security framework designed to discover, manage, secure, and govern identities across the enterprise.
-
Zero Trust and SASE: Secure users, applications, and data across an increasingly distributed attack surface through a unified Zero Trust and secure-access service edge architecture that incorporates AI-driven threat detection and prevention.
-
Resilient cloud: Improve visibility, compliance, and autonomous risk reduction across multicloud environments through AI-enabled security-posture management and stronger governance.
-
Firewall modernization: Modernize firewall infrastructures to reduce operational complexity, improve visibility, and strengthen enterprise-wide security.
“AI is reshaping both business and cybersecurity, making deep ecosystem collaboration more important than ever,” said Nikesh Arora, Chairman and Chief Executive Officer, Palo Alto Networks. “Expanding our alliance with NTT DATA allows us to operationalize platformization at true global scale, helping enterprises eliminate legacy complexity and move fast without sacrificing safety.” “AI is redefining every aspect of the enterprise, but it is also transforming the threat landscape at unprecedented speed. Organizations need a new approach to cyber resilience that combines AI-driven security, deep industry expertise and global scale,” said Abhijit Dubey, Chief Executive Officer and Chief AI Officer, NTT DATA, Inc.
“Together with Palo Alto Networks, we’re bringing AI-powered cybersecurity innovation together with NTT DATA’s consulting, engineering and managed services capabilities to help clients securely accelerate AI adoption and stay ahead of evolving threats.”
NTT DATA brings world-class cybersecurity expertise to the collaboration, backed by over 7,500 cybersecurity professionals, 70+ delivery centers and 20+ Autonomous Cyber Defense Centers. Paired with Palo Alto Networks AI-powered platforms and Unit 42 threat intelligence, the alliance delivers the technology, expertise and global reach enterprise organizations need to securely deploy AI across complex environments.
About NTT DATA:
Fortune Global 100. We are committed to accelerating client success and positively impacting society through responsible innovation. We are one of the world’s leading AI and digital infrastructure providers, with unmatched capabilities in enterprise-scale AI, cloud, security, connectivity, data centers and application services. Our consulting and industry solutions help organizations and society move confidently and sustainably into the digital future. As a Global Top Employer, we have experts in more than 70 countries. We also offer clients access to a robust ecosystem of innovation centers as well as established and start-up partners. NTT DATA is part of NTT Group, which invests over $3 billion each year in R&D. Visit us at nttdata.com
About Palo Alto Networks:
Palo Alto Networks (NASDAQ: PANW), the global AI cybersecurity leader, protects our digital way of life with a comprehensive portfolio of cybersecurity solutions and platforms across Network, Cloud, Security Operations, AI and Identity. Trusted by 70,000+ customers and powered by Unit 42 threat intelligence, our AI-driven platforms eliminate complexity, empowering enterprises to modernize with confidence and securing the speed of innovation. Explore the future of security at www.paloaltonetworks.com.
………………………………………………………………………………………………………………………………………………………………………………………………
References:
Anthropic’s Project Glasswing aims to reshape IT cybersecurity
Palo Alto Networks and Google Cloud expand partnership with advanced AI infrastructure and cloud security
Highlights and Analysis of July 30th U.S. Senate hearing on AI and telecommunications
Applying Zero Trust at the Wireless Edge: Securing Mixed WPA2 and WPA3 IoT Fleets
Fortinet and Palo Alto Networks are leaders in Gartner Magic Quadrant for Network Firewalls
Key Differences Between Network Cybersecurity and Control System Cybersecurity & Why It Matters
SHIELD-6G with AI-native cyber threat intelligence platform to enhance cybersecurity for Europe’s future 6G networks
Countdown to Q-day: How modern-day Quantum and AI collusion could lead to The Death of Encryption
Cybersecurity threats in telecoms require protection of network infrastructure and availability
Network X Americas: AT&T and Comcast reveal huge AI impact on network operations
Sovereign AI infrastructure for telecom companies: implementation and challenges
Dell’Oro: Data Center Physical Infrastructure revenue to grow at 22% CAGR from 2025-2025/forecast comparisons, analysis, risks
According to Dell’Oro Group, global Data Center Physical Infrastructure (DCPI) manufacturer revenue is projected to grow at a 22% compound annual growth rate (CAGR) from 2025 to 2030, reaching $120 billion by the end of the period. This growth is driven by net additions to installed IT capacity, which account for the large majority of the forecast. Additionally, the infrastructure content per megawatt will have a smaller effect as higher-density and liquid-cooled architectures redistribute spend across DCPI categories.
“The AI buildout has moved past the point where it can be treated as a surge. It is now the baseline against which the rest of the market is measured,” said Alex Cordovil, Research Director at Dell’Oro Group. “What has changed in this forecast is where the risk sits. Demand is no longer the open question—delivery is. Equipment lead times, construction labor, grid interconnection, and community consent all remain constrained, especially with the first statewide data center moratorium now in force.”
Additional highlights from the Data Center Physical Infrastructure 5-Year July 2026 forecast report:
- Capacity Additions Peak in 2026: Annual net capacity additions peak in year-over-year growth terms in 2026 and moderate steadily thereafter, remaining in double-digit growth territory through 2030. The market is still expanding quickly, but no longer accelerating. North America leads capacity additions over the period, followed by China.
- Thermal Management Leads Segment Growth: Thermal Management remains the fastest-growing DCPI segment, with liquid cooling the fastest-growing technology as rack densification moves the technology from an option to a precondition. Heat rejection coverage has been expanded in this edition, with water-cooled chillers expected to grow faster than air-cooled units on scalability rather than efficiency. Chillers remain a staple of data center specifications, even in warm-water designs, since free cooling loses effectiveness during the hottest days of the year.
- UPS Growth Concentrates in Larger Systems: Growth within the UPS segment concentrates in higher power rating three-phase systems, which are expected to expand faster than smaller units as the larger building blocks of AI clusters push deployments up the capacity curve. Medium-voltage designs are gaining ground, connecting UPS systems closer to the grid and attracting new entrants alongside established suppliers. Solid-state transformers are projected to weigh meaningfully on UPS demand beginning in 2029, initially focusing on large AI factories that have largely moved away from UPS-based architectures.
- Hyperscalers and Colocation Anchor Demand: Hyperscalers end the period as the largest single contributor to DCPI revenue, although their growth has slowed compared to the pace seen in 2025–26, as they lean more heavily on colocation partners to serve workloads, particularly outside the United States. Colocation remains central to the buildout, and the spread of powered shell development is shifting equipment procurement onto the tenant, moving revenue among customer segments without altering building occupancy. Newly separated in this forecast, AI-specialized Cloud—the neoclouds and AI model builders—becomes one of the fastest-growing lines in our coverage. Enterprise demand continues to grow, but more slowly than the rest of the market.
- Regional Diversification Builds: North America continues to lead regional growth, with China the next largest contributor. EMEA is the only region revised downward from the January forecast, reflecting slower power availability and a more difficult permitting environment. Community opposition has become a material constraint on siting, blocking or delaying a meaningful share of announced projects. Together with the expected repricing of U.S. natural gas, are expected to support faster growth in CALA and Asia Pacific excluding China.
Dell’Oro Group’s Data Center Physical Infrastructure 5-Year Forecast report provides a complete overview of the Data Center Physical Infrastructure market. This covers market sizes and forecasts for uninterruptible power supplies (UPS), thermal management, cabinet power distribution and busway, rack power distribution, IT racks and containment, and software and services. Allocation of manufacturer revenues by hyperscaler, other cloud, colocation, telco, and enterprise customer segments is also provided, alongside a forecast of data center capacity additions by region. For more information about the report, please contact us at [email protected].
………………………………………………………………………………………………………………………………………………………………………………………
Forecast Comparisons:
Dell’Oro’s $120 billion DCPI forecast through 2030 is at the high end of published physical-infrastructure manufacturer-revenue estimates, but it is directionally consistent with other firms’ forecasts for adjacent power, cooling, and mechanical/electrical (M&E) categories. The differences largely reflect market definition: DCPI is not interchangeable with total data-center capex, construction, IT equipment, or facilities real estate.
The 22% Dell’Oro CAGR should not be read as a consensus CAGR for every DCPI component. Power equipment forecasts around 7.5% and broader support-infrastructure forecasts around 8.2% suggest more moderate growth in legacy categories, while AI-linked liquid cooling is projected to grow in the mid- to high-teens.
The key forecasting judgment is therefore AI infrastructure content per MW: if GPU density keeps climbing and liquid cooling, high-voltage distribution, energy storage, and modular power systems become standard rather than niche, DCPI revenue can grow substantially faster than data-center floor space or even installed MW. Conversely, grid constraints, AI-demand normalization, and lower equipment dollars per watt from scale and engineering improvements could constrain manufacturer revenue growth even as deployed capacity continues to expand.
Comparable Forecasts:
A useful interpretation is that Dell’Oro’s $120 billion is plausible only if the market increasingly captures high-value AI-ready electrical and thermal systems—not merely traditional UPS, air-conditioning, and rack revenue. Adding standalone power and cooling forecasts cannot produce a clean “DCPI total,” because analysts differ in whether they include services, software/DCIM, integration, installation, generators, switchgear, rack infrastructure, and edge facilities.
………………………………………………………………………………………………………………………………………………………………………………………………………..
Image Generated by Perplexity.ai
…………………………………………………………………………………………………………………………………………………….
Analysis – main spending drivers:
-
AI accelerator density. GPU/accelerator clusters raise rack power from conventional enterprise levels to much higher levels, increasing demand for power distribution, UPS capacity, switchgear, busways, backup generation, and energy storage. ABI Research expects AI-dedicated active data-center capacity to rise from 11.5 GW in 2026 to 43.6 GW in 2031, and projects that AI will represent more than half of total data-center capacity in the early 2030s.
-
Shift from air cooling to liquid cooling. Higher-density AI systems cannot be served economically—or sometimes technically—by conventional room-level air cooling alone. Direct-to-chip cold plates, coolant-distribution units, rear-door heat exchangers, liquid loops, heat-rejection equipment, and controls raise cooling-system content per MW. Cooling equipment is therefore forecast to grow faster than the more mature broad power-equipment category.
-
Rapid capacity additions by hyperscalers and colocation operators. JLL expects roughly 97 GW of data-center capacity to be added globally from 2025 to 2030, approximately doubling the sector to about 200 GW. Every new MW requires a physical plant, even where the IT stack is sourced separately.
-
Power availability is becoming the binding constraint. Global data-center electricity consumption is expected to roughly double to 945 TWh by 2030 in the IEA base case. This puts a premium on grid interconnection equipment, substations, medium-voltage distribution, on-site generation, batteries, and energy-management systems—and can cause operators to overbuild or deploy infrastructure earlier than their server installations.
-
Resilience requirements and time-to-power. AI facilities require high availability alongside enormous load ramps. Operators are spending on redundant electrical paths, backup generation, battery systems, microgrids, and modular/skid-based electrical infrastructure to shorten construction schedules and reduce exposure to grid-connection delays.
-
Retrofitting the installed base. Demand is not solely greenfield. Existing hyperscale, colocation, and enterprise sites must upgrade electrical distribution and thermal plants to host AI pods, often retaining conventional infrastructure for legacy workloads while adding liquid-cooling islands.
-
Efficiency, water, and carbon constraints. Higher energy costs, grid constraints, water availability, and sustainability targets push investment toward more efficient thermal architectures, heat reuse where feasible, advanced controls, and power-management systems. These are often capital-intensive even when they lower lifetime PUE, water use, or operating cost.
……………………………………………………………………………………………………………………………………………………………….
Huge Risks to the forecast:
The central downside to Dell’Oro’s forecast is an AI-demand and funding reset: if OpenAI, Anthropic, or other frontier-model providers fail to turn extraordinary usage growth into durable, high-margin cash flows, capacity commitments could be deferred, resized, or cancelled. Because the DCPI forecast assumes nearly 200 GW of added data-center capacity through 2030, even a partial reduction in the AI build plan would materially affect power, cooling, and electrical-equipment orders.
The OpenAI/Anthropic risk:
The potential issue is not that either company vanishes overnight. It is that they—and the hyperscalers and GPU-cloud firms supporting them—may discover that the revenue and gross-margin trajectory does not justify the scale of previously contracted compute.
The risk chain is: AI monetization miss→lower compute utilization / pricing→capex deferrals→fewer energized MW→lower DCPI revenue.
The exposure is unusually concentrated. Advanced AI demand is dominated by a small number of hyperscalers and frontier-model providers; McKinsey estimates that 60–65% of AI workloads in the United States and Europe will be hosted on hyperscaler infrastructure by 2030. Thus, a retrenchment by a few large buyers can have an outsized effect on the physical-infrastructure supply chain.
Why OpenAI is a focal point:
OpenAI’s downside case would be a mismatch between compute obligations and customer monetization:
-
Consumer AI usage may remain high, but paid conversion, enterprise seat expansion, API volume, or willingness to pay for frontier-model performance may disappoint.
-
Inference costs may not decline fast enough relative to prices, leaving growth without attractive contribution margins.
-
New models may yield diminishing commercial differentiation, shortening product cycles and weakening customers’ willingness to pay premium prices.
-
Its financing requirements could become harder to meet if capital markets reassess terminal valuations, the cost of debt rises, or strategic partners limit exposure.
Some reporting and commentary point to very large continuing compute costs and funding needs relative to reported revenue, but the precise economics are opaque because OpenAI remains private and uses non-GAAP and run-rate measures inconsistently across reports. That opacity is itself a risk: DCPI vendors can see announced projects and committed capacity, but cannot fully observe the ultimate cash-flow support for the tenant’s demand.
Why Anthropic is not a complete hedge:
Anthropic’s enterprise orientation and reported revenue growth could diversify the sector’s demand base, but it does not eliminate systemic risk. It faces many of the same conditions:
-
Revenue is substantially concentrated in a relatively early enterprise-AI adoption cycle.
-
Enterprise customers can trial models broadly but consolidate suppliers quickly if performance differences narrow.
-
Model-price competition could reduce revenue per token or per API call faster than cost-per-token declines.
-
Large training runs are discretionary. A pause in the cadence of frontier-model releases would immediately reduce the urgency of new GPU clusters and associated electrical/cooling plant.
Recent reports describe unusually rapid revenue expansion and positive adjusted operating income for Anthropic, but the sustainability and definition of those measures are not independently transparent in the way public-company financial statements are. The relevant question for DCPI is not just whether Anthropic grows revenue, but whether its long-term contracted compute load and its own capital support remain sufficient to sustain multi-year facility commitments.
Other downside mechanisms:
An AI crash is the sharpest downside scenario, but Dell’Oro’s bullish outcome also depends on several more gradual assumptions.
Dell’Oro itself reportedly frames the immediate risk as delivery—equipment lead times, construction labor, grid interconnection, and community consent—rather than demand. Those bottlenecks can cut near-term revenue even if AI demand is real, because DCPI is recognized when facilities are physically delivered and commissioned, not when a GPU cluster or capacity plan is announced.
Efficiency is a double-edged sword:
Dell’Oro’s premise benefits from high rack density: AI systems require more substantial electrical architecture and move cooling from conventional air systems toward liquid cooling. McKinsey notes that direct-to-chip cooling can address roughly 60–120 kW racks, and that immersion can support still higher densities; those architectures increase DCPI content per rack and often per MW.
But efficiency can reverse the volume implication. Better accelerators, model distillation, mixture-of-experts approaches, lower-precision inference, and power-system improvements can reduce electricity and infrastructure required per unit of AI output. The IEA explicitly models a “High Efficiency” pathway in which technology and software efficiency gains materially restrain data-center electricity demand, while its “Headwinds” case assumes slower AI uptake and capacity growth that plateaus beyond 2030, with efficiency offsetting much of the effect of increased IT use.
The key analytical distinction is:
-
Revenue per MW can rise because AI racks need liquid cooling, high-capacity UPS, switchgear, busways, and sophisticated controls.
-
Total MW deployed can fall if model efficiency improves or commercial demand disappoints.
Dell’Oro’s $120 billion outcome requires both substantial net new MW and elevated DCPI content per MW. A positive outcome on only the second factor would not fully protect the forecast.
What would signal trouble:
For a forward-looking DCPI thesis, monitor leading indicators rather than announced headline capex:
-
OpenAI and Anthropic: paid enterprise adoption, API demand, realized—not merely annualized—revenue, gross margin, cash burn, and financing terms.
-
Hyperscalers: capex guidance, AI-service revenue, remaining performance obligations, capacity utilization, and disclosure of power or data-center commitments.
-
GPU-clouds and colocation firms: customer concentration, lease pre-commitments, cancellations, financing costs, and the ratio of contracted versus speculative capacity.
-
Physical deployment: utility interconnection queues, energized MW rather than planned MW, transformer/switchgear order cancellations, and data-center construction starts.
-
Economics: inference price declines versus cost declines, GPU utilization, and evidence that enterprise AI deployments generate measurable productivity or revenue returns.
A particularly bearish signal would be simultaneous model-price deflation, falling GPU utilization, and delayed data-center energization. That combination would mean the sector is not merely supply constrained; it would imply that the financial rationale for capacity has weakened.
Bottom line:
A failure by OpenAI or Anthropic to meet expectations could trigger a classic capital-cycle correction: capacity was ordered on expectations of demand, but the cash flows needed to validate the investment arrive later, at lower margins, or not at all. In that scenario, DCPI’s most vulnerable segments are discretionary greenfield power and cooling deployments attached to single large AI tenants or thinly capitalized GPU-cloud providers.
However, a single lab’s disappointment would not necessarily collapse the entire market. DCPI demand also comes from hyperscaler internal workloads, enterprise AI, cloud migration, conventional data growth, colocation expansion, and infrastructure upgrades. The most likely downside is therefore a lower and lumpier growth path, with project delays and inventory/order corrections, rather than zero growth. The more severe Dell’Oro downside requires a broad AI-ROI failure that causes multiple frontier labs and hyperscalers to retrench at the same time.
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Expose: AI is more than a bubble; it’s a data center debt bomb
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Inside Amazon’s new data center network architecture: quasi random network topology and passive optical devices
Big Fiber’s $250M financing deal to buildout dark fiber routes for AI Data Center expansion
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Disclaimer: Perplexity.ai was used for research and analysis in this article.
……………………………………………………………………………………………………………………..
Executive Summary:
This past Monday, six giant Wall Street asset managers, private-equity firms and banks announced an effort to raise $500 billion to keep fueling the A.I. boom by financing more data centers, power plants and chips. The proposed platform would direct capital to Nvidia customers—including AI startups and data-center operators—at precisely the point when many have struggled to obtain funding through ordinary credit channels.
We take that as a huge warning sign for the proposed AI investments. Here’s why: If the underlying projects offered clearly proven cash flows, predictable utilization and collateral with durable value, lenders would not need a specially assembled consortium, headline-scale commitments and Nvidia’s direct involvement to make the loans happen. The initiative appears designed to overcome a financing bottleneck created by the extraordinary gap between AI infrastructure spending and demonstrated AI revenue.
This proposed $500 billion AI-financing initiative is less a validation of durable AI economics than an admission that the sector’s spending plans have outgrown its customers’ ability—or willingness—to finance them conventionally. Rather than demonstrating independently sustainable demand, the arrangement risks extending an investment cycle increasingly dependent on vendor-enabled credit, opaque commitments and financial engineering.
The firms—Apollo, BlackRock, Blackstone, Brookfield, Goldman Sachs and KKR—said they were working together to come up with that huge sum to lend to Nvidia’s customers, including the start-ups that use the company’s chips in data centers to develop and operate A.I. software. These customers, Nvidia said, have been struggling to secure financing for chips and data centers.
Nvidia will connect its customers with one of the six lenders, which will provide financing that could range from loans to credit. The financing will be “at attractive rates,” Nvidia said in a blog post.
In practical terms, this is a vendor-financing mechanism, even if the capital technically comes from third parties. Nvidia is helping its customers obtain the money required to buy Nvidia-dependent infrastructure. The more readily startups and data-center operators can borrow, the more equipment they can order; the more equipment they order, the more Nvidia can sell. That does not mean the demand is fictitious, but it does make it harder to distinguish independent end-user demand from demand supported by an ecosystem that is financing itself.
Circularity is the principal concern. When suppliers, investors, cloud providers, AI labs and lenders all have financial incentives to keep capital circulating within the same small group of counterparties, reported growth can look more robust than the ultimate economics justify. The risk is not simply that projects fail individually. It is that a shortfall in AI-service revenues, utilization or pricing could spread simultaneously through hardware vendors, AI developers, cloud operators, private-credit vehicles and the securities backed by their cash flows. Circular financing can blur the line between real external demand and investment-funded purchases.
Executives from the lenders joined Jensen Huang, Nvidia’s CEO & founder, for an unusual, extended interview on CNBC, where they talked up their new, seemingly insatiable desire to finance infrastructure for A.I. Huang said on the air. He added that “A.I. labs” and “A.I. start-ups” would have access to the financing. He did not name those companies or whether Nvidia would receive any money as part of the effort. David M. Solomon, Goldman’s chief executive, said the consortium was Mr. Huang’s idea.
“We need to raise this money as fast as possible,” said Larry Fink, BlackRock’s chief executive. He also stated: “There’s quite a bit of negativity around A.I. and data centers right now, but let’s be clear: This is going to be creating a huge amount of jobs.”
Skeptical Analysis:
The urgency in those statements deserves more scrutiny. Speed is not a substitute for underwriting, and job-creation claims do not establish that investments will meet their cost of capital. The industry is attempting to finance assets whose useful economic life may be much shorter and more uncertain than that of traditional infrastructure. A GPU fleet can lose competitiveness rapidly when a new architecture, memory standard or systems design emerges. Its resale value can fall sharply if capacity demand weakens. Treating such hardware as collateral comparable to a toll road, utility asset or long-lived building is a major assumption—not an established fact.
The announcement punctuates a head rush on Wall Street and in Silicon Valley into anything that even vaguely resembles A.I. The stocks of tech giants and chipmakers have soared for most of this year, and a pair of the biggest names in the space, Anthropic and OpenAI, are expected to file for initial public offerings that could value them at $1 trillion apiece.
But soaring equity valuations and enormous projected IPO valuations do not answer the basic return-on-investment question: who will pay enough, for long enough, to justify the total cost of the data centers, power plants, networking, GPUs and debt now being assembled? AI vendors may generate impressive revenue growth while still failing to earn enough to cover the depreciation, energy, financing and replacement costs of the infrastructure required to produce it.
Nvidia’s financing narrative appears to conflate broad interest in AI-enabled services with broad, independent demand for capital-intensive AI infrastructure. Governments, enterprises and startups may all seek access to AI capabilities, but the current demand for hyperscale GPU clusters, dedicated power capacity and purpose-built “AI factories” remains concentrated among a relatively small group of frontier-model developers and cloud platforms.
That distinction matters because broad adoption of AI applications does not automatically translate into economically sustainable demand for vast new data-center capacity. Enterprises can consume AI through APIs, hosted platforms, smaller models and open-source software without owning—or financing—dedicated high-density compute infrastructure. Nvidia itself describes demand as spanning enterprises, startups, governments, nations and AI labs, but the critical question for investors is how much of that demand converts into durable, contracted infrastructure revenue rather than experimentation, pilots or subsidized consumption.
As Bloomberg reported last week, OpenAI accounted for somewhere between 50% and 70% of Microsoft’s AI revenue in the 12 months to 30 June.
That degree of concentration is significant. Microsoft disclosed $24.1 billion in sales from OpenAI during the year ended in June; outside estimates place that at more than half, and perhaps about 70%, of Microsoft’s AI-related revenue. Much of the revenue reflects OpenAI’s spending on Microsoft cloud and model-development services, meaning a substantial portion of the apparent AI revenue base may be generated within a tightly linked commercial relationship rather than by a diversified population of external enterprise customers.
That could be problematic if the picture is similar at other hyperscalers and at other frontier AI companies like Anthropic, for example. A market in which a handful of loss-making model developers drive an outsized share of cloud and infrastructure revenue is inherently more fragile than one supported by a broad base of profitable end users. It exposes infrastructure providers and lenders to customer concentration, correlated capital spending and the possibility that a reduction in financing at one frontier lab quickly reduces demand across the supply chain.
Indeed, as has been reported by multiple correspondents – most notably staunch AI critic Ed Zitron – LLM makers like OpenAI are losing money hand over fist and can only charge so much for tokens before customers either curb their usage or switch to open source models. Zitron wrote:
“It’s estimated that 70% or more of the AI revenues of Microsoft, Google, and Amazon were from either OpenAI or Anthropic. UBS estimated that next year, Anthropic and OpenAI’s compute spend would be 48% of all Google Cloud revenues — which means that they likely account for even more than 70% of its AI revenues.”
The commercial challenge is not whether frontier models have value- they do. It is whether they can deliver that value at prices that exceed the combined costs of training, inference, electricity, networking, cloud capacity, depreciation and ongoing model development. If token pricing rises too far, customers may reduce usage, shift workloads to lower-cost models, or use open-source alternatives. If pricing remains low, frontier-model providers may struggle to cover their infrastructure bills. Open-source fine-tuning can materially reduce costs for specialized enterprise workloads, reinforcing the competitive pressure on premium proprietary-model pricing.
The most plausible downside is that the technology becomes broadly useful but insufficiently profitable to support today’s extreme capital intensity. That outcome would leave the sector with too much high-cost capacity, thin margins, declining GPU collateral values and lenders dependent on assumptions about utilization and cash flows that have not yet been tested through a downturn. The foundational financial risk is straightforward: AI-service revenues may prove insufficient to service the fixed obligations incurred to construct the infrastructure. Notably, Nvidia stock dipped modestly on Monday after The Financial Times reported that the company was nearing the mammoth financing deal.
While the contours of the arrangements were announced Monday afternoon, details remained scarce. A joint news release referred only to “memorandums of understanding” to “create dedicated pools of capital at significant scale.”
That language is important. Memorandums of Understanding (MoU’s) are not equivalent to binding, fully funded commitments. Until investors know the actual terms—capital committed, leverage permitted, collateral requirements, Nvidia’s role in losses, loan maturities, customer concentration limits and underwriting standards—the $500 billion figure is better understood as an ambitious financing target than as validated capital deployment. Reporting has described the initiative as a multiyear target rather than cash already committed, while questions remain about the scale of any Nvidia backstop.
During their television interview, the lenders’ executives alluded vaguely to “yield-based products” and even securitization, or the creation of bonds that would divvy up the revenue from A.I. labs into risky and less risky categories. There were several references to A.I. as a new asset class and to allowing smaller investors an opportunity to invest in debt backed by the data centers.
This is where the proposal moves from aggressive investment to potential systemic-risk creation. Securitization can distribute risk, but it does not eliminate it; it can instead diffuse difficult-to-value exposure across a wider investor base. Packaging AI-data-center debt into yield products may make financing more available, but it also risks obscuring the quality of the underlying cash flows, the degree of correlated exposure among borrowers and the vulnerability of rapidly depreciating hardware collateral. The more complex the capital stack becomes, the greater the danger that investors mistake engineered liquidity for genuine economic value.
Executive Quotes:
“NVIDIA has reached an important milestone. We began by building chips; today, we are helping create a new class of productive, investable infrastructure: AI factories,” said Jensen Huang, founder and CEO of NVIDIA. “In AI, compute is revenue. NVIDIA compute is uniquely suited for this role. It is broadly adopted, flexible across models and workloads, fungible and transferable across customers and operators, and continuously improved through CUDA software — extending its useful life and improving its economics over time. It is supported by a deep global ecosystem of developers, customers and offtakers. That is why we are bringing the world’s leading long-term capital providers together to independently underwrite AI infrastructure. These financing platforms will help customers access scarce compute at scale and build the DSX AI factories that will power every industry and country in the age of AI.”
“Modern compute has emerged as a scarce, mission-critical asset class with compelling investment characteristics that is positioned to drive significant long-term economic growth and productivity gains,” said Apollo President Jim Zelter. “The combination of NVIDIA’s proprietary technology ecosystem and Apollo’s flexible, long-term capital base provides a strong foundation to support the next stage of the AI buildout as part of the broader Global Industrial Renaissance.”
“The AI buildout will require unprecedented investment and a skilled workforce to turn that investment into the infrastructure that will help power future growth,” said Larry Fink, Chairman and CEO of BlackRock. “This partnership deepens our relationship with NVIDIA, including through the AI Infrastructure Partnership, and brings together NVIDIA’s leadership in accelerated computing with BlackRock’s ability to connect long-term capital to essential infrastructure. Together, we can help deliver the compute capacity that companies need to grow and create more jobs, supporting the continued growth of the U.S. and global economies, while creating attractive, long-term investment opportunities for our clients.”
“NVIDIA has created extraordinary demand for its compute through an intense focus on customer value and versatile technology,” said Jon Gray, President and COO of Blackstone. “We continue to be enormous investors globally across the NVIDIA ecosystem, and this announcement further underscores our confidence in their platform and the future of AI infrastructure.”
“As our strategic partner, NVIDIA is enabling us to scale AI factories. We are excited about further collaboration to build and fund the backbone of AI globally,” said Bruce Flatt, CEO of Brookfield. “With demand for large-scale AI compute growing significantly as adoption scales across industries, compute is fast becoming the essential layer of infrastructure and a core pillar of the Brookfield AI infrastructure strategy.”
“We’re in a pivotal moment of a historic AI investment cycle. NVIDIA’s full-stack platform is in high demand and uniquely positioned at the center of that global buildout,” said David Solomon, Chairman and CEO of Goldman Sachs. “Our investment and distribution roles reflect our confidence in NVIDIA’s leadership, and we’re excited for the new opportunity to create a market for credit backed by NVIDIA compute.”
“Compute has become a critical infrastructure asset. As we’ve scaled our approach to digital infrastructure, we’ve learned that delivery, not ambition, is the hard part. That’s why we’re excited to build on our strategic partnership with NVIDIA, a founding investor in Helix Digital Infrastructure, to bring together NVIDIA’s accelerated computing platform with KKR’s long-duration capital, infrastructure expertise and capital markets capabilities to turn growing demand into real capacity at extraordinary scale,” said Joe Bae and Scott Nuttall, Co-Chief Executive Officers of KKR.
“This is the very beginning — like what it was when I started in the mortgage-backed securities market in the 1970s,” Mr. Fink said. “I look upon this as a next future for financial engineering.”
That analogy should be treated as cautionary, not reassuring. Financial engineering can expand access to capital and spread risk efficiently when assets have transparent valuations, stable cash flows and conservative underwriting. It becomes dangerous when it is used to finance unproven revenue models, rapidly obsolescing assets and demand forecasts that must remain exceptionally optimistic simply to justify the initial investment.
Huge Risks Explained:
If AI demand stalls, Nvidia faces a sharp reversal in hardware demand and a potentially damaging credit overhang, while lenders could be left financing underutilized data centers secured by equipment whose value can decline far faster than conventional infrastructure. The common vulnerability is that the same uncertain AI revenue streams would be expected to support chip purchases, data-center leases, project debt and securitized investment products. Nvidia is especially exposed to risks:
-
Order cancellations and lower pricing power. Cloud providers, AI labs and startups would likely slow GPU orders, defer deployments or renegotiate capacity commitments. Nvidia could face weaker revenue growth, inventory risk and pressure on the high margins that have supported its valuation.
-
Vendor-financing and counterparty risk. If Nvidia is arranging or backstopping financing for customers buying its systems, a demand slowdown could turn what appeared to be hardware sales into indirect credit exposure. Customers unable to earn adequate returns from AI services may struggle to repay loans used to buy Nvidia equipment. The risk is magnified where the company’s commercial success depends on borrowers gaining access to financing in the first place.247wallst+1
-
Collateral impairment. GPUs are not durable, slow-depreciating infrastructure assets. A new chip generation, a shift toward more efficient models, or weak utilization can materially reduce the resale value of installed systems. If lenders rely on those systems as collateral, a default could leave them holding equipment worth substantially less than the loan balance—and Nvidia could face lower demand for both new and prior-generation products. Moody’s identifies rapid capacity expansion and fast-changing chips, cooling and computing architectures as sources of overbuilding and technology-obsolescence risk.moodys
-
Feedback-loop risk. A slowdown could create a negative cycle: AI customers reduce spending; Nvidia’s sales weaken; lenders become more cautious; financing availability tightens; customers cut orders further. Where vendors, customers and capital providers are financially intertwined, the decline can be more abrupt than a normal inventory correction.
-
Equity-valuation risk. Nvidia’s market value reflects unusually strong assumptions about the longevity of AI spending, margins and growth. A reassessment of those assumptions could compress the valuation sharply even if Nvidia remains profitable. BIS warns that disappointment in AI returns could trigger a sudden financing pullback and turn the capex boom into a prolonged investment bust.bis
Lenders’ exposure:
The most immediate lender risk is a mismatch between long-lived debt obligations and unstable, technology-dependent revenue. A data center might be financed over many years, but its GPU fleet may need continual upgrades to remain competitive—requiring additional capital expenditure before the original debt is repaid. Moody’s notes that this combination of increasing capital intensity, uncertain compute requirements and structured finance can pressure developers, landlords and investors through execution, renewal and refinancing risk.moodys
Construction and power risks:
A demand slowdown could arrive before projects enter service. That creates a particularly difficult situation for lenders because construction interest, cost overruns and power-reservation charges may accumulate before revenue begins.
Permitting delays, local opposition, water constraints and electricity-grid limitations further compound this exposure. Reuters reported that lenders increasingly treat project readiness—including approvals, permits and local community support—as a credit factor because delays can increase costs, jeopardize covenants and prevent projects from reaching revenue-generating operation.
System-wide scenario:
The more serious scenario is a correlated unwind:
-
AI applications fail to deliver enough monetizable demand.
-
AI labs and cloud providers reduce compute commitments.
-
Data-center utilization and expected rental income fall.
-
Borrowers cannot service or refinance project debt.
-
GPUs and related infrastructure lose collateral value.
-
Losses reach private-credit funds, banks, securitized vehicles, insurers and institutional investors.
-
New financing becomes unavailable, causing further cuts in infrastructure orders and Nvidia sales.
This would not necessarily resemble the 2008 banking crisis: some first-loss exposure sits outside regulated banks. But Chicago Booth research estimates that a severe re-rating of AI-related debt could still produce roughly $60 billion to $140 billion in realized credit losses, alongside large equity-market effects.
What matters most:
The decisive question is not whether AI is useful or whether data centers remain necessary. It is whether cash-paying end users will generate sufficient, durable revenue to justify the full cost of the hardware, power, real estate, construction and financing now being committed. If that answer is no, the sector may discover that it financed capacity—not returns.
……………………………………………………………………………………………………………………………………………………………………………………
From Google’s Gemini:
-
- The Revenue Void: If OpenAI or Anthropic defers or cancels capacity commitments, hyperscalers are left with energized Megawatts (MW) that have no immediate, high-paying tenant.
- Stranded Capital: The specialized power, liquid cooling systems, and electrical equipment tailored for dense AI clusters cannot easily be repurposed for traditional cloud workloads without lowering returns on invested capital (ROIC).
| Financial Metric | Baseline Forecast (Bull Case) | Partial Monetization Reset | Severe Crash / Structural Downside |
|---|---|---|---|
| Cloud Revenue Growth | Accelerated (driven by AI APIs & enterprise seats) | Flattens out as enterprise customers consolidate suppliers | Decelerates sharply; circular cloud revenue loops collapse |
| CapEx Infrastructure | Full execution of Dell’Oro’s ~200 GW build out by 2030 | 20–30% of capacity commitments deferred or resized | Mass cancellations of orders; multi-year build freezes |
| Operating Margins | Expands as inference costs decline relative to software prices | Compresses due to underutilized GPU clusters and high DCPI fixed costs | Severe contraction; massive asset write-downs and depreciation drag |
| ROIC | Historic highs driven by high-density compute demand | Diluted; longer payback periods for specialized data centers | Tanks; billions in stranded physical capital and obsolete hardware |
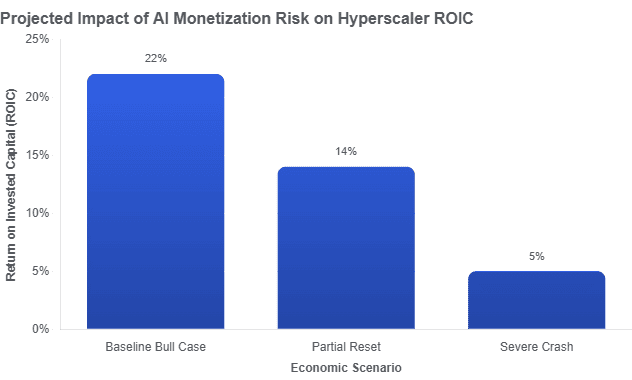
References:
https://www.nytimes.com/2026/08/10/business/ai-nvidia-lenders-500-billion.html
https://www.wheresyoured.at/dont-look-up/
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs (07/23/26)
Merry-go-round of dog chasing its tail: Relationship between U.S. hyperscalers and private Gen AI companies
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Amazon’s Jeff Bezos at Italian Tech Week: “AI is a kind of industrial bubble”
Big Tech AI spending binge results in massive job cuts!
AI spending boom accelerates: Big tech to invest an aggregate of $400 billion in 2025; much more in 2026!
FT: Scale of AI private company valuations dwarfs dot-com boom
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
AI Data Center Boom Carries Huge Default and Demand Risks
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Gartner: AI spending >$2 trillion in 2026 driven by hyperscalers data center investments
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?