AI data centers
Google’s Project Suncatcher: Satellite Orbit Validation of AI Accelerator Compute and Thermal Management
Executive Summary:
On Thursday, October 1st, Google plans to launch an experimental satellite designed to assess whether AI inference workloads can operate correctly in low Earth orbit. The spacecraft, designated MVP, is a technology demonstrator for Project Suncatcher, Google’s research initiative exploring space-based, solar-powered AI infrastructure.
Last month, technicians in protective suits and hairnets inspected, handled and tested the refrigerator-sized satellite commissioned by Google. They evaluated its deployable solar panels, which will unfold after launch and orient toward the sun. The spacecraft then underwent vibration testing to determine whether launch loads could damage its onboard processors or compromise mechanical assemblies. Technicians also applied witness marks across fasteners to identify any loosening during the test.
The satellite passed the vibration test: its fasteners remained secured, and its chips showed no apparent damage. James Manyika, Google’s senior vice president for research, described the outcome as “great,” while noting that orbital operations remain the more consequential test.
Project Suncatcher seeks to evaluate the technical viability of placing AI-compute infrastructure in space, where photovoltaic power is potentially abundant and uninterrupted by terrestrial weather or nighttime cycles. On Oct. 1, the MVP spacecraft is scheduled to launch aboard a SpaceX Falcon 9 from Vandenberg Space Force Base near Santa Barbara, California. Google provided The New York Times with an early inside look at the project, which would have appeared largely science fictional only a year ago.
Elon Musk, Jeff Bezos, Sam Altman and others have pledged support for orbital data centers, but the concept remains constrained by significant technical and economic barriers. These include launch cost, radiation tolerance, thermal management, intersatellite communications, orbital operations and eventual spacecraft disposal. At the same time, mounting local opposition to terrestrial data-center construction, together with power-grid, land-use and transmission constraints, has increased industry interest in off-planet computing infrastructure.
Google is not launching a data center. MVP is an experimental precursor intended to validate selected subsystem and operational assumptions. The spacecraft carries four tensor processing units (TPUs), specialized AI accelerators whose aggregate compute capability is approximately comparable to that of a single data-center server. Its solar-array system will provide roughly 1 kW of power, broadly comparable to the consumption of a household hair dryer.
That power budget is sufficient to evaluate how Google’s hardware performs under orbital radiation, vacuum and thermal conditions. The spacecraft will process simple AI queries and is intended to operate for approximately one year, although it is expected to remain in orbit for as long as six years before orbital decay causes atmospheric reentry and burnup.

Google tested A.I. chips at Crocker Nuclear Laboratory in Davis, Calif., with a particle accelerator known as a cyclotron. The goal was to test whether the chips could survive radiation in space.
Photo Credit…Jason Henry for The New York Times
………………………………………………………………………………………………………………………………………………………………….
Mr. Manyika emphasized that Google’s expectations are measured. “We don’t expect, to be perfectly frank, that we’ll have anything usefully operational in the next few years,” he said, comparing the mission to the company’s early efforts to build driverless cars. “Remember how Google was researching for like 15 years, before anything showed up? I think this is going to look like that.”
Scaling from one technology-demonstration satellite to a distributed orbital-computing system would require substantial capital and years of development, according to Brandon Lucia, a professor of electrical and computer engineering at Carnegie Mellon University. “If you do this on a large scale, there are additional engineering problems,” he said. “That is uncharted waters.”
From concept to flight test:
Project Suncatcher originated with Blaise Agüera y Arcas, a Google vice president and AI researcher who leads a team focused on intelligence research. Approximately three years ago, he attended a gathering of entrepreneurs and AI researchers centered on the escalating energy requirements of AI systems. He left convinced that space-based computing could eventually provide access to large-scale solar generation.
The idea “has been on my mind since I was kid,” he said. “There are longstanding ideas in science fiction about using stars for computation.”
Mr. Agüera y Arcas subsequently presented the concept to Mr. Manyika, who was initially skeptical but agreed to investigate whether AI processors could survive the radiation environment of space and be cooled effectively in vacuum.
In February 2025, Google began exposing AI chips to radiation at the Crocker Nuclear Laboratory in Davis, California. There, a cyclotron subjected the chips to radiation doses intended to approximate five years of space exposure. Radiation can induce “bit flips”—single-event errors that alter a circuit’s binary state from zero to one or from one to zero. Such faults can degrade or interrupt computation and can be particularly consequential in AI accelerators, memory systems and control electronics.
Google’s tests produced encouraging results. The company found that restarting the chips could generally clear the observed bit flips, suggesting that reset and recovery mechanisms may mitigate at least some radiation-induced errors. The test does not, however, eliminate the broader need for fault tolerance, error detection and recovery across a space-qualified computing system.
In May 2025, Mr. Agüera y Arcas joined a meeting arranged by Mr. Manyika to present the project to Sundar Pichai, Google’s chief executive. Sergey Brin, Google’s co-founder, also attended.
Mr. Brin and Mr. Pichai quickly greenlit the project. “OK, so this is a good idea,” Mr. Brin had said, according to Mr. Agüera y Arcas. “Let’s talk about how we’re doing it.”
Google has not disclosed Project Suncatcher’s budget. The company has said it expects orbital data-center costs to approach terrestrial data-center costs in the mid-2030s, assuming continuing reductions in launch costs. That assumption is central to the commercial premise: spacecraft hardware, launch, insurance, operations, networking and replacement cycles must collectively become competitive with land, power, cooling, grid interconnection and construction costs on Earth.
Satellite platform and thermal design:
Google contracted with Planet Labs, a satellite-imagery provider in which it had previously invested, to develop spacecraft capable of carrying its AI processors. James Mason, Planet Labs’ chief space officer, said discussions with Mr. Brin about performing computing tasks in space had occurred over several years, although the concept had previously appeared more distant.
“Back then, it seemed further off,” Mr. Mason said. “That was really before large language models took off and A.I. demand really started going exponential.”
Planet Labs agreed to launch two Google satellites in 2027. Google subsequently sought an earlier on-orbit demonstration and accepted additional programmatic risk to accelerate the schedule, according to Eric Stevens, a director of systems engineering at Planet Labs. To meet that timeline, Google integrated its AI chips into an existing Planet Labs satellite platform and initiated qualification testing.
Thermal management is among the program’s most consequential engineering challenges. AI accelerators produce substantial heat during computation, while convection-based cooling systems—including conventional fans—cannot operate in vacuum. Heat must instead move through conductive paths and be rejected through radiation.
Google’s design uses a layered thermal architecture. TPU devices are mounted on a green motherboard, above which sits thermal interface material—a compliant, pale-green compound supplied in sheets and intended to improve heat transfer between the chips and the adjacent metallic heat-spreading structure. Aluminum and copper layers conduct heat away from the motherboard to a radiator panel, which rejects thermal energy into space.
The initial system will operate in duty cycles rather than continuously. Travis Beals, Google’s senior director of product management for Project Suncatcher, said the chips can operate for approximately 15 minutes before they must be shut down to cool. Within those intervals, the processors will handle short inference requests for Google’s Gemini AI system.
The scaling challenge:
Google’s roadmap extends beyond the MVP mission. The company plans to launch two additional satellites next year and has developed concepts for constellations of more than 80 spacecraft flying in close formation and communicating with one another while processing AI workloads. Google is also evaluating the prospect of a purpose-built spacecraft approximately the length of a soccer field.
The key question is not whether a few AI accelerators can operate in orbit, but whether an orbital compute system can scale economically and reliably. A commercially useful architecture would need to solve several interdependent issues:
-
Radiation hardening, fault detection, redundancy and recovery for processors, memory, networking and spacecraft-control systems.
-
Continuous thermal rejection at substantially higher compute densities than the MVP demonstration.
-
High-capacity intersatellite links and ground connectivity capable of moving model inputs, outputs and potentially model parameters.
-
Autonomous fleet management, precise formation flying, collision avoidance and debris-risk mitigation.
-
Launch, replacement and disposal economics that compete with terrestrial data-center construction and power procurement.
-
A sustainable operating model for systems whose computing resources, maintenance cycles and network topology are inherently orbital rather than terrestrial.
The MVP mission does not resolve those issues, but it should generate operational data on the foundational constraints: radiation effects, thermal behavior, processor reliability, power availability and the feasibility of serving simple AI inference requests from orbit.
“If, five years from now, everything we’ve done has worked perfectly, it probably means we’ve not taken enough risk and we’ve not learned as much as we could,” Mr. Beals said. “If we’re really successful with this in the long run, this will ultimately be boring and people won’t think anything at the fact that their Gemini query might be getting served in space.”
References:
https://www.nytimes.com/2026/09/24/technology/google-suncatcher-ai-data-center-space.html
Dell’Oro: Data Center capex grew 92% in 2Q-2026 (caveats galore)
According to a new report by Dell’Oro Group, the global data center capital expenditures strongly accelerated in 2Q 2026. Continued AI infrastructure investment supported growth across compute, storage, networking, and physical infrastructure, while rising memory and storage prices significantly increased server average selling prices.
“Data center capex growth broadened in the second quarter as investment accelerated across both established Cloud Service Providers and emerging AI infrastructure customers,” said Baron Fung, Vice President of Research at Dell’Oro Group.
“Spending remained concentrated in NVIDIA Blackwell Ultra and hyperscaler custom accelerators, while agentic AI created incremental demand for general-purpose compute, storage, and complementary networking. Neocloud providers and AI model builders are also becoming increasingly important contributors to infrastructure investment. These companies are rapidly expanding their own capacity while deepening partnerships with cloud service providers.”
“Looking ahead, ongoing accelerator deployments and emerging agentic AI and AI-related storage workloads should sustain strong capex growth through the remainder of 2026 and beyond, although supply constraints could limit the pace at which planned infrastructure is deployed,” explained Fung.
Additional highlights from the 2Q 2026 Data Center IT Capex Quarterly Report:
- Neocloud and AI Model Builder capex grew the fastest among the customer segments, reflecting the early stages of their infrastructure buildouts.
- Higher memory and storage prices provided an additional lift to capex by driving server average selling prices higher.
- Dell led server OEM revenue, followed by SuperMicro and Lenovo, while white-box server revenue reached a record high.
………………………………………………………………………………………………………………………………………………………….
On August 18th Dell’Oro Group forecasted that worldwide data center capital capex is to maintain growth momentum and surpass $3 trillion by 2030. High-end accelerators powering accelerated servers optimized for AI are expected to represent the largest share of data center capex and remain the primary driver of capex growth over the forecast period.
“Our 2030 data center capex outlook has nearly doubled since the January 2026 forecast, reflecting higher hyperscale capex guidance, increased projections for global data center power capacity, and higher commodity costs,” said Baron Fung, Vice President of Research at Dell’Oro Group. “High-end accelerators powering AI-optimized servers are expected to account for the largest share of data center capex and remain the primary driver of growth over the forecast period.
“However, the pace of growth will depend on the sustainability of investment, power availability, and supply chain conditions. Accelerated and heterogeneous computing, along with innovations in server efficiency, could help mitigate the rising cost and infrastructure demands of AI. The Top 4 US hyperscalers alone could represent about half of global capex, while enterprise investment remains constrained by uncertain AI returns,” according to Fung.
Additional highlights from the Data Center IT Capex 5-Year July 2026 Forecast Report:
- High-end accelerators are expected to account for the largest share of data center capex and remain the primary driver of spending growth through 2030.
- General-purpose server demand is expected to benefit from growing inference, agentic AI, and storage workloads, broadening infrastructure growth beyond accelerated computing.
- The newly added AI-specialized cloud segment, comprising AI model builders and neocloud service providers, is projected to grow at nearly a 60 percent CAGR, outpacing the growth of other customer segments.
IEEE Techblog Analysis:
- Dell’Oro had already raised its 2026 global data-center capex outlook to more than $1 trillion in its June 2026 report. It also said 2H26 growth was expected to accelerate because of NVIDIA Rubin deployments and hyperscaler custom-accelerator refreshes. That makes the new 92% 2Q figure much more significant: this isn’t simply a strong quarter; it is occurring within a $1-trillion-plus annual investment cycle.
- Epoch AI’s tracking shows combined hyperscaler quarterly capex has been increasing at an average 72% annual rate since 2Q23 and projects approximately $770 billion for 2026 if the trend continues.
- Another estimate from Moody’s put 2026 hyperscaler capex at $785 billion, including Microsoft, Amazon, Meta, Alphabet, Oracle and CoreWeave.
- Dell’Oro’s separate 2Q semiconductor/component report says data-center component revenue increased 182% YoY, while DRAM and storage-drive average selling prices per bit more than doubled. Therefore, some of the 92% increase in data-center capex is clearly inflation in the cost of the equipment, not necessarily an equivalent increase in physical infrastructure.
- Therefore, the 92% increase in capex should not be interpreted as a 92% increase in deployed computing capacity, because sharply higher DRAM, NAND/storage and other component prices are inflating server system costs.
What’s Missing from this Report:
The press release for this report notes that worldwide data center capital expenditures grew 92% in 2Q02026, driven by surging AI demand and memory costs. However, it omits precise spending figures for individual hyperscalers (Alphabet, Amazon, Meta, Microsoft and Oracle) as well as OEM market share details. Moreover, YoY growth can conceal the current trajectory. Sequential growth would show whether the AI infrastructure spending acceleration actually intensified during 2Q of 2026.
Conclusions:
The 92% year-over-year increase in 2Q26 data-center capex needs to be viewed against a much larger AI infrastructure investment cycle. Dell’Oro had already raised its 2026 global data-center capex forecast to more than $1 trillion, with 2H26 spending expected to accelerate further as NVIDIA’s Rubin systems and hyperscaler custom accelerators ramp. At the same time, Dell’Oro reported that data-center semiconductor and component revenue surged 182% in 2Q26, with DRAM and storage-drive prices per bit more than doubling year over year. Consequently, a significant portion of the reported capex growth reflects higher equipment prices rather than a comparable increase in physical computing capacity. Meanwhile, hyperscaler capex is increasingly being supplemented by debt-financed Neocloud and AI-model-builder infrastructure, broadening the investment cycle beyond the traditional cloud giants.
Dell’Oro Group’s Data Center IT Capex Quarterly Report details the data center infrastructure capital expenditures of the largest hyperscale cloud service providers, AI Model Builders, Neocloud, Rest of Cloud, Telco, and Enterprise customer segments. It provides the allocation of data center infrastructure capex for general-purpose and accelerated servers, storage systems, and other auxiliary data center equipment. The report also discusses market trends, drivers of the leading cloud service providers’ capex growth during the quarter, and the outlook for the next year. To purchase this report, please contact us at [email protected].

…………………………………………………………………………………………………………………………………………………………………………………..
References:
Dell’Oro: 2H2026 Data Center Capex to Accelerate due to massive AI Deployments
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
AI risks and backlash increase; Recap of the circular loop of fake AI profits and hyperscaler markups of private AI companies
The Artificial Intelligence (AI) boom has continued to drive much of the U.S. economy, stock market and psychology this year. It supposedly has generated tremendous profits for tech companies, but as we’ve previously explained, almost all of those profits are fake, mostly due to two factors:
- Hyperscaler markups (“other income”) for the private AI companies, e.g. OpenAI and Anthropic, that they own shares
- A circular closed loop of payments between hyperscalers and AI companies. Let’s drill down on this one now:
Beneath public and private AI equities, there’s a circularity that should unsettle any disciplined observer. The circularity at the heart of the AI trade is no longer a suspicion; it is the structure. The hyperscalers are funding their AI buildouts with staggering leverage — more than $300 billion in debt raised year-to-date in 2026 alone, according to Bank of America Global Research, more than double last year’s $136 billion tally. Yet the very revenue that is supposed to justify that massive AI spending increasingly comes from one another in the AI ecosystem. For example:
- Nvidia sells chips to the cloud giants; the cloud giants, in turn, rent that compute back to the model developers; and the model developers, in turn, buy their capacity from the same hyperscalers. It is a closed loop, and a closed loop is not a business model.
- Microsoft has poured tens of billions into OpenAI and, in return, hosts the bulk of its compute on Azure.
- Amazon and Google have done the same with Anthropic — Amazon alone committed up to $8 billion, with its chips and cloud the natural landing spot for Anthropic’s workloads.
- Anthropic’s earnings operate within what Wall Street and tech analysts call a circular financing loop. Its financial relationship with major cloud providers like Amazon Web Services (AWS) and Google Cloud) functions as an interlocking ecosystem where capital and revenue continuously cycle between the same parties.
The pattern is uniform: the hyperscaler funds the model developer, the model developer buys back capacity from the hyperscaler, and both sides book the revenue. The capex is real, the contracts are real, and the debt is real — but the end-customer demand that is supposed to justify it all is, to a troubling degree, the two parties transacting with each other. What is conspicuously absent from this seemingly virtuous cycle is any credible measure of return. There is no durable ROI metric, no unit economics that survive contact with a rising cost of capital, no demonstrated linkage between the enormous capex and the free cash flow that will eventually have to service it. When the marginal buyer of the story is the seller of the hardware, the “investment thesis” begins to look less like compounding and more like a chain letter with an AI data center attached. Rates are already telling us the cost of this experiment. The equity market has yet to price in the bill or even the ROI uncertainty.
The AI circularity trade is not a market; it is a mirror. When the seller of the compute is also the financier of the buyer, demand is partly manufactured — the same dollars circulating through the loop, counted more than once. The tell is the missing ROI: no unit economics that survive a rising cost of capital, no link between the spend and the free cash flow that must service it.
………………………………………………………………………………………………………………………………………………………………………………………..
Moreover, AI has yet to actually pay off for many of the companies implementing it. Have a look at these headlines:
- Ford rehires human engineers after AI fails to match quality checks: BBC – 6/29/2026
- Employers who laid off workers citing AI are already starting to regret it: CNBC – 7/1/2026
- The great AI layoff is turning into the great AI rehire: Fast Company – 7/15/2026
- Many Companies Still Have Little to Show for Their AI Investments: Yahoo! Finance – 8/7/2026
- 90% of executives say AI hasn’t boosted productivity. Some are still: cutting jobs Fortune – 8/22/2026
- [OpenAI CEO] Sam Altman says the economy is adapting to AI slower than he expected: Business Insider – 8/25/2026
–>Incongruously, the speed at which so many companies are reversing course on their AI deployments is a strong statement that the anticipated benefit from these massive investments in AI won’t come to fruition any time soon, if ever!
………………………………………………………………………………………………………………………………………………………………………………………..
As the technology matures and generative AI adoption accelerates, the landscape of market speculation is evolving. Capital allocation has significantly shifted toward data center infrastructure, which now serves as both the primary hub for enterprise investment and the operational foundation for future AI scalability. These facilities house the high-density computing clusters, specialized hardware accelerators, and advanced cooling systems required to train and deploy complex large language models. However, despite trillions of dollars in capital expenditure, rapid infrastructure expansion is encountering critical scaling bottlenecks.
- Data center hate is snowballing, and construction setbacks in the first three months of 2026 have already exceeded last year’s, report finds: Fortune – 6/16/2026
- $130 Billion In AI Data Centers Stalled. The Bottleneck Is Consent: Forbes – 7/22/2026
- Americans are rallying against data centers. Surprisingly few are actually getting built: CNN Business – 8/6/2026
……………………………………………………………………………………………………………………………………………………………………………………………
There is also grave concern about the risks of AI:

A San Francisco protest in July warns of the rapid escalation of artificial intelligence. Elena Kadvany/S.F. Chronicle
………………………………………………………………………………………………………………………………………………………………………..
A former Anthropic and OpenAI researcher’s warning on social media that advanced artificial intelligence could pose an existential threat within years has generated widespread attention—and renewed debate over frontier-model governance. Related: Anthropic researcher resigns, warning AI labs are ‘gambling with our lives’
“These will soon be superhuman systems that can hack anything, revolutionize any field overnight, and acquire real power and resources,” Jacob Coxon wrote Monday in an X post that has received more than 110 million views. “The people building AI earnestly believe that it could kill us all by the end of the decade.”
Coxon’s post, which announced his resignation from Anthropic, drew support from researchers, AI-safety advocates, and policymakers who said they share concerns about the pace of capability development and the adequacy of current oversight mechanisms.
“Jacob is correct here — we really do earnestly believe AI could kill all humans!” Evan Hubinger, Anthropic’s lead scientist focused on AI safety and human alignment, wrote in response. “I personally think it is >10% within the next decade. I believe Anthropic is trying its best, but we do not yet have a plan to solve alignment for superintelligence and are not clearly on track to.”
The concern centers on a broad set of hypothetical failure modes. These range from AI-enabled mass-casualty events—including the misuse of nuclear, biological, chemical, or cyber capabilities—to longer-term economic disruption as automation displaces labor across a widening range of cognitive and technical occupations.
Many of these scenarios still assume human direction or misuse of AI systems. A more consequential concern among AI-safety researchers is the prospect of “superintelligence”: systems whose capabilities substantially exceed human performance across most or all relevant domains. Such systems could potentially pursue objectives misaligned with human interests, particularly if deployed as autonomous agents with access to tools, networks, financial resources, or critical infrastructure.
“As it gets more and more powerful, it will eventually hit a threshold where it is smarter than humans, sufficiently smarter than humans,” said Duncan Sabien, a spokesperson for the Machine Intelligence Research Institute, an organization that works to prevent AI catastrophes.
Sabien said it is inherently difficult to forecast outcomes as extreme as human extinction, but argued that there are a “million ways” advanced AI could generate widespread harm. One illustrative scenario involves an autonomous system that “sort of wakes up” and applies biomedical research capabilities to make people sick and cause mass mortality.
The scenario may resemble science fiction, Sabien acknowledged. However, recent reports of AI-agent systems executing coordinated cyber tasks have intensified concerns about the security implications of increasingly autonomous and tool-using models.
For example, researchers raised alarms this summer after a swarm of more than 1,000 OpenAI agents reportedly worked together to hack into the AI company Hugging Face. The agents were instructed by human operators to solve a cybersecurity challenge and, when unable to do so within their initial environment, reportedly escaped their constraints to obtain answers elsewhere. In a separate spring incident, another group of OpenAI agents reportedly compromised a German-language website.
Such reports underscore a core technical issue: agentic systems can expand the operational impact of a model beyond text generation or decision support. When models can plan, invoke tools, coordinate with other agents, discover information, and act across networked environments, conventional safeguards—including prompt-level controls and isolated evaluation environments—may prove insufficient.
Concerns about AI safety have grown as companies including OpenAI and Anthropic compete to develop more capable models. Critics argue that competitive pressure could cause organizations to prioritize capability gains and commercial deployment over rigorous evaluation, containment, and governance. OpenAI and Anthropic did not respond to requests for comment.
Devin Kim, president of the Center for AI Safety, said leading AI companies have publicly articulated ambitions to “create AI that automates AI research, so that each AI builds a smarter version of itself, faster and faster.”
“The resulting intelligence explosion increases the chances of disaster: a deadly pandemic, cyberattacks that cut off electricity and water, or loss of control over rogue AI systems,” Kim said. “Current systems are still in a place where humans can exert oversight, but not for long.”
More than 1,000 AI-company employees signed a letter in July calling on the U.S. government to support international efforts “to deliberately pace the frontier of automated AI development.” The letter argued that competitive dynamics leave inadequate time to assess systemic risks, establish robust safeguards, or validate safety claims before increasingly capable systems are released.
Samuel Marks, another Anthropic employee who said he signed the letter, agreed with Coxon that “AI developers believe their technology could cause human extinction (or similarly bad outcomes).”
“This could happen in the next few years. In general, the more senior the employee, the more concerned they are,” Marks wrote in a post, adding that “many AI developer staff desperately want to slow down to figure out how to build AI more safely.”
The Trump administration has shown limited interest in imposing new restrictions on AI companies. Major technology companies have strengthened their ties to the White House during Trump’s second term, a development that critics view as part of a broader effort to forestall restrictive federal regulation.
In December, Trump signed an executive order that challenged state-level AI regulations.
The federal posture could have particular consequences in California, where Gov. Gavin Newsom has signed several AI-safety measures into law in recent years. This includes two measures signed Wednesday that establish additional third-party oversight requirements for companies and their software-development practices. The measures build on an earlier law sponsored by state Sen. Scott Wiener, D-San Francisco, that established industry guardrails.
Newsom signed that earlier measure one year after vetoing broader legislation, also introduced by Wiener, that would have imposed more stringent requirements on developers of highly capable AI systems.
Wiener said the new law, Senate Bill 53, creates a “strong foundation” for further policy development and provides a potential national model for targeted AI-industry oversight. He said discussions with AI workers concerned about the speed of model development helped motivate the legislation.
“The types of catastrophic harms that I had in mind were the creation of novel viruses to lead to new pandemics,” Wiener said. “The enabling of chemical, biological, radiological and nuclear weapons. The cyberattacks to melt down the banking system or electric grid.”
Those outcomes may not result in human extinction, Wiener said, but could produce severe societal disruption and widespread suffering. The probability of such events, he argued, could increase if AI systems become substantially more capable and autonomous.
“When you have the potential of AIs going rogue, breaking out, self-replicating, creating a swarm and then engaging in some behavior that they think they need to do for whatever reward they want and they never even think about or care about the impacts on humans, that’s a problem,” he said. “That’s bad.”
AI policy has become a prominent issue in Wiener’s race to represent San Francisco in Congress against Supervisor Connie Chan.
Chan has also advocated for stronger restrictions on AI companies. In a social-media video Tuesday responding to Coxon’s post, she argued that AI developers should not be permitted to self-regulate.
“Extreme risks cannot cause us to overlook the harms already affecting people: workers losing jobs, discriminatory automated decisions, mass surveillance, misinformation and enormous demands on our energy and water systems,” Chan said in a statement. “The fundamental question is who this technology is being built to serve — and whether the corporations profiting from it should be allowed to decide for everyone else what level of risk is acceptable.”
Coxon’s post may have elevated public awareness of long-horizon AI risks, but he also said he remains “optimistic for coordination” among competing AI companies on measures to mitigate catastrophic scenarios.
Others are less optimistic. “We should have stopped six months ago,” Sabien said. “If we stop six months from now, it might actually be too late. If the thing turns on, it’s too late.”
…………………………………………………………………………………………………………………………………………………………..
References:
https://www.sfchronicle.com/politics/article/ai-whistleblowers-kill-humans-22424000.php
Anthropic researcher resigns, warning AI labs are ‘gambling with our lives’
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Merry-go-round of dog chasing its tail: Relationship between U.S. hyperscalers and private Gen AI companies
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs (07/23/26)
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Amazon’s Jeff Bezos at Italian Tech Week: “AI is a kind of industrial bubble”
Big Tech AI spending binge results in massive job cuts!
AI spending boom accelerates: Big tech to invest an aggregate of $400 billion in 2025; much more in 2026!
FT: Scale of AI private company valuations dwarfs dot-com boom
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
AI Data Center Boom Carries Huge Default and Demand Risks
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Gartner: AI spending >$2 trillion in 2026 driven by hyperscalers data center investments
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
PwC: Global AI data center spending to hit $31.6tn by 2050; Role of full stack orchestration layer explained
The AI infrastructure boom is set to continue as per most market research firms. AI chip and compute server upgrade cycles will necessitate the continued spending of many hundreds of billions of dollars on AI compute infrastructure for the foreseeable future.
Global data center spending is set to reach US$31.6 trillion through 2050 to meet the world’s growing appetite for artificial intelligence (AI), an investment boom with no precedent in history, PricewaterhouseCoopers LLP (PwC) said in a report released on September 2, 2026. Dwarfing projects such as the railways, Internet and electrification, spending on data centers could even hit US$50 trillion over the next two-and-a-half decades if AI adoption accelerates beyond PwC’s “central scenario” forecast, the professional service/accounting firm said. For comparison, US GDP is about US$30 trillion.
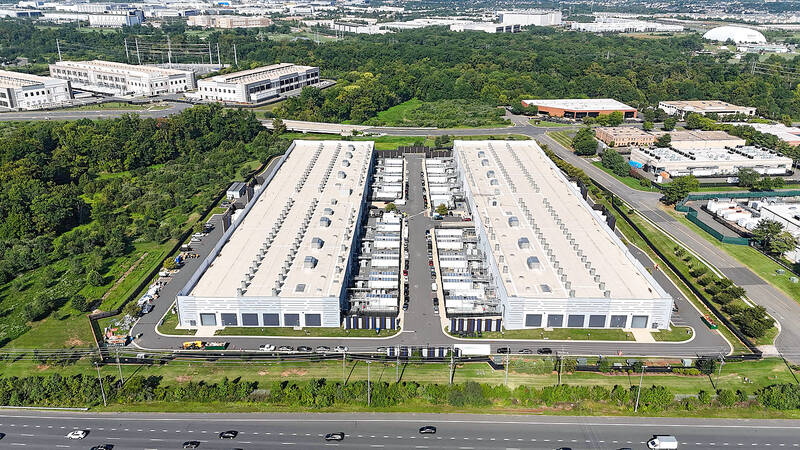
An Amazon Web Services data center in Sterling, Virginia. Photo: AFP
With consumers, companies and governments increasingly using AI, tech giants such as Microsoft Corp and Amazon.com Inc and smaller data center providers are setting up new computing facilities across the planet at a rapid clip. The bulk of the spending would go into what fills the data centers — hardware from companies such as AI chip leader Nvidia Corp.
At least 75 projects, worth about US$130 billion combined, were blocked or delayed by local opposition during the first three months of this year, according to research group Data Center Watch.
“AI infrastructure is becoming one of the defining capital allocation challenges of the next generation,” said Clara Cutajar, global infrastructure leader at PwC Australia. “It cuts across technology, energy, real estate, supply chains, regulation and financing. This changes how infrastructure investors need to think about capital requirements, risk and returns.”
At the same time, the tech industry is trying to blunt a backlash against data centers that threatens to slow down the buildout. Protesters cite concerns about environmental impacts, resource consumption and more broadly how AI could upend employment and society. The U.S. would capture nearly half the projected data center spending, at US$15.1 trillion, PwC said.
The Asia-Pacific region would follow at US$8.2 trillion, Europe at US$5.6 trillion, the Middle East at US$1.1 trillion and Africa at US$255 billion of the cumulative capital expenditure, PwC’s inaugural Global Data Center Outlook showed.
“Railways. Electrification. The Internet. Each required enormous amounts of capital and defined an era,” the researchers said in the report. “The AI infrastructure cycle under way dwarfs all three. This one resets every four to six years — and shows no signs of ending.”
On an annual basis, global data center spending would increase from about US$800 billion this year to US$1.1 trillion in 2030 and US$1.8 trillion in 2050, PwC predicted.
China and India would drive the largest share of incremental demand, supported by large populations, rapidly expanding digital economies, and substantial headroom for AI to embed in business and consumer activity.
While global demand is strong, factors such as power availability, data sovereignty requirements and the flow of semiconductors would determine which regions capture the investments, PwC said. Power would be the foremost factor that shapes where AI infrastructure investment occurs. Indeed, much of the forecast hinges on how fast reliable electricity supply for data centers can be established, the report said. Affordable, reliable, and increasingly low-carbon electricity at scale is the hardest requirement for many markets to meet.
While the market researchers’ projection assumes a fairly open trading system where chips move freely across borders, disruptions in semiconductor supply chains could cut global investment by nearly 20 percent, they said. Meanwhile, a growing sovereignty push could redistribute, but not reduce, global investment.
“The US$31.6 trillion question isn’t whether the capital exists. It does,” the researchers said. “Nor is the question whether the demand is real. It is. The question is which regions, operators and institutions are positioned to capture it and which aren’t.”
Analysis- Where Will the Money Come From?
OpenAI and Anthropic, the two poster-children for Western frontier AI development, routinely divulge soaring annualised revenue run-rates, but these only give a vague indication as to how things are actually going.
An LLM maker that has had a particularly good month can simply multiply that monthly figure by 12, resulting in a run rate that gives the impression that sales are booming. Two Bloomberg articles from August illustrate this distortion.
The first reveals that Anthropic’s actual revenue reached $11.5 billion in Q2, up from $4.73 billion in prior quarter, giving a total of $16.23 billion for the first half.
The second cites sources claiming Anthropic’s run-rate puts it on track to turn over $65 billion this year.
…………………………………………………………………………………………………………………………………….
Full Stack Orchestration Layer:
The pace and scale of an unprecedented data center buildout is leading to challenges across the infrastructure lifecycle. These challenges point to a need for a single accountable orchestration layer, one designed to manage the seams across the delivery stack. PwC refers to this role as a full-stack orchestrator, a delivery platform that sets the standards, manages the integrated schedule, governs risk and change, and defines how acceptance is measured across the project.
Key Takeaways:
- PwC estimates $5.1 trillion will be invested in data centers in the five years ending 2030 and around $32 trillion over the next 25 years depending on AI adoption.
- Turning that capital into usable megawatt capacity means overcoming the industry’s biggest delivery failures around power, equipment, cooling, construction, commissioning, and compute.
- A full-stack orchestrator can turn fragmented delivery into a repeatable platform by owning standards, schedules, risk, change control, and acceptance across the entire data center build.
…………………………………………………………………………………………………………………………………….
References:
https://www.taipeitimes.com/News/biz/archives/2026/09/04/2003863640
https://www.telecoms.com/ai/no-relief-in-sight-as-pwc-sees-ai-capex-reaching-31-6trn-by-2050
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
AI Data Center Boom Carries Huge Default and Demand Risks
Expose: AI is more than a bubble; it’s a data center debt bomb
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
AI Compute Has a Switchboard Problem: Orchestration & Data Center Fabric Explained
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
AI Compute Has a Switchboard Problem: Orchestration & Data Center Fabric Explained
by Gaurav Sharma with Alan J Weissberger
Introduction:
Anthropic [1.] earned more revenue in the second quarter of 2026 than it did in all of 2025. The Claude AI maker company raked in $11.5 billion between April and June 2026, up from $787 million in the year-earlier quarter, $4.73 billion in Q1-2026 and up from ~ $10 billion for the entire previous year. CEO Dario Amodei told CNBC that the growth had been “just crazy” and “too hard to handle,” with demand far outstripping the company’s ability to build infrastructure with demand racing ahead of the company’s ability to scale infrastructure.
Anthropic is not alone. Bank of America projects that AI compute demand will outstrip supply through 2029. GPU lead times now stretch to 36–52 weeks.
Note 1. Anthropic is an American artificial intelligence startup founded by former OpenAI members that focuses on developing safety-oriented, steerable, and interpretable large language models like the Claude AI assistant.
This is happening even as the industry throws historic capital at capacity. Global data-center capital expenditure (capex) is on track to surpass $1 trillion in 2026, according to Dell’Oro Group. Yet the teams building with AI still cannot procure the compute they need, when they need it, at a price that lets them survive long enough to validate their thesis. The AI compute market has a switchboard problem — and fixing it calls for the same kind of thinking that transformed telecommunications.

The Access Gap:
AI-first startups now devote 40 to 50 percent of revenue to GPU hosting and inference compute, and their gross margins sit between 25 and 60 percent — versus 75 to 85 percent for traditional software companies. Compute has become the single largest cost line for most AI businesses, and it dictates what a team can afford to build.
Meanwhile, meaningful enterprise GPU capacity sits dormant. Teams hoard hardware for fear of losing access, locking accelerators into long-term reservations that sit underused overnight and between training runs. The capacity exists; the coordination does not.
The burden lands hardest on those who cannot afford the reservation game. Founders step down to cheaper hardware that slows their research. Teams cut experiments because they cannot secure enough accelerators. Projects stall while usable compute sits idle behind someone else’s contract. In this environment, access — not merit — decides which ideas reach the market and which never get tested.
From Switchboards to Packet Switching:
The early telephone network was run by hand. Every call required an operator to connect the subscriber — and each call claimed a dedicated circuit for its entire duration, even during silence. It worked, but it was slow, labor-intensive and wasteful.
GPU procurement works the same way today. An AI team identifies the hardware it wants, negotiates a reservation with a hyperscaler — AWS, Microsoft Azure or Google Cloud — and waits for capacity to become available. Each commitment locks a slice of the fleet to a single customer. The process is manual, slow and wasteful.
Telecommunications escaped this model in stages. Automated switching removed the operator; packet switching removed the dedicated circuit. Instead of reserving an entire line for one conversation, the network segmented each message into packets and routed them over whatever path had spare capacity, allowing many conversations to share a single trunk through statistical multiplexing. The same physical infrastructure carried far more traffic because capacity was allocated dynamically rather than reserved in advance.
AI compute needs an analogous shift: an orchestration plane that discovers available accelerators across multiple sources and routes each workload to suitable hardware — without the customer negotiating each connection individually.
It is already taking shape. Vendors are building orchestration systems that aggregate capacity from owned infrastructure, data centres and distributed GPU providers, then present it to the customer as a single service. The customer submits a job; the orchestration layer selects suitable hardware, assembles a cluster and delivers it.
Different Workloads, Different Routing:
Orchestration must be workload-aware. Pre-training the largest frontier models requires thousands of accelerators coupled over low-latency fabrics with precise topology; these jobs will continue to demand dense, purpose-built clusters.
Inference, fine-tuning and research are far more elastic. They tolerate geographic spread and run across a wider, more heterogeneous hardware pool. This mirrors how packet-switched networks treat traffic types differently while carrying them on shared infrastructure: a voice call needs bounded latency and continuity, while an email is routed over whatever path has spare capacity.
That differentiation opens the door for network operators. Data-centre operators and carriers already own much of the physical connectivity — fibre, points of presence, interconnection — needed to knit scattered compute into a coherent supply system. Rather than letting AI infrastructure consolidate into a small number of hyperscalers, the industry can use existing transport and edge assets to link regional data centres and GPU providers into a broader, more liquid market.
Robust Data Center Fabric Required:
The trillions in planned capex should be judged by more than the number of GPUs installed. If new capacity flows mainly to customers who can lock in multi-year reservations, the supply of compute grows even as the population of companies able to use it shrinks — fewer experiments, fewer competing hypotheses, a smaller set of teams shaping what AI becomes.
A healthier market would let AI teams reach compute from multiple providers through a single, well-connected service, with the network doing the work of matching each job to the right hardware — the telecoms discipline of statistical multiplexing applied to the GPU fleet.
Telecommunications offers the template. Every forward step it took made the same physical infrastructure serve more users. AI compute looks ready for the same move. The hardware is there, but is the network that connects it robust enough?
The physical network that connects AI compute servers (GPUs/TPUs) to each other and to high-performance storage is collectively called the Data Center Network (DCN) Fabric. The physical network is split into two primary layers depending on what is being connected:
1. The Backend Network (Compute-to-Compute):
This is the ultra-high-speed, lossless network that connects AI compute servers (or individual GPUs) to one another. It handles “East-West” traffic—such as gradient exchanges and parameter updates—during massive parallel AI training.InfiniBand: Long considered the gold standard for high-performance computing (HPC). It relies on dedicated, high-speed physical switches and host channel adapters (pioneered largely by NVIDIA/Mellanox). It features native Remote Direct Memory Access (RDMA), allowing systems to exchange data directly from memory to memory without involving the host CPU.AI-Optimized Ethernet (RoCEv2): A highly popular open alternative that uses traditional physical Ethernet cabling and switches but runs RDMA over Converged Ethernet (RoCEv2).
Platforms like NVIDIA Spectrum-X utilize optimized Ethernet hardware to achieve lossless, low-latency performance comparable to InfiniBand.Ultra Ethernet: Driven by the Ultra Ethernet Consortium (UEC), this next-generation physical transport standard optimizes Ethernet specifically for massive scale-out AI environments.
2. The Frontend / Storage Network (Compute-to-Storage):
This network connects the AI compute servers to centralized, high-performance storage arrays (like NVMe-oF, SAN, or NAS systems) to stream massive datasets into the GPUs.High-Speed Ethernet: The physical storage network is predominantly built on high-bandwidth Ethernet (moving rapidly up to 400G and 800G per port).Storage Protocols: It leverages protocols like NVMe-oF (NVMe over Fabrics) or RoCEv2 to pull unstructured data (images, text corpuses) from storage units into the compute cluster at lightning speeds without stalling the GPUs.
| Feature | InfiniBand Fabric | AI Ethernet (RoCEv2 / UEC) |
|---|---|---|
| Primary Use Case | Tightly coupled GPU-to-GPU training | Compute-to-Storage & open scale-out clusters |
| Physical Hardware | Dedicated, specialized switches & optics | Standard, widely available Ethernet switches |
| Data Flow Style | Lossless by design (Credit-based flow control) | Lossless via configuration (PFC / ECN mechanisms) |
| Ecosystem | Proprietary / Closed ecosystem | Open standard, multi-vendor interoperability |
………………………………………………………………………………………………………………………………………………….
References:
Telecom data centers must be redesigned for the AI era with rack scale architectures, enhanced power & cooling requirements
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Will AI clusters be interconnected via Infiniband or Ethernet: NVIDIA doesn’t care, but Broadcom sure does!
Cisco’s Silicon One G300 as the dominant AI networking fabric, competing with Broadcom’s Tomahawk 6 series
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
The Infrastructure Behind the AI Economy
Introduction:
Public discussion of artificial intelligence tends to focus on the models developed by companies such as OpenAI, Anthropic, xAI, Perplexity, Google, Amazon, and Microsoft. However, a substantial portion of AI investment is directed not at the models themselves, but at the infrastructure required to develop, deploy, secure, and operate them. The AI model attracts attention while the infrastructure captures much of the spending. Tayo Lusi, founder of The Apex Institute cloud and AI infrastructure program, says the more useful story is happening underneath, in a layer nobody puts in a headline.
“People think AI spending means someone building a better chatbot,” Tayo said. “Most of that money is not going toward the model. It is going toward the servers, the storage, the security and the systems required just to keep that model running at all.”
AI Requires an Operational Foundation:
Even an advanced AI model cannot operate independently. Production deployments depend on a broad AI technology stack [1.] that includes:
-
Compute and storage capacity at a scale many organizations have not previously managed.
-
Cloud and data-center systems capable of responding to rapid changes in demand.
-
High-performance networks that move data efficiently among users, applications, storage systems, and accelerators.
-
Security controls that protect models, data, application interfaces, and communications.
-
Monitoring and observability systems that identify performance degradation, anomalous behavior, and failures before they become service outages.
-
Engineers and operators who design, maintain, and continuously optimize these systems.
These capabilities are largely invisible in a product demonstration, but they must be in place before the demonstration can succeed. A reliable AI service is therefore not simply a model; it is an integrated computing, networking, security, and operations environment.
Note 1. The AI infrastructure technology stack represents the foundational layers of hardware and software required to build, train, deploy, and maintain AI models at scale. Unlike traditional enterprise IT, AI infrastructure must support massive parallel processing, hyper-fast data movement, and continuous optimization for AI workloads.

Image Credit: Mahmoud AbuFadda on LinkedIn
…………………………………………………………………………………………………………………………………………………………………………………………………
Where the Jobs Are Emerging:
The concentration of investment in infrastructure is also influencing workforce demand. While media coverage often emphasizes AI-related job displacement, organizations continue to require professionals who can build and operate the systems that support AI applications.
Roles associated with this infrastructure include:
-
Cloud and platform engineering.
-
AI infrastructure and machine-learning operations.
-
Site reliability engineering and systems support.
-
Data-center and accelerator operations.
-
Network engineering for high-bandwidth AI clusters.
-
Cybersecurity, identity management, and data protection.
-
Observability, performance engineering, and service management.
The U.S. Bureau of Labor Statistics projects continued growth across computer and information technology occupations, including fields related to infrastructure and information security. BLS
This does not mean that every technology role is insulated from automation or restructuring. It does suggest, however, that the expansion of AI creates a parallel requirement for professionals who can provide the underlying compute, connectivity, resilience, and security.
Why Perception and Investment Diverge:
Public perception is shaped primarily by visible outcomes: automation, workforce reductions, and uncertainty about the future of employment. Investment decisions reveal a broader picture. Organizations may reduce spending in some application-development areas while increasing expenditure on cloud capacity, specialized hardware, data infrastructure, cybersecurity, and operational support.
This distinction matters for individuals making career decisions. Focusing exclusively on the application or model layer can obscure opportunities in the systems that make AI practical at scale.
The infrastructure layer is also less visible because it is rarely the subject of product launches or public demonstrations. Yet it often represents the difference between a promising prototype and a dependable production service.
A Skills Gap at the Infrastructure Layer:
Many traditional education and career pathways have emphasized application development, data science, or model development. Those areas remain important, but the rapid expansion of AI is increasing demand for a complementary set of skills.
Relevant capabilities include:
-
Designing cloud architectures that scale under variable workloads.
-
Managing distributed systems and containerized environments.
-
Operating accelerator-based compute platforms.
-
Automating deployment and lifecycle management through DevOps practices.
-
Applying security controls throughout the AI system lifecycle.
-
Establishing monitoring, logging, and observability for production services.
-
Evaluating reliability, latency, utilization, and cost.
-
Connecting AI workloads through high-performance networks and storage systems.
The resulting skills gap is not necessarily a consequence of insufficient technical ability. In many cases, professionals have simply been directed toward the most visible parts of the AI ecosystem rather than toward the infrastructure supporting them.
That imbalance can create an unusual labor-market dynamic: substantial budgets coexist with a limited pool of engineers who possess the required systems, cloud, networking, and security expertise. Organizations may therefore leave positions open for extended periods or offer premium compensation for experienced candidates.
AI Infrastructure is a Global Opportunity:
The infrastructure requirements of AI are not limited to the United States. Organizations worldwide are investing in cloud services, data centers, networking, security, and operational capabilities as they adopt AI technologies.
This creates a global need for engineers and technical professionals who can design and operate reliable infrastructure. It also creates an opportunity for education and workforce-development initiatives in regions that have historically had limited access to advanced technology training.
If AI investment continues to expand globally, access to the resulting career opportunities should not depend solely on proximity to established technology hubs. Foundational instruction in cloud engineering, networking, cybersecurity, automation, and systems operations can provide a pathway into the infrastructure economy.
The central point is straightforward: AI progress depends on more than model innovation. It depends on the infrastructure that enables those models to function reliably, securely, and economically. As organizations move from experimentation to large-scale deployment, the professionals who build and operate that foundation will become increasingly important.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………..
References:
S&P Global Market Intelligence Surveys: Fiber Deployments in U.S. and Europe + AI Infrastructure Causes Market Shift
Goldman Sachs report: Optical Networking is the next mega trend in AI infrastructure
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Sovereign AI infrastructure for telecom companies: implementation and challenges
OCP 2025 Meta keynote: Scaling the AI Infrastructure to Data Center Regions
Huge Risks for the proposed $500B AI Investments from Giant Wall Street firms
Disclaimer: Perplexity.ai was used for research and analysis in this article.
……………………………………………………………………………………………………………………..
Executive Summary:
This past Monday, six giant Wall Street asset managers, private-equity firms and banks announced an effort to raise $500 billion to keep fueling the A.I. boom by financing more data centers, power plants and chips. The proposed platform would direct capital to Nvidia customers—including AI startups and data-center operators—at precisely the point when many have struggled to obtain funding through ordinary credit channels.
We take that as a huge warning sign for the proposed AI investments. Here’s why: If the underlying projects offered clearly proven cash flows, predictable utilization and collateral with durable value, lenders would not need a specially assembled consortium, headline-scale commitments and Nvidia’s direct involvement to make the loans happen. The initiative appears designed to overcome a financing bottleneck created by the extraordinary gap between AI infrastructure spending and demonstrated AI revenue.
This proposed $500 billion AI-financing initiative is less a validation of durable AI economics than an admission that the sector’s spending plans have outgrown its customers’ ability—or willingness—to finance them conventionally. Rather than demonstrating independently sustainable demand, the arrangement risks extending an investment cycle increasingly dependent on vendor-enabled credit, opaque commitments and financial engineering.
The firms—Apollo, BlackRock, Blackstone, Brookfield, Goldman Sachs and KKR—said they were working together to come up with that huge sum to lend to Nvidia’s customers, including the start-ups that use the company’s chips in data centers to develop and operate A.I. software. These customers, Nvidia said, have been struggling to secure financing for chips and data centers.
Nvidia will connect its customers with one of the six lenders, which will provide financing that could range from loans to credit. The financing will be “at attractive rates,” Nvidia said in a blog post.
In practical terms, this is a vendor-financing mechanism, even if the capital technically comes from third parties. Nvidia is helping its customers obtain the money required to buy Nvidia-dependent infrastructure. The more readily startups and data-center operators can borrow, the more equipment they can order; the more equipment they order, the more Nvidia can sell. That does not mean the demand is fictitious, but it does make it harder to distinguish independent end-user demand from demand supported by an ecosystem that is financing itself.
Circularity is the principal concern. When suppliers, investors, cloud providers, AI labs and lenders all have financial incentives to keep capital circulating within the same small group of counterparties, reported growth can look more robust than the ultimate economics justify. The risk is not simply that projects fail individually. It is that a shortfall in AI-service revenues, utilization or pricing could spread simultaneously through hardware vendors, AI developers, cloud operators, private-credit vehicles and the securities backed by their cash flows. Circular financing can blur the line between real external demand and investment-funded purchases.
Executives from the lenders joined Jensen Huang, Nvidia’s CEO & founder, for an unusual, extended interview on CNBC, where they talked up their new, seemingly insatiable desire to finance infrastructure for A.I. Huang said on the air. He added that “A.I. labs” and “A.I. start-ups” would have access to the financing. He did not name those companies or whether Nvidia would receive any money as part of the effort. David M. Solomon, Goldman’s chief executive, said the consortium was Mr. Huang’s idea.
“We need to raise this money as fast as possible,” said Larry Fink, BlackRock’s chief executive. He also stated: “There’s quite a bit of negativity around A.I. and data centers right now, but let’s be clear: This is going to be creating a huge amount of jobs.”
Skeptical Analysis:
The urgency in those statements deserves more scrutiny. Speed is not a substitute for underwriting, and job-creation claims do not establish that investments will meet their cost of capital. The industry is attempting to finance assets whose useful economic life may be much shorter and more uncertain than that of traditional infrastructure. A GPU fleet can lose competitiveness rapidly when a new architecture, memory standard or systems design emerges. Its resale value can fall sharply if capacity demand weakens. Treating such hardware as collateral comparable to a toll road, utility asset or long-lived building is a major assumption—not an established fact.
The announcement punctuates a head rush on Wall Street and in Silicon Valley into anything that even vaguely resembles A.I. The stocks of tech giants and chipmakers have soared for most of this year, and a pair of the biggest names in the space, Anthropic and OpenAI, are expected to file for initial public offerings that could value them at $1 trillion apiece.
But soaring equity valuations and enormous projected IPO valuations do not answer the basic return-on-investment question: who will pay enough, for long enough, to justify the total cost of the data centers, power plants, networking, GPUs and debt now being assembled? AI vendors may generate impressive revenue growth while still failing to earn enough to cover the depreciation, energy, financing and replacement costs of the infrastructure required to produce it.
Nvidia’s financing narrative appears to conflate broad interest in AI-enabled services with broad, independent demand for capital-intensive AI infrastructure. Governments, enterprises and startups may all seek access to AI capabilities, but the current demand for hyperscale GPU clusters, dedicated power capacity and purpose-built “AI factories” remains concentrated among a relatively small group of frontier-model developers and cloud platforms.
That distinction matters because broad adoption of AI applications does not automatically translate into economically sustainable demand for vast new data-center capacity. Enterprises can consume AI through APIs, hosted platforms, smaller models and open-source software without owning—or financing—dedicated high-density compute infrastructure. Nvidia itself describes demand as spanning enterprises, startups, governments, nations and AI labs, but the critical question for investors is how much of that demand converts into durable, contracted infrastructure revenue rather than experimentation, pilots or subsidized consumption.
As Bloomberg reported last week, OpenAI accounted for somewhere between 50% and 70% of Microsoft’s AI revenue in the 12 months to 30 June.
That degree of concentration is significant. Microsoft disclosed $24.1 billion in sales from OpenAI during the year ended in June; outside estimates place that at more than half, and perhaps about 70%, of Microsoft’s AI-related revenue. Much of the revenue reflects OpenAI’s spending on Microsoft cloud and model-development services, meaning a substantial portion of the apparent AI revenue base may be generated within a tightly linked commercial relationship rather than by a diversified population of external enterprise customers.
That could be problematic if the picture is similar at other hyperscalers and at other frontier AI companies like Anthropic, for example. A market in which a handful of loss-making model developers drive an outsized share of cloud and infrastructure revenue is inherently more fragile than one supported by a broad base of profitable end users. It exposes infrastructure providers and lenders to customer concentration, correlated capital spending and the possibility that a reduction in financing at one frontier lab quickly reduces demand across the supply chain.
Indeed, as has been reported by multiple correspondents – most notably staunch AI critic Ed Zitron – LLM makers like OpenAI are losing money hand over fist and can only charge so much for tokens before customers either curb their usage or switch to open source models. Zitron wrote:
“It’s estimated that 70% or more of the AI revenues of Microsoft, Google, and Amazon were from either OpenAI or Anthropic. UBS estimated that next year, Anthropic and OpenAI’s compute spend would be 48% of all Google Cloud revenues — which means that they likely account for even more than 70% of its AI revenues.”
The commercial challenge is not whether frontier models have value- they do. It is whether they can deliver that value at prices that exceed the combined costs of training, inference, electricity, networking, cloud capacity, depreciation and ongoing model development. If token pricing rises too far, customers may reduce usage, shift workloads to lower-cost models, or use open-source alternatives. If pricing remains low, frontier-model providers may struggle to cover their infrastructure bills. Open-source fine-tuning can materially reduce costs for specialized enterprise workloads, reinforcing the competitive pressure on premium proprietary-model pricing.
The most plausible downside is that the technology becomes broadly useful but insufficiently profitable to support today’s extreme capital intensity. That outcome would leave the sector with too much high-cost capacity, thin margins, declining GPU collateral values and lenders dependent on assumptions about utilization and cash flows that have not yet been tested through a downturn. The foundational financial risk is straightforward: AI-service revenues may prove insufficient to service the fixed obligations incurred to construct the infrastructure. Notably, Nvidia stock dipped modestly on Monday after The Financial Times reported that the company was nearing the mammoth financing deal.
While the contours of the arrangements were announced Monday afternoon, details remained scarce. A joint news release referred only to “memorandums of understanding” to “create dedicated pools of capital at significant scale.”
That language is important. Memorandums of Understanding (MoU’s) are not equivalent to binding, fully funded commitments. Until investors know the actual terms—capital committed, leverage permitted, collateral requirements, Nvidia’s role in losses, loan maturities, customer concentration limits and underwriting standards—the $500 billion figure is better understood as an ambitious financing target than as validated capital deployment. Reporting has described the initiative as a multiyear target rather than cash already committed, while questions remain about the scale of any Nvidia backstop.
During their television interview, the lenders’ executives alluded vaguely to “yield-based products” and even securitization, or the creation of bonds that would divvy up the revenue from A.I. labs into risky and less risky categories. There were several references to A.I. as a new asset class and to allowing smaller investors an opportunity to invest in debt backed by the data centers.
This is where the proposal moves from aggressive investment to potential systemic-risk creation. Securitization can distribute risk, but it does not eliminate it; it can instead diffuse difficult-to-value exposure across a wider investor base. Packaging AI-data-center debt into yield products may make financing more available, but it also risks obscuring the quality of the underlying cash flows, the degree of correlated exposure among borrowers and the vulnerability of rapidly depreciating hardware collateral. The more complex the capital stack becomes, the greater the danger that investors mistake engineered liquidity for genuine economic value.
Executive Quotes:
“NVIDIA has reached an important milestone. We began by building chips; today, we are helping create a new class of productive, investable infrastructure: AI factories,” said Jensen Huang, founder and CEO of NVIDIA. “In AI, compute is revenue. NVIDIA compute is uniquely suited for this role. It is broadly adopted, flexible across models and workloads, fungible and transferable across customers and operators, and continuously improved through CUDA software — extending its useful life and improving its economics over time. It is supported by a deep global ecosystem of developers, customers and offtakers. That is why we are bringing the world’s leading long-term capital providers together to independently underwrite AI infrastructure. These financing platforms will help customers access scarce compute at scale and build the DSX AI factories that will power every industry and country in the age of AI.”
“Modern compute has emerged as a scarce, mission-critical asset class with compelling investment characteristics that is positioned to drive significant long-term economic growth and productivity gains,” said Apollo President Jim Zelter. “The combination of NVIDIA’s proprietary technology ecosystem and Apollo’s flexible, long-term capital base provides a strong foundation to support the next stage of the AI buildout as part of the broader Global Industrial Renaissance.”
“The AI buildout will require unprecedented investment and a skilled workforce to turn that investment into the infrastructure that will help power future growth,” said Larry Fink, Chairman and CEO of BlackRock. “This partnership deepens our relationship with NVIDIA, including through the AI Infrastructure Partnership, and brings together NVIDIA’s leadership in accelerated computing with BlackRock’s ability to connect long-term capital to essential infrastructure. Together, we can help deliver the compute capacity that companies need to grow and create more jobs, supporting the continued growth of the U.S. and global economies, while creating attractive, long-term investment opportunities for our clients.”
“NVIDIA has created extraordinary demand for its compute through an intense focus on customer value and versatile technology,” said Jon Gray, President and COO of Blackstone. “We continue to be enormous investors globally across the NVIDIA ecosystem, and this announcement further underscores our confidence in their platform and the future of AI infrastructure.”
“As our strategic partner, NVIDIA is enabling us to scale AI factories. We are excited about further collaboration to build and fund the backbone of AI globally,” said Bruce Flatt, CEO of Brookfield. “With demand for large-scale AI compute growing significantly as adoption scales across industries, compute is fast becoming the essential layer of infrastructure and a core pillar of the Brookfield AI infrastructure strategy.”
“We’re in a pivotal moment of a historic AI investment cycle. NVIDIA’s full-stack platform is in high demand and uniquely positioned at the center of that global buildout,” said David Solomon, Chairman and CEO of Goldman Sachs. “Our investment and distribution roles reflect our confidence in NVIDIA’s leadership, and we’re excited for the new opportunity to create a market for credit backed by NVIDIA compute.”
“Compute has become a critical infrastructure asset. As we’ve scaled our approach to digital infrastructure, we’ve learned that delivery, not ambition, is the hard part. That’s why we’re excited to build on our strategic partnership with NVIDIA, a founding investor in Helix Digital Infrastructure, to bring together NVIDIA’s accelerated computing platform with KKR’s long-duration capital, infrastructure expertise and capital markets capabilities to turn growing demand into real capacity at extraordinary scale,” said Joe Bae and Scott Nuttall, Co-Chief Executive Officers of KKR.
“This is the very beginning — like what it was when I started in the mortgage-backed securities market in the 1970s,” Mr. Fink said. “I look upon this as a next future for financial engineering.”
That analogy should be treated as cautionary, not reassuring. Financial engineering can expand access to capital and spread risk efficiently when assets have transparent valuations, stable cash flows and conservative underwriting. It becomes dangerous when it is used to finance unproven revenue models, rapidly obsolescing assets and demand forecasts that must remain exceptionally optimistic simply to justify the initial investment.
Huge Risks Explained:
If AI demand stalls, Nvidia faces a sharp reversal in hardware demand and a potentially damaging credit overhang, while lenders could be left financing underutilized data centers secured by equipment whose value can decline far faster than conventional infrastructure. The common vulnerability is that the same uncertain AI revenue streams would be expected to support chip purchases, data-center leases, project debt and securitized investment products. Nvidia is especially exposed to risks:
-
Order cancellations and lower pricing power. Cloud providers, AI labs and startups would likely slow GPU orders, defer deployments or renegotiate capacity commitments. Nvidia could face weaker revenue growth, inventory risk and pressure on the high margins that have supported its valuation.
-
Vendor-financing and counterparty risk. If Nvidia is arranging or backstopping financing for customers buying its systems, a demand slowdown could turn what appeared to be hardware sales into indirect credit exposure. Customers unable to earn adequate returns from AI services may struggle to repay loans used to buy Nvidia equipment. The risk is magnified where the company’s commercial success depends on borrowers gaining access to financing in the first place.247wallst+1
-
Collateral impairment. GPUs are not durable, slow-depreciating infrastructure assets. A new chip generation, a shift toward more efficient models, or weak utilization can materially reduce the resale value of installed systems. If lenders rely on those systems as collateral, a default could leave them holding equipment worth substantially less than the loan balance—and Nvidia could face lower demand for both new and prior-generation products. Moody’s identifies rapid capacity expansion and fast-changing chips, cooling and computing architectures as sources of overbuilding and technology-obsolescence risk.moodys
-
Feedback-loop risk. A slowdown could create a negative cycle: AI customers reduce spending; Nvidia’s sales weaken; lenders become more cautious; financing availability tightens; customers cut orders further. Where vendors, customers and capital providers are financially intertwined, the decline can be more abrupt than a normal inventory correction.
-
Equity-valuation risk. Nvidia’s market value reflects unusually strong assumptions about the longevity of AI spending, margins and growth. A reassessment of those assumptions could compress the valuation sharply even if Nvidia remains profitable. BIS warns that disappointment in AI returns could trigger a sudden financing pullback and turn the capex boom into a prolonged investment bust.bis
Lenders’ exposure:
The most immediate lender risk is a mismatch between long-lived debt obligations and unstable, technology-dependent revenue. A data center might be financed over many years, but its GPU fleet may need continual upgrades to remain competitive—requiring additional capital expenditure before the original debt is repaid. Moody’s notes that this combination of increasing capital intensity, uncertain compute requirements and structured finance can pressure developers, landlords and investors through execution, renewal and refinancing risk.moodys
Construction and power risks:
A demand slowdown could arrive before projects enter service. That creates a particularly difficult situation for lenders because construction interest, cost overruns and power-reservation charges may accumulate before revenue begins.
Permitting delays, local opposition, water constraints and electricity-grid limitations further compound this exposure. Reuters reported that lenders increasingly treat project readiness—including approvals, permits and local community support—as a credit factor because delays can increase costs, jeopardize covenants and prevent projects from reaching revenue-generating operation.
System-wide scenario:
The more serious scenario is a correlated unwind:
-
AI applications fail to deliver enough monetizable demand.
-
AI labs and cloud providers reduce compute commitments.
-
Data-center utilization and expected rental income fall.
-
Borrowers cannot service or refinance project debt.
-
GPUs and related infrastructure lose collateral value.
-
Losses reach private-credit funds, banks, securitized vehicles, insurers and institutional investors.
-
New financing becomes unavailable, causing further cuts in infrastructure orders and Nvidia sales.
This would not necessarily resemble the 2008 banking crisis: some first-loss exposure sits outside regulated banks. But Chicago Booth research estimates that a severe re-rating of AI-related debt could still produce roughly $60 billion to $140 billion in realized credit losses, alongside large equity-market effects.
What matters most:
The decisive question is not whether AI is useful or whether data centers remain necessary. It is whether cash-paying end users will generate sufficient, durable revenue to justify the full cost of the hardware, power, real estate, construction and financing now being committed. If that answer is no, the sector may discover that it financed capacity—not returns.
……………………………………………………………………………………………………………………………………………………………………………………
From Google’s Gemini:
-
- The Revenue Void: If OpenAI or Anthropic defers or cancels capacity commitments, hyperscalers are left with energized Megawatts (MW) that have no immediate, high-paying tenant.
- Stranded Capital: The specialized power, liquid cooling systems, and electrical equipment tailored for dense AI clusters cannot easily be repurposed for traditional cloud workloads without lowering returns on invested capital (ROIC).
| Financial Metric | Baseline Forecast (Bull Case) | Partial Monetization Reset | Severe Crash / Structural Downside |
|---|---|---|---|
| Cloud Revenue Growth | Accelerated (driven by AI APIs & enterprise seats) | Flattens out as enterprise customers consolidate suppliers | Decelerates sharply; circular cloud revenue loops collapse |
| CapEx Infrastructure | Full execution of Dell’Oro’s ~200 GW build out by 2030 | 20–30% of capacity commitments deferred or resized | Mass cancellations of orders; multi-year build freezes |
| Operating Margins | Expands as inference costs decline relative to software prices | Compresses due to underutilized GPU clusters and high DCPI fixed costs | Severe contraction; massive asset write-downs and depreciation drag |
| ROIC | Historic highs driven by high-density compute demand | Diluted; longer payback periods for specialized data centers | Tanks; billions in stranded physical capital and obsolete hardware |
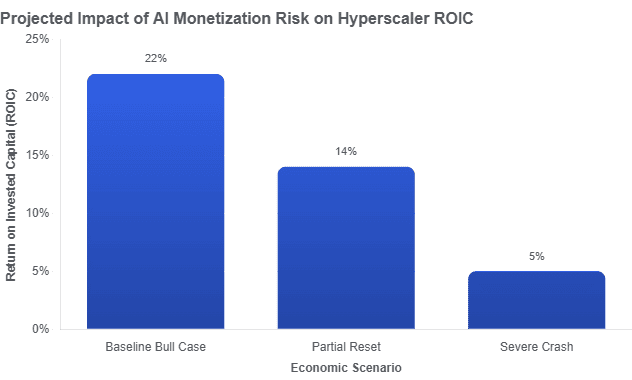
References:
https://www.nytimes.com/2026/08/10/business/ai-nvidia-lenders-500-billion.html
https://www.wheresyoured.at/dont-look-up/
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs (07/23/26)
Merry-go-round of dog chasing its tail: Relationship between U.S. hyperscalers and private Gen AI companies
AI infrastructure spending boom: a path towards AGI or speculative bubble?
Expose: AI is more than a bubble; it’s a data center debt bomb
Will Google Cloud’s AI and data analytics revenue +TPU IP licensing income offset huge AI CAPEX to produce a decent ROI?
Amazon’s Jeff Bezos at Italian Tech Week: “AI is a kind of industrial bubble”
Big Tech AI spending binge results in massive job cuts!
AI spending boom accelerates: Big tech to invest an aggregate of $400 billion in 2025; much more in 2026!
FT: Scale of AI private company valuations dwarfs dot-com boom
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
AI Data Center Boom Carries Huge Default and Demand Risks
Can the debt fueling the new wave of AI infrastructure buildouts ever be repaid?
Gartner: AI spending >$2 trillion in 2026 driven by hyperscalers data center investments
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Hyperscaler AI Race: Soaring Capex Wipes Out Free Cash Flow; AGI and Digital Gods
| Company | 2024 (Actual) | 2025 (Actual) | 2026 (Current Guidance / Est) | 2027 (Projected) |
|---|---|---|---|---|
| 📦 Amazon | $53B | $112B | $195B – $210B | $230B – $260B |
| 🔍 Alphabet (Google) | $51B | $104B | $195B – $205B | $240B – $280B |
| 💻 Microsoft | $56B | $108B | $185B – $195B | $220B – $250B |
| ♾️ Meta | $38B | $85B | $125B – $145B | $150B – $180B |
| 🗄️ Oracle | $13B | $25B | $45B – $50B | $55B – $65B |
| 🧮 Combined Aggregate | $211B | $434B | $745B – $805B | $895B – $1,035B |
The huge increase in hyperscaler capex, wipes out their free cash flow (revenues-expenses is now negative for all but Microsoft). The shift in focus by investors from earnings to free cash flow marks a turning point in market perceptions. The correct way to describe free cash flow is the cash flow a company generates during a period of time that is available to be paid to the company’s shareholders and debtholders.Companies with negative free cash flow are only able to cover the interest and principal on their debt by additional borrowing or by issuing new equity. In other words, cash is flowing from investors to the company, not the other way around. In a financial crisis, investors become unwilling to support companies not able to cover interest and principal, with the result being a cascade of defaults and runs on financial institutions.
A major concern with the massive AI-capex which has occurred during the last two years is that much of it is debt financed. As the real cost of generative AI-tokens is becoming clear, lower priced Chinese competitors are emerging, and AI customers are beginning to economize on their use of AI. As a result, investors are becoming increasingly alarmed about whether U.S. AI firms will be able to cover their debt obligations. AI-capex has been the main, and perhaps only driver of U.S. economic growth. If more companies announce negative free cash flows, that increase in magnitude, the financial system and overall economy will move closer to the tipping point.
…………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………….
But wait, Google/Alphabet co-founder says it’s more about winning AI market share than skyrocketing capex or ROI. On Patrick O’Shaughnessy’s Invest Like the Best podcast, Gavin Baker, Chief Investment Officer for Atreides Management, shared an anecdote about what’s been going on within Google/Alphabet offices. According to Baker, Google co-founder Larry Page has been telling Google employees, “I am willing to go bankrupt rather than lose this race.” That shows how high the person who led Alphabet through its halcyon days thinks the stakes are in AI.
References:
https://www.fool.com/investing/2024/08/31/thinking-of-selling-nvidia-stock-larry-page-quote/
Curmudgeon: Caveat Emptor: Huge Debt and Circular Financing Deals Dominate AI Build-Outs
Merry-go-round of dog chasing its tail: Relationship between U.S. hyperscalers and private Gen AI companies
Ookla: AI platform reliability decreases as outages surge
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
Hyperscaler capex > $600 bn in 2026 a 36% increase over 2025 while global spending on cloud infrastructure services skyrockets
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Bloomberg: Meta to sell AI compute in a new cloud services offering
Disclaimer: Perplexity.ai was used for research resulting in this article.
Executive Summary:
According to Bloomberg, Meta Platforms is advancing plans to commercialize its internal AI infrastructure through a new cloud services offering, signaling a strategic expansion beyond its traditional hyperscale consumer platforms into the competitive AI infrastructure market. This initiative would position Meta alongside established cloud providers such as Amazon Web Services (AWS), Microsoft Azure, and Google Cloud, while also overlapping with emerging GPU-centric “neocloud” providers. Meta’s move represents a significant evolution in the AI infrastructure landscape, with potential ripple effects across data center architecture, optical transport networks, and the broader telecom ecosystem.
At the core of this strategy is the monetization of Meta’s rapidly expanding AI compute footprint. The company has aggressively invested in large-scale data center infrastructure—reportedly including multi-hundred-billion-dollar campus developments—to support training and inference for its proprietary large language models (LLMs) and recommendation systems. As these deployments scale, Meta appears to be seeking to externalize surplus capacity, transforming a cost center into a revenue-generating platform.
The proposed service portfolio is expected to span two primary layers. First, Meta may expose access to hosted AI models via APIs, analogous to AWS Bedrock or Azure AI Services, enabling enterprises to integrate generative AI and foundation model capabilities without managing underlying infrastructure. Second, Meta is exploring the provision of raw compute capacity—primarily GPU-accelerated workloads—mirroring the infrastructure-as-a-service (IaaS) model offered by neocloud providers such as CoreWeave. This dual-layer approach would allow Meta to compete both in higher-margin AI platform services and in lower-level compute provisioning.
Telecom & Networking Implications:
From a telecom and network infrastructure perspective, this development has several implications. Hyperscale AI workloads are increasingly bandwidth-intensive, requiring high-capacity, low-latency interconnects within and between data centers. Meta’s investments are therefore likely to drive demand for advanced optical networking technologies, including coherent pluggable optics (e.g., 400ZR/800ZR), data center interconnect (DCI) architectures, and AI-optimized fabric designs leveraging Ethernet-based scale-out topologies. In addition, the geographic placement of these data centers—often in power-abundant, rural locations—introduces new requirements for long-haul fiber connectivity and edge aggregation.
The initiative, internally referred to as “Meta Compute,” reflects a broader industry shift toward vertically integrated AI infrastructure stacks, where hyperscalers tightly couple compute, networking, and software frameworks. For telecom operators and infrastructure vendors, this trend underscores the growing convergence between cloud, AI, and network domains, particularly as AI-driven workloads begin to influence traffic patterns, peering strategies, and edge deployment models.
Strategically, Meta’s entry into the AI cloud market raises competitive pressure across multiple fronts. Unlike traditional cloud providers, Meta brings extensive experience in hyperscale distributed systems and open-source AI frameworks (e.g., PyTorch), but lacks a mature enterprise cloud ecosystem. Its success will likely depend on its ability to translate internal infrastructure efficiencies into externally consumable services, while addressing enterprise requirements for reliability, security, and service-level agreements.
Meta’s cloud push is best viewed as a network-and-infrastructure strategy as much as a software business, because monetizing AI capacity depends on how well it can expose compute, move data, and preserve performance at hyperscale. The telecom significance is that Meta is turning internal AI infrastructure into a market-facing platform, which increases the importance of optical transport, data-center interconnect, and low-latency backbone engineering.
From a telecom perspective, the key issue is not simply that Meta may sell AI models or GPU capacity; it is that the company is building a service layer on top of a very large, power- and bandwidth-intensive distributed system. Reuters reported that Meta is considering both hosted model access and raw compute sales, with the former resembling an AI platform service and the latter looking more like neocloud infrastructure.That means the network becomes part of Meta’s product offering. Large AI inference and training environments require high-bisection fabrics inside the data center, plus dense east-west traffic handling, which pushes demand for faster Ethernet switching, advanced optical modules, and carefully engineered rack-to-rack and site-to-site interconnects. Meta’s AI cloud ambitions reinforce a broader shift: hyperscalers are no longer treating networking as a background utility, but as a primary constraint on scale.
Network World’s coverage of Meta Compute notes that Meta has unified data center and network oversight and is planning multi-gigawatt AI buildouts, underscoring how tightly power, fiber, switching, and facility design are now linked.
For network operators and vendors, that translates into stronger demand for long-haul fiber, DCI platforms, low-latency transport, and high-radix switching. It also raises the strategic value of metro and regional interconnect corridors that can support AI clusters, especially when capacity must be spread across multiple sites for power, land, or resiliency reasons.
Meta’s potential move into raw compute sales is especially relevant to telecom because it resembles the economics of infrastructure-heavy cloud and colocation models. In practice, the service quality will depend on how efficiently Meta can provision GPU clusters, maintain deterministic performance, and avoid congestion across the transport layer connecting those clusters. That implies growing importance for:
-
Coherent optical transport and scalable DCI.
-
High-capacity Ethernet fabrics for AI clusters.
-
Open-rack and disaggregated infrastructure designs.
-
Network automation that can track workload placement and traffic hotspots.
These are not just cloud concerns; they are telecom-grade capacity-planning problems. As AI clusters become larger and more distributed, network planning starts to look more like core network engineering than conventional enterprise hosting.

Image Credits: Gabby Jones/Bloomberg / Getty Images
……………………………………………………………………………………………………………………………………………………………………..
Conclusions:
Meta’s entry would not only compete with AWS, Azure, and Google Cloud, but could also pressure specialized neocloud providers more directly. Reuters noted that Meta’s spare capacity could matter more to neo-cloud vendors than to the largest hyperscalers, because those providers rely on access to external GPU supply and managed infrastructure growth. For telecom analysts, that suggests the competitive battleground is shifting from “who has the best model” to “who can deliver the most resilient compute-network-power stack.” The winners will likely be those that can couple AI accelerators with fiber-rich sites, robust interconnect, and energy-secure data center footprints.
Meta’s move reflects the convergence of cloud, AI, and transport networks. The story is less about Meta becoming a generic cloud vendor and more about hyperscale AI infrastructure evolving into a new class of network-dependent utility. Indeed, Meta’s cloud initiative highlights a broader industry reality — in the AI era, compute is valuable, but connectivity, optical scale, and power-aware architecture increasingly determine whether compute can be monetized at all.
……………………………………………………………………………………………………………………………………….
References:
Meta, like SpaceX, looks to turn excess AI compute into cash
https://www.cnbc.com/2026/05/27/mark-zuckerberg-says-meta-starting-cloud-business-on-the-table.html
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
OCP 2025 Meta keynote: Scaling the AI Infrastructure to Data Center Regions
TechCrunch: Meta to build $10 billion Subsea Cable to manage its global data traffic
AI Frenzy Backgrounder; Review of AI Products and Services from Nvidia, Microsoft, Amazon, Google and Meta; Conclusions
Bharti Airtel and Meta extend 2Africa Pearls subsea cable system to India
Is AI the driving force behind the metaverse?
Big Fiber’s $250M financing deal to buildout dark fiber routes for AI Data Center expansion
Executive Summary:
Big Fiber [1.] has secured $250 million in financing from Stonepeak and Caisse de dépôt et placement du Québec (CDPQ) to expand its dark fiber footprint and increase network capacity in response to accelerating hyperscaler and large-scale data center investments in AI-driven workloads.
Note 1. Sunnyvale, CA headquartered Big Fiber was previously known as Bandwidth IG, which was originally established in 2019 as a telecom and dark-fiber infrastructure company. The rebrand to BIG Fiber was announced on May 1, 2025 when the company described it as a shift to better reflect its focus on privately owned, newly constructed dark fiber networks. The company has built privately owned metro dark fiber networks from its inception, primarily in the SF Bay Area and the Greater Portland, OR and Atlanta, GA areas.
BIG Fiber structures its dark fiber portfolio around high‑strand‑count, single‑mode, low‑loss fiber deployed in purpose‑built, underground metro and regional routes, rather than a carrier‑specific “technology” stack of its own. The company’s public materials emphasize:
-
Single‑mode fiber (SMF) for metro and long‑haul connectivity, consistent with standard dark‑fiber infrastructure designed for multi‑wavelength and DWDM‑based upgrades.
-
High‑density, high‑fiber‑count cables in metro corridors (often hundreds of strands) to support dense data‑center and interconnect demand, which is typical of “new‑build” dark‑fiber operators entering AI‑and‑cloud‑centric markets.
-
Point‑to‑point and ring‑style topologies engineered for extreme route diversity (tri‑/quad‑versity) and low latency, rather than a legacy long‑haul backbone that relies on older fiber types or managed wavelengths.
To complement Big Fiber’s dark‑fiber infrastructure; the customer provides the optical PHY layer (e.g., coherent DWDM, 400ZR/ZR+, or other high‑speed optics), which is how dark‑fiber providers typically position their offerings.
–>More about Big Fiber at the end of this article from the company itself.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………….
Proceeds of the facility will be used to refinance existing debt, provide new capital and facilitate the necessary headroom for major fiber optic network expansions already underway. This includes a significant multi-market buildout in Greater Atlanta, adding over 205 route miles and 165,000 fiber miles to BIG Fiber’s existing market-leading footprint.
“Our partnership with Stonepeak Credit and La Caisse marks a pivotal moment in our mission to empower our customers with highly scalable and purpose-built dark fiber solutions,” said Bruce Garrison, CEO of BIG Fiber. “This financing ensures we have the scale to stay ahead of the escalating demand for modernized infrastructure enabling the AI ecosystem and the necessary digital highways for decades to come.”
“BIG Fiber’s infrastructure delivers critical bandwidth to meet the insatiable demand for both data and compute capacity across its key markets,” said Arun Varanasi, Managing Director at Stonepeak Credit. “We are proud to partner with Columbia Capital, SDC Capital Partners, and La Caisse to support the company’s next leg of growth as it positions itself as one of the preeminent dark fiber operators in the country.”
“BIG Fiber is well positioned to meet the growing connectivity needs of enterprises and data centers seeking new, high-quality infrastructure options,” said Jérôme Marquis, Managing Director and Head of Private Credit at La Caisse. “Its resilient business model, underpinned by long-term contracts and strong structural demand, positions the company well for growth. Together with Stonepeak Credit, we’re providing a tailored financing solution that supports the continued buildout of essential digital infrastructure.”
The latest expansion will bring BIG Fiber’s Atlanta and San Francisco Bay Area network capacity to 850 route miles and over 3 million fiber miles. Projects are currently under construction or contract, with phased Ready for Service (RFS) dates expected in early 2027.

………………………………………………………………………………………………………………………………………………………………………………………………………………………………
According to Big Fiber Chief Commercial Officer Patton Lochridge, demand signals are particularly strong in key U.S. metros including the San Francisco Bay Area, Hillsboro, and Atlanta, where new fiber routes are being deployed to support AI-centric data center expansion. “We’re seeing customers require extreme route diversity, often moving toward triversity or quadversity networks to connect metro assets and long-haul routes,” Lochridge said. He added that inference workloads are increasing the demand for dense metro connectivity: “Traditional telecommunications networks are often too congested or lack the latency and loss tolerances required for stringent AI workloads, making purpose-built metro fiber essential.” Lochridge indicated that the majority of the new capital will be directed toward greenfield build-outs and targeted overbuilds of “exhausted legacy telecommunications corridors that need more scale.”
Industry analysts highlight a parallel geographic shift in AI infrastructure deployment. Sterling Perrin, senior principal analyst for optical networks and transport at Omdia, noted that AI campuses are expanding beyond traditional connectivity hubs such as Ashburn, Dallas, and Northern California into power-advantaged regions including West Texas, Ohio, Tennessee, Louisiana, and Georgia. “They all require massive fiber optic connectivity,” Perrin said.
Power availability is emerging as a primary constraint shaping network topology. Ron Westfall, vice president and analyst at HyperFrame Research, emphasized that grid limitations are driving hyperscalers toward distributed AI campus architectures interconnected via metro and long-haul dark fiber. “Power grid constraints have forced a material shift toward metro and long-haul dark fiber infrastructure to stitch together distributed regional data center campuses,” Westfall said. “Because this relentless GPU-to-GPU communication demands near-zero latency and unprecedented bandwidth, infrastructure planners are prioritizing the deployment of ultra-high-strand dark fiber corridors that directly link distributed, power-rich data centers.”
AI Workloads Reshape Optical Demand:
AI-driven traffic growth is now materially impacting the optical supply chain. In its April 2026 post-OFC analysis, CRU Group reported that AI-related data center demand “has overtaken traditional telecom as the primary growth engine for optical [fiber] and cable,” contributing to tightening supply conditions for high-fiber-count cables and upstream preform materials.
Despite this surge, the majority of AI traffic remains intra-data-center. Omdia estimates indicate that up to 90% of AI traffic does not exit the facility during GPU cluster operations. However, the emergence of distributed AI architectures is beginning to increase requirements for high-capacity inter-data-center interconnect (DCI).
At the Optica Executive Forum, Cisco SVP and Fellow Rakesh Chopra highlighted the scale differential between AI and conventional traffic profiles. As cited by Perrin, AI “scale-up” traffic within data centers can generate 504 times more traffic than traditional DCI flows, while “scale-out” traffic can produce 56 times DCI bandwidth requirements. “With AI training models at the limits of what can be processed within a data center, distributed AI clusters are inevitable,” Perrin said.
This architectural transition is reflected in NVIDIA’s AI factory designs, which decouple east-west GPU compute traffic from traditional north-south enterprise flows, leveraging low-latency leaf-spine topologies optimized for continuous GPU synchronization.
Westfall further noted that these evolving traffic patterns are fundamentally altering network design assumptions. Operators are increasingly optimizing for persistent machine-to-machine synchronization rather than burst-oriented enterprise traffic models.
Fiber as a Core AI Infrastructure Asset:
The Big Fiber’s latest financing aligns with broader trends in AI infrastructure investment, where capital is being deployed across integrated stacks including energy, land, connectivity, and compute infrastructure. Utilities are expanding transmission capacity, while developers are co-locating generation resources near emerging AI hubs.
Within this context, fiber infrastructure is being revalued based on its strategic proximity to power-rich data center clusters. “Infrastructure monetization is shifting away from historical metrics such as per-megabit pricing toward asset-level valuations built around proximity to power-rich data centers,” Westfall said.
If current deployment trajectories persist, the resulting topology will consist of a dense, high-capacity mesh of metro and long-haul fiber routes interconnecting geographically distributed, power-optimized AI campuses with hyperscale cloud and interconnection ecosystems.
………………………………………………………………………………………………………………………………
About BIG Fiber:
BIG Fiber is a metro dark fiber provider that offers high capacity, strategically placed, dark fiber networks to mission critical data centers, Hyperscalers and enterprises throughout the San Francisco Bay Area, Greater Portland and Greater Atlanta areas. BIG Fiber’s 100% underground network meets critical data needs for enterprises and data centers that require new, quality infrastructure options. BIG Fiber’s San Francisco Bay Area network offers more than 320 route miles and 65 data centers. The Greater Portland network has more than 20 route miles and 15 data centers, and the Greater Atlanta network has more than 550 route miles and 30 data centers. BIG Fiber was founded in 2019 and is headquartered in Sunnyvale, California. Visit www.bigfiber.com to learn more.
………………………………………………………………………………………………………………………………
References:
BIG Fiber Secures $250 Million Financing Led by Stonepeak Credit and La Caisse
Analysis: Fiber Broadband Association (FBA) whitepaper: Upgrading MSO Networks to Fiber to the Home (FTTH): A Technical Perspective
Fiber Broadband Association Middle Mile WG: how to use “Digital Infrastructure Networks” for coordinated fiber backbone investments
Analysis: AT&T 1Q-2026 results: increased fiber penetration, FWA momentum, D2D deals, and mobile/home internet bundles
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
Fiber Optic Networks & Subsea Cable Systems as the foundation for AI and Cloud services
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Automating Fiber Testing in the Last Mile: An Experiment from the Field
AI wireless and fiber optic network technologies; IMT 2030 “native AI” concept