AI
NVIDIA and global telecom leaders to build 6G on open and secure AI-native platforms + Linux Foundation launches OCUDU
- AI-RAN Integration: Shifting from fixed-function hardware to AI-RAN architecture to turn networks into programmable AI infrastructure.
- Architectural Resilience: Implementing open and trusted principles to ensure interoperability, supply-chain security, and rapid innovation cycles.
- Integrated Sensing & Communication: Leveraging AI-native platforms to enable real-time intelligence and decision-making at the network edge.
- Scalability: Addressing the complexity of 6G to support billions of autonomous endpoints that demand higher security and lower latency than current architectures can provide.
The NVIDIA AI Aerial platform is a software-defined, cloud-native framework for building, training, and deploying AI-native 5G and 6G wireless networks. It transitions traditional fixed-function hardware to a programmable, multi-tenant infrastructure that runs both Radio Access Network (RAN) and AI workloads simultaneously on NVIDIA-accelerated computing.
Image Credit: NVIDIA
Quotes:
“AI is driving the largest infrastructure buildout in history, and telecommunications is the next frontier,” stated Jensen Huang, founder and CEO of NVIDIA. “By building AI-RAN, we are transforming global telecom networks into a ubiquitous AI fabric.”
Allison Kirkby, chief executive of BT Group, said: “Connectivity is the backbone of economic growth, and with this collaboration, we’re helping lay the foundations for a future ecosystem that is intelligent, sustainable and secure. By building on open and trustworthy AI native platforms, we can simplify future technologies like 6G, ensuring they build upon the strengths of today’s 5G networks while still unlocking powerful new capabilities at scale.”
Tim Höttges, CEO of Deutsche Telekom AG, said: “Best network, best customer experience — that remains our promise. With an open, intelligent and trusted 6G infrastructure, we are laying the foundation for the era of physical AI and unlocking new value for our customers, for industry and for society.”
Arielle Roth, Assistant Secretary of Commerce for Communications and Information, and Administrator at the National Telecommunications and Information Administration, said: “America’s 6G leadership will be critical to our nation’s economic prosperity, national security and global competitiveness. Today’s announcement demonstrates that the United States and our allies and partners around the world are leading in this next-generation technology. We look forward to the next steps from this international industry coalition as they advance and implement their shared 6G vision.”
Jung Jai-hun, president and CEO of SK Telecom, said: “SKT is evolving telco infrastructure to serve as the foundation for the AI era, where connectivity serves as a platform for intelligence and innovation. Together, we can build open, trusted infrastructure that drives a global ecosystem of AI innovation.”
Hideyuki Tsukuda, executive vice president and chief technology officer of SoftBank Corp., said: “Al-native 6G will transform wireless networks into secure, software-defined infrastructure that supports the next wave of global innovation. SoftBank Corp. is driving this innovation with NVIDIA by advancing open and trusted platforms that enable interoperability, resilience and continuous evolution at scale.”
Srini Gopalan, CEO of T-Mobile, said: “We’re at a pivotal moment. In the U.S., we’ve laid the foundation with 5G Advanced and AI-native networks where intelligence lives inside the network. As 6G becomes the backbone of the AI era, telecom will serve as the nervous system of the digital economy, enabling autonomous systems and intelligent industries at scale and unlocking new value for customers and businesses alike. T-Mobile is proud to help define what’s next through deep ecosystem collaboration and sustained innovation.”
……………………………………………………………………………………………………………………………………………
Linux Foundation launches OCUDU:
Separately, the Linux Foundation (LF) today announced the formation of the Open Centralized Unit Distributed Unit (OCUDU) Ecosystem Foundation, an open collaboration hub dedicated to building, scaling, and sustaining the OCUDU technical project assets and leveraging them to establish a foundational reference platform for RAN including AI based algorithms and solutions. The OCUDU Ecosystem Foundation provides a critical mechanism for industry vendors to optimally guide OCUDU development to support 5G and early AI Native 6G services.
The OCUDU Ecosystem Foundation brings together an ecosystem across enterprise, telecom operators, cloud providers, equipment vendors, and research institutions to co-develop and integrate critical components required for 5G and early 6G deployments. This community-driven model complements global standards from 3GPP and O-RAN alliance and industry alliances like AI-RAN alliance. This global effort ensures that innovation, transparency, and interoperability remain at the core of global software-defined RAN evolution.
“By aligning global efforts under the Linux Foundation, we’re building an open, trusted, and secure open source platform to power the next decade of wireless innovation,” said Arpit Joshipura, general manager, Networking, Edge and IoT, at the Linux Foundation. “The OCUDU Ecosystem Foundation represents a key step forward in open source RAN, specifically for CU and DU.”
“This initiative brings the best of the open source model to one of the most critical layers of future wireless: the foundation for an interoperable, software-defined radio access network,” said Dr. Tom Rondeau, principal director for FutureG. “By shifting the maintenance of these common components to a collaborative, open-source project, under neutral governance at the Linux Foundation, we enable our industry partners to focus their resources on the innovative and monetizable technologies that are most effective for the nation. We are building a foundation that enables shared success and accelerates progress for the entire ecosystem. We are looking forward to seeing this approach provide a vital platform for strengthening our relationships and collaboration with our allies and international partners.”
“The key to driving innovation in wireless is to leverage a broad ecosystem of experts in networking, radio software, and emerging AI technologies,” said Joe Kochan, CEO of NSC. “What started with a competitive proposal process to elicit the best technology solutions from among NSC’s large and diverse membership is now expanding under the Linux Foundation, and NSC is proud to continue partnering with both LF and the FutureG team to advance OCUDU development efforts and build the next generation of wireless capabilities.”
References:
Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020)
SKT 6G ATHENA White Paper: a mid-to-long term network evolution strategy for the AI era
Dell’Oro: RAN Market Stabilized in 2025 with 1% CAG forecast over next 5 years; Opinion on AI RAN, 5G Advanced, 6G RAN/Core risks
Nokia and Rohde & Schwarz collaborate on AI-powered 6G receiver years before IMT 2030 RIT submissions to ITU-R WP5D
SK Telecom, DOCOMO, NTT and Nokia develop 6G AI-native air interface
Market research firms Omdia and Dell’Oro: impact of 6G and AI investments on telcos
Ericsson goes with custom silicon (rather than Nvidia GPUs) for AI RAN
Dell’Oro: Analysis of the Nokia-NVIDIA-partnership on AI RAN
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
Intel and AI chip startup SambaNova partner; SN50 AI inferencing chip max speed said to be 5X faster than competitive AI chips
Intel and AI chip startup SambaNova have entered into a multi-year strategic collaboration to deploy high-performance, cost-efficient AI inference solutions [1.] tailored for AI-native firms, enterprises, and government sectors. This global initiative leverages Intel® Xeon® infrastructure, with Intel Capital further signaling commitment through participation in SambaNova’s $350M Series E financing round. The collaboration will give customers a powerful alternative to GPU‑centric solutions, offering optimized performance for leading open‑source models with predictable throughput and total cost of ownership. Founded in 2017, the Palo Alto, CA company specializes in AI chips and software. SambaNova’s Chairman is Lip-Bu Tan, who is also the CEO of Intel!
Note 1. AI inferencing is the process of using a trained AI model to make real-time predictions, decisions, or generate content from new, previously unseen data. It transforms inputs (a query, image, sensor reading) into useful results (a sentence, classification, alert). Unlike training and language models, inference is about prompt execution, often requiring low-latency (speed) and high efficiency. AI Inference chips have attracted intense investor interest following a wave of deal making around rivals to Nvidia, as AI companies seek faster and more efficient hardware. See References below for more information.
………………………………………………………………………………………………………………………………………………………………………………………………………………………………….
For high-scale AI workloads, the integration of Intel CPUs with SambaNova’s specialized AI platform was said to offer a high-efficiency rack-level inference alternative. This partnership serves as a strategic bridge as Intel scales its independent GPU-based offerings. Intel remains fully committed to its internal GPU roadmap, continuing aggressive investment across architecture, software, and systems. This collaboration enhances Intel’s edge-to-cloud strategy without altering its competitive trajectory in the GPU market. By combining Xeon processors, Intel networking, and SambaNova systems, the two companies are positioned to capture a significant share of the multi-billion-dollar inference market through heterogeneous data center architectures.
As part of the collaboration, Intel plans to make a strategic investment in SambaNova to accelerate the rollout of an Intel‑powered AI cloud. The collaboration is expected to span three key areas:
- AI Cloud Expansion – Scaling SambaNova’s vertically integrated AI cloud, built on Intel Xeon‑based infrastructure and optimized for large language and multimodal models. The platform will deliver low‑latency, high‑throughput AI services, supported by reference architectures, deployment blueprints, and partnerships with system integrators and software vendors.
- Integrated AI Infrastructure – Combining SambaNova’s systems with Intel’s CPUs, accelerators, and networking technologies to power scalable, production‑ready inference for reasoning, code generation, multimodal applications, and agentic workflows.
- Go‑to‑Market Execution – Joint co‑selling and co‑marketing through Intel’s global enterprise, cloud, and partner channels to accelerate adoption across the AI ecosystem.
Together, SambaNova and Intel aim to shape the next generation of heterogeneous AI data centers — integrating Intel Xeon processors, Intel GPUs, Intel networking and storage, and SambaNova systems — to unlock a multi‑billion‑dollar inference market opportunity.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………
SambaNova also announced its SN50 AI chip, which boasts a max speed that’s 5X faster than competitive chips, according to the company.
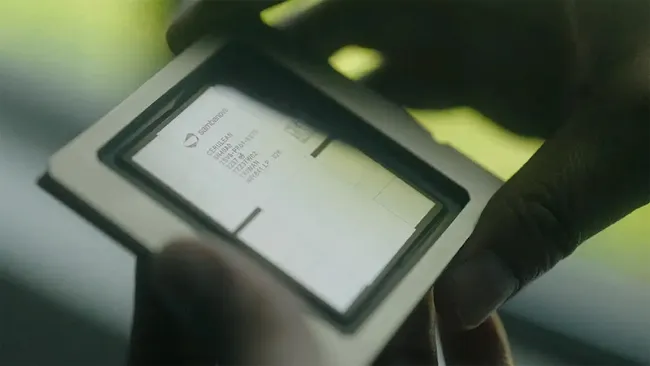
Image Credit: SambaNova
Positioned as the most efficient chip for agentic AI, the SN50 chip offers enterprises a 3X lower total cost of ownership – a powerful foundation to scale fast inference and bring autonomous AI agents into full production. The SN50 will be shipping to customers later this year. To quickly scale and distribute SN50, SambaNova is collaborating with Intel, and has obtained $350 million in strategic Series E financing to expand manufacturing and cloud capacity.
“AI is no longer a contest to build the biggest model,” said Rodrigo Liang, co‑founder and CEO of SambaNova. “With the SN50 and our deep collaboration with Intel, the real race is about who can light up entire data centers with AI agents that answer instantly, never stall, and do it at a cost that turns AI from an experiment into the most profitable engine in the cloud.”
“Customers are asking for more choice and more efficient ways to scale AI,” said Kevork Kechichian, EVP, General Manager, Data Center Group, Intel. “By combining Intel’s leadership in compute, networking, and memory with SambaNova’s full-stack AI systems and inference cloud platform, we are delivering a compelling option for organizations looking for GPU alternatives to deploy advanced AI at scale.”
The SN50 delivers five times more compute per accelerator and four times more network bandwidth than the previous generation. It links up to 256 accelerators over a multi‑terabyte‑per‑second interconnect, cutting time‑to‑first‑token and supporting larger batch sizes. The result: Enterprises can deploy bigger, longer‑context AI models with higher throughput and responsiveness — while keeping performance high and costs and latency under control.
“AI is moving from a software story to an infrastructure story,” said Landon Downs, co-founder and managing partner at Cambium Capital. “SN50 is engineered for the real-world latency and economic requirements that will determine who successfully deploys agentic AI at scale.”
Built on SambaNova’s Reconfigurable Data Unit (RDU) architecture, SN50 delivers:
- Instant AI Experiences – Ultra‑low latency delivers real‑time responsiveness for next‑gen enterprise apps like voice assistants.
- Unmatched Scale and Concurrency – Power thousands of simultaneous AI sessions with consistent high performance.
- Breakthrough Model Capacity – Three‑tier memory architecture unlocks 10T+ parameter models and 10M+ context lengths for deeper reasoning and richer outputs.
- Maximum Efficiency at Scale – Higher hardware utilization lowers cost‑per‑token, driving greater performance and ROI.
- Smarter Memory, Smarter Efficiency – Resident multi‑model memory and agentic caching optimize the three‑tier architecture, cutting infrastructure costs for enterprise‑scale AI deployments.
“The new SambaNova SN50 RDU changes the tokenomics of AI inference at scale. By delivering both high performance and high throughput with a chip that uses existing power and is air cooled, SambaNova is changing the game,” said Peter Rutten, Research Vice-President Performance Intensive Computing at analyst firm IDC.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………
SoftBank Corp. will be the first customer to deploy SN50 within its next‑generation AI data centers in Japan. The deployment will power low‑latency inference services for sovereign and enterprise customers across Asia‑Pacific, supporting both open‑source and proprietary frontier models with aggressive latency and throughput requirements.
“With SN50, we are building an AI inference fabric for Japan that can serve our customers and partners with the speed, resiliency and sovereignty they expect from SoftBank,” said Hironobu Tamba, Vice President and Head of the Data Platform Strategy Division of the Technology Unit at SoftBank Corp. “By standardizing on SN50, we gain the ability to deliver world‑class AI services on our own terms — with the performance of the best GPU clusters, but with far better economics and control.”
The SN50 deployment deepens SambaNova’s existing relationship with SoftBank Corp., which already hosts SambaCloud to provide ultra‑fast inference for developers in the region. By anchoring its newest clusters on SN50, SoftBank positions SambaNova as the inference backbone for its sovereign AI initiatives and future large‑scale agentic services.
……………………………………………………………………………………………………………………………………………………………………………………………………………………………………
References:
Nvidia AI-RAN survey results; AI inferencing as a reinvention of edge computing?
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Groq and Nvidia in non-exclusive AI Inference technology licensing agreement; top Groq execs joining Nvidia
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Custom AI Chips: Powering the next wave of Intelligent Computing
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
OpenAI and Broadcom in $10B deal to make custom AI chips
Huawei to Double Output of Ascend AI chips in 2026; OpenAI orders HBM chips from SK Hynix & Samsung for Stargate UAE project
U.S. export controls on Nvidia H20 AI chips enables Huawei’s 910C GPU to be favored by AI tech giants in China
Superclusters of Nvidia GPU/AI chips combined with end-to-end network platforms to create next generation data centers
Nscale pitches “Sovereign AI” to telecom operators to provide AI-as-a-service (AIaaS)
Nscale [1.], headquartered in London, UK, is suggesting that telecom networks host “Sovereign AI” infrastructure, to ensure that data remains within regional borders while driving efficiency and automation. The company is collaborating with Nokia to accelerate global AI infrastructure deployment and is showcasing these solutions at MWC 2026. The company is partnering with telecom operators to transform their existing national fiber and edge sites into high-performance AI data centers. They aim to leverage telco assets to deliver GPU-powered AI-as-a-Service (AIaaS), optimize their 5G networks, and support AI-driven analytics.
Note 1. Nscale is building the advanced infrastructure, systems and solutions that enables practitioners, enterprises, and governments across the globe to create, deploy, and scale their most transformative AI systems. Nscale’s AI Compute offering provides on-demand access to high-performance GPUs, enabling businesses and developers to execute complex computational tasks like AI model training and data analysis without the need for upfront investment in expensive hardware. Nscale is building its own high-density data centers with direct liquid cooling to support these initiatives.
Nscale says they are “empowering telecommunications providers to deliver a range of AI services and solutions which help support network optimization and network performance monitoring, alongside improving customer experience with AI-powered automation tools. With our scalable GPU infrastructure and AI expertise, our telco customers can provide industry-leading AI-as-a-service (AIaaS), scale for 5G and benefit from artificial intelligence.”
Last week at the UK Telecoms Innovation Network (UKTIN)’s AI & Advanced Connectivity: State of AI panel, Nscale’s Simon Rowell spoke about the importance of building infrastructure that is resilient and able to adapt over time. Technologies evolve, but what matters is whether the underlying infrastructure can accommodate that change. Across telco networks and digital services, the fundamentals remain consistent: efficiency, automation, productivity, and resilience. Nscale is focused on building flexible AI infrastructure that can support real services as requirements change.

UK Telecoms Innovation Network Panel Session State of AI in UK Telecoms. Photo Credit: Nscale
…………………………………………………………………………………………………………………………………………………………………
Nokia and Nscale are collaborating to accelerate the development of AI-ready data center infrastructure across Europe and globally. As part of this partnership, Nokia serves as the preferred networking partner for Nscale, providing IP, optical networking, and data center switching technology to support high-performance AI clusters. Key aspects of the collaboration include:
- Infrastructure Build-out: Nokia is supplying its 7220 IXR and 7750 SR platforms to support Nscale’s AI-ready data centers, including a key project in Stavanger, Norway, and a 50 MW AI Campus in Loughton, U.K..
- Strategic Investment: Nokia is an investor in Nscale’s Series B funding round, supporting the company’s expansion and the deployment of up to 300,000 GPUs.
- Technology & Innovation: The partnership focuses on co-developing networking stacks for AI clusters, utilizing Nokia’s Ethernet-based data center fabric for low-latency, high-performance computing. Sustainability
- Focus: The collaboration emphasizes energy-efficient cooling and 100% renewable energy for data center operations. Nokia Nokia +4
David Power CTO at Nscale said, “Our mission is to redefine the boundaries of AI and High-Performance Computing through innovative, sustainable solutions. Nokia’s data center fabric enables us to scale our GPU clusters while maintaining the reliability and performance needed to serve our customers with cutting-edge AI services. The flexibility of Nokia’s solution ensures we can bring advanced AI capabilities to market faster.”
……………………………………………………………………………………………………………………………………………………………………..
References:
Sovereign AI infrastructure for telecom companies: implementation and challenges
Nokia in major pivot from traditional telecom to AI, cloud infrastructure, data center networking and 6G
Nokia selects Intel’s Justin Hotard as new CEO to increase growth in IP networking and data center connections
Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020)
Private 5G networks move to include automation, autonomous systems, edge computing & AI operations
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
China vs U.S.: Race to Generate Power for AI Data Centers as Electricity Demand Soars
The International Energy Agency (IEA) forecasts that in the next five years, the global demand for power (electricity) is set to grow roughly 50% faster than it did during the previous decade – and more than twice as fast as energy demand overall. That tremendous increase in demand is due to power hungry AI data centers. There’s also electric cars and buses, electric-powered industrial machines, and electric heating of homes.
Global AI growth will be contingent on generating more power for data centers:
- Global data center power demand is now expected to rise to a record 1,596 terawatt-hours by 2035 – +255% increase from 2025 levels.
- The U.S. is set to remain the leader in energy consumption with a +144% surge in demand over this period, to 430 terawatt-hours.
- China’s demand is projected to rise +255%, to 397 terawatt-hours.
- European demand is expected to surge +303%, to 274 terawatt-hours.
- New data centers coming online between now and 2030 will need more than 600 terawatt-hours of electricity. This is enough to power ~60 million homes.


Power for AI Data Centers: China vs U.S.:
China is currently ahead of the United States in generating and building out power infrastructure to support AI data centers, a phenomenon sometimes described by industry observers as an “electron gap.”
China’s rapid, centralized expansion of electricity generation—including both massive renewable projects and traditional, dispatchable power—has created a significant capacity advantage in the race to support AI workloads, which are increasingly limited by energy availability rather than just chip access.
Key factors in China’s power advantage for AI include:
Massive Generation Growth: Between 2010 and 2024, China’s power production increased by more than the rest of the world combined. In 2024 alone, China added 543 gigawatts of power capacity—more than the total capacity added by the U.S. in its entire history.
Significant Surplus Capacity: By 2030, China is projected to have roughly 400 gigawatts of spare power capacity, which is triple the expected power demand of the global data center fleet at that time.
“Eastern Data, Western Computing” Initiative: China is actively shifting energy-intensive data centers to its resource-rich western regions (like Inner Mongolia) while powering them with surplus renewable energy, such as wind and solar.
Lower Costs and Faster Buildouts: Data centers in China can pay less than half the rates for electricity that American data centers do. Furthermore, projects in China can move from planning to operation in months, compared to years in the U.S. due to faster permitting and fewer regulatory hurdles.
Conclusions:
While the U.S. currently leads in advanced AI chips and model development, it is facing a severe “energy bottleneck” for new data centers, with some requiring over a gigawatt of power. U.S. power demand has remained relatively flat for 20 years, resulting in a lag in building new capacity, whereas China has traditionally built power infrastructure in anticipation of high demand. Morgan Stanley has forecast that U.S. data centers could face a 44-gigawatt electricity shortfall in the next three years.
Despite China’s advantage in energy, U.S. export controls on high-end AI chips (such as Nvidia’s GPUs) have acted as a significant constraint on China’s actual AI compute power. This has led to a situation where the U.S. has the best “brains” (chips) but limited power to run them, while China has the “muscle” (energy) but limited access to top-tier AI brains.
However, the rapid improvements in Chinese AI models (such as DeepSeek), which are more energy-efficient and optimized for lower-tier hardware, may help mitigate this constraint.
References:
https://www.iea.org/reports/electricity-2026
https://x.com/KobeissiLetter/status/2023437717888250284
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Analysis: Ethernet gains on InfiniBand in data center connectivity market; White Box/ODM vendors top choice for AI hyperscalers
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
Analysis: Rakuten Mobile and Intel partnership to embed AI directly into vRAN
Today, Rakuten Mobile and Intel announced a partnership to embed Artificial Intelligence (AI) directly into the virtualized Radio Access Network (vRAN) stack. While vRAN currently represents a small percentage of the total RAN market (Dell’Oro Group recently forecasts vRAN to account for 5% to 10% of the total RAN market by 2026), this partnership could boost increase that percentage as it addresses key adoption hurdles—performance, power, and AI integration. Key areas of innovation include:
- Enhanced Wireless Spectral Efficiency: Optimizing spectrum utilization for superior network performance and capacity.
- Automated RAN Operations: Streamlining network management and reducing operational complexities through intelligent automation.
- Optimized Resource Allocation: Dynamically allocating network resources for maximum efficiency and subscriber experience.
- Increased Energy Efficiency: Significantly reducing power consumption in the RAN, contributing to sustainable network operations.
The partnership essentially aims to make vRAN superior in performance and TCO (Total Cost of Ownership) compared to traditional, proprietary, purpose built RAN hardware.
“We are incredibly excited to expand our collaboration with Intel to pioneer truly AI-native RAN architectures,” said Sharad Sriwastawa, co-CEO and CTO, Rakuten Mobile. “Together, we are validating transformative AI-driven innovations that will not only shape but define the future of mobile networks. This partnership showcases how intelligent RAN can be achieved through the seamless and efficient integration of AI workloads directly within existing vRAN software stacks, delivering unparalleled performance and efficiency.”
Rakuten Mobile and Intel are engaged in rigorous testing and validation of cutting-edge RAN AI use cases across Layer 1, Layer 2, and comprehensive RAN operation and network platform management. A core objective is the seamless integration of AI directly into the RAN stack, meticulously addressing integration challenges while upholding carrier-grade reliability and stringent latency requirements.
Utilizing Intel FlexRAN reference software, the Intel vRAN AI Development Kit, and a robust suite of AI tools and libraries, Rakuten Mobile is collaboratively training, optimizing, and deploying sophisticated AI models specifically tailored for demanding RAN workloads. This collaborative effort is designed to realize ultra-low, real-time AI latency on Intel Xeon 6 SoC, capitalizing on their built-in AI acceleration capabilities, including AVX512/VNNI and AMX.
“AI is transforming how networks are built and operated,” said Kevork Kechichian, Executive Vice President and General Manager of the Data Center Group, Intel Corporation. “Together with Rakuten, we are demonstrating how AI benefits can be achieved in vRAN. Intel Xeon processors power the majority of commercial vRAN deployments worldwide, and this transformation momentum continues to accelerate. Intel is providing AI-ready Xeon platforms that allow operators like Rakuten to design AI-ready infrastructure from the ground up, with built-in acceleration capabilities.”
Rakuten says they are “poised to unlock new levels of RAN performance, efficiency, and automation by embedding AI directly into the RAN software stack, this AI-native evolution represents the future of cloud-native, AI-powered RAN – inherently software-upgradable and built on open, general-purpose computing platforms. Additionally, the extended collaboration between Rakuten Mobile and Intel marks a significant step toward realizing the vision of autonomous, self-optimizing networks and powerfully reinforces both companies’ commitment to open, programmable, and intelligent RAN infrastructure worldwide.”
……………………………………………………………………………………………………………………………………………………………………..
- AI-Native Efficiency & Performance: The collaboration focuses on integrating AI to improve network performance and energy efficiency, which is a major pain point for operators. By embedding AI directly into the vRAN stack, they are enhancing wireless spectral efficiency, reducing power consumption, and automating RAN operations.
- Leveraging High-Performance Hardware: The initiative utilizes Intel® Xeon® 6 processors with built-in vRAN Boost. This eliminates the need for external, power-hungry accelerator cards, offering up to 2.4x more capacity and 70% better performance-per-watt.
- Validation of Large-Scale Commercial Viability: Rakuten Mobile operates the world’s first fully virtualized, cloud-native network. Its continued collaboration with Intel to make the vRAN AI-native provides a proven blueprint for other operators, reducing the perceived risk of adopting vRAN, particularly in brownfield (existing) networks.
- Acceleration of Open RAN Ecosystem: The collaboration supports the broader push towards Open RAN, which is expected to see a significant rise in market share, doubling between 2022 and 2026.
………………………………………………………………………………………………………………………………………………………………
- Market Share Shift: Omdia forecasts that vRAN’s share of the RAN baseband subsector will reach 20% by 2028. That’s a significant jump from its current low single-digit percentage.
- Explosive CAGR: The global vRAN market is projected to grow from approximately $16.6 billion in 2024 to nearly $80 billion by 2033, representing a 19.5% CAGR.
- Small Cell Dominance: By the end of 2026, it is estimated that 77% of all vRAN implementations will be on small cell architectures, a key area where Rakuten and Intel have demonstrated success.
References:
https://corp.mobile.rakuten.co.jp/english/news/press/2026/0210_01/
Virtual RAN gets a boost from Samsung demo using Intel’s Grand Rapids/Xeon Series 6 SoC
RAN silicon rethink – from purpose built products & ASICs to general purpose processors or GPUs for vRAN & AI RAN
vRAN market disappoints – just like OpenRAN and mobile 5G
LightCounting: Open RAN/vRAN market is pausing and regrouping
Dell’Oro: Private 5G ecosystem is evolving; vRAN gaining momentum; skepticism increasing
https://www.mordorintelligence.com/industry-reports/virtualized-ran-vran-market
https://www.grandviewresearch.com/industry-analysis/virtualized-radio-access-network-market-report
Nvidia CEO Huang: AI is the largest infrastructure buildout in human history; AI Data Center CAPEX will generate new revenue streams for operators
Executive Summary:
In a February 6, 2026 CNBC interview with with Scott Wapner, Nvidia CEO Jensen Huang [1.] characterized the current AI build‑out as “the largest infrastructure buildout in human history,” driven by exceptionally high demand for compute from hyperscalers and AI companies. “Through the roof” is how he described AI infrastructure spending. It’s a “once-in-a-generation infrastructure buildout,” specifically highlighting that demand for Nvidia’s Blackwell chips and the upcoming Vera Rubin platform is “sky-high.” He emphasized that the shift from experimental AI to AI as a fundamental utility has reached a definitive inflection point for every major industry.
Jensen forecasts aa roughly 7–to- 8‑year AI investment cycle lies ahead, with capital intensity justified because deployed AI infrastructure is already generating rising cash flows for operators. He maintains that the widely cited ~$660 billion AI data center capex pipeline is sustainable, on the grounds that GPUs and surrounding systems are revenue‑generating assets, not speculative overbuild. In his view, as long as customers can monetize AI workloads profitably, they will “keep multiplying their investments,” which underpins continued multi‑year GPU demand, including for prior‑generation parts that remain fully leased.
Note 1. Being the undisputed leader of AI hardware (GPU chips and networking equipment via its Mellanox acquisition), Nvidia MUST ALWAYS MAKE POSITIVE REMARKS AND FORECASTS related to the AI build out boom. Reader discretion is advised regarding Huang’s extremely bullish, “all-in on AI” remarks.

Huang reiterated that AI will “fundamentally change how we compute everything,” shifting data centers from general‑purpose CPU‑centric architectures to accelerated computing built around GPUs and dense networking. He emphasizes Nvidia’s positioning as a full‑stack infrastructure and computing platform provider—chips, systems, networking, and software—rather than a standalone chip vendor. He accuratedly stated that Nvidia designs “all components of AI infrastructure” so that system‑level optimization (GPU, NIC, interconnect, software stack) can deliver performance gains that outpace what is possible with a single chip under a slowing Moore’s Law. The installed base is presented as productive: even six‑year‑old A100‑class GPUs are described as fully utilized through leasing, underscoring persistent elasticity of AI compute demand across generations.
AI Poster Childs – OpenAI and Anthropic:
Huang praised OpenAI and Anthropic, the two leading artificial intelligence labs, which both use Nvidia chips through cloud providers. Nvidia invested $10 billion in Anthropic last year, and Huang said earlier this week that the chipmaker will invest heavily in OpenAI’s next fundraising round.
“Anthropic is making great money. Open AI is making great money,” Huang said. “If they could have twice as much compute, the revenues would go up four times as much.”
He said that all the graphics processing units that Nvidia has sold in the past — even six-year old chips such as the A100 — are currently being rented, reflecting sustained demand for AI computing power.
“To the extent that people continue to pay for the AI and the AI companies are able to generate a profit from that, they’re going to keep on doubling, doubling, doubling, doubling,” Huang said.
Economics, utilization, and returns:
On economics, Huang’s central claim is that AI capex converts into recurring, growing revenue streams for cloud providers and AI platforms, which differentiates this cycle from prior overbuilds. He highlights very high utilization: GPUs from multiple generations remain in service, with cloud operators effectively turning them into yield‑bearing infrastructure.
This utilization and monetization profile underlies his view that the capex “arms race” is rational: when AI services are profitable, incremental racks of GPUs, network fabric, and storage can be modeled as NPV‑positive infrastructure projects rather than speculative capacity. He implies that concerns about a near‑term capex cliff are misplaced so long as end‑market AI adoption continues to inflect.
Competitive and geopolitical context:
Huang acknowledges intensifying global competition in AI chips and infrastructure, including from Chinese vendors such as Huawei, especially under U.S. export controls that have reduced Nvidia’s China revenue share to roughly half of pre‑control levels. He frames Nvidia’s strategy as maintaining an innovation lead so that developers worldwide depend on its leading‑edge AI platforms, which he sees as key to U.S. leadership in the AI race.
He also ties AI infrastructure to national‑scale priorities in energy and industrial policy, suggesting that AI data centers are becoming a foundational layer of economic productivity, analogous to past buildouts in electricity and the internet.
Implications for hyperscalers and chips:
Hyperscalers (and also Nvidia customers) Meta , Amazon, Google/Alphabet and Microsoft recently stated that they plan to dramatically increase spending on AI infrastructure in the years ahead. In total, these hyperscalers could spend $660 billion on capital expenditures in 2026 [2.] , with much of that spending going toward buying Nvidia’s chips. Huang’s message to them is that AI data centers are evolving into “AI factories” where each gigawatt of capacity represents tens of billions of dollars of investment spanning land, compute, and networking. He suggests that the hyperscaler industry—roughly a $2.5 trillion sector with about $500 billion in annual capex transitioning from CPU to GPU‑centric generative AI—still has substantial room to run.
Note 2. An understated point is that while these hyperscalers are spending hundered of billions of dollars on AI data centers and Nvidia chips/equipment they are simultaneously laying off tens of thousands of employees. For example, Amazon recently announced 16,000 job cuts this year after 14,000 layoffs last October.
From a chip‑level perspective, he argues that Nvidia’s competitive moat stems from tightly integrated hardware, networking, and software ecosystems rather than any single component, positioning the company as the systems architect of AI infrastructure rather than just a merchant GPU vendor.
References:
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Superclusters of Nvidia GPU/AI chips combined with end-to-end network platforms to create next generation data centers
184K global tech layoffs in 2025 to date; ~27.3% related to AI replacing workers
Analysis: Edge AI and Qualcomm’s AI Program for Innovators 2026 – APAC for startups to lead in AI innovation
Qualcomm is a strong believer in Edge AI as an enabler of faster, more secure, and energy-efficient processing directly on devices—rather than the cloud—unlocking real-time intelligence for industries like robotics and smart cities.
In support of that vision, the fabless SoC company announced the official launch of its Qualcomm AI Program for Innovators (QAIPI) 2026 – APAC, a regional startup incubation initiative that supports startups across Japan, Singapore, and South Korea in advancing the development and commercialization of innovative edge AI solutions.
Building on Qualcomm’s commitment to edge AI innovation, the second edition of QAIPI-APAC invites startups to develop intelligent solutions across a broad range of edge-AI applications using Qualcomm Dragonwing™ and Snapdragon® platforms, together with the new Arduino® UNO Q development board, strengthening their pathway toward global commercialization.
Startups gain comprehensive support and resources, including access to Qualcomm Dragonwing™ and Snapdragon® platforms, the Arduino® UNO Q development board, technical guidance and mentorship, a grant of up to US$10,000, and eligibility for up to US$5,000 in patent filing incentives, accelerating AI product development and deployment.
Applications are open now through April 30, 2026 and will be evaluated based on innovation, technical feasibility, potential societal impact, and commercial relevance. The program will be implemented in two phases. The application phase is open to eligible startups incorporated and registered in Japan, Singapore, or South Korea. Shortlisted startups will enter the mentorship phase, receiving one-on-one guidance, online training, technical support, and access to Qualcomm-powered hardware platforms and development kits for product development. They will also receive a shortlist grant of up to US$10,000 and may be eligible for a patent filing incentive of up to US$5,000. At the conclusion of the program, shortlisted startups may be invited to showcase their innovations at a signature Demo Day in late 2026, engaging with industry leaders, investors, and potential collaborators across the APAC innovation ecosystem.
Comment and Analysis:
Qualcomm is a strong believer in Edge AI—the practice of running AI models directly on devices (smartphones, cars, IoT, PCs) rather than in the cloud—because they view it as the next major technological paradigm shift, overcoming limitations inherent in cloud computing. Despite the challenges of power consumption and processing limitations, Qualcomm’s strategy hinges on specialized, heterogenous computing rather than relying solely on RISC-based CPU cores.
Key Issues for Qualcomm’s Edge AI solutions:
- Qualcomm® AI Engine: This combines specialized hardware, including the Hexagon NPU (Neural Processing Unit), Adreno GPU, and CPU. The NPU is specifically designed to handle high-performance, complex AI workloads (like Generative AI) far more efficiently than a generic CPU.
- Custom Oryon CPU: The latest Snapdragon X Elite platform features customized cores that provide high performance while outperforming traditional x86 solutions in power efficiency for everyday tasks.
- Specialization Saves Power: By using specialized AI engines (NPUs) rather than general-purpose CPU/GPU cores, Qualcomm can run inference tasks at a fraction of the power cost.
- Lower Overall Energy: Doing AI at the edge can save total energy by avoiding the need to send data to a power-hungry data center, which requires network infrastructure, and then sending it back.
- Intelligent Efficiency: The Snapdragon 8 Elite, for example, saw a 27% reduction in power consumption while increasing AI performance significantly.
- Instant Responsiveness (Low Latency): For autonomous vehicles or industrial robotics, a few milliseconds of latency to the cloud can be catastrophic. Edge AI provides real-time, instantaneous analysis.
- Privacy and Security: Data never leaves the device. This is crucial for privacy-conscious users (biometrics) and compliance (GDPR), which is a major advantage over cloud-based AI.
- Offline Capability: Edge devices, such as agricultural sensors or smart home devices in remote areas, continue to function without internet connectivity.
- Diversification: With the smartphone market maturing, Qualcomm sees the “Connected Intelligent Edge” as a huge growth opportunity, extending their reach into automotive, IoT, and PCs.
- “Ecosystem of You”: Qualcomm aims to connect billions of devices, making AI personal and context-aware, rather than generic.
- Qualcomm AI Hub: This makes it easier for developers to deploy optimized models on Snapdragon devices.
- Model Optimization: They specialize in making AI models smaller and more efficient (using quantization and specialized AI inference) to run on devices without requiring massive, cloud-sized computing power.
References:
Qualcomm CEO: AI will become pervasive, at the edge, and run on Snapdragon SoC devices
Huawei, Qualcomm, Samsung, and Ericsson Leading Patent Race in $15 Billion 5G Licensing Market
Private 5G networks move to include automation, autonomous systems, edge computing & AI operations
Nvidia’s networking solutions give it an edge over competitive AI chip makers
Nvidia AI-RAN survey results; AI inferencing as a reinvention of edge computing?
CES 2025: Intel announces edge compute processors with AI inferencing capabilities
Qualcomm CEO: expect “pre-commercial” 6G devices by 2028
Analysis: SpaceX FCC filing to launch up to 1M LEO satellites for solar powered AI data centers in space
SpaceX has applied to the Federal Communications Commission (FCC) for permission to launch up to 1 million LEO satellites for a new solar-powered AI data center system in space. The private company, 40% owned by Elon Musk, envisions an orbital data center system with “unprecedented computing capacity” needed to run large-scale AI inference and applications for billions of users, according to SpaceX’s filing entered late on Friday.
Credit: Blueee/Alamy Stock Photo
The proposed new satellites would operate in “narrow orbital shells” of up to 50 kilometers each. The satellites would operate at altitudes of between 500 kilometers and 2,000 kilometers, and 30 degrees, and “sun-synchronous orbit inclinations” to capture power from the sun. The system is designed to be interconnected via optical links with existing Starlink broadband satellites, which would transmit data traffic back to ground Earth stations.
“Fortunately, the development of fully reusable launch vehicles like Starship that can deploy millions of tons of mass per year to orbit when launching at rate, means on-orbit processing capacity can reach unprecedented scale and speed compared to terrestrial buildouts, with significantly reduced environmental impact,” SpaceX said.
- Energy Density & Sustainability: By tapping into “near-constant solar power,” SpaceX aims to utilize a fraction of the Sun’s output—noting that even a millionth of its energy exceeds current civilizational demand by four orders of magnitude.
- Thermal Management: To address the cooling requirements of high-density AI clusters, these satellites will utilize radiative heat dissipation, eliminating the water-intensive cooling loops required by terrestrial facilities.
- Opex & Scalability: The financial viability of this orbital layer is tethered to the Starship launch platform. SpaceX anticipates that the radical reduction in $/kg launch costs provided by a fully reusable heavy-lift vehicle will enable rapid scaling and ensure that, within years, the lowest LCOA (Levelized Cost of AI) will be achieved in orbit.
- Vacuum-Speed Data Transmission: In a vacuum, light propagates roughly 50% faster than through terrestrial fiber optic cables. By utilizing Starlink’s optical inter-satellite links (OISLs)—a “petabit” laser mesh—data can bypass terrestrial bottlenecks and subsea cables. This potentially reduces intercontinental latency for AI inference to under 50ms, surpassing many long-haul terrestrial routes.
- Edge-Native Processing & Data Gravity: Current workflows require downlinking massive raw datasets (e.g., Synthetic Aperture Radar imagery) for terrestrial processing, a process that can take hours. Shifting to orbital edge computing allows for “in-situ” AI inference, processing data onboard to deliver actionable insights in minutes rather than hours. This “Space Cloud” architecture eliminates the need to route raw data back to the Earth’s internet backbone, reducing data transmission volumes by up to 90%.
- LEO Proximity vs. Terrestrial Hops: While terrestrial fiber remains the “gold standard” for short-range latency (typically 1–10ms), it is often hindered by inefficient routing and multiple hops. SpaceX’s LEO constellation, operating at altitudes between 340km and 614km, currently delivers median peak-hour latencies of ~26ms in the US. Future orbital configurations may feature clusters at varying 50km intervals to optimize for specific workload and latency tiers.
………………………………………………………………………………………………………………………………………………………………………………………
The SpaceX FCC filing on Friday follows an exclusive report by Reuters that Elon Musk is considering merging SpaceX with his xAI (Grok chatbot) company ahead of an IPO later this year. Under the proposed merger, shares of xAI would be exchanged for shares in SpaceX. Two entities have been set up in Nevada to facilitate the transaction, Reuters said. Musk also runs electric automaker Tesla, tunnel company The Boring Co. and neurotechnology company Neuralink.
………………………………………………………………………………………………………………………………………………………………………………………
References:
Google’s Project Suncatcher: a moonshot project to power ML/AI compute from space
Blue Origin announces TeraWave – satellite internet rival for Starlink and Amazon Leo
China ITU filing to put ~200K satellites in low earth orbit while FCC authorizes 7.5K additional Starlink LEO satellites
Amazon Leo (formerly Project Kuiper) unveils satellite broadband for enterprises; Competitive analysis with Starlink
Telecoms.com’s survey: 5G NTNs to highlight service reliability and network redundancy
Huge significance of EchoStar’s AWS-4 spectrum sale to SpaceX
U.S. BEAD overhaul to benefit Starlink/SpaceX at the expense of fiber broadband providers
Telstra selects SpaceX’s Starlink to bring Satellite-to-Mobile text messaging to its customers in Australia
SpaceX launches first set of Starlink satellites with direct-to-cell capabilities
AST SpaceMobile to deliver U.S. nationwide LEO satellite services in 2026
GEO satellite internet from HughesNet and Viasat can’t compete with LEO Starlink in speed or latency
How will fiber and equipment vendors meet the increased demand for fiber optics in 2026 due to AI data center buildouts?
Subsea cable systems: the new high-capacity, high-resilience backbone of the AI-driven global network
Fiber Optic Boost: Corning and Meta in multiyear $6 billion deal to accelerate U.S data center buildout
Corning Incorporated and Meta Platforms, Inc. (previously known as Facebook) have entered a multiyear agreement valued at up to $6 billion. This strategic collaboration aims to accelerate the deployment of cutting-edge data center infrastructure within the U.S. to bolster Meta’s advanced applications, technologies, and ambitious artificial intelligence initiatives. The agreement specifies that Corning will furnish Meta with its latest advancements in optical fiber, cable, and comprehensive connectivity solutions. As part of this commitment, Corning plans to significantly scale its manufacturing capabilities across its North Carolina facilities.
A key element of this expansion is a substantial capacity increase at its fiber optic cable manufacturing plant in Hickory NC, for which Meta will serve as the foundational anchor customer. The construction and operation of these data centers — critical infrastructure that supports our technologies and moves us toward personalized superintelligence — necessitate robust server and hardware systems designed to facilitate information transfer and connectivity with minimal latency. Fiber optic cabling is a cornerstone component for enabling this high-speed, near real-time connectivity, powering applications from sophisticated wearable technology like the Ray-Ban Meta AI glasses to the global connectivity services utilized by billions of individuals and enterprises.
“This long-term partnership with Meta reflects Corning’s commitment to develop, innovate, and manufacture the critical technologies that power next-generation data centers here in the U.S.,” said Wendell P. Weeks, Chairman and Chief Executive Officer, Corning Incorporated. “The investment will expand our manufacturing footprint in North Carolina, support an increase in Corning’s employment levels in the state by 15 to 20 percent, and help sustain a highly skilled workforce of more than 5,000 — including the scientists, engineers, and production teams at two of the world’s largest optical fiber and cable manufacturing facilities. Together with Meta, we’re strengthening domestic supply chains and helping ensure that advanced data centers are built using U.S. innovation and advanced manufacturing.”
Meta is expanding its commitment to build industry-leading data centers in the U.S. and to source advanced technology made domestically. Here are two quotes from them:
- “Building the most advanced data centers in the U.S. requires world-class partners and American manufacturing,” said Joel Kaplan, Chief Global Affairs Officer at Meta. “We’re proud to partner with Corning – a company with deep expertise in optical connectivity and commitment to domestic manufacturing – for the high-performance fiber optic cables our AI infrastructure needs. This collaboration will help create good-paying, skilled U.S. jobs, strengthen local economies, and help secure the U.S. lead in the global AI race.”
- “As digital tools and generative AI continue to transform our economy — in fields like healthcare, finance, agriculture, and more — the demand for fiber connectivity will continue to grow. By supporting American companies like Corning and building and operating data centers in America, we’re helping ensure that our nation maintains its competitive edge in the digital economy and the global race for AI leadership.”
Key elements of the agreement:
- Multiyear, up to $6 billion commitment.
- Corning to supply latest generation optical fiber, cable and connectivity products designed to meet the density and scale demands of advanced AI data centers.
- New optical cable manufacturing facility in Hickory, North Carolina, in addition to expanded production capacity across Corning’s North Carolina operations.
- Agreement supports Corning’s projected employment growth in North Carolina by 15 to 20 percent, sustaining a skilled workforce of more than 5,000 employees in the state, including thousands of jobs tied to two of the world’s largest optical fiber and cable manufacturing facilities.
…………………………………………………………………………………………………………………………………………………………….
Comment and Analysis:
Corning’s “up to $6 billion” Meta agreement is essentially a long‑term, anchor‑tenant bet that AI‑era data centers will be fundamentally more fiber‑intensive than legacy cloud resident data centers, with Corning positioning itself as the default U.S. optical plant for Meta’s buildout through ~2030. In practice, this deal is a long‑term take‑or‑pay style capacity lock that de‑risks Corning’s capex while giving Meta priority access to scarce, high‑performance data‑center‑grade fiber and cabling.
AI data centers are becoming the new FTTH in the sense that hyperscale AI buildouts are now the primary structural driver of incremental fiber demand, design innovation, and capex prioritization—but with far higher fiber intensity per site and far tighter performance constraints than residential access ever imposed.
Why “AI Data Centers are the new FTTH” for fiber optic vendors:
For fiber‑optic vendors, AI data centers now play the role that FTTH did in the 2005–2015 cycle: the anchor use case that justifies new glass, cable, and connectivity capacity.
-
AI‑optimized data centers need 2–4× more fiber cabling than traditional hyperscalers, and in some designs more than 10×, driven by massively parallel GPU fabrics and east–west traffic.
-
U.S. hyperscale capacity is expected to triple by 2029, forcing roughly a 2× increase in fiber route miles and a 2.3× increase in total fiber miles, a demand shock comparable to or larger than the early FTTH boom but concentrated in fewer, much larger customers.
-
This is already reshaping product roadmaps toward ultra‑high‑fiber‑count (UHFC) cable, bend‑insensitive fiber, and very‑small‑form‑factor connectors to handle hundreds to thousands of fibers per rack and per duct.
In other words, where FTTH once dictated volume and economies of scale, AI data centers now dictate density, performance, and margin mix.
Carrier‑infrastructure: from access to fabric:
From a carrier perspective, the “new FTTH” analogy is about what drives long‑haul and metro planning: instead of last‑mile penetration, it’s AI fabric connectivity and east–west inter‑DC routes.
-
Each new hyperscale/AI data center is modeled to require on the order of 135 new fiber route miles just to reach three core network interconnection points, plus additional miles for new long‑haul routes and capacity upgrades.
-
An FBA‑commissioned study projects U.S. data centers alone will need on the order of 214 million additional fiber miles by 2029, nearly doubling the installed base from ~160M to ~373M fiber miles; that is the new “build everywhere” narrative operators once used for FTTH.
-
Carriers now plan backbone routes, ILAs, and regional rings around dense clusters of AI campuses, treating them as primary traffic gravity wells rather than as just a handful of peering sites at the edge of a consumer broadband network.
The strategic shift: FTTH made the access network fiber‑rich; AI makes the entire cloud and transport fabric fiber‑hungry.
Strategic implications:
-
AI is now the dominant incremental fiber use case: residential fiber adds subscribers; AI adds orders of magnitude more fibers per site and per route.
-
Network economics are moving from passing more homes to feeding more GPUs: route miles, fiber counts, and connector density are being dimensioned to training clusters and inference fabrics, not household penetration curves.
-
Policy and investment narratives should treat AI inter‑DC and campus fiber as “national infrastructure” on par with last‑mile FTTH, given the scale of projected doubling in route miles and more than doubling in fiber miles by 2029.
In summary, the next decade of fiber innovation and capex will be written less in curb‑side PON and more in ultra‑dense, AI‑centric data centers with internal fiber optical fabrics and interconnects.
……………………………………………………………………………………………………………………………………………………………………………………………….
References:
Meta Announces Up to $6 Billion Agreement With Corning to Support US Manufacturing
Big tech spending on AI data centers and infrastructure vs the fiber optic buildout during the dot-com boom (& bust)
Analysis: Cisco, HPE/Juniper, and Nvidia network equipment for AI data centers
Networking chips and modules for AI data centers: Infiniband, Ultra Ethernet, Optical Connections
Will billions of dollars big tech is spending on Gen AI data centers produce a decent ROI?
Superclusters of Nvidia GPU/AI chips combined with end-to-end network platforms to create next generation data centers
Lumen Technologies to connect Prometheus Hyperscale’s energy efficient AI data centers
Proposed solutions to high energy consumption of Generative AI LLMs: optimized hardware, new algorithms, green data centers
Hyper Scale Mega Data Centers: Time is NOW for Fiber Optics to the Compute Server
China’s open source AI models to capture a larger share of 2026 global AI market
Overview of AI Models – China vs U.S. :
Chinese AI language models (LMs) have advanced rapidly and are now contesting with the U.S. for global market leadership. Alibaba’s Qwen-Image-2512 is emerging as a top-performing, free, open-source model capable of high-fidelity human, landscape, and text rendering. Other key, competitive models include Zhipu AI’s GLM-Image (trained on domestic chips), ByteDance’s Seedream 4.0, and UNIMO-G.
Today, Alibaba-backed Moonshot AI released an upgrade of its flagship AI model, heating up a domestic arms race ahead of an expected rollout by Chinese AI hotshot DeepSeek. The latest iteration of Moonshot’s Kimi can process text, images, and videos simultaneously from a single prompt, the company said in a statement, aligning with a trend toward so-called omni models pioneered by industry leaders like OpenAI and Alphabet Inc.’s Google.
Moonshot AI Kimi website. Photographer: Raul Ariano/Bloomberg
………………………………………………………………………………………………………………………………………………………………………………………………………………………………………………..
Chinese AI models are rapidly narrowing the gap with Western counterparts in quality and accessibility. That shift is forcing U.S. AI leaders like Alphabet’s Google, Microsoft’s Copilot, OpenAI, and Anthropic to fight harder to maintain their technological lead in AI. That’s despite their humongous spending on AI data centers, related AI models and infrastructure.
In early 2025, investors seized on DeepSeek’s purportedly lean $5.6 million LM training bill as a sign that Nvidia’s high-end GPUs were already a relic and that U.S. hyperscalers had overspent on AI infrastructure. Instead, the opposite dynamic played out: as models became more capable and more efficient, usage exploded, proving out a classic Jevons’ Paradox and validating the massive data-center build-outs by Microsoft, Amazon, and Google.
The real competitive threat from DeepSeek and its peers is now coming from a different direction. Many Chinese foundation models are released as “open source” or “open weight” AI models which makes them effectively free to download, easy to modify, and cheap to run at scale. By contrast, most leading U.S. players keep tight control over their systems, restricting access to paid APIs and higher-priced subscriptions that protect margins but limit diffusion.
That strategic divergence is visible in how these systems are actually used. U.S. models such as Google’s Gemini, Anthropic’s Claude, and OpenAI’s GPT series still dominate frontier benchmarks [1′] and high‑stakes reasoning tasks. According to a recently published report by OpenRouter, a third-party AI model aggregator, and venture capital firm Andreessen Horowitz. Chinese open-source models have captured roughly 30% of the “working” AI market. They are especially strong in coding support and roleplay-style assistants—where developers and enterprises optimize for cost efficiency, local customization, and deployment freedom rather than raw leaderboard scores.
Note 1. A frontier benchmark for AI models is a high-difficulty evaluation designed to test the absolute limits of artificial intelligence in complex,, often unsolved, reasoning tasks. FrontierMath, for example, is a prominent benchmark focusing on expert-level mathematics, requiring AI to solve hundreds of unpublished problems that challenge, rather than merely measure, current capabilities.
China’s open playbook:
China’s more permissive stance on model weights is not just a pricing strategy — it’s an acceleration strategy. Opening weights turns the broader developer community into an extension of the R&D pipeline, allowing users to inspect internals, pressure‑test safety, and push incremental improvements upstream.
As Kyle Miller at Georgetown’s Center for Security and Emerging Technology argues, China is effectively trading away some proprietary control to gain speed and breadth: by letting capability diffuse across the ecosystem, it can partially offset the difficulty of going head‑to‑head with tightly controlled U.S. champions like OpenAI and Anthropic. That diffusion logic is particularly potent in a system where state planners, big tech platforms, and startups are all incentivized to show visible progress in AI.
Even so, the performance gap has not vanished. Estimates compiled by Epoch AI suggest that Chinese models, on average, trail leading U.S. releases by about seven months. The window briefly narrowed during DeepSeek’s R1 launch in early 2025, when it looked like Chinese labs might have structurally compressed the lag; since then, the gap has widened again as U.S. firms have pushed ahead at the frontier.
Capital, chips, and the power problem:
The reason the U.S. lead has held is massive AI infrastructure spending. Consensus forecasts put capital expenditure by largely American hyperscalers at roughly $400 billion in 2025 and more than $520 billion in 2026, according to Goldman Sachs Research. By comparison, UBS analysts estimate that China’s major internet platforms collectively spent only about $57 billion last year—a fraction of U.S. outlays, even if headline Chinese policy rhetoric around AI is more aggressive.
But sustaining that level of investment runs into a physical constraint that can’t be hand‑waved away: electricity. The newest data-center designs draw more than a gigawatt of power each—about the output of a nuclear reactor—turning grid capacity into a strategic bottleneck. China now generates more than twice as much power as the U.S., and its centralized planning system can more readily steer incremental capacity toward AI clusters than America’s fragmented, heavily regulated electricity market.
That asymmetry is already shaping how some on Wall Street frame the race. Christopher Woods, global head of equity strategy at Jefferies, recently reiterated that China’s combination of open‑source models and abundant cheap power makes it a structurally formidable AI competitor. In his view, the “DeepSeek moment” of early last year remains a warning that markets have largely chosen to ignore as they rotate back into U.S. AI mega‑caps.
A fragile U.S. AI advantage:
For now, U.S. companies still control the most important chokepoint in the stack: advanced AI accelerators. Access to Nvidia’s cutting‑edge GPUs remains a decisive advantage. Yesterday, Microsoft announced the Maia 200 chip – their first silicon and system platform optimized specifically for AI inference. The chip was was designed for efficiency, both in terms of its ability to deliver tokens per dollar and performance per watt of power used.
“Maia 200 can deliver 30% better performance per dollar than the latest generation hardware in our fleet today,” Microsoft EVP for Cloud and AI Scott Guthrie wrote in a blog post.

Image Credit: Microsoft
……………………………………………………………………………………………………………………………………………………………………………………………………………………………….
Leading Chinese AI research labs have struggled to match training results using only domestic designed silicon. DeepSeek, which is developing the successor to its flagship model and is widely expected to release it around Lunar New Year, reportedly experimented with chips from Huawei and other local vendors before concluding that performance was inadequate and turning to Nvidia GPUs for at least part of the training run.
That reliance underscores the limits of China’s current self‑reliance push—but it also shouldn’t be comforting to U.S. strategists. Chinese firms are actively working around the hardware gap, not waiting for it to close. DeepSeek’s latest research focuses on training larger models with fewer chips through more efficient memory design, an incremental but important reminder that architectural innovation can partially offset disadvantages in raw compute.
From a technology‑editorial perspective, the underlying story is not simply “China versus the U.S.” at the model frontier. It is a clash between two AI industrial strategies: an American approach that concentrates capital, compute, and control in a handful of tightly integrated platforms, and a Chinese approach that leans on open weights, diffusion, and state‑backed infrastructure to pull the broader ecosystem forward.
The question for 2026 is whether U.S. AI firms’ lead in capability and chips can keep outrunning China’s advantages in openness and power—or whether the market will again wait for a shock like DeepSeek to re‑price that risk.
Deepseek and Other Chinese AI Models:
DeepSeek published research this month outlining a method of training larger models using fewer chips through a more efficient memory design. “We view DeepSeek’s architecture as a new, promising engineering solution that could enable continued model scaling without a proportional increase in GPU capacity,” wrote UBS analyst Timothy Arcuri.
Export controls haven’t prevented Chinese companies from training advanced models, but challenges emerge when the models are deployed at scale. Zhipu AI, which released its open-weight GLM 4.7 model in December, said this month it was rationing sales of its coding product to 20% of previous capacity after demand from users overwhelmed its servers.
Moonshot, Zhipu AI and MiniMax Group Inc are among a handful of AI LM front-runners in a hotly contested battle among Chinese large language model makers, which at one point was dubbed the “War of One Hundred Models.”
“I don’t see compute constraints limiting [Chinese companies’] ability to make models that are better and compete near the U.S. frontier,” Georgetown’s Miller says. “I would say compute constraints hit on the wider ecosystem level when it comes to deployment.”
Gaining access to Nvidia AI chips:
U.S. President Donald Trump’s plan to allow Nvidia to sell its H200 chips to China could be pivotal. Alibaba Group and ByteDance, TikTok’s parent company, have privately indicated interest in ordering more than 200,000 units each, Bloomberg reported. The H200 outperforms any Chinese-produced AI chip, with a roughly 32% processing-power advantage over Huawei’s Ascend 910C.
With access to Nvidia AI chips, Chinese labs could build AI-training supercomputers as capable as American ones at 50% extra cost compared with U.S.-made ones, according to the Institute for Progress. Subsidies by the Chinese government could cover that differential, leveling the playing field, the institute says.
Conclusions:
A combination of open-source innovation and loosened chip controls could create a cheaper, more capable Chinese AI ecosystem. The possibility is emerging just as OpenAI and Anthropic consider public stock listings (IPOs) and U.S. hyperscalers such as Microsoft and Meta Platforms face pressure to justify heavy spending.
The risk for U.S. AI leaders is no longer theoretical; China’s open‑weight, low‑cost model ecosystem is already eroding the moat that Google, OpenAI, and Anthropic thought they were building. By prioritizing diffusion over tight control, Chinese firms are seeding a broad developer base, compressing iteration cycles, and normalizing expectations that powerful models should be cheap—or effectively free—to adapt and deploy.
U.S. AI leaders could face pressure on pricing and profit margins from China AI competitors while having to deal with AI infrastructure costs and power constraints. Their AI advantage remains real, but fragile—highly exposed to regulatory shifts, export controls, and any breakthrough in China’s workarounds on hardware and training efficiency. The uncomfortable prospect for U.S. AI incumbents is that they could win the race for the best models and still lose ground in the market if China’s diffusion‑driven strategy defines how AI is actually consumed at scale.
…………………………………………………………………………………………………………………………………………………………………………………………………………………..
References:
https://www.barrons.com/articles/deepseek-ai-gemini-chatgpt-stocks-ccde892c
https://blogs.microsoft.com/blog/2026/01/26/maia-200-the-ai-accelerator-built-for-inference/
China gaining on U.S. in AI technology arms race- silicon, models and research
U.S. export controls on Nvidia H20 AI chips enables Huawei’s 910C GPU to be favored by AI tech giants in China
Goldman Sachs: Big 3 China telecom operators are the biggest beneficiaries of China’s AI boom via DeepSeek models; China Mobile’s ‘AI+NETWORK’ strategy
Bloomberg: China Lures Billionaires Into Race to Catch U.S. in AI
Comparing AI Native mode in 6G (IMT 2030) vs AI Overlay/Add-On status in 5G (IMT 2020)